GPT-6.1 Sol Hands-On: Does It Fall Short of Claude Opus 5.5 in 3D Tasks?

GPT-6.1 Sol matches Sonnet's price but falls short in 3D generation while excelling at visual scene recreation.
OpenAI's GPT-6.1 Sol, launched at developer day, is priced identically to Claude Sonnet 5.5 ($2/$10 per million tokens), shifting its competitive tier from Opus down to Sonnet. In 3D game generation tests — the reviewer's specialty — Sol was "competent but not jaw-dropping," with pool party and skateboarding city visuals generally trailing Sonnet 5.5. However, it shone in static scene recreation (Jerry's Seinfeld apartment, RuneScape UI) and showed strong token efficiency throughout. The reviewer openly acknowledges the framework's 3D-visual bias, noting Sol's potential in software engineering and edge device domains remains underexplored.
A New Contender: GPT-6.1 Sol's Positioning and Pricing
OpenAI unveiled GPT-6.1 Sol at its developer day — a rapid iteration following GPT-6 Sol. The previous Sol didn't leave a strong impression in 3D generation tests, and this 6.1 release is officially described as "approaching Astra-level intelligence." Astra is OpenAI's most capable available model at $50 per million output tokens, while Sol comes in at just one-fifth of that cost.
Pricing is the key story here. GPT-6.1 Sol is priced at $2 per million input tokens and $10 per million output tokens — identical to Claude Sonnet 5.5 (referred to as "Sonic 5.5" in the video), which launched just the day before. This means Sol, once seen as an Opus-level competitor, is now priced head-to-head against Sonnet. The model has a knowledge cutoff of April 30, 2026, a context window exceeding one million tokens, a maximum output of 128K tokens, and supports both text and image input modalities.
Looking at benchmarks, the 6.1 version achieves a respectable capability jump over GPT-6 Sol despite the modest version number increment. Notably, the model performs best at high reasoning effort — not at the Max or Ultra tiers. This echoes a recent trend: higher reasoning intensity doesn't always yield better results, and can sometimes hurt scores on certain benchmarks by causing the model to "overthink" straightforward tasks.
A note on DeepSWE and reasoning effort: DeepSWE (Deep Software Engineering Benchmark) evaluates large models on complex software engineering tasks in real codebases — including understanding existing code structure, locating bugs, and writing patches. It's similar to SWE-bench but emphasizes high-difficulty, multi-step engineering reasoning. "Reasoning effort" is a tunable parameter in the OpenAI API that lets developers choose how much compute the model spends on internal "thinking" (low/medium/high/max). Higher tiers produce longer chain-of-thought reasoning, but don't always yield better answers — some benchmarks actually score higher at medium effort, because over-reasoning causes the model to "take the long way around" on simple tasks, introducing unnecessary errors.
3D Game Tests: Competent, but Not Impressive
The reviewer ran a series of 3D generation tasks on a system equipped with Blender and Godot, covering a backyard pool party, a GTA-style city, an orbital flight game, a subway FPS, and a skateboarding game.
The pool party test was particularly revealing. To ensure fairness, all caches and temp files were cleared to confirm no residual data from prior runs, and the model was tested in both Ultra (with fast mode) and pure Max mode. Both runs produced nearly identical results — Max mode was simply slower. Frankly, the visual output fell far short of Sonnet 5.5's version from the previous day, especially in character model fidelity.
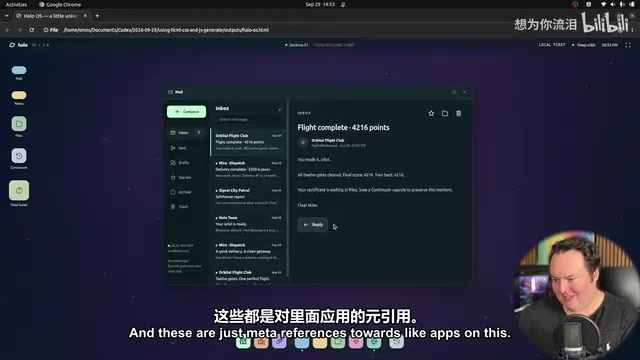
An interesting observation emerged around the "mail app" convergence behavior: multiple models from different vendors independently connected email applications with in-game features — such as launching games directly from an inbox or receiving flight status reports. This cross-vendor, cross-model convergence is a fascinating lens through which to observe current LLM behavioral patterns.
The orbital flight game (Orbital Run) earned higher marks — sound effects pitch up with speed, there's a music lab feature, and even a save-state rewind (Chrono) mechanic. This was completed fairly quickly in Max mode. Overall: "competent, but not jaw-dropping."
Why do models converge on the mail app? One likely explanation: LLMs are trained on large volumes of game dev tutorials, sample code, and GitHub projects, a significant portion of which happen to use email notifications as demonstration vehicles for game events (flight status reports, mission completion alerts, etc.). When different vendors' models independently tackle similar tasks, systematic overlap in training data naturally leads to convergence on similar implementation details. This relates to the "model homogenization" phenomenon observed in academia — despite architectural differences, shared web corpora can cause multiple models to exhibit nearly identical behavior in specific scenarios.
Skateboarding Game and Robotic Arm: Weaknesses and Highlights
The self-contained C++ skateboarding game test introduced a turning point. The initial output was a fairly barren New York street block with no pedestrian interaction — a noticeable gap compared to Sonnet's "vibrant city." But after the tester added a follow-up prompt (asking for improvement and explicitly permitting multi-file C++ rather than single-file), the model produced a significantly improved version: excellent water effects, realistic building reflections on the water surface, and complete sound design.

A "replay feature" suggested in the comments was particularly impressive — pressing Z triggers a cinematic replay after landing a trick, and the model had to independently determine the start and end timestamps of the trick. It handled this remarkably well, earning the description "X Games-level Pro Skate quality" from the tester.
The robotic arm grasping test revealed a different capability profile. The model worked for 18 minutes at high reasoning effort with fast mode, and every time the target vehicle was moved, flipped, or repositioned, the arm navigated to it accurately with precise, minimally destructive movements. Ultimately, though, the model "gave up" — it judged the task uncompletable and stopped. By contrast, Sonnet 5.5 did succeed, but in a near-destructive, largely luck-based manner. The tester actually expressed a degree of respect for Sol's decision to recognize its own limits.
Scene Recreation: Where Visual Understanding Shines
If the game tests were mixed, the static scene recreation tests revealed Sol's genuine strength: visual understanding.
The recreation of Jerry's apartment from Seinfeld was described as "absolutely stunning." Multiple locks on the door, text details on computer screens, the view outside the window, a green Klein bicycle with a modeled chain, a Porsche poster — and preset view switches with lighting controls for different scenes (office, bedroom, dollhouse perspective). The model even cited sources for set details. While the layout isn't entirely faithful to the show's actual floor plan, the precision of individual elements represents a massive capability leap.
The pixel-accurate recreation of the Old School RuneScape Grand Exchange PvP scene was equally impressive — the inventory UI with weapon icons, sharks, and potions was nearly pixel-perfect, and familiar NPCs were faithfully reproduced. The main shortcomings were a distant camera angle, insufficient character realism, and inability to trigger special attacks.

The SAAB 900 Turbo 3D modeling was a deliberately chosen challenge — the car has a uniquely odd shape that resists being templated onto a conventional sports car. The result wasn't a perfect likeness, but the front air dam structure, the signature stripes on the bumper, headlight textures, the strut towers and battery in the engine bay, and wheel design were all noteworthy. It also supported interactive features like opening the hood, changing color, and entering the driver's seat — ready to drop into a game.
Token Efficiency and Overall Assessment
The entire test session — including extensive Ultra and Max mode tasks — consumed only about 3% of the usage quota (dropping from 98% to 95%), reflecting strong token efficiency. The tester also attempted a non-visual task: connecting a vintage Pentium 3 laptop running Red Hat via USB and Ethernet, then asking the model to autonomously bypass the login screen and reinstall the OS. However, an accidental downgrade to the more permissive Daybreak model and the need for manual intervention meant the experiment couldn't be completed successfully.
Overall, GPT-6.1 Sol is a competent, token-efficient, and relatively affordable model. But in the 3D visual tasks that define this reviewer's testing framework, it didn't reach the "mind-bending" level that Sonnet 5.5 delivered the day before. Given that both models now carry identical price tags, that's not a favorable position for Sol.
The tester also acknowledged the inherent limitations of their evaluation framework — Sol may have stronger advantages in areas like edge device optimization or low-level software engineering that weren't fully explored here. In other words, Sol isn't worse overall; it's simply weaker on the specific test types this channel emphasizes. That kind of self-awareness is worth noting: a single-dimension benchmark comparison isn't enough to pass final judgment on a frontier model.
Notes on Daybreak and the Red Hat experiment: Daybreak refers to a permissive model variant used in OpenAI's internal or test environments, typically allowing the model to execute higher-risk operations (system commands, network access, etc.). The Red Hat laptop "autonomous login bypass and OS reinstall" experiment is a classic example of testing AI agent capabilities in a real computing environment with multi-step operations — closely aligned with OpenAI's Operator capability direction. Such tests require the model not just to generate code, but to dynamically adjust strategy based on real-world feedback in a closed loop. This represents one of the most important frontiers in current frontier model capability research.
Related articles

Cursor AI Programming in Practice: Build a Student Management System from Scratch in 30 Minutes
A Bilibili creator demonstrates Cursor AI programming: generating a student management system in 30 minutes with natural language. Details on Agent mode, Claude selection, prompt techniques, and thresholds.

Top 20 AI Coding Tools Ranking: From Rock-Solid to Lackluster, a Scored Matrix
Bilibili creator releases top 20 AI coding tools ranking, tiered T0–T4 from rock-solid to lackluster, with Claude Code and Codex tied at T0. This article details the scoring dimensions (capability, reliability, robustness, durability, cost, domestic availability) and tool performances to help developers choose the right AI coding assistant.

Vibe Coding Systematic Tutorial: Master AI-Assisted Programming from Zero
A three-month Vibe Coding tutorial from a Bilibili creator covering Codex, ClaudeCode, and Cursor, from core logic to commercial project practice for beginners.