GPT-6 Astra Only Changes 0.016% of Weights, Math Score Skyrockets 6x
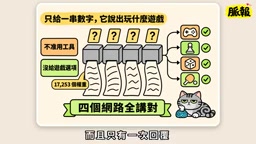
AI weight changes boost math scores 6x, but it's just removing roadblocks, not getting smarter.
The article explores two logics behind AI model capability improvement through a striking case. Researchers had frontier model GPT-6 Astra directly modify only 0.016% of a small Qwen model's weights, raising its MATH500 score from 7.9% to 48.1%—about a 6x increase. But the authors admit this only fixed the model's reasoning loop, letting answers it could already compute be written out, rather than genuinely improving math ability. In a control experiment, Gemma 3 270M, lacking obvious loop roadblocks, improved by less than 1 percentage point under the same operation—a gap of about 45x. The article thus proposes the concept of "empty-handedness" to distinguish experimental conditions, and cites Simon Willison's laptop test showing this capability has been distributed to local small models but the process is slow and black-box-like. The final conclusion: changing weights can remove obstacles but cannot add new abilities; evaluating AI scores should first ask three questions about tool conditions, starting bottlenecks, and control verification.
A Troubling Score Jump Case
Recently, an AI model's math test score jumped from 7.9% to 48.1%—a roughly 6x increase. Even more surprising: this improvement came solely from modifying an extremely tiny proportion of another model's weights (0.016%). Is the model getting smarter, or was it just stuck somewhere that finally got unblocked? The YouTube channel "Mai Bao" uses this example to break down two completely different upgrade logics, and the answer may directly affect how you view every AI "breakthrough."
The Experiment: A Model Modifies a Model, Touching Only One "Buzzing" Direction
This example comes from a paper by researcher Rikiya Techie et al., which Simon Willison introduced on his blog. The paper's core claim is bold: frontier models (such as GPT-6 Astra, which OpenAI claims is the most capable) can both interpret and modify another model's raw weights.
Raw weights are essentially a file stuffed with numbers describing what a model can do. Astra directly modifies these numbers—equivalent to touching the model's abilities without touching the training pipeline.
Specifically for the math experiment: researchers had Astra modify the weights of a small Qwen model, with the goal of fixing a specific flaw—the model tends to get stuck in "thinking loops," and the official model card also admits it's more prone than other Qwen models to over-thinking and never finishing. Astra traced the loop to a direction in the weights and subtracted it.
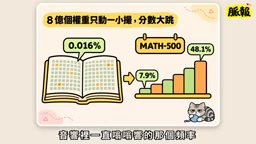
In the end, only 0.016% of the weights were changed—if you convert this to a 100,000-word book, that's roughly 16 characters. But the MATH500 score went from 7.9% to 48.1%.
The Truth Behind the Score: Was the Roadblock Removed, or Did Ability Grow?
The paper authors themselves admit: fixing the loop doesn't equal better math—it just lets the model finish writing out answers it could already compute. Two data points illustrate the point: while the proportion of responses hitting the trial-run limit dropped from 93% to 33%, the score rose from 7.9% to 48.1%. Responses that didn't hit the limit became 9.6x the original, while the score was about 6.1x the original—the proportion that could finish grew faster than the score.
So the more reasonable interpretation of this case is the second one: what was originally stuck is no longer stuck. "Mai Bao" calls this difference "empty-handedness"—the fewer tools, the higher the empty-handedness. Changing weights is like removing roadblocks; Qwen has roadblocks to remove, while the control group Gemma 3 270M doesn't have such obvious roadblocks.
MATH500 is one of the commonly used benchmarks for measuring large models' math reasoning ability, containing 500 competition-style math problems covering algebra, geometry, number theory, combinatorics, and other categories, with answers usually being exactly matchable values or expressions. Because the problem count is moderate and difficulty is clearly stratified, it's often used to quickly compare different models or the same model before and after changes. Note that MATH500 problems often require complete multi-step reasoning; if a model gets stuck in a loop or times out mid-reasoning, it will be marked wrong even if the final answer could have been computed—this is exactly the key background for the "score jump" in this article's case.
Weights are parameters learned through training in neural networks, stored as massive numbers of floating-point values, determining how the model responds to inputs. "Modifying raw weights" means directly editing these values without retraining or adjusting prompts. Because weights are enormous in scale, changing an extremely small proportion (like 0.016%) is numerically negligible, yet it may happen to act on a direction that gets repeatedly activated, thereby changing model behavior. This also explains why "changing weights" is more like precisely removing a local obstacle rather than systematically improving ability.
Thinking loop refers to a model repeatedly returning to similar lines of thought or expressions when generating responses, unable to converge on a final answer, commonly seen in tasks requiring long-chain reasoning. It manifests as the same sentence being rewritten multiple times, steps jumping back and forth, and conclusions never being reached. In evaluations, such responses are often truncated for exceeding trial-run counts or generation length limits, and directly counted as failures. In this article, 93% of the small Qwen model's responses hit the limit, indicating its bottleneck is mainly not "can't compute" but "can't finish computing." After fixing the loop, answers that could originally be computed can be written out, and the score naturally rebounds substantially—which is why the authors emphasize that "fixing the loop doesn't equal better math."
Control Experiment: Why It Doesn't Work When You Switch Models
Researchers also did a control: having Astra modify the weights of Gemma 3 270M. The Gemma series is small in size and rarely gets stuck in loops, with only 8.5% of responses hitting the limit (compared to Qwen's 93%). As a result, after Astra's modifications, Gemma's performance on MATH500 improved very little; even Astra's best reported modification only brought marginal gains, and it itself marked this modification as "not established"—not yet countable.
How big is the gap? Qwen improved by 40.2 percentage points, while Gemma improved by less than 1 percentage point—a difference of about 45x. The errors Astra saw were ordinary reasoning problems like arithmetic errors and invalid algebra steps, with no single component that could be switched off.
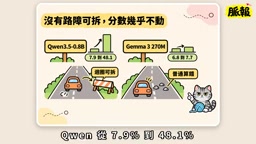
The authors' conclusion is clear: changing weights can remove obstacles covering abilities, but cannot add abilities the model never had. This path is called "removing roadblocks"; when there are no roadblocks, the tool fails.
Gemma 3 270M is an ultra-small model in Google's Gemma series, with about 270 million parameters, emphasizing lightweight and local deployment. Compared to larger models, small models are more prone to ordinary reasoning problems like arithmetic errors or invalid steps in long-chain math reasoning, rather than necessarily manifesting as obvious repetitive loops. The significance of the control group is: if changing weights is merely "removing roadblocks," then when the model itself has no obvious roadblocks and bottlenecks are dispersed across numerous ordinary errors, the same operation will be hard-pressed to bring substantial improvement. Gemma had only 8.5% of responses hit the limit, precisely indicating it lacks a loop obstacle that can be removed at a single point, so Astra's changes could only bring marginal gains and were marked as "not established."
This Capability Has Already Been Distributed to Laptops
Simon Willison did a more down-to-earth test: feeding the paper's publicly released prompts on GitHub directly to the Qwen 3.8B model on his own laptop. This model has only a 17-sentence instruction file and is openly downloadable. As a result, it recognized Pac-Man (46 min 12 sec), Pong (1 hr 4 min 54 sec), Breakout (52 min 25 sec), but got Freeway wrong—Simon attributed this to the game being relatively obscure.
Simon's assessment was "impressive," but he also noted the cost was a long wait. During the wait, the model left behind massive reasoning records, hand-calculating which cell the 381st input falls into, backtracking and revising mid-way. The author believes this "heavy prediction" behavior is practically impossible for almost anyone, and currently looks like a black-box method. However, Simon believes that experienced people with pen and paper and enough effort could reach the same answers, and he leans toward the "hard work" side.
Two Questions That Need to Be Viewed Separately
Simon believes the paper mixes two topics: first, what a model can do with raw weights when it doesn't run tools or execute programs; second, how effectively a model can update and improve other models once it has programs. He only pursues the first question and finds it more interesting.
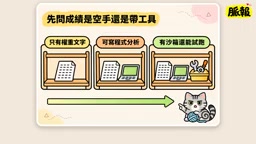
"Mai Bao" uses "empty-handedness" to distinguish the experiments: the game-guessing experiment can't run anything, so empty-handedness is highest; in the math model modification experiment, Astra can write Python to analyze weights but isn't allowed to actually run the network—like holding a calculator to study a design blueprint but not being able to start the test drive; in the Go experiment, Astra has a Python sandbox, can read and write weights, and can repeatedly practice with trial runs.
What This Means for Your Work
The paper authors predict that future network weights will soon be directly optimized by reasoning-capable language models. Simon finds this direction cool but believes peripheral commentary doesn't hold up. He isn't prepared to declare the era of raw code over, nor does he accept the notion that "the future is incomprehensible machines changing their own weights in incomprehensible ways."
If you're worried that methods you're learning now will soon be replaced, this paper needn't be treated as an alarm. "Mai Bao"'s conclusion is: there's not a single way of working you need to change this week; what needs updating is your eye for AI score headlines.
Next time you see AI achieve another astonishing result, you can first ask three questions:
- What tools did it have on hand at the time?
- Where was the starting point originally stuck?
- Does it still hold with a different control model?
Scores can still be exciting, but finish asking these three questions first.
Related articles

9 AI Subscription Plans Compared: The Real Cost Per 100M Tokens Revealed
Bilibili creator tests 9 AI subscription plans from Volcano, Alibaba, Tencent, Baidu, Zhipu, Xiaomi, MiniMax and more, converting them all to real cost per 100M tokens, breaking down fixed-quota vs. three-tier coefficient billing and how caching, time-of-day discounts, and window limits affect actual quota.

Vibe Coding for Beginners: Expressing Intent Instead of Handwriting Code
What is Vibe Coding? A 137-episode Bilibili course defines it: the core is expressing intent, not writing code. This article analyzes Vibe Coding's productivity logic, target audience, and entry expectations to help beginners decide if it's worth learning.

LangChain Beginner's Guide: An Agent Development Roadmap from LangGraph to Deep Agents
Clarify the encapsulation relationship among LangChain, LangGraph, and Deep Agents, and master the learning path and selection logic for agent development frameworks—suitable for beginners in large model development.