Gradient-Free Learning: LLMs Edit Robot Policies Directly in Weight Space
LLMs can edit robot policies directly in weight space, bypassing gradients to fix behavior cloning failures.
The article introduces "weight-space programming": handing a trained robot policy's weights to an LLM, which locates and modifies parameters based on task descriptions or failure feedback to repair behavior—no backpropagation or extra data needed. It targets behavior cloning's failures under data scarcity and task perturbations, turning learning from gradient optimization into semantic weight editing. The article analyzes the technical logic and notes limitations: no theoretical guarantees for editing precision, weight scale far exceeding context windows, and risk of damaging existing capabilities. It concludes with implications for robot learning and model repair.
When Behavior Cloning Fails, LLMs Can Directly Rewrite Policy Networks
The standard pipeline for training new robot skills is: collect data, behavior cloning, deploy. But according to research shared in the Reddit community, this pipeline frequently fails—especially when data is limited or the task changes slightly. A new approach bypasses gradient updates: hand the trained policy network to a large language model and let the LLM modify parameters directly in weight space to repair policy behavior.
The core claim of this work is that LLMs can not only generate text or code, but also understand the semantic structure of neural network weights, precisely "debugging" robot policies much like editing code. The original blog (jstranghoener.github.io) calls this process "weight-space programming."
Why Does Behavior Cloning Fail So Easily?
Behavior cloning is essentially supervised learning: fitting a policy to expert demonstration data. Its shortcomings are obvious—edge cases not covered by the data, noise in demonstrations, and task perturbations can all cause the policy to collapse at deployment. The traditional remedy is to collect more data and retrain, which is costly and time-consuming.
The intervention of LLMs changes this loop. Researchers treat the weights of the policy network as a readable and writable "program." Based on task descriptions or failure feedback, the LLM directly locates and modifies the relevant parameters without backpropagation. This amounts to turning "learning" from gradient optimization into weight editing based on semantic understanding.
The distribution shift problem of behavior cloning: The core flaw of behavior cloning is known academically as "covariate shift" or "compounding error." During training, the policy only sees the state distribution along expert trajectories, but at deployment, once a small deviation occurs, it enters states not covered by the training data, producing even larger deviations and forming cumulative error. This phenomenon was first systematically analyzed by Ross et al. in 2011 when they proposed the DAgger algorithm; their theoretical guarantees show that compounding error grows quadratically with episode length rather than simply linearly. This is also why simply adding demonstration data cannot fundamentally solve the problem—data coverage can never exhaust all possible deviating states.
The Technical Logic of Weight-Space Programming
According to the blog, the key to this method is enabling the LLM to understand the mapping between weights and behavior. Different layers and channels in a policy network often correspond to specific motion patterns or perceptual responses, and the LLM can acquire this correspondence through weight serialization, structural annotation, and similar techniques.
Once the mapping is established, the LLM can execute editing instructions such as "increase the force of the grasping action" or "correct the oscillation when turning." The entire process involves no gradient computation and requires no additional training data, relying only on the LLM's ability to reason about weight semantics.
Weight serialization and the hypernetwork background: Converting neural network weights into sequences that an LLM can process typically draws on "weight serialization" techniques, such as converting floating-point parameters into strings or discrete tokens by layer or channel. A more systematic approach comes from hypernetwork research—using a small network to generate the weights of a large network—as well as recent work on "weight-space learning" (such as Schürholt et al.'s research on neural network classification), which demonstrates that weights themselves contain structural information recognizable by models. In addition, the model editing field (such as ROME and MEMIT) has shown that model behavior can be changed by locating specific layer parameters, providing a methodological foundation for "LLMs understanding weight semantics." However, transferring this to the continuous control parameters of robot policies remains a new problem.
Potential and Limitations Coexist
The value of this direction lies in transferring the general reasoning capabilities of LLMs to the low-level parameters of robot control, offering a low-cost repair path for data-scarce scenarios. If a policy fails only locally, weight editing may be faster and more resource-efficient than retraining.
But the limitations are equally obvious: LLM understanding of weights is still coarse, and editing precision and reliability lack theoretical guarantees; the weight scale of complex policies far exceeds the context window, and how to efficiently present weight information remains an engineering challenge. In addition, directly modifying weights may destroy the policy's original capabilities on other tasks, requiring additional stability evaluation.
The conflict between context windows and parameter scale: Taking common robot policy networks (such as vision-motion policies based on ResNet or ViT) as an example, parameter counts typically range from millions to hundreds of millions. Even after quantization or sparsification compression, their textual representation far exceeds the context window of current LLMs (typically 128K to 1M tokens). Therefore, practical systems need to design "weight summarization" or "parameter indexing" mechanisms that present only information about key layers or key channels to the LLM while keeping the rest frozen. Although this selective editing is feasible, automatically identifying "which parameters are relevant to the current failure mode" is itself a difficult problem, currently relying mostly on manually specified layer ranges or gradient-based sensitivity analysis.
Implications for the Robot Learning Paradigm
The most noteworthy aspect of this research is that it proposes a different learning metaphor: learning does not necessarily have to go through gradients. When a model is large enough and understands structure well enough, editing parameters itself can become a form of "learning." This also has reference significance for foundation model fine-tuning and model repair beyond the robotics field.
Of course, weight-space programming is still in an early exploratory stage and remains far from replacing traditional training methods. But it opens up an idea worth following: making LLMs the "programmers" of model parameters, not just consumers of data.
One-line Summary
LLMs can edit robot policies directly in weight space, bypassing gradient updates to repair behavior cloning failures.
Paragraph Summary
The article introduces a new approach called "weight-space programming": handing the weights of a trained robot policy network to a large language model, which then directly locates and modifies parameters based on task descriptions or failure feedback to repair policy behavior, without backpropagation or additional training data. Aimed at behavior cloning's tendency to fail under data scarcity and task perturbations, the method turns learning from gradient optimization into weight editing based on semantic understanding. The article analyzes its technical logic—the LLM must establish a mapping between weights and behavior—and points out current limitations: editing precision lacks theoretical guarantees, the weight scale of complex policies far exceeds context windows, and direct modification may destroy existing capabilities. Finally, it discusses the implications of this idea for the robot learning paradigm and model repair.
Related articles
Hands-On with Shopify AI Toolkit: Official Validation for AI-Generated Shopify Code
Hands-on with Shopify's official AI Toolkit: connect Shopify docs, API schemas, and code validation to Claude Code and other coding assistants to intercept AI-fabricated fields. Installation steps, offline validation, and telemetry-on-by-default warnings.
Claude Orchestrating an AI Coding Team: A Practical Analysis of Agent Orchestrator
The open-source Agent Orchestrator lets Claude Code dispatch Codex, Gemini, Cursor and more for parallel AI coding, with Git Worktree isolation, CI auto-correction, and mobile notifications for AI team collaboration. This article analyzes its core mechanisms, cost structure, and use cases.
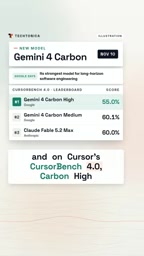
Google's New AI Coding Model Beats Claude at One-Third the Cost
Google's Gemini 4 Carbon edges past Claude Fable 5.2 Max on CursorBench 4.0 at 60.4% vs 60%, costing just $9.22 per task versus $32.79—about one-third.