How Do Hidden Tokens in Reasoning Models Make Cloud Bills Spike 8x?

Hidden chain-of-thought tokens in reasoning models are billed at high output rates, spiking cloud bills 5-8x.
Enterprises expected reasoning models to cut costs, but hidden chain-of-thought tokens caused cloud bills to surge. Extended reasoning models silently generate 4,000-12,000 internal thinking tokens per API call, billed at 4-5x the output rate. Logic42 tests show a standard model costs $14.20 per 1,000 workflows versus $119.50 for an unbounded reasoning model, with latency rising from 1.15s to 14.2s. Three traps: hidden output billing multiplier, cache eviction, and TokenMaxxing. Gateway-level semantic routing and token budget enforcement cut costs 74% to $31.10 and latency to 1.68s.
How Do Hidden Tokens in Reasoning Models Make Cloud Bills Spike 8x?
Enterprises expected AI inference costs to fall, only to find their cloud bills surging. The reason: extended reasoning models silently generate 4,000 to 12,000 hidden chain-of-thought tokens per API call, and these tokens are billed at the high output-token rate. Even though base model prices per million tokens have dropped 90%, unrouted reasoning calls and 128K-context workloads still push enterprise cloud bills up 5 to 8.4 times.
According to Logic42's measurements across 50,000 enterprise agent workflows, a standard non-reasoning model costs just $14.20 to process 1,000 workflows, while a default, unbounded reasoning model costs $119.50 — with end-to-end latency also spiking from 1.15 seconds to 14.2 seconds. Developers see only a 230-token JSON response in their logs, never the 6,840 hidden reasoning tokens the gateway discards before returning the result.
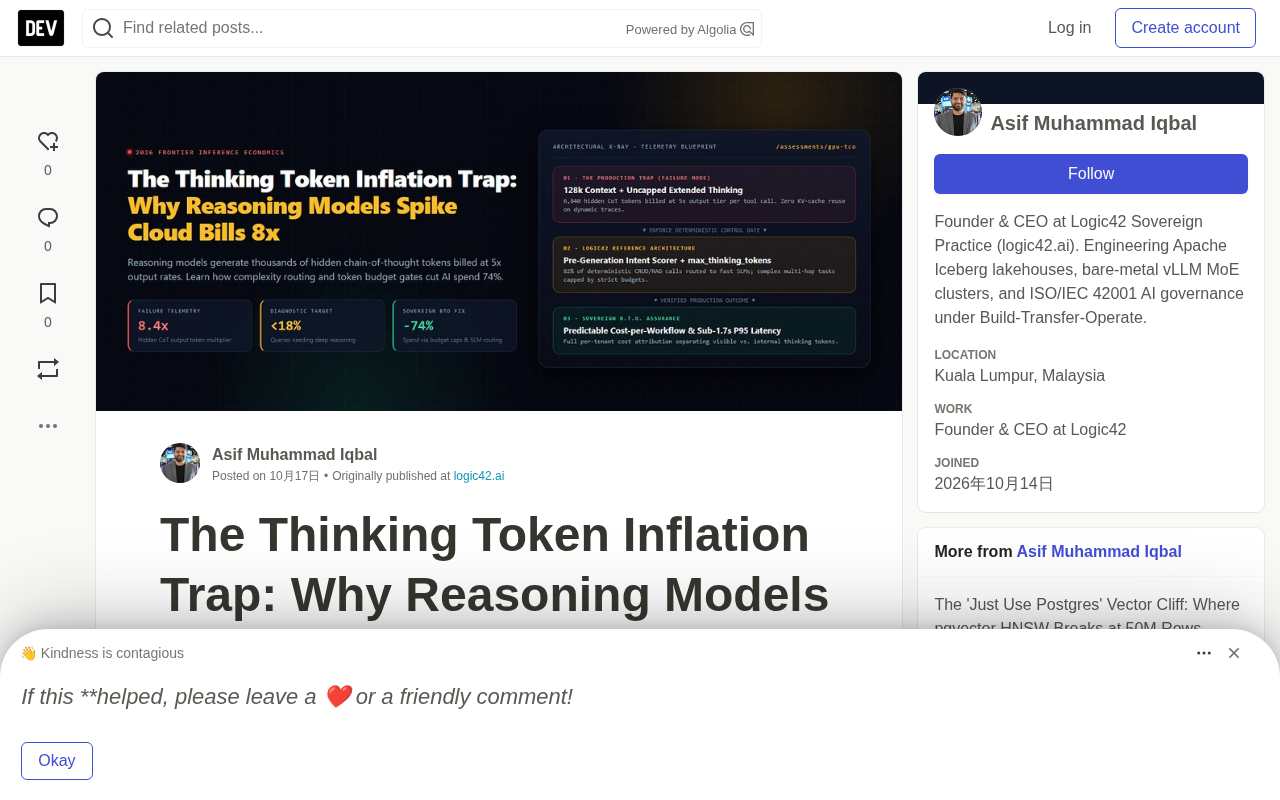
Three Architectural Traps Behind Reasoning Model Cost Spikes
1. The Hidden Output Billing Multiplier
Frontier API providers price output tokens at 4 to 5 times the rate of input tokens, because autoregressive decoding is bottlenecked by GPU high-bandwidth memory bandwidth. Every internal <think> token requires a full forward pass. When an agent retries a failed tool call three times, it pays a 5x output premium for more than 20,000 temporary thinking tokens that never reach the user.
Autoregressive decoding and the memory bandwidth bottleneck: When a large language model generates each token, it must load all model weights from the GPU's high-bandwidth memory (HBM) and run attention computation against the current context. This process is memory-bound rather than compute-bound; decoding speed is directly limited by HBM bandwidth, leaving much of the GPU's compute idle. This is precisely why the per-token cost on the output side is far higher than on the input side — input can be processed in a single parallel forward pass over the entire prompt, while output must be decoded serially, token by token. The 4-5x premium API providers charge for output tokens is essentially pricing this serial, low-utilization decoding process. Understanding this makes it clear: hidden chain-of-thought tokens, though invisible to users, genuinely consume the most expensive decoding resources, so billing them at the output rate isn't arbitrary markup — it's a direct reflection of the cost structure.
KV cache and prefix caching mechanisms: KV cache refers to the model storing the computed key-value pairs (Key/Value) for each layer in GPU memory during generation, avoiding recomputation of historical context for subsequent tokens and thereby speeding up decoding. Prefix caching goes further, reusing the KV state of identical prefixes across requests so that repeated system prompts enjoy substantial discounts. But this optimization depends on the prefix remaining stable: once the chain-of-thought trajectory is regenerated or stripped each turn, cache hit rates plummet, and the burst overhead of test-time computation can no longer be amortized across multi-turn sessions, driving costs up.
2. Ephemeral Reasoning Cache Eviction
Static system prompts can enjoy a 90% KV cache discount, but dynamic chain-of-thought trajectories are stripped between turns or regenerated at each step. Internal reasoning tokens change every turn, so prefix caching cannot amortize test-time compute bursts across multi-turn agent sessions.
3. TokenMaxxing on Trivial Classification Tasks
Cheap nominal input prices tempt developers to dump entire 128K-token codebases or untrimmed RAG documents into flagship reasoning models for simple pattern extraction. Large noisy contexts confuse the model's reasoning verifier, trapping it in self-doubt loops and doubling internal thinking token consumption.
Architecture Comparison: Unbounded Reasoning vs. Deterministic Budget Routing
To stop runaway test-time compute spending, you must classify query complexity before the call and enforce hard reasoning token caps by task tier. Logic42's architecture deploys a pre-generation semantic router and token budget enforcer at the gateway layer, strictly limiting extended thinking to highly ambiguous multi-hop tasks.
Its core routing logic has three gates: first, when a tenant's daily spend reaches 85% of budget, a hard circuit breaker downgrades to a small non-reasoning model; second, more than 80% of deterministic CRUD and formatting tasks are routed to zero-thinking models; third, high-complexity synthesis tasks get a strictly capped thinking token budget (1,024 to 2,048) to prevent context-driven thinking bloat.
Measurements show that with the complexity- and budget-gated architecture, cost per 1,000 workflows drops from $119.50 to $31.10 — a 74% reduction — and P95 latency falls from 14.2 seconds to 1.68 seconds.
Semantic routing and token budget enforcer: The semantic router is a lightweight classifier that runs before the request enters the model, deciding based on the query's semantic complexity (e.g., whether it involves multi-hop reasoning or tool-call chains) whether to dispatch the request to a zero-thinking small model, a standard model, or a reasoning model with a thinking budget. The token budget enforcer is the component that enforces hard caps at the gateway layer; it doesn't rely on the model SDK's default behavior but rewrites parameters such as max_thinking_tokens before the request is sent and verifies the actual reasoning tokens consumed after the response returns. Together, the two enable control before costs are incurred rather than after the bill is generated. This "classify first, then cap" gateway-level design makes reasoning budgets an auditable, enforceable policy rather than a soft constraint dependent on developer discipline.
Three Rules for Controlling Test-Time Compute Economics
Disable reasoning on deterministic tool loops: More than 82% of production agent steps involve JSON formatting, parameter extraction, or CRUD state checks. Route these calls to fast non-reasoning models (max_thinking_tokens = 0) to avoid paying an output premium for trivial syntax tasks.
Enforce explicit budget_tokens caps per endpoint: Never leave thinking.budget_tokens or reasoning_effort at unbounded defaults in production SDKs. Set hard caps (1,024 to 2,048 tokens) and track usage.completion_tokens_details.reasoning_tokens as a separate Prometheus metric per tenant.
Repatriate high-volume reasoning to private MoE clusters: When sustained reasoning workloads exceed 40 million output tokens per day, cloud API output markups break unit economics. Migrating open-weight mixture-of-experts reasoning models to dedicated bare-metal NVIDIA H200/B200 clusters converts the variable per-token penalty into fixed hardware amortization.
If you don't separate visible output tokens from hidden thinking tokens in your FinOps telemetry, test-time compute inflation will silently devour your AI roadmap. Enterprises should prioritize deterministic model routing and sovereign GPU clusters, so engineering teams get frontier reasoning capability at a predictable unit cost.
Mixture-of-experts (MoE) architecture and self-hosting economics: A mixture-of-experts model consists of multiple "expert" subnetworks plus a gating network; each forward pass activates only a few experts, so the total parameter count can be large while the compute cost per inference stays relatively manageable. For high-volume reasoning workloads, the key advantage of self-hosting open-weight MoE models is converting variable per-token costs into fixed GPU hardware amortization: once the cluster is built, marginal token cost depends mainly on utilization and power rather than the cloud provider's output markup. NVIDIA H200 and B200 both feature large-capacity, high-bandwidth memory, making them well suited to hosting MoE weights and long-context KV caches. When sustained reasoning output exceeds 40 million tokens per day, the amortized cost of a self-built cluster is typically lower than the cloud API output premium — but this also requires the enterprise to have model operations, batch scheduling, and GPU utilization monitoring capabilities; otherwise, fixed costs become a new source of waste.
One-line Summary
Hidden chain-of-thought tokens in reasoning models are billed at high output rates, spiking cloud bills 5 to 8 times.
Paragraph Summary
The article notes that enterprises expecting reasoning models to cut costs instead saw cloud bills surge due to hidden chain-of-thought tokens. Extended reasoning models silently generate 4,000 to 12,000 internal thinking tokens per API call, billed at 4-5x the output-token rate. Logic42's measurements show a standard model costs just $14.20 per 1,000 workflows, while an unbounded reasoning model costs $119.50, with latency rising from 1.15 to 14.2 seconds. The three architectural traps are the hidden output billing multiplier, ephemeral reasoning cache eviction, and TokenMaxxing on trivial tasks. The article proposes deploying a semantic router and token budget enforcer at the gateway layer; through budget circuit breakers, task tiering, and hard thinking caps, costs drop to $31.10 (a 74% reduction) and latency to 1.68 seconds. It also offers three rules: disable reasoning on deterministic tool loops, enforce budget_tokens caps, and migrate high loads to private MoE clusters.
Related articles

Bilibili's Hit Dify Tutorial: A Practical Guide to Building 20+ AI Apps from Scratch
A distilled guide to Bilibili's top-rated Dify tutorial: Windows + Docker deployment, MySQL connection, five app types, model integration strategy, and publishing.

Agent Skills Beginner's Guide: From Concepts to Multi-Agent Collaboration in Practice
A comprehensive guide to Agent Skills: core concepts, components, the importance of Description, standardization, beginner learning paths, and multi-agent collaboration.

One Neuron Detects Both Cats and Cars? We Reproduced It and Found a New Explanation
The cat-car neuron reinterpreted: researcher Cammarata argues it distinguishes pointy from round, not cats from cars. We reproduced the experiment and found the new explanation holds on most inputs—but cars are the exception. The interpretability debate continues on language models.