How Personalized Data Analysis Reveals Daily Emotional Well-Being
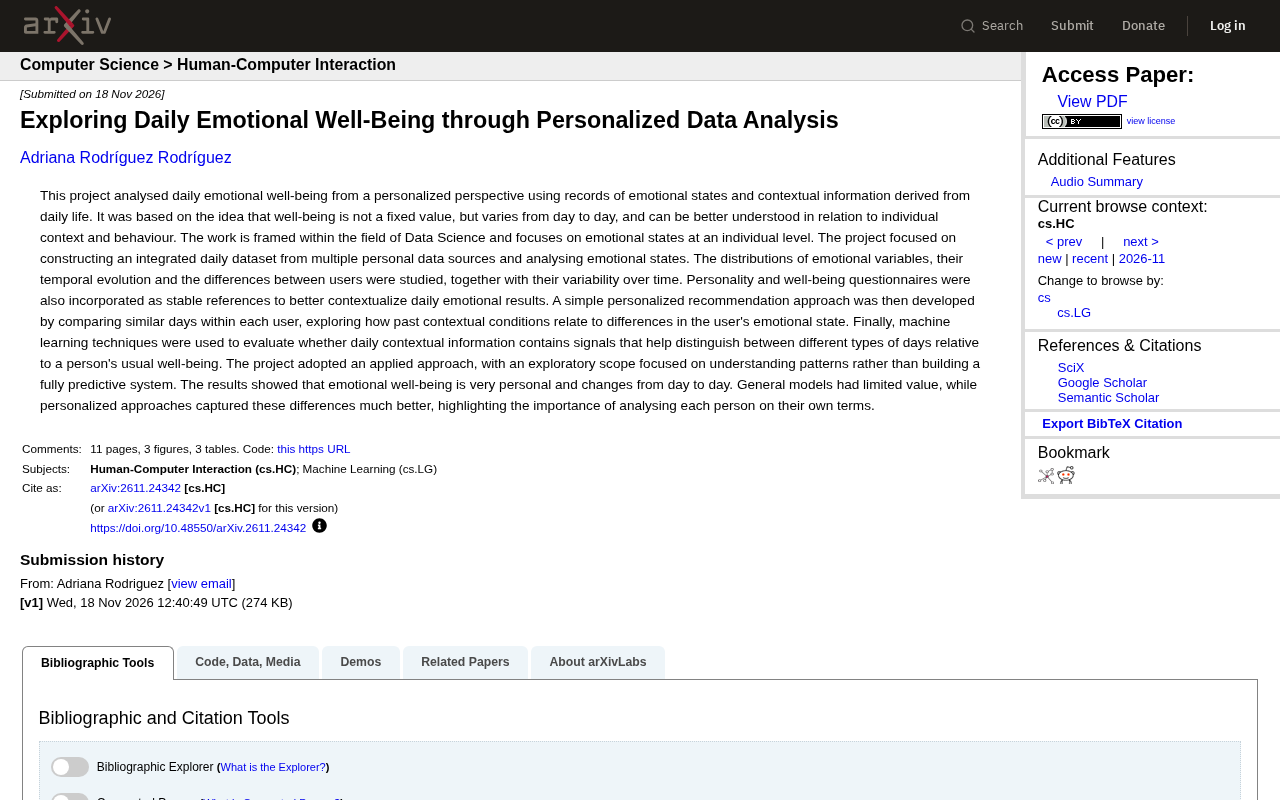
Research uses personalized data analysis to reveal daily emotional well-being fluctuations, highlighting the limits of generic models and the value of person-centered approaches.
This data science project, "Exploring Daily Emotional Well-Being Through Personalized Data Analysis," adopts an applied exploratory approach to understand emotional well-being over time and across individuals. It integrates multi-source personal data (mood records, behavior logs, contextual information) into daily datasets, addresses data alignment, missing values, and temporal granularity, and incorporates personality and well-being questionnaires as stable references. Researchers developed a simple personalized recommendation method comparing similar days within users to explore context–emotion associations. Machine learning evaluation shows daily contextual information contains signals distinguishing personal norms, but generic models have limited value while personalized modeling better captures within- and between-person variability. The core conclusion: emotional well-being is highly personal and fluctuates daily, and future health tools need person-centered adaptive analysis rather than one-size-fits-all models.
Emotional well-being is not static—it fluctuates with the ups and downs of daily life. A research project titled "Exploring Daily Emotional Well-Being Through Personalized Data Analysis" attempts to understand how emotional well-being changes over time and across individuals from a personal perspective, combining mood state records with everyday contextual information. This work falls within the field of data science, focusing on individual-level emotional state analysis and adopting an applied exploratory approach aimed at discovering patterns rather than building a complete predictive system.
Building an Integrated Daily Dataset
One of the project's core challenges was integrating information from multiple personal data sources into a unified daily dataset. These sources may include mood state records, daily behavior logs, and contextual information. Researchers needed to address issues such as data alignment, missing values, and temporal granularity. Through integration, the team was able to observe the distribution of emotional variables, trends over time, and differences between users, while also analyzing the temporal variability of these variables.
To more accurately interpret daily emotional outcomes, the project also incorporated personality questionnaires and well-being questionnaires as stable references. These questionnaires provide relatively enduring traits and baseline well-being levels for individuals, helping to distinguish daily fluctuations from long-term tendencies. This design—combining stable traits with dynamic states—is an important foundation for personalized analysis.
Data alignment and temporal granularity When integrating multi-source personal data, it is often necessary to unify data collected at different frequencies (e.g., once-daily mood ratings, hourly behavior records) to the same temporal granularity (e.g., "day"). Common approaches include aggregating high-frequency data by day (e.g., taking the mean, sum, or maximum) or interpolating low-frequency data. Data alignment refers to ensuring that records from different sources match on timestamps, avoiding erroneous associations caused by inconsistent collection times. Missing value handling requires care: direct deletion may lose information, and simple imputation may introduce bias—strategies should be chosen based on the specific context (e.g., multiple imputation or model-based imputation). These preprocessing steps directly affect the reliability of subsequent analyses.
Personalized Recommendations: Finding Similar Days
Building on the integrated data, researchers developed a simple personalized recommendation method. This method explores associations between past contextual conditions and differences in users' emotional states by comparing similar days within each user. For example, if a user tends to feel better under certain specific conditions (such as sleep duration, social activities, work stress, etc.), the system can identify similar days and offer recommendations based on personal history.
This approach emphasizes "similarity" rather than universal rules. Because emotional well-being is highly personal, generic models often struggle to capture individual-specific patterns. By confining the analysis to within a single user, recommendations can be more closely tailored to the individual's actual circumstances.
Similarity measurement is at the core of determining whether two "days" are similar. Common methods include Euclidean distance, cosine similarity, or weighted distance based on feature weights. In personalized scenarios, weights need to be adjusted according to the contextual dimensions the user cares about (e.g., sleep, social interaction) to make similarity more reflective of the individual's reality. Additionally, dynamic time warping (DTW) can be used to handle phase shifts in time series, or tree-based similarity learning can be employed. The choice of similarity measure directly affects recommendation quality and should be tuned through cross-validation or user feedback.
Machine Learning to Evaluate Contextual Signals
The project further used machine learning techniques to assess whether daily contextual information contains signals that help distinguish different "day types"—where day types are defined relative to an individual's usual well-being level. In other words, researchers wanted to know: can daily contextual data help determine whether a given day deviates from that user's norm?
The results showed that generic models have limited value, while personalized methods can better capture these differences. This highlights the importance of modeling each person's own circumstances in emotional well-being analysis. Machine learning here is not used to build a predictive black box, but as an exploratory tool to validate the effectiveness of contextual signals.
Within-person and between-person variability is a key distinction in emotion analysis. Within-person variability refers to mood fluctuations for the same user across different time points, while between-person variability refers to baseline differences between different users. Generic models typically mix the two in modeling, easily overlooking within-person patterns. Personalized methods instead model each user separately first, or introduce user ID as a random effect, thereby separating the two types of variability. Evaluation should use leave-one-out or user-based train-test splits to avoid data leakage. This distinction helps understand the dynamic nature of emotional well-being and provides a basis for personalized interventions.
Key Findings and Implications
The core conclusion of the research is that emotional well-being is highly personal and changes daily. Generic models struggle to effectively capture this within-person and between-person variability, while personalized methods can significantly improve the ability to capture differences. This finding has implications for health technology applications: future emotional well-being tools may need to abandon "one-size-fits-all" models in favor of person-centered adaptive analysis.
The project also acknowledges its exploratory nature and did not attempt to build a complete predictive system. Future work could further enrich data sources, improve similarity measurement methods, and explore how to deliver personalized emotional well-being support while protecting privacy.
Overall, this research demonstrates the potential of data science in individual emotional well-being analysis, emphasizes the importance of understanding mood fluctuations from a personal context, and offers ideas for more precise and human-centered health analysis tools.
Related articles
FBI-Warned AI Hacking Tool ARTEX: Cost Disruption and Defensive Restructuring
The FBI-warned AI hacking tool ARTEX reduces penetration testing costs to $150-$1,500, causing financial data breaches and supply chain attacks. Learn how it works, real cases, and a five-step defense strategy.
FBI Warns: ARTEX AI Hacking Tool Breaches Systems in Three Hours
FBI warns the open-source AI pentesting framework ARTEX is being abused, with some intrusions gaining privileged access in under three hours, over 1,600 consoles exposed, and links to South Korean financial data breaches and the ConnectWise supply chain attack.
FBI Warns About Artex: AI-Driven Attack Framework Threatens Cloud Identity Security
FBI warns that the AI penetration testing framework Artex is being used for automated attacks: written in Go and driven by AI agents, it covers the full chain from reconnaissance to data exfiltration. This article analyzes its real threat to cloud identity and privilege security and key defense priorities.