How to Build Your Personal AI Benchmark: 5 Steps to Find the Right LLM for You

Build a personal AI benchmark in 5 steps to find which LLM truly fits your workflow.
With new models launching every 11 days and public benchmarks losing credibility as their data enters training sets, the most effective approach is building a personal AI benchmark. The 5-step method covers: selecting tasks that reflect your real work distribution, choosing up to four candidates including a baseline, running blind tests in fresh conversations, using an AI judge from a different model family as a cross-reference, and making a Switch/Split/Stay decision factoring in cost, speed, company constraints, and switching costs. Once built, the benchmark is reusable every time a major model shift is worth evaluating.
New models are emerging at an average rate of one every 11 days — Opus 5.5, GPT 6.1, Grok, various open-weight models arriving one after another. Every release comes with a polished benchmark table, but do those scores actually tell you which model fits your workflow? At this practitioner-focused workshop co-hosted by AI Daily Brief host NLW and Nufar Gaspar, the answer is clear: no. What you need is a personal AI benchmark.
Why Public Benchmarks Are Becoming Less Reliable
Nathaniel repeatedly drives home one point throughout the episode: be skeptical of launch-day scores. This isn't an accusation of dishonesty — it's because most benchmark data has already made its way into models' training sets, becoming part of the "canon." The longer a benchmark has existed, the less it's worth referencing.
More critically, at this stage, differences between models are no longer simply about being "better" or "worse" — they're about how a model feels to you, and how it fits into the model stack you've built for yourself. NLW puts it plainly: you can almost guarantee that sometimes, a model representing the state of the art on a particular benchmark will actually perform worse on your specific version of a task — especially in highly subjective domains like writing.
Beyond scores, there's another category of noise worth watching out for: the "seven-day hype cycle" after a model launch. Early impressions are heavily skewed toward building 3D mini-games and reproducible, socially shareable demos. Some even argue that certain models are specifically optimized for influencer testing. The feedback that actually matters tends to surface seven days or more later, when real-world reports emerge from actual work — like "it quietly missed a clause in contract review," which means far more to a lawyer than a slick retro 3D game.
Step 1: Choose the Right Tasks to Test (The Most Critical Step)
Nufar breaks the entire process into five steps, and she calls the first one "the most decisive": deciding which tasks belong in your reusable benchmark.
The principles for selecting tasks are worth unpacking one by one:
- Diverse and balanced: Cover your real work and personal use, proportional to how you actually use AI.
- You trust the results enough to make decisions from them: If the test results don't give you enough confidence to act, the benchmark is worthless.
- Prioritize high-frequency tasks: Things you do repeatedly every day have the most to gain from improvement.
- Consider failure cost: If you clearly know what "badly wrong" looks like for a certain task, that's actually a great test case — quickly identifying failure is sometimes more effective than defining what "good" looks like.
- Distinguish "from scratch" from "working from existing material": Tasks like polishing emails or refining decks require a starting draft.
- Include at least one "wishlist" task: Something you tried with AI but weren't happy with, so you stopped doing it regularly. When a new frontier model appears, this becomes your immediate excitement point.
Nufar's own six use cases include: generating LinkedIn posts from raw notes, handling price negotiations and sensitive emails with stakeholders, researching AI tool features by pricing tier, a course learner portal website, generating practice questions for a new audience in one shot, and her wishlist item — a truly sensible weekly plan that requires no back-and-forth iteration. She admits no model has yet gotten a complex weekly plan right in a single generation.
Steps 2 & 3: Select Candidates and Run Blind Tests
Once tasks are defined, you choose your candidates. An important note here: candidates don't have to be models — they could also be a new harness (tool framework) or a combination of an agentic tool and a model.
Nufar offers a lesson from experience: she tested seven model options this time and found "seven was way too many" — reviewing seven outputs for each of six tasks was exhausting. She recommends a maximum of four candidates, and you must include a baseline representing how you currently work.
Two rules when running tests: execute each prompt in a fresh conversation to avoid context contamination, and hide the model names. We carry strong biases toward our favorite tools, and blind testing is the only way to see clearly. For scoring, she recommends a combination of a 1–5 numerical rating and a one-sentence subjective note.
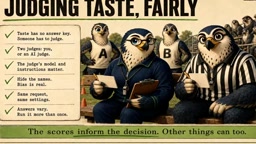
On anonymization, Nufar offers four methods: ask a friend to shuffle things around, use a spreadsheet to generate random IDs, use an AI tool to relabel outputs, or use the script she shared directly. The script approach requires API keys — you can use OpenRouter to call multiple models with a single key, which is completely feasible for non-technical users.
She also highlights a practical tip: include at least one visual task (website design, app UI, image generation), because visual results are easier to score quickly and form preferences around.
OpenRouter is an API aggregation layer that lets developers and non-technical users call hundreds of models from different providers (including GPT, Claude, Gemini, Grok, and more) using a single API key, without needing to register separate API accounts on each platform. For personal benchmarking, its practical value lies in running parallel calls to multiple models under one account while comparing actual usage costs on a single bill. Harness, in AI engineering contexts, refers to a tool framework that wraps model calls — it governs how prompts are structured, how outputs are processed, whether retry logic is applied, and more. The same underlying model paired with different harnesses can produce dramatically different real-world results, which is why "candidates" aren't limited to models alone.
Using AI as a Judge: Useful, but Take It with a Grain of Salt
Beyond your own scoring, the workflow also supports bringing in "AI as a judge" — having one model score results against a predefined rubric, then cross-referencing that with your own preferences.
But Nufar has clear warnings on this:
- Evaluate the judge itself: If the judge has no correlation with your taste, it's a bad judge — discard it.
- The judge should come from a different model family: "AI nepotism" is real — models tend to favor members of their own family. Since she hadn't tested Gemini as a candidate, she used Gemini Pro as her judge.
- The judge can't see visual output: When evaluating a website, the judge only reads code and text — it can't see the rendered result the way a human can. Using an API to have AI judge visual content is often a poor choice.

When Nufar finally revealed results, the surprises kept coming: for LinkedIn posts, her top picks were Kimi, Fable, and Opus (she'd expected GPT to win); GPT family models were best for price negotiations; GPT and Grok tied for practice questions; Grok unexpectedly won on weekly planning; and Opus 5.5 took the course portal. She and the AI judge only agreed on one category — price negotiation — and diverged on everything else. This further reinforces the case for treating AI judge conclusions with a discount.
AI as a judge is an automated evaluation paradigm: an independent language model scores the output of a target model according to human-predefined scoring dimensions (a rubric), replacing or supplementing human review. This approach is extremely valuable for large-scale testing, but carries two types of systematic bias: family bias (models tend to score members of their own family higher — the "AI nepotism" mentioned above) and format bias (judge models tend to favor well-structured, formally worded outputs over more natural expressions that humans might actually prefer). Cross-referencing AI judge conclusions with human subjective scoring, rather than relying solely on either, is the current industry standard practice.
Step 5: Make a Decision — But Don't Just Look at Who Won
The final step is the decision, which Nufar distills into three outcomes: Switch, Split, or Stay.
The key insight is that a model winning your benchmark doesn't mean you must switch. The real decision requires layering in multiple practical considerations:
- Company constraints: Many employees can only use approved models, but even so, choosing between configurations like "fast/deep thinking" modes is a valid benchmark, and you can even run results with mock data to make the case for purchasing new licenses.
- Cost: The numbers in the workshop are striking — Fable ranked first by the judge, but its total cost was an order of magnitude higher than the others. GPT Sol scored the same as Fable in Nufar's own ratings, but at a fraction of the cost.
- Speed: Grok had extremely long average latency, despite reasonable costs. NLW specifically mentioned that Sam Altman admitted he hadn't realized how much speed mattered to him until he used ultra-fast mode. Nufar herself became acutely sensitive to speed after waiting 20 minutes for a website to generate.
- Switching cost: Building habits is expensive — if the improvement isn't significant, staying put has real value too.
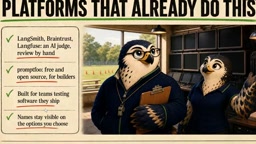
For teams needing enterprise-scale, ongoing, standardized evaluation, Nufar mentions ready-made platforms like LangSmith, Braintrust, and Langfuse. But for personal use, the manual or script-based approach described above is more than sufficient.
LangSmith, Braintrust, and Langfuse are all observability and evaluation platforms for LLM applications. Their core features include tracing inputs and outputs for every model call, logging latency and costs, managing evaluation datasets, and running automated test suites. Their primary audience is development teams or enterprises that need to continuously monitor model performance in production environments, supporting standardized, versioned evaluation processes integrated into CI/CD pipelines. For individuals or small teams, the onboarding cost is relatively high, but once usage scales up and longitudinal tracking across time becomes necessary, their structured data recording capabilities far outpace manual spreadsheet solutions.
One Investment, Long-Term Returns
The most compelling aspect of this benchmark is its reusability: build it once carefully, and whenever a significant model change comes along worth considering, you can simply re-run the same benchmark. Nufar's recommendation is to "do it at least once, if only for the joy of surprising yourself when the results come in."
Her own conclusions are worth noting. As a heavy user of Claude and Cursor with Grok, this exercise has her seriously considering elevating GPT into her "top two" tools — if she could only pick one, she'd even be willing to shift primarily to GPT. NLW's approach, meanwhile, is completely different: he goes "entirely by feel," routinely throwing the same task at multiple models simultaneously.
This is precisely what illustrates the nature of a personal benchmark — there are no universal right answers. As NLW puts it, if any part of this process doesn't feel practical to you, the whole point is to reshape it so it works for you. The purpose of a benchmark, ultimately, is to answer one question: "Does this model matter to me, and in what ways?"
Related articles

GitHub Daily · October 23: Agent Runtimes and Skill Libraries Surge on the Same Day
NVIDIA open-sources OpenShell, a Rust security runtime for autonomous agents; Claude-Red turns security methodology into SKILL.md skills; VoxCPM2 drops the tokenizer.

Build an AI Super Employee System at Zero Cost: A Full Breakdown of Automated Agent Workflows
A deep breakdown of the AI super employee system demoed on Bilibili: agent orchestration, digital human voiceovers, map and enterprise lead generation, 24/7 customer service, and legal modules. We analyze the business logic and compliance risks behind zero-cost signup to help entrepreneurs judge the real ROI of this AI digital employee system.

The Essential Difference Between Chatbots and AI Agents: Crossing from Conversation to Execution
What's the difference between a chatbot and an AI agent? Based on the MCP series on the Learn Tech channel, this article uses examples like booking flights and summarizing notes to explain: a chatbot only gives answers, while an agent actually completes tasks through a think-act-observe loop. It breaks down the four core components—model, tools, memory, and goal—as well as MCP's role as a bridge, and discusses agents' applicable boundaries and permission risks.