How to Quantitatively Evaluate Agent System Engineering Quality? A Six-Dimension Framework Explained
Agent engineering quality requires six dimensions, four evaluator layers, and release gates — not just a success rate.
The article starts with a common interview question to expose the core flaw of relying solely on success rate: Agents are non-deterministic systems that can't be measured with a single number. It breaks engineering quality into six dimensions — outcome, process, reliability, cost, observability, and security — and proposes Cost per Successful Task as the North Star metric, supported by six process metrics including Pass@1 and unassisted completion rate. A four-layer evaluator system (deterministic checks → rules → LLM-as-judge → human arbitration) ensures measurement credibility. All metrics feed into a release gate pipeline of offline regression, shadow mode, canary release, and failure accumulation, forming a continuous improvement flywheel.
Why the Intuitive Answer of "Look at Success Rate" Falls Apart
Here's a high-frequency interview question that stumps many candidates: Setting aside underlying model capabilities, how do you quantitatively evaluate the engineering quality of an Agent system? The intuitive answer is usually — look at the success rate, the percentage of tasks completed, plus user feedback. But an interviewer only needs three follow-up questions to make that answer collapse: What do you say when the success rate looks great but business metrics don't budge? Given the randomness in models, if the same task runs twice and produces different results, is your success rate even trustworthy? When something goes wrong in production, can you replay every step of the Agent within ten minutes and clearly explain whether the fault lies with the model, the tools, or the orchestration?
The problem isn't with the candidates — it's that evaluating an Agent system is fundamentally not something you can summarize with a single number. Traditional software is deterministic: the same input always produces the same output. An Agent, by nature, is a non-deterministic decision-making system — give it the same question today and it might give you solution A; tomorrow it might give you solution B.
There's a key equation here: the quality users actually perceive = model capability (comprehension, reasoning, generation) + system engineering (orchestration, tools, memory, permissions, observability, testing, recovery mechanisms). Since the interview question has already excluded model capability from the equation, all remaining variables fall on the system engineering side. The focus of measurement is never how smart the system is on any given occasion — it's whether the system can deliver results in a stable and controlled manner.
Six Dimensions for Measuring Engineering Quality
Breaking down "stable and controlled" gives us six indispensable dimensions:
Outcome Quality — Was the task ultimately completed correctly? Were user constraints satisfied? This is the foundation, but looking only at results isn't enough — a correct result could simply be luck.
Process Quality — Were the right tools selected? Was the path efficient? When errors occur, can the system self-correct and converge?
Reliability — When faced with anomalies, long-running tasks, or environmental changes, can the system recover on its own?
Efficiency and Cost — Every step an Agent takes costs money. Behind each successful task lies a burn rate of time, tokens, and tool fees — and that bill needs to be tallied.
The two dimensions most often overlooked: Observability (can a failure be fully replayed, located, and attributed to a root cause?) and Security and Governance (are permissions, sensitive data, and high-risk actions always under control?).
One-line summary: miss any one of these six dimensions, and the quality you're seeing is probably inflated.
The North Star Metric and Six Process Metrics
Once you have the dimensions, you still need concrete numbers. The first principle — don't just look at success rate; look at the cost of success.
Here's a recommended North Star metric: Cost per Successful Task, with a straightforward formula: total cost divided by the number of successful tasks.
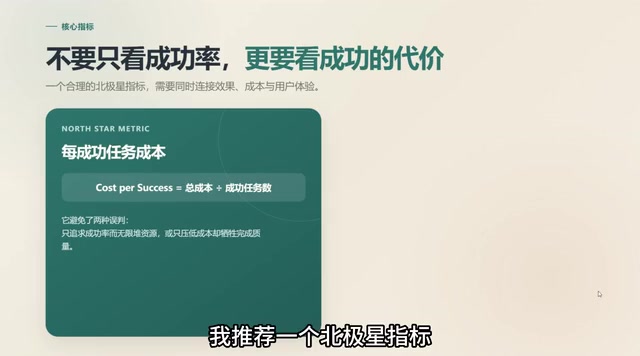
It earns its North Star status because it has veto power over two extremes: chasing success rate alone leads to wild resource spending, while obsessing over cost alone sacrifices quality. By binding outcome and cost into a single metric, dashboards become much harder to game.
Below the North Star, add six process metrics:
- Task Success Rate: Success must be a verifiable business end state — data actually written to the database, files actually saved to disk — not the model saying "it's done."
- Pass@1: First-attempt success, which is far closer to the real user experience than a success rate that allows unlimited retries.
- P95 End-to-End Latency: Focus on the tail, and separate model latency from tool latency so you know where the time is actually going.
- Unassisted Completion Rate: Completed entirely without human takeover — this is what true automation looks like.
- Tool Call Validity Rate: Specifically catches problems like infinite loops and repeated parameter errors.
- Recovery Success Rate: When a tool fails or the environment becomes abnormal, can the system recover on its own and still complete the task?
Pass@k is a standardized metric originally developed to evaluate code generation capabilities of language models, introduced by OpenAI in the HumanEval benchmark and later widely adopted in Agent evaluation. Pass@1 represents the probability that the model generates a correct result in a single sample; Pass@k represents the probability that at least one of k samples is correct. The gap between the two directly reflects system stability: a low Pass@1 combined with a high Pass@10 means the system needs to "run multiple times and get lucky" to succeed — generally unacceptable in a production environment. The article's emphasis on Pass@1 over "success rate after unlimited retries" is precisely because end users typically have the patience for one attempt, not ten silent retries happening behind the scenes.
Four-Layer Evaluators: Making Your Numbers Trustworthy
Having metrics still isn't enough — are the numbers you're measuring actually credible? That's the trap the second interview follow-up digs. The solution is a four-layer evaluator system, built on the principle: the earlier the layer, the more deterministic; the later the layer, the more human oversight is needed.
Layer 1 — Deterministic Checks: Formats, fields, files, database states, API return codes — anything that can be verified with code should absolutely not be evaluated by a model. It's faster, more stable, and easier to debug.
Layer 2 — Rules and Heuristics: Keyword constraint checks, schema validation, pre-execution rules — balancing efficiency with interpretability.
Layer 3 — LLM as Judge: Only now do you bring in LLM judgment, for handling open-ended quality assessments. But two disciplines must be maintained: first, fix scoring criteria and assign one evaluator per dimension — don't use a single giant prompt to evaluate all dimensions; second, continuously check for preference bias.
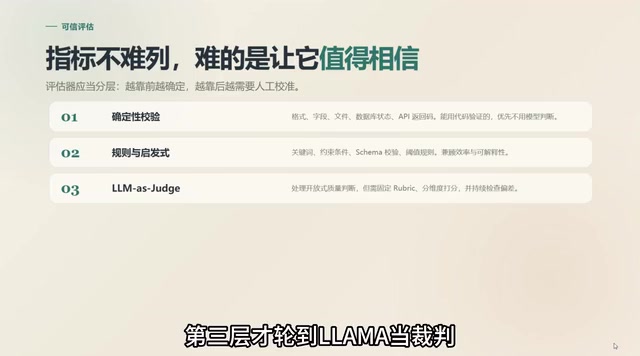
Layer 4 — Human Arbitration: Spot-check disputed samples to calibrate the alignment between evaluators and ground-truth standards.
There's also a "dual-track principle": examine both whether the outcome is correct and whether the path was sound. The outcome tells you whether value was delivered; the path helps you locate problems and guide fixes.
LLM-as-a-Judge is a technique widely adopted in Agent evaluation systems in recent years. The core idea: when task output correctness cannot be determined by hard rules, use an independent language model to score or make binary judgments. Common implementations construct an Evaluator Prompt that feeds in the task description, expected criteria, and actual output together, asking the judge model to output a score and reasoning. This approach excels at handling "reasonableness" at the natural language level, but has several known failure modes: position bias (tendency to score earlier-appearing options higher), verbosity bias (longer responses tend to score higher), and self-reinforcement bias (a model judging its own model family's outputs tends to inflate scores). The emphasis in Layer 3 on "one evaluator per dimension" and "continuously check for preference bias" is an engineering safeguard specifically targeting these known failure patterns.
Turning Evaluation into a Release Gate
How do all these metrics actually get used? In one sentence — turn evaluation into release gates, not reports that sit in documentation. Every change to a prompt, tool upgrade, workflow adjustment, or model version swap goes through the same quality pipeline, with four gates operating in sequence:
- Offline Regression: A golden test set covering core flows, historical failures, and edge cases. If this gate doesn't pass, nothing ships.
- Shadow Mode: Run alongside real traffic without touching real users — the sole purpose is comparing the differences between old and new execution traces.
- Canary Release: Route a small percentage of real traffic and monitor four dashboards (success rate, intervention rate, latency, cost) — full rollout only when all thresholds are met.
- Full Rollout and Failure Accumulation: The most critical step — failures generated during full rollout must never be discarded. They should continuously be deposited into the next round of regression assets.
Production failure → human root cause analysis → deposit bad cases into regression set → fix and validate — the faster this flywheel spins, the higher the engineering quality.
Shadow Mode is a traffic mirroring test technique originating from system switchover practices in finance and telecommunications, now widely adopted in ML system deployments. How it works: the production system responds normally to user requests while simultaneously sending the same inputs to the candidate version in parallel. The candidate fully executes but its results are not returned to users and produce no side effects. For Agent systems, this means the new workflow runs the complete decision and tool-calling chain on real requests, but all write operations (database writes, file creation, external API calls) must be intercepted or redirected to a sandbox environment — otherwise data contamination occurs. Shadow mode's value lies in its ability to expose long-tail issues that only appear under real traffic distributions, which offline test sets struggle to cover.
Four Most Common Pitfalls
Anyone building Agents has likely fallen into these traps:
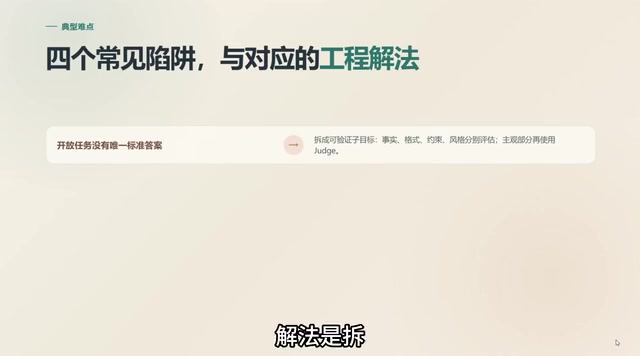
Pitfall 1: Open-ended tasks have no single ground truth. How do you judge "write some good copy" as right or wrong? The solution is decomposition — break it down into verifiable sub-goals, judging facts, format, constraints, and style separately. Use code for what can be automated; delegate only the subjective parts to the model judge.
Pitfall 2: The same task produces different results on two runs. The solution is straightforward — fix model version and sampling parameters during evaluation, and report mean, percentiles, and confidence intervals across multiple runs. Nobody trusts a single score.
Pitfall 3: Success rate went up, but the user experience didn't improve. This means you're being deceived by proxy metrics. The solution is to return to business end states and track hard currency metrics: unassisted completion rate, cost per successful task, and user time-to-completion.
Pitfall 4: The external environment keeps changing. If a tool vendor quietly updates a schema, the Agent silently degrades. The solution: implement contract validation for tools, inject failures for stress testing, run scheduled health checks, and automatically trigger key-path regression whenever a tool is updated.
The True Definition of High Engineering Quality
Looking back at that opening interview, what the candidate lacked wasn't intelligence — it was a system. The real answer should be:
High engineering quality doesn't mean the Agent never makes mistakes — no non-deterministic system can be error-free. High engineering quality means every mistake is controllable, traceable, and fixable.
Ultimately, evaluating an Agent system's engineering quality is really evaluating one thing: does this team have the capability to continuously improve a non-deterministic system?
Leave you with three self-assessment questions: First, can you produce a credible set of numbers showing whether today's system works? Second, when something goes wrong, can you quickly replay it and attribute the fault to a specific layer? Third, does every failure get turned into a test case in tomorrow's regression set? If all three answers are "yes," the engineering quality of that Agent system is solid.
Related articles
Kijai Updates MiniMax-H3 VAE: Lower VRAM Usage Without Quality Loss
Kijai updated the MiniMax-H3 int8 quantized VAE, enabling RTX 3060 12GB users to generate 1MP/10s and 0.7MP/15s videos with no reported quality loss.
Aerial Reconnaissance a Century Ago: Neubronner's Miniature Pigeon Camera
German pharmacist Julius Neubronner's miniature pigeon camera was a legendary early attempt at aerial photography. Explore its engineering ingenuity, military significance, and historical legacy.
AI Agent Fundamentals: From Traditional Programs to the Perception-Decision-Action Loop
A beginner's guide to AI Agents: covering traditional programs vs. agents, the perception-decision-action loop, LLM + tool calling + memory stack, and real-world use cases.