Jira's Parent Company Atlassian Launches Teamwork Graph to Help AI Truly Understand Team Collaboration
Atlassian builds Teamwork Graph for Jira, using a unified data layer to give AI team context.
The article introduces Teamwork Graph, a major update Atlassian is building for Jira — a "unified data layer and context engine" designed to solve the data silo problem where critical information is trapped in isolated apps like Jira and Confluence. It operates in three layers: aggregating data across apps, mapping collaboration and dependency relationships, and surfacing signals about how work gets done. The most imaginative part is that AI can access this context to find information, answer questions, and even take action under permission controls, filling the gap where general-purpose AI lacks enterprise context. The author notes significant upfront investment is required, but for teams deeply using the Atlassian ecosystem, long-term productivity value could be substantial.
According to a YouTube creator's shared insights, Atlassian is building a major update for Jira called Teamwork Graph. This system, described as a "unified data layer and context engine," aims to solve a core problem that has plagued enterprise collaboration for years: critical information is trapped in isolated applications.
Why Is Teamwork Graph Needed?
Jira users span industries and roles — from software development to project management, from marketing operations to customer support. But one undeniable fact is that teams' working methods have long transcended the boundaries of any single tool. Information is scattered across Jira, Confluence, and various other applications, forming data silos.
Atlassian spent years studying how people actually work, trying to find ways to connect these fragments. Teamwork Graph is the product of that research — it aims not just to connect data, but to understand the relationships between data.
The Three Core Capabilities of Teamwork Graph
According to the video, Teamwork Graph's operation can be broken down into three layers:
First, data aggregation. It brings together data from Jira, Confluence, and other applications and tools the team has connected. This isn't simple data relocation — it's integration built on top of usage scenarios.
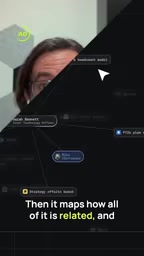
Second, relationship mapping. The system maps out the associations between all data — who collaborates with whom, who is responsible for what task, which projects have dependencies on each other. This relationship network transforms previously isolated information points into meaningful connections.
Third, signal surfacing. The system proactively identifies and surfaces signals about how work gets done — such as who you collaborate with and what your current work priorities are — making the right connections more visible.
Knowledge Graphs and Entity-Relationship Modeling
The technical foundation of the "relationship mapping" layer is the knowledge graph: abstracting people, tasks, projects, and documents as entities (nodes), and abstracting "responsible for," "depends on," "collaborates with," and "mentions" as relationships (edges), thereby forming a queryable, reasoning-capable network. Unlike full-text search, which only matches keywords, a graph supports multi-hop queries — for example, "find all tasks that have a dependency relationship with a certain project and whose owners have recently attended related meetings." This structure also makes "signal surfacing" possible: the system can identify collaboration partners and work priorities based on metrics such as relationship density and activity levels. For a data model like Jira's, which is already centered on tickets and people associations, graph-ification is a relatively natural extension.
How AI Benefits
This is the most imaginative part of the entire system. The video's author specifically emphasizes: "The AI tools you use can now tap into this context."
This means AI is no longer just answering questions in a vacuum — it can find specific information, answer questions relevant to the team's actual work, and even take action directly. More importantly, all of this happens under permission controls: AI can only see what you're allowed to see.
From a product logic perspective, this solves a long-standing problem that has hindered enterprise AI adoption: general-purpose AI tools lack internal enterprise context, and Teamwork Graph happens to provide that missing layer of context.
Context Windows and Retrieval-Augmented Generation (RAG)
What the article calls "AI accessing context" is typically implemented in enterprise scenarios through retrieval-augmented generation (RAG): the model itself doesn't have internal enterprise data built in; instead, before answering, it retrieves relevant fragments from external data sources and assembles them into the prompt for the model to generate an answer. Teamwork Graph plays exactly this "retrieval layer" role — it provides not only raw documents but also structured relationships like "who is responsible for what and which tasks depend on each other," making retrieval results more precise. Compared to cramming all data into a limited context window, RAG can fetch on demand, balancing cost and accuracy. This also explains why permission controls are critical: the retrieval stage must filter out content the user isn't authorized to access; otherwise, sensitive information could leak through model output.
A Signal Worth Watching
The video author's closing assessment is blunt: "If I were running a production project, this sounds like a lot of work, but for team productivity, this would be a home run."
This captures the dual nature of Teamwork Graph. On one hand, building such a data layer requires significant upfront investment; on the other hand, once it's running, it could fundamentally change how teams collaborate with AI.
For teams already deeply using Jira and Confluence, the value of this update may far exceed expectations — it turns AI from a "general-purpose assistant" into an "assistant that understands your team."
One-line Summary
Atlassian builds Teamwork Graph for Jira, using a unified data layer to provide AI with team context.
Paragraph Summary
The article introduces Teamwork Graph, a major update Atlassian is building for Jira — a system positioned as a "unified data layer and context engine" aimed at solving the data silo problem where critical information is trapped in isolated applications like Jira and Confluence. Its operation is divided into three layers: aggregating data from various applications, mapping collaboration and dependency relationships between data, and proactively surfacing signals about how work gets done. The most imaginative part is that AI can access this layer of context, enabling it to find information, answer questions, and even take action under permission controls — filling the gap where general-purpose AI lacks internal enterprise context. The author notes that building such a data layer requires significant upfront investment, but for teams already deeply embedded in the Atlassian ecosystem, the long-term productivity value could be very significant.
Related articles
GPT-6.2 Astra vs. Sol Controversy: Behind the Polarized Reviews
OpenAI's Astra and Sol 6.2 face review controversy: early testers panned them, then OpenAI said the version had been updated. A hands-on look at computer use, video editing strengths, communication weaknesses, and the shifting cost and subscription quota landscape.
Anthropic IPO and GPT-6.2 Astra: Data Dependencies and Safety Concerns Behind the Model Competition
In-depth analysis of Anthropic's IPO and GPT-6.2 Astra: model performance depends on training data, not universal intelligence; chain-of-thought monitoring is failing as a safety pillar.
Atlassian Teamwork Graph: Giving AI Agents Better Context
Atlassian leverages Jira's contextual advantage to build Teamwork Graph, connecting people, projects, documents, and code so AI agents deliver better output with fewer tokens.