KC-Maps: AI-Accelerated Molecular Dynamics Simulation Without Trajectory Data

KC-Maps learns SDE transition kernels using only trajectory-free marginal samples and known coefficients, accelerating simulation and saving GPU-hours.
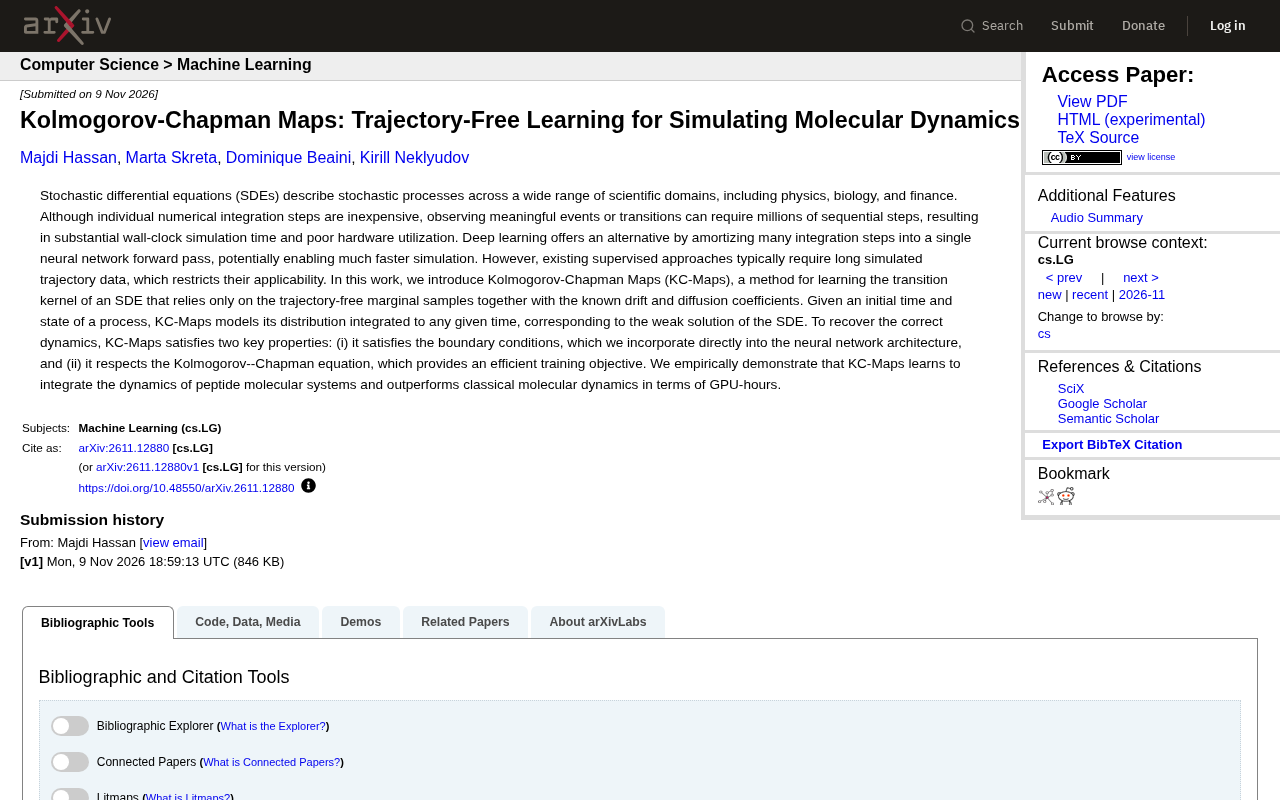
KC-Maps proposes an SDE simulation acceleration method that does not rely on long trajectory data. Instead of supervised training on numerically generated trajectories, it uses marginal distribution samples at each time point plus known drift and diffusion coefficients to learn the SDE transition kernel. It embeds the boundary condition into the network architecture and uses the Kolmogorov-Chapman equation to ensure multi-step consistency. Experiments on peptide systems show lower GPU-hour consumption than classical molecular dynamics.
Stochastic differential equations (SDEs) are a universal language for describing stochastic processes in physics, biology, finance, and other fields. Although single-step numerical integration is inexpensive, simulating meaningful events or state transitions often requires millions of sequential steps, resulting in long actual runtimes and low hardware utilization. Deep learning offers a shortcut: amortizing a large number of integration steps into a single neural network forward pass, thereby greatly accelerating simulation. However, existing supervised methods typically rely on long trajectory data, which limits their applicability. The recently proposed Kolmogorov-Chapman Maps (KC-Maps) attempt to break this bottleneck—learning the transition kernel of an SDE using only trajectory-free marginal samples and known drift and diffusion coefficients.
The Bottleneck of Existing Methods: Dependence on Trajectory Data
Traditionally, the approach to accelerating SDE simulation with deep learning is "imitation": first run a large number of numerical simulations to generate trajectories, then train a neural network to fit these trajectories. This approach has two obvious shortcomings. First, generating high-quality trajectories itself consumes substantial computational resources, which contradicts the original goal of accelerating simulation; second, the state space covered by trajectory data is limited, restricting the model's generalization ability. KC-Maps starts from a different point: it does not require long trajectories, and can learn the transition kernel from the initial time to any time using only marginal samples at each time point (i.e., trajectory-free distribution snapshots) plus the SDE's drift and diffusion coefficients. This amounts to directly modeling the weak solution of the SDE—given an initial time and state, predicting the distribution of the process at the target time.
The weak solution of an SDE refers to a stochastic process satisfying the following condition: its generator matches the differential operator of the given SDE, which is equivalent to saying that the transition probability distribution of the process satisfies the corresponding Fokker-Planck equation. Unlike the strong solution (solving pathwise given initial conditions and a Brownian motion path), the weak solution does not require pointwise trajectory matching, only that the probability distribution evolves correctly. KC-Maps learns the transition kernel in the weak-solution sense (i.e., the conditional distribution given the initial time and state), so it does not need to simulate any concrete trajectories and can be trained using only marginal distribution samples. This explains why KC-Maps can escape dependence on long trajectory data: it directly models distribution evolution rather than imitating individual trajectories.
The Core Mechanism of KC-Maps: Boundary Conditions and the Kolmogorov-Chapman Equation
The design of KC-Maps revolves around two key properties. First, it satisfies a boundary condition: when the target time equals the initial time, the transition kernel degenerates into a Dirac δ function. The research team encodes this constraint directly into the neural network architecture rather than softly penalizing it through the loss function, thereby guaranteeing that the model outputs the exact initial state at zero time interval. Second, it obeys the Kolmogorov-Chapman equation—this equation requires that the transition kernel from the initial time to the final time equals the integral of the transition kernels over all intermediate times (i.e., the Markov property). KC-Maps uses this equation to construct the training objective, so that the model automatically satisfies multi-step consistency during training. Together, these two properties ensure that the model recovers the correct dynamics rather than merely fitting the sample distribution.
The Kolmogorov-Chapman equation is the cornerstone of Markov processes, stated as: for any three times (t_0 < t_1 < t_2), the transition kernel satisfies (p(t_2, x_2 | t_0, x_0) = \int p(t_2, x_2 | t_1, x_1) p(t_1, x_1 | t_0, x_0) dx_1). Its physical meaning is: the transition probability from the initial state to the final state equals the sum (integral) of the path probabilities of first going to an intermediate state and then transitioning from it to the final state. This equation is a compatibility condition that the weak solution of an SDE must satisfy, and it is also the theoretical basis for the training loss constructed by KC-Maps—by forcing the model's integrated predictions over multiple intermediate times to be consistent with direct prediction, it ensures that the network learns a transition kernel consistent with the Markov property rather than merely fitting marginal distributions.
Experimental Validation: Peptide Molecular Systems and GPU-Hour Comparison
In the empirical section, the authors apply KC-Maps to dynamical integration of peptide molecular systems. The results show that KC-Maps can learn to integrate the dynamics of these molecular systems and outperforms classical molecular dynamics in terms of GPU-hours. Although the original text does not disclose a specific speedup factor, the conclusion that it "outperforms classical molecular dynamics in terms of GPU-hours" is sufficient to demonstrate its efficiency advantage. It should be noted that this advantage rests on the premise of using only marginal samples and known coefficients, thereby avoiding the expensive cost of trajectory data generation. For scenarios such as biomolecular simulation that require long-time evolution, KC-Maps offers an attractive alternative path.
Peptide molecular systems are small biomolecules formed by several amino acids linked through peptide bonds, commonly used as benchmarks in molecular dynamics simulation. Peptides have flexible chain structures, and their conformational changes involve motions across multiple time scales (from femtosecond-level bond vibrations to microsecond-level folding), so traditional MD simulation requires extremely small integration step sizes and extremely long simulation times to capture meaningful state transitions, resulting in high computational cost. Validation on such systems shows that KC-Maps can complete dynamical integration with fewer GPU-hours, indicating that the method has a practical efficiency advantage on challenging multiscale biomolecular systems.
Significance and Limitations
The value of KC-Maps lies in shifting the deep learning paradigm for SDE simulation from "trajectory supervision" to "distribution matching," lowering the data requirements. At the same time, by embedding physical constraints (boundary conditions) and mathematical structure (the Kolmogorov-Chapman equation) into the architecture design, the model gains better interpretability and generalization potential. However, the method relies on known drift and diffusion coefficients; for real systems with unknown coefficients, parameter estimation is still required first. In addition, current experiments focus on peptide molecular systems and have not yet validated more complex macromolecules or non-equilibrium processes. Future work may explore how to combine KC-Maps with coefficient learning to further broaden the scope of application.
One-line Summary
KC-Maps learns SDE transition kernels using only trajectory-free marginal samples and known coefficients, accelerating simulation and saving GPU-hours.
Paragraph Summary
KC-Maps proposes an SDE simulation acceleration method that does not rely on long trajectory data. Traditional deep learning methods require large amounts of numerically simulated trajectories for supervised training, which is costly and has limited generalization. KC-Maps instead uses marginal distribution samples at each time point together with known drift and diffusion coefficients to directly learn the SDE transition kernel. The model embeds the boundary condition (the transition kernel degenerates to a δ function at zero time interval) into the network architecture, and uses the Kolmogorov-Chapman equation to construct the training objective to ensure multi-step consistency. Experiments on peptide molecular systems show that KC-Maps consumes fewer GPU-hours than classical molecular dynamics simulation. The method corresponds to the weak solution of the SDE and currently relies on known coefficients with a limited experimental scope, but it provides a new idea for the deep learning paradigm of SDE simulation.
Related articles
Gemini 4 Hydrogen In-Depth Review: Real Value Beyond Cost-Effectiveness
Based on Artificial Analysis selection data and hands-on feedback, this review unpacks the Gemini 4 Hydrogen value paradox: high scores don't equal high value, performance splits across automation workflows and coding tasks, pricing and Google subscription bundles are separate ledgers, and SynthID output labeling could be a dealbreaker.
Gemini 4 Hydrogen Five Extreme Tests: 96.7% Accuracy and One-Prompt Website Building
A YouTube creator runs five extreme tests on Gemini 4 Hydrogen: single-prompt game generation, 3D solar system simulation, 30-minute video timestamp localization, converting a 287-page report into an interactive dashboard, and 96.7% accuracy in hallucination resistance.
Gemini 4 Hydrogen Released: A 2.5x Faster Everyday AI Model
Google releases Gemini 4 Hydrogen, claiming 2.5x the speed of Gemini 3.8 Flash, with four-tier thinking control, a million-token context, and Orchestrator multi-model collaboration. API pricing is $1.50 per million input tokens.