Krea2 Local Deployment: Component Selection for Photorealism and Prompt Accuracy

How RTX 3090 users can balance prompt fidelity and photorealism in Krea2 local workflows.
This article examines a Reddit discussion from an RTX 3090 (24GB VRAM) user seeking guidance on Krea2 workflow components, exploring the classic tradeoff between prompt adherence and photorealistic output in local AI image generation. It covers how text encoder architecture and structured controls like ControlNet drive prompt fidelity, while checkpoint training focus, sampler selection, and tiled upscaling govern photorealism. For 24GB VRAM setups, the article recommends prioritizing full main model loading, tiled upscaling to manage peak VRAM, on-demand LoRA loading, and leveraging 64GB RAM as a model cache. The author emphasizes that no universal solution exists — optimal results require iterative, scene-specific experimentation.
Background: A Typical Local Generation Scenario
In AI image generation, balancing photorealistic quality with high prompt fidelity under limited hardware constraints is one of the most persistent challenges for local deployment enthusiasts. A Reddit user running an RTX 3090 (24GB VRAM) with 64GB of system RAM recently sparked a discussion around component choices for Krea2-related workflows. While the original post was light on specifics, it touches on a broadly relevant technical question worth unpacking.
The Original Post: A Familiar Local Generation Dilemma
The poster's ask was straightforward — find the right component combination for maximum prompt adherence and photorealistic output when working with Krea2-related models. Their hardware setup:
- GPU: RTX 3090, 24GB VRAM
- RAM: 64GB
This is a mid-to-high-end consumer configuration for local inference. 24GB of VRAM is sufficient for most mainstream diffusion models and high-resolution workflows, though it can hit its ceiling when loading multiple large models, LoRAs, and high-res upscaling pipelines simultaneously.
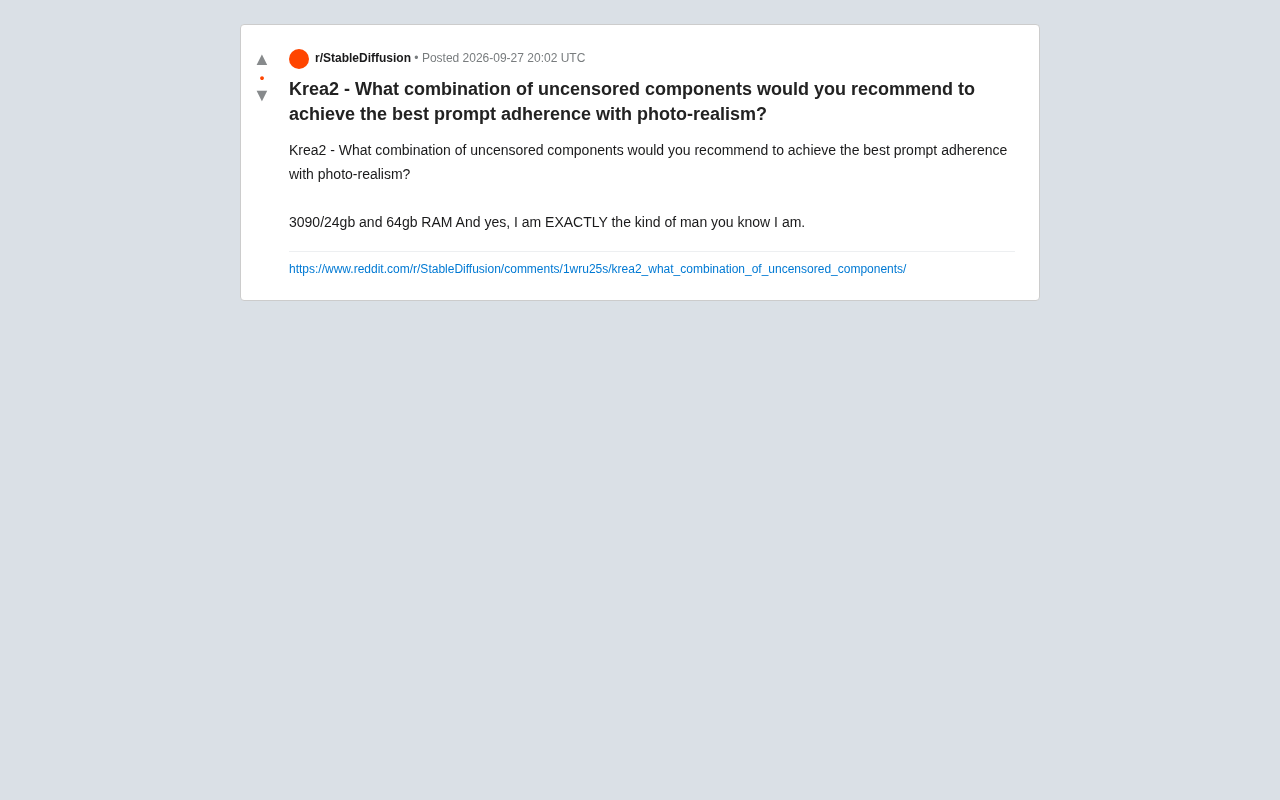
It's worth noting that the original post didn't include a specific model list or parameter configuration — it was more of an open-ended community question. So this article focuses on mapping out the key factors that influence image quality and prompt fidelity in local photorealistic generation.
Prompt Adherence vs. Photorealism: A Balancing Act
Many local users discover that prompt adherence and photorealism don't always improve together. Some highly photorealistic models — especially checkpoints fine-tuned heavily on real photographs — excel at rendering skin texture and light gradation, but may handle complex prompts less effectively than base models.
What Drives Prompt Adherence
Prompt-following ability is primarily determined by the underlying model's text encoder and training data. Using a more capable text understanding module, or introducing structured control mechanisms like ControlNet and regional prompting, typically yields meaningful improvements in composition and semantic fidelity. For users who prioritize precise control, workflow-level orchestration often matters more than simply swapping models.
The text encoder is the core component governing prompt adherence. Looking at the evolution of diffusion models: early SD 1.x used CLIP ViT-L as its text encoder, with limited vocabulary and semantic understanding that struggled with complex sentence structures and multi-concept combinations, often causing semantic drift. SD XL introduced a dual-encoder architecture (CLIP ViT-L + OpenCLIP ViT-bigG), significantly improving semantic capture for longer prompts. Newer architectures like Flux go further by incorporating large language models like T5-XXL as encoders, bringing natural language comprehension close to LLM-level capability — dramatically improving fidelity in scenarios involving compositional logic and attribute binding (e.g., correctly interpreting "red hat" rather than "red" and "hat" as separate concepts). ControlNet and similar structured control approaches add spatial constraints on top of semantic understanding, solving the distinct problems of "understanding what you say" versus "placing it where you want it."
What Drives Photorealistic Quality
Photorealism depends more on the checkpoint's training orientation, sampler selection, and the upscaling pipeline. The right number of sampling steps, appropriate denoising strength, and tile-based high-resolution upscaling can preserve fine detail while avoiding the dreaded "plastic" look.
Tiled upscaling (Tiled Upscale) is a critical step in local photorealistic workflows. The approach splits a large image into overlapping tiles, runs each through diffusion at low denoising strength, then seamlessly stitches them back together. This allows processing of 2K or 4K images without exceeding VRAM limits, while the upscaling pass can add micro-level detail like skin pores and fabric fibers — avoiding the blurriness of naive bilinear upscaling. Common implementations include the Ultimate SD Upscale node in ComfyUI and the equivalent script in A1111. Denoising strength selection is critical: too high destroys the original composition, too low yields minimal detail gain. The 0.2–0.4 range is the empirical sweet spot for most photorealistic scenarios, though the exact value depends on source resolution and target scale factor.
Sampler choice also affects photorealistic quality. Schedulers like DPM++ 2M Karras and DPM++ SDE Karras produce detail-rich results with naturally distributed noise even at lower step counts, while Euler a introduces more randomness at low steps — useful for exploring diversity but less ideal for stable, reproducible outputs.
Resource Allocation Recommendations for 24GB VRAM
For a 3090/24GB configuration, the core strategy is intelligently orchestrating the workflow within your VRAM budget:
- Prioritize keeping the main model fully loaded to avoid constant VRAM-to-RAM swapping
- Use tiled approaches for high-resolution upscaling to reduce peak VRAM spikes
- Load LoRAs and additional control modules on demand rather than all at once
- Use the 64GB of RAM as a model weight cache buffer to minimize repeated disk reads
Smart VRAM management consistently delivers better results than blindly chasing larger models.
The real bottlenecks with 24GB VRAM in current mainstream workflows tend to appear in two scenarios: single-pass high-resolution generation and multiple models resident simultaneously. Take SDXL as an example — the base model alone consumes roughly 6–7GB of VRAM. Add a Refiner model, multiple ControlNet weights (around 1.4GB each), and a high-precision VAE, and peak VRAM easily exceeds 20GB. Modern frontends like ComfyUI support on-demand model loading and unloading, enabling pipeline orchestration that avoids keeping multiple models resident at the same time. For larger models like Flux (the full version is approximately 23GB), FP8 or NF4 quantization is required to run stably within 24GB — though quantization introduces some detail loss, requiring a tradeoff between VRAM constraints and output quality. The 64GB of system RAM primarily serves as an in-memory model weight cache, avoiding repeated disk reads when switching models. The benefit is relatively modest for NVMe SSD users but significant for those on mechanical hard drives.
The Value and Limits of Community Discussions
Posts like this one are valuable because they reflect the genuine dual demand in the local generation community for controllability and image quality. However, since the original post lacks specific component names, parameters, or generated examples, its reproducibility is quite limited.
For readers aiming to achieve similar results, the more pragmatic approach is: clearly define your primary goal (is composition control the priority, or texture quality?), then select models and workflows aligned with that goal, and iteratively tune parameters through small-batch testing. There's no one-size-fits-all combination — the optimal solution almost always emerges from repeated experimentation with specific use cases.
Summary
At its core, the discussion around Krea2 represents the classic tradeoff that has always defined local AI image generation: how to simultaneously approach photorealistic texture and semantic precision under constrained hardware. An RTX 3090 with 64GB of RAM offers enough headroom for meaningful experimentation. The key is understanding each component's contribution to the final output, and making deliberate tradeoffs within the constraints of your VRAM budget.
Related articles

Gaussian Process Bandit Optimization: Exploration Strategies and Inference Regret Guarantees
Cumulative regret guarantees in Bayesian optimization fail to reflect final recommendation quality. This article examines a new study that provides inference regret guarantees for Gaussian process bandit optimization through exploration query strategies and fill distance analysis, validated on hyperparameter optimization and control tasks.

The Most Detailed Codex Guide on Bilibili: From Installation to Real-World Practice
The most detailed Codex guide on Bilibili: from app store installation to daily work mode configuration, with a real coffee shop project demonstrating file organization, data extraction, dashboard creation, and other practical tasks. Learn to use Plan Mode and desktop pets to leverage Codex efficiently.

Appearance Compensation in Volume Rendering: Why RGB Accuracy Cannot Guarantee Density Correctness
Volume rendering research reveals that volumetric data perfectly reproducing external RGB views may still contain density errors: appearance compensation can double central density and keep external rays unchanged even when L2 error exceeds 14.52%. Density recovery depends on appearance capacity, spatial resolution, and measurement design.