LangGraph Agent Memory Staleness: How to Prevent Agents from Making Decisions on Outdated Data

How LangGraph agents silently use stale memory — and practical strategies to fix it.
LangGraph agents with persistent memory face a subtle but critical problem: stale memories are used silently without any errors. Vector retrieval understands semantic relevance but ignores timeliness, so outdated facts keep surfacing. This article evaluates three common fixes — full rebuild (too costly), TTL timestamps (mismatched to data change rhythm), and proactive invalidation (architecturally complex) — and proposes more practical approaches: decoupling memory from sources, adding freshness scoring, and triggering explicit conflict resolution instead of silently adopting a single memory.
When building LangGraph agents with persistent memory, many developers hit the same wall: stale memory. This isn't an explicit error that throws an exception — it's a silent logic trap. The agent confidently makes decisions based on facts that were valid a few sessions ago but are no longer true today.
The Core Problem: Silent Stale Data
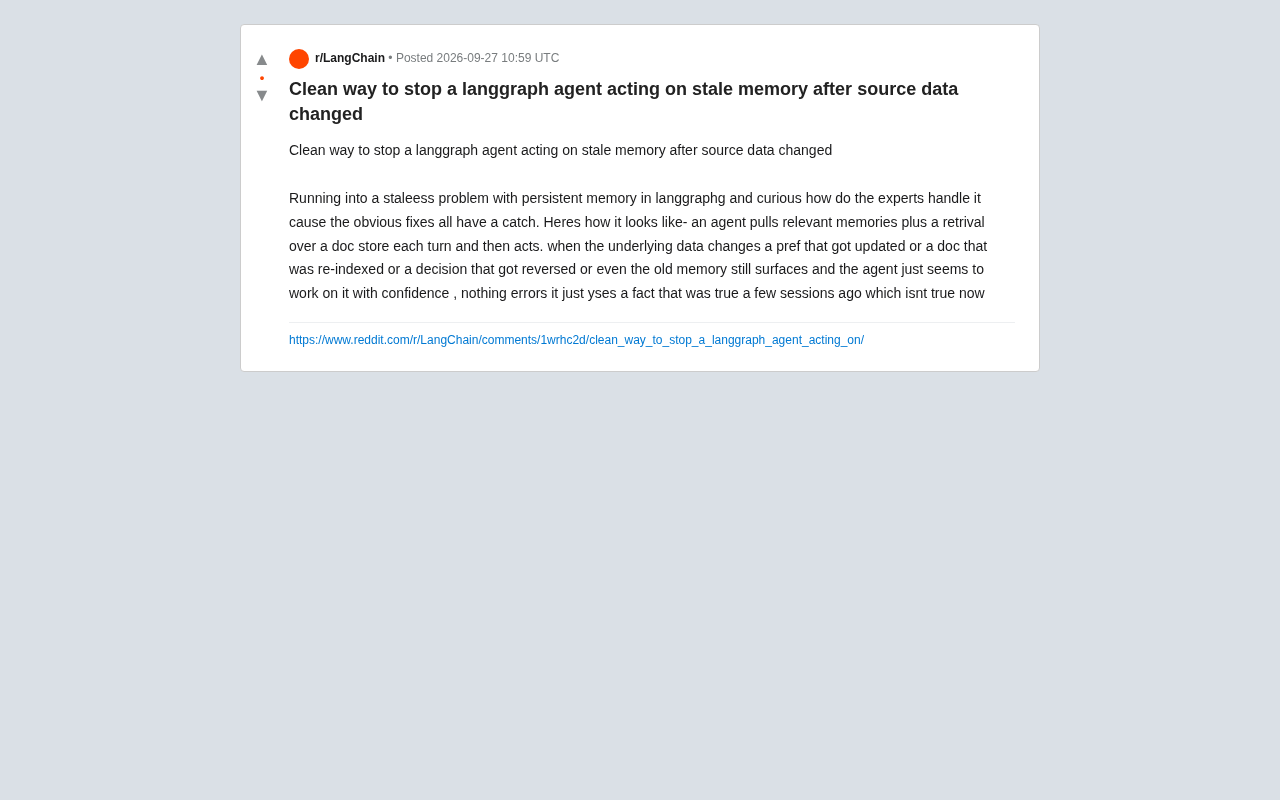
A Reddit developer described a classic scenario: the agent pulls relevant memories each conversation turn, runs retrieval against a doc store, and then acts accordingly. When the underlying data changes — a user preference is updated, a document is re-indexed, a decision is reversed — the old memory still surfaces, and the agent uses it without hesitation.
"nothing errors it just uses a fact that was true a few sessions ago which isn't true now."
This is what makes memory systems so tricky: there's no alarm between correctness and availability. Retrieval systems care about "relevance" but can't judge "timeliness." A semantically high-matching stale memory is often recalled over a less-matching but current one — overriding the correct answer.
From an information retrieval perspective, the root cause lies in how vector stores work. LangGraph's persistent memory is typically stored as vector embeddings, retrieved via cosine similarity or approximate nearest neighbor (ANN) algorithms to match semantically relevant entries. These systems are designed to be "semantically lossless" — they know how close two pieces of text are in meaning, but they're completely blind to the time dimension. A memory like "user prefers dark mode" occupies nearly the same position in embedding space whether it was written three years ago or yesterday. The retrieval engine has no way to distinguish. This stands in sharp contrast to traditional relational databases, where a SQL query can easily add a WHERE updated_at > ... filter. The semantic-first nature of vector retrieval means time filtering must be implemented as a separate metadata layer — one that most developers overlook when building prototypes.
Why the "Obvious Fixes" All Have a Catch
The original poster astutely noted that the most straightforward solutions "all have a catch." Here's a breakdown of the common approaches and their trade-offs:
Option 1: Fully Rebuild Memory Each Round
The direct approach is to regenerate memories from source data every turn, eliminating stale content entirely. But this introduces massive latency and cost, and throws away the cross-session continuity that persistent memory is supposed to provide — effectively degrading the memory system into plain real-time retrieval.
Option 2: Add Timestamps and TTL to Memories
Attach a timestamp or time-to-live (TTL) to each memory entry, expiring it when it ages out. The problem: data changes at unpredictable rates. A document might go unchanged for a year, or be updated three times in a day. A fixed expiration window either deletes too early (losing valid information) or too late (stale data keeps causing problems).
Option 3: Proactive Invalidation on Data Change
A more engineering-forward approach is to build a mapping between data sources and memories, actively invalidating associated memories when a source document is re-indexed or a preference is updated. This is architecturally cleaner but requires tracking the "source fingerprint" of every memory, placing higher demands on system observability and data pipelines.
This approach aligns closely with content-addressable storage and event-driven architecture patterns. Concretely, you record a "source fingerprint" for each memory — typically the hash or version number of the source document. When a document is re-indexed, the data pipeline publishes an invalidation event downstream, and the memory management layer marks all memories referencing that source fingerprint as pending verification or deletes them outright. This essentially reframes the memory consistency problem as a classic cache invalidation problem — one for which distributed systems already offer many mature patterns, such as async invalidation via message queues and conflict detection via version vectors. The trade-off is a significant increase in system complexity: you need a reliable event bus and comprehensive observability across the entire data change pipeline.
More Practical Engineering Approaches
Drawing from community discussion, several directions are worth pursuing in production systems:
Decouple memory from factual sources. Rather than baking "facts" directly into memories, store "references to sources" instead. The agent validates at runtime whether the source is still current, leaving mutable facts to the retrieval layer for real-time fetching — and only persisting stable preferences and historical interaction patterns as long-term memory.
Introduce version numbers and freshness scoring. Maintain version identifiers for both memory entries and source documents. At retrieval time, rank not just by semantic similarity but also by a freshness weight. When conflicting memories exist on the same topic, prioritize the higher-versioned entry and actively retire older versions.
Conflict detection over silent adoption. Rather than letting the agent quietly use a single memory, trigger explicit reasoning or clarification when multiple relevant but contradictory memories are retrieved. Turning "staleness" from a silent error into a detectable signal is a critical step in controlling this class of problem.
Deeper Implications for Memory System Design
This seemingly specific LangGraph problem actually touches on a fundamental tension in all agent memory architectures: the value of persistence lies in remembering, while the requirement of correctness lies in forgetting. A robust memory system must support all four capabilities — writing, recall, updating, and invalidation — yet most current frameworks handle the first two well while largely neglecting the latter two.
The pragmatic stance for developers is: don't chase a "perfect fix." Instead, make an explicit trade-off between cost, latency, and accuracy based on how time-sensitive your business domain is. Route time-sensitive facts through real-time retrieval, let stable user profiles live in long-term memory, and establish clear invalidation boundaries between the two — this is probably the cleanest solution available today.
Cognitive science's classification of human memory offers a useful reference framework for agent memory architecture design. Researchers typically distinguish between episodic memory (records of specific experiences), semantic memory (abstract concepts and facts), and procedural memory (skills and habits). In agent system design, these three types have very different sensitivity to staleness: episodic memory (e.g., "the user mentioned X in our last session") naturally carries a timestamp and suits a TTL strategy; semantic memory (e.g., "the user's professional background") changes slowly but does expire, suiting version tracking; procedural memory (e.g., "the user prefers short responses") is relatively stable and can be retained long-term. Separating these three memory types at the storage layer and applying different invalidation strategies to each is a practical entry point for building more robust memory systems — and a design dimension that is still rarely discussed systematically in the LangGraph ecosystem.
Related articles

Free Unlimited Claude Code Solution: Agnes AI + CC Switch Setup Guide
No paid subscription needed — pair the free AI platform Agnes AI with the open-source tool CC Switch to provide a backend for Claude Code, enabling unlimited free calls to text, image, and video models. This guide covers the full setup, test results, and usage boundaries.

A Complete Zero-Cost Guide to Getting Started with Claude Code for Beginners in China
A beginner's guide to Claude Code for users in China: two installation methods (command line and IDE plugin), full configuration steps for replacing the official API with the free domestic LongCat model, and a hands-on demo of building a small tool with natural language, plus tips.

When the NSA Gets Involved: The AI Supply Chain Crisis Behind Open-Source CVEs and API Key Hijacking
Multiple open-source projects disclosed severe CVEs in one day, PHP flaws alarmed the FBI, and Railway and OpenCode were breached with API keys stolen. This article breaks down the vulnerability window, AI-accelerated exploitation, and the AI supply chain crisis behind the API key black market, with a developer defense checklist.