LLM Judge in Production Traffic: A Practical Guide from Flagging to Closed Loop
The value of an LLM Judge isn't scoring but driving a quality loop where production traffic feeds offline evals.
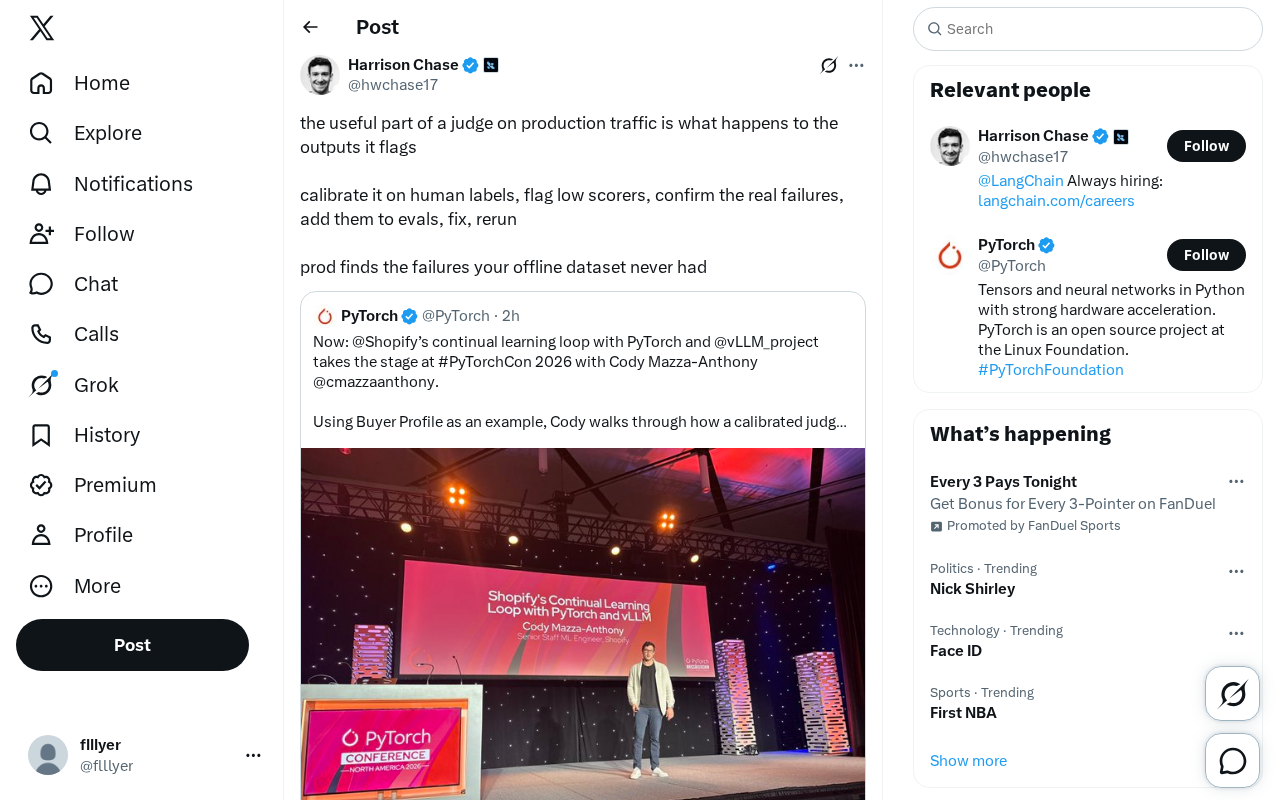
The article notes that offline eval sets only cover failure modes developers imagined, while real users create unexpected edge cases. A Twitter perspective argues the real value of an LLM Judge on production traffic is not the scores but what happens to flagged outputs. It redefines the Judge as a failure discovery engine and lays out a five-step loop: calibrate with human labels, flag low scores, confirm real failures, add them to evals, and fix and rerun — connecting offline evaluation with production monitoring.
Why Your Offline Eval Set Is Never Enough
In LLM application development, offline eval sets are the foundation of quality assurance, but they have a fundamental flaw: they only cover the failure modes you thought of. Real users will use your product in ways you never anticipated, producing edge cases that don't exist in your offline dataset.
A practical perspective from Twitter points out that the real value of deploying an LLM Judge on production traffic is not the scores it gives, but what happens to the outputs it flags afterward. In other words, the Judge is not the endpoint — it's the starting point of a quality closed loop.
This perspective is worth unpacking — it redefines the Judge from a "scoring tool" into a "failure discovery engine."
The Right Way to Use a Judge: A Five-Step Closed Loop
The original tweet lays out a concise but complete operational chain:
calibrate it on human labels, flag low scorers, confirm the real failures, add them to evals, fix, rerun
Broken down, these five steps form a continuously running quality flywheel:
1. Calibrate the Judge with Human Labels
The Judge is itself a model, and it makes mistakes. Before using it on production traffic, you must calibrate its judgment criteria with human-labeled samples. This step determines the reliability of all downstream signals — a "low-score output" flagged by an uncalibrated Judge may be largely false positives, and the team will burn out in the noise.
The core of calibration is aligning the Judge's score distribution with human expert judgment, especially on edge cases.
LLM Judge refers to the mechanism of using another large language model to automatically score or classify the output of a target model. A common approach is to provide a rubric and the output to be evaluated, and have the Judge produce a score, label, or rationale. Its advantages are strong scalability and far lower cost than human review, but it is still fundamentally a probabilistic model with systematic biases: it may favor longer answers, be sensitive to specific phrasing, or be unstable on edge cases. Therefore "calibration" is not an optional step — an uncalibrated Judge is like a sensor with unknown bias, whose flagged results cannot be used directly as quality signals. Calibration typically includes: building a human-labeled set covering typical and edge cases, computing agreement between the Judge and human ratings (e.g., accuracy, Kappa coefficient), adjusting prompts or rubrics, and if necessary fine-tuning the Judge on labeled data.
2. Flag Low-Scoring Outputs
Once calibrated, have the Judge continuously scan production traffic and flag outputs with low scores. The "low score" threshold should be set according to business tolerance, rather than mechanically picking some fixed value.
3. Confirm the Real Failures
This is the step most easily skipped, yet the most critical. A low score flagged by the Judge does not equal a real failure — human review is needed to confirm which are genuine model problems and which are Judge misjudgments or unreasonable user inputs. This step converts "signals" into "knowledge."
4. Add to the Eval Set
Confirmed real failure cases should be added to the offline eval set. This is exactly the core insight of the original tweet: production traffic can find failures your offline dataset never had. Each addition brings the offline eval closer to the real-world distribution.
The data distribution of an eval set determines how much real risk offline evaluation can reflect. If the eval set mainly comes from developers' imagination or early samples, it will systematically underestimate the proportion of long-tail scenarios. Adding confirmed failure samples from production traffic to the eval set is essentially distribution correction: gradually bringing the failure-mode distribution of the eval set closer to the real failure distribution of the production environment. In practice, care should be taken to avoid the eval set being dominated by a single type of failure; it can be managed in layers by failure type, user scenario, input length, and other dimensions, with each sample recording its source, failure reason, and expected behavior. In this way, the eval set is not only a collection of regression test cases but also a traceable knowledge base of failures.
5. Fix and Rerun
Fix the confirmed failures (adjust prompts, add data, modify logic, etc.), then rerun the eval set to verify. The loop is completed here, and the next round of production traffic will bring new failure samples.
Why This Closed Loop Works
The traditional approach treats offline evaluation and production monitoring as two independent stages: the offline set ensures launch quality, while production monitoring watches metric fluctuations. But there is no feedback path between them, and the offline set gradually drifts away from real usage scenarios.
The Judge-driven closed loop connects the two: production traffic becomes a continuous supply source for the offline eval set, and the offline eval set becomes the verification baseline for fix effectiveness. This two-way flow turns quality assurance from "one-time gatekeeping" into "continuous evolution."
Another easily overlooked point is the cost structure. Compared with full manual review of production outputs, the Judge only does initial screening, and humans only review the small number of flagged samples, concentrating manpower where the information value is highest.
A Few Things to Watch in Practice
Judge calibration is not a one-time task. As the product iterates and user behavior changes, the Judge's judgment criteria may drift and need periodic recalibration with new human labels.
The false positive rate determines whether the loop can run. If the proportion of real failures among the low-score outputs flagged by the Judge is too low, the burden of human review will overwhelm the process. Calibration should focus on optimizing this.
Failure attribution must be specific. When adding a failure to the eval set, record the failure type and context; otherwise the eval set only grows in quantity without improving in quality.
Loop speed is a key metric. The shorter the time from discovering a failure in production traffic to fixing and shipping, the smaller the window during which users are exposed to the problem. This cycle itself is worth measuring and optimizing.
False positive rate and recall are the two core metrics for measuring the quality of a Judge's initial screening. A false positive is an output the Judge flags as a failure but is actually normal, which directly translates into wasted human review effort; a miss is a real failure that is not flagged, causing the problem to escape to the user side. There is a trade-off between the two: lowering the threshold increases recall but also false positives, and raising the threshold does the opposite. Whether the loop can keep running depends on whether the false positive rate is kept within what the team's manpower can bear. During calibration, you should plot the false positive/miss curve at different thresholds and choose an operating point based on human review capacity, rather than pursuing a single optimal score.
Conclusion
The value of an LLM Judge on production traffic is not in the scores, but in the closed loop it initiates: "flag — confirm — add — fix — rerun." The production environment is the only place that can expose the real failure distribution. Only by feeding this signal into the offline evaluation system can quality assurance keep up with how the product is actually used.
One-line Summary
The value of an LLM Judge is not in scoring, but in driving a quality closed loop where production traffic feeds back into offline evaluation.
Paragraph Summary
The article points out that the fundamental flaw of offline eval sets is that they only cover failure modes developers thought of, while real users produce unexpected edge cases. A practical perspective from Twitter holds that the real value of deploying an LLM Judge on production traffic is not the scores themselves, but what happens to the outputs it flags. The article redefines the Judge as a "failure discovery engine" and breaks down a five-step closed loop: calibrate the Judge with human labels, flag low-scoring outputs, manually confirm real failures, add failure samples to the eval set, and fix and rerun to verify. This closed loop connects the previously disconnected offline evaluation and production monitoring, making production traffic a continuous supply source for the eval set and the offline eval set a verification baseline for fix effectiveness. The article also discusses practical considerations such as calibration drift, false positive rate, failure attribution granularity, and loop speed.
Related articles

Free Unlimited Claude Code Solution: Agnes AI + CC Switch Setup Guide
No paid subscription needed — pair the free AI platform Agnes AI with the open-source tool CC Switch to provide a backend for Claude Code, enabling unlimited free calls to text, image, and video models. This guide covers the full setup, test results, and usage boundaries.

A Complete Zero-Cost Guide to Getting Started with Claude Code for Beginners in China
A beginner's guide to Claude Code for users in China: two installation methods (command line and IDE plugin), full configuration steps for replacing the official API with the free domestic LongCat model, and a hands-on demo of building a small tool with natural language, plus tips.

When the NSA Gets Involved: The AI Supply Chain Crisis Behind Open-Source CVEs and API Key Hijacking
Multiple open-source projects disclosed severe CVEs in one day, PHP flaws alarmed the FBI, and Railway and OpenCode were breached with API keys stolen. This article breaks down the vulnerability window, AI-accelerated exploitation, and the AI supply chain crisis behind the API key black market, with a developer defense checklist.