Long Context Isn't Necessary: Compressing Short Context Preserves Task Accuracy

Frequent compaction to keep a short context preserves accuracy on long tasks—long context isn't essential.
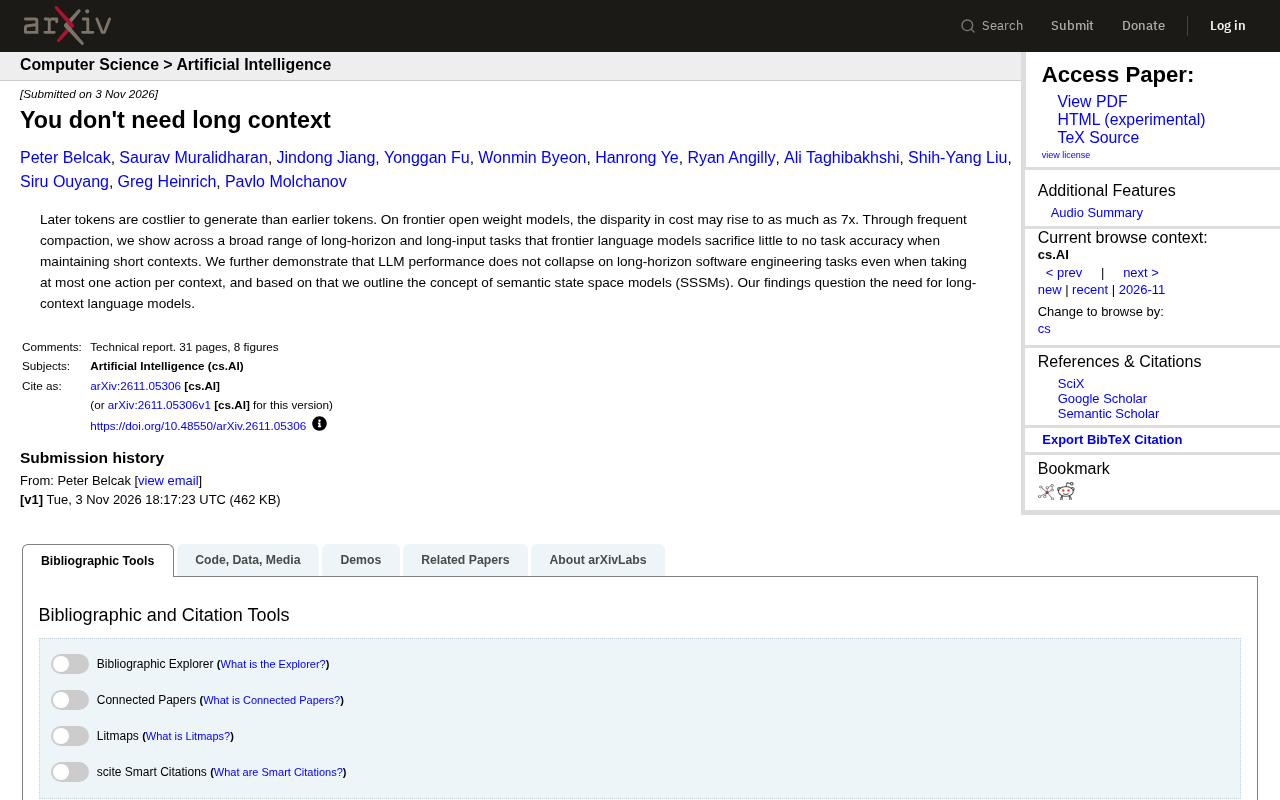
Based on an RSS source analysis, the article notes that later tokens in autoregressive generation cost more—up to 7x on frontier open-weight models—because each new token attends to all prior tokens. Researchers tested a "frequent compaction" strategy that periodically compresses history into shorter summaries or state representations so the model always works in a short context window, and found almost no accuracy loss across long-horizon and long-input tasks. In long-horizon software engineering experiments, LLM performance holds even when only one action's context is kept per step. The article thus introduces Semantic State Space Models (SSSMs), arguing for replacing long history with compressed semantic state and questioning the necessity of blindly expanding context windows, since compressed short contexts offer cost and engineering advantages.
Introduction
Large language model (LLM) context windows keep expanding, from a few thousand tokens to hundreds of thousands, and the industry seems to have accepted a default assumption: "longer context = stronger capability." But an analysis from an RSS source argues the opposite: maintaining a short context with frequent compaction barely sacrifices task accuracy on frontier open-weight models, and can even substantially reduce generation cost. The analysis also introduces the concept of Semantic State Space Models (SSSMs) and questions the necessity of long-context models.
Later-generated tokens are more expensive
The analysis points out that the further back a token is generated, the more expensive it becomes. On frontier open-weight models, this cost difference can be as high as 7x. This isn't purely a hardware or algorithm issue—it stems from the nature of autoregressive generation: each new token requires attention computation against all previous tokens, so the longer the sequence, the greater the per-token compute. As a result, even if a model supports long context, generating the latter half of a long sequence is significantly more expensive than the beginning.
This finding directly challenges the intuition that "the longer the context, the better." If keeping a short context preserves performance, then using a long context not only wastes compute but may also drive up inference latency and cost.
The cost difference here stems from the self-attention mechanism of the Transformer decoder. During autoregressive generation, each new token must compute attention weights against all existing tokens in the sequence, and the computational complexity grows quadratically with sequence length (O(n²)). So generating the 1000th token requires far more compute than generating the 1st. The "7x" figure is an empirical value measured under a specific model and sequence length; the exact multiplier varies with model size, sequence length, and hardware efficiency. It's important to understand this: long context is not "free" capacity—it translates into real overhead in inference time and cost. This also explains why, even when models claim to support ultra-long context, cost must still be weighed in actual deployment.
Frequent compaction preserves accuracy
Researchers tested frontier language models on a variety of long-horizon and long-input tasks using a frequent compaction strategy. Frequent compaction means periodically compressing the historical context into a shorter summary or state representation during task execution, so that the model always works within a short context window.
The results showed that across a broad range of tasks, the model barely sacrificed task accuracy. This means that for many practical applications, we don't need to stuff the entire conversation history or document into the context window; instead, we can maintain a compact state through dynamic compression.
Context compression typically has three engineering implementation paths: first, summary-based compression, using an LLM to condense historical dialogue or documents into shorter text; second, state-based compression, maintaining a structured memory object (such as task progress or confirmed facts) that is updated incrementally at each step; third, retrieval-based compression, keeping only the fragments relevant to the current step and storing the rest in external storage for on-demand recall. The challenge of frequent compaction lies in the trade-off of "what to compress and what to discard"—over-compression loses critical details, while under-compression loses the cost advantage. The claim of "barely sacrificing accuracy" in the original article is a result observed under specific tasks and compression strategies, and does not mean that any compression is lossless. In practice, compression frequency and granularity need to be tuned according to the information density of the task.
Long-horizon software engineering tasks: no collapse even with one action per step
The analysis also specifically examined long-horizon software engineering tasks. Experiments showed that even when the model executes only one action per context (i.e., clearing or compressing the context after each step), LLM performance does not collapse. The traditional view holds that long tasks require retaining the full history to maintain coherence, but this experiment gives a different answer.
This result has direct implications for the design of AI coding agents: an agent doesn't need to rely on ultra-long context to remember all code modification history; it can maintain task continuity through compressed state or external memory. This not only reduces the cost of each inference but also avoids the attention dilution problem caused by long context.
Semantic State Space Models (SSSMs)
Based on these findings, researchers proposed the concept of Semantic State Space Models (SSSMs). Although the original article does not give a complete mathematical definition of SSSMs, it can be inferred from context that SSSMs aim to replace long-context history with a compressed semantic state, similar to how state space models summarize sequence information with a hidden state.
The core idea of SSSMs is that the model does not need to explicitly retain all historical tokens but instead maintains a semantic state that is updated and compressed at each step. This both controls context length and preserves the key information needed for the task. If this concept is further developed, it could lead to more efficient architectures for handling long tasks and reduce reliance on long context windows.
A State Space Model (SSM) is a class of sequence modeling architectures whose core is to recursively summarize historical information with a hidden state vector, updating the state at each step based on new input rather than retaining all historical tokens as Transformer does. Classic examples include S4 and Mamba, which have linear or near-linear computational complexity in long-sequence modeling. SSSMs borrow this idea but extend the "state" from a numerical hidden vector to a compressed representation at the semantic level—for example, a natural language summary or structured memory. The difference between the two is that the state of a traditional SSM is determined by model parameters and the training process and cannot be directly interpreted, whereas the semantic state of an SSSM is closer to a human-readable summary of the task context, making it easier to interface with the LLM's prompt interface. SSSMs are currently more of a conceptual framework, and their specific training objectives and update mechanisms remain to be clarified.
Doubts about long-context models
The analysis ultimately questions the necessity of long-context language models. Although long context still has value in certain scenarios (such as full-text retrieval and multi-document reasoning), experiments show that by compressing short context, models can maintain accuracy on long-horizon tasks. This means that blindly pursuing larger context windows may not be the optimal path.
From a cost perspective, generating the latter tokens of a long context costs up to 7x more, while frequent compaction can significantly reduce inference overhead. From an engineering perspective, maintaining a short context also simplifies memory management and improves inference speed. Of course, compression strategies themselves carry the risk of information loss, and how to design efficient compression algorithms remains an open problem.
Conclusion
This analysis provides a perspective cross-validated by multiple sources: cost differences, frequent compaction experiments, long-horizon software engineering tasks, and the SSSM concept all point to one conclusion—long context is not a necessary condition for many tasks. For AI application developers and researchers, this means more attention should be paid to context compression and state maintenance techniques rather than simply expanding context windows. In the future, ideas such as SSSMs may drive more economical and efficient language model architectures.
Related articles

9 AI Subscription Plans Compared: The Real Cost Per 100M Tokens Revealed
Bilibili creator tests 9 AI subscription plans from Volcano, Alibaba, Tencent, Baidu, Zhipu, Xiaomi, MiniMax and more, converting them all to real cost per 100M tokens, breaking down fixed-quota vs. three-tier coefficient billing and how caching, time-of-day discounts, and window limits affect actual quota.

Vibe Coding for Beginners: Expressing Intent Instead of Handwriting Code
What is Vibe Coding? A 137-episode Bilibili course defines it: the core is expressing intent, not writing code. This article analyzes Vibe Coding's productivity logic, target audience, and entry expectations to help beginners decide if it's worth learning.

LangChain Beginner's Guide: An Agent Development Roadmap from LangGraph to Deep Agents
Clarify the encapsulation relationship among LangChain, LangGraph, and Deep Agents, and master the learning path and selection logic for agent development frameworks—suitable for beginners in large model development.