Microsoft Foundry: Bigger Models Aren't Always Better—Choosing the Right Model Matters More Than Prompts
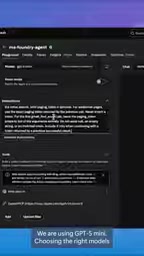
Choosing the right model matters as much as good prompts; small models can cost one percent of large ones.
The article argues that in AI application development, model selection can rival prompt engineering in impact, yet developers habitually reach for the largest models—driving up cost and latency without guaranteed gains while overlooking small models that run on phones and cost one percent as much. Prompt engineering solves "how to communicate"; model selection solves "who solves it." The right approach is to understand the problem and desired outcome first, then match models rationally to the task.
In AI application development, a widely overlooked truth is coming to light: choosing the right model may matter just as much as writing good prompts. Discussions around the Microsoft Foundry platform point out that developers often fall into the "bigger is better" trap, overlooking the enormous cost advantages that small, efficient models can deliver.
Model Selection Matters as Much as Prompt Engineering
In the Microsoft Foundry discussion, a core point is made explicitly: choosing the right model and understanding which one to deploy for a specific problem can have an impact comparable to doing good prompt engineering. This means developers shouldn't spend all their energy polishing prompts—they should start from the essence of the task and match the most suitable model.
Prompt engineering is certainly important, but it addresses the question of "how to communicate with the model"; model selection addresses the question of "who solves the problem." If you get the latter wrong, even the most ingenious prompts may yield half the result with twice the effort.
Big-Model Obsession: A Common Development Pitfall
The speaker candidly admits to having "failed" moments—always gravitating toward exploring the biggest, most powerful models. This mindset is quite common among developers: when facing a new task, the first instinct is to call the model with the largest parameter count, assuming it will surely deliver the best results.
The consequences of this habitual thinking are obvious: soaring costs, slower responses, and no guaranteed substantive improvement in task performance. More critically, it causes developers to miss the lightweight options that are genuinely well-suited to their scenarios.
The Overlooked Value of Small Models: Same Task, One Percent of the Cost
The speaker points out that people have stopped paying attention to smaller, more efficient models—models that can even run on a phone yet accomplish the same tasks at perhaps one percent of the cost of large models. That's an order-of-magnitude difference.
For a large number of routine tasks, small models are entirely sufficient. Using expensive large models for simple classification, extraction, summarization, and similar scenarios is essentially a waste of resources. The truly professional approach is to select models in tiers based on task complexity.
The relationship between model parameter scale and capability is not linear. The parameter scale of large language models is typically measured in billions (B); the more parameters, the stronger the model's performance generally is in complex reasoning, long-context understanding, multilingual capability, and more—but this improvement shows clear diminishing marginal returns. For tasks with relatively fixed structures—classification, information extraction, text summarization, sentiment judgment—models with a few billion or even fewer parameters can often achieve accuracy close to that of hundred-billion-parameter models. At the same time, inference cost is highly correlated with parameter scale: the compute consumed per call, memory footprint, and latency all rise significantly as models grow. So "small models cost only one percent" is not an exaggeration—it's the real economic difference brought about by model tiering. Understanding this trade-off is the technical prerequisite for making rational model choices.
How to Make the Right Model Choice
The speaker offers a clear decision path: if you understand the problem itself and know what kind of result you want, you should be able to choose the model that can equally handle the job.
This requires developers to have two capabilities: first, accurately break down task requirements and clarify output standards; second, have a clear understanding of the capability boundaries of candidate models. On this basis, model selection is no longer a gut-feeling "bigger is better" but a rational decision based on task fit.
This philosophy emphasized by Microsoft Foundry is essentially pushing AI development from "stacking resources" toward "precise matching." For teams pursuing cost-effectiveness and sustainability, this may be a more worthwhile investment than chasing the most powerful model.
Model selection can be grounded in systematic evaluation methods rather than intuition alone. A common approach is to build a small-scale task evaluation set, organizing typical real-world inputs and expected outputs into samples, then having candidate models run against them one by one, comparing accuracy, latency, and per-call cost across three dimensions. In addition, a "routing" strategy can be adopted: first use a small model to handle requests, then escalate to a large model when confidence is insufficient or task complexity exceeds a threshold—balancing quality and cost overall. Model catalogs and evaluation tools provided by platforms like Microsoft Foundry are precisely designed to lower the barrier to such comparative experiments, enabling developers to support model selection decisions with data rather than impressions.
One-line Summary
Choosing the right model matters as much as writing good prompts—small models can cost as little as one percent of large models.
Paragraph Summary
The article points out that in AI application development, model selection can have an impact comparable to prompt engineering, yet developers commonly fall into the "bigger is better" trap, habitually calling the largest models. This inertia leads to soaring costs and slower responses without necessarily improving results, while causing people to overlook small models that can run on a phone, accomplish the same tasks, and cost only one percent of large models. The article emphasizes that prompt engineering addresses "how to communicate," while model selection addresses "who solves the problem"—getting the latter wrong means half the result with twice the effort. The right approach is to first understand the essence of the problem and the desired outcome, then make rational model choices based on task fit, moving AI development from "stacking resources" toward "precise matching."
Related articles

Gemini 4 Neon Review: Benchmark Scores Rival Carbon, API Pricing and Quota Breakdown
Google Gemini 4 Neon is now live, benchmark scores closely tracking Carbon, API pricing 3/15 at twice Hydrogen's rate. This article compiles Bilibili creator testing: Neon can replace 90% of Carbon scenarios, AntiGravity quota consumption is only one-third of Carbon, plus subscription channel restrictions and 2API ban risks.

Gemini 4 Helium Coming Soon? Signals of Google Loosening Subscription Restrictions
Google team member hints releases will continue; community speculates Gemini 4 Helium (Flash Lite) may be next. Subscription ban controversy gets a response as product lead says "Soon," suggesting restrictions may be lifted. This article covers Gemini developments, OpenAI Coding Agent and risk management, Doubao real-time audio-video API, and compute business dynamics.

AI-Assisted React Development in Practice: Optimizing a Video App and Handling Errors
A 14-year veteran developer demonstrates AI-assisted React video app optimization: compressing video from 80MB to 5MB (~94%) via ImageKit, plus reliable error handling and retry mechanisms. Includes planning, code understanding, and verification methods for working with AI.