ModHarness-RL: Letting the Agent Training Framework Evolve Itself
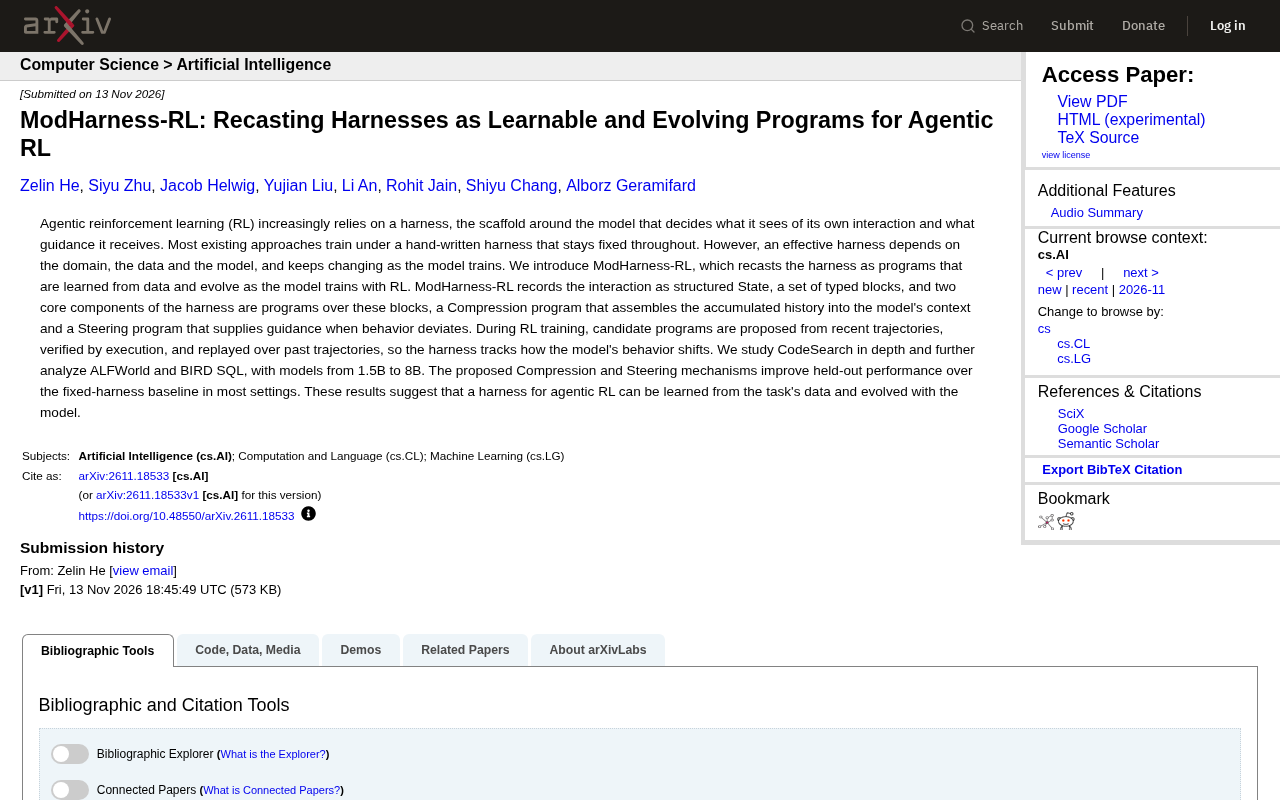
ModHarness-RL turns the hand-written harness of agentic RL into a learnable program that evolves with the model.
This article introduces ModHarness-RL, which addresses the bottleneck in agentic RL where fixed hand-written harnesses struggle to adapt to dynamic models. The method redefines the harness as a learnable, evolvable program built on typed structured states, with compression and steering programs as core components. A propose-verify-replay loop enables the harness to track changes in model behavior. On CodeSearch, ALFWorld, and BIRD SQL, models from 1.5B to 8B outperform fixed-harness baselines on held-out performance in most settings.
The Bottleneck of Agentic RL: The Limits of Hand-Written Frameworks
In agentic reinforcement learning (Agentic RL), the model is not trained in a vacuum—it relies on a peripheral component known as the harness. This "framework" determines which parts of its interaction history the agent can see, and what kind of steering signals it receives when its behavior deviates.
Currently, the mainstream approach uses a hand-written and fixed harness. However, an effective harness is highly dependent on the task domain, training data, and the model itself, and as training progresses, the model's behavioral patterns are constantly changing. Adapting a static set of rules to a dynamic model is essentially using yesterday's map to find today's road.
The recently proposed ModHarness-RL directly targets this contradiction: it no longer treats the harness as a manually designed constant, but redefines it as a program that can be learned from data and evolves as the model trains.
Core Mechanisms: Structured State and Dual-Program Drive
ModHarness-RL's design revolves around two key abstractions, shifting the harness from "fixed rules" to "learnable programs".
Structured State
The method first records the agent's interactions as a structured state representation: a series of typed blocks. This representation makes it easy for subsequent programs to selectively combine and operate on these blocks, rather than cramming raw historical text into the context window all at once.
Typed blocks — this design draws on ideas from programming languages and structured data processing: each interaction record (such as a model's tool call, an observation returned by the environment, or a system prompt) is no longer a piece of free text, but an independent unit with an explicit type label. The benefit is that subsequent compression and steering programs can retrieve, filter, reorder, or truncate blocks of specific types, without having to perform fuzzy summarization or truncation on the entire text. Compared with common "sliding-window truncation" or "summary compression", typed representation preserves the semantic boundaries of interactions, making programmatic operations more precise and reproducible, and providing a stable operating interface for learned programs.
Compression and Steering: Two Core Programs
On top of the structured state, the harness's two core components are implemented as programs operating on these blocks:
- Compression program: responsible for assembling the accumulated interaction history into the context the model ultimately receives. It determines "what the model can see".
- Steering program: when a deviation from expected behavior is detected, it provides guidance signals to the model. It determines "what help the model gets when it deviates".
Together, these two programs constitute the behavioral logic of the harness, and the key to ModHarness-RL is that—they are not hard-coded, but learned from data.
Context compression is a rigid problem in long-horizon agent tasks: interaction trajectories often far exceed the model's context window, and how to trade off historical information directly determines whether the model can maintain task coherence. Common approaches include keeping the most recent steps, summarizing history, or retrieving by relevance. ModHarness-RL's compression program delegates this decision to learnable logic, essentially learning a "history selection policy". Steering, on the other hand, differs from reward signals—rewards act on parameter updates, while steering is an immediate prompt injected at inference time to pull a deviating agent back on track; the two are complementary in time scale and target of action.
Training Loop: Propose, Verify, and Replay
How does ModHarness-RL achieve framework evolution during RL training? Its process can be summarized as a three-step loop:
- Propose: generate candidate programs from recent trajectories.
- Verify: validate the effectiveness of candidate programs through actual execution.
- Replay: replay programs on past trajectories to observe their performance.
This loop enables the harness to track changes in model behavior. As training progresses, the model's behavioral distribution shifts, and the harness adjusts its compression and steering strategies accordingly, forming a "co-evolution" relationship.
This design avoids a common dilemma in hand-designing harnesses: designers need to anticipate the behavioral patterns the model may exhibit throughout the entire training process, which is nearly impossible in complex tasks.
The replay here shares some common ground with experience replay in reinforcement learning, but the goal is different: experience replay is used to stabilize value estimation, whereas replay here re-executes candidate harness programs on historical trajectories to evaluate their performance under different model behavior distributions. Verify is also noteworthy—candidate programs must be screened through actual execution rather than static scoring, which prevents programs that "look reasonable but fail at runtime" from being adopted, and also aligns with the core positioning of treating the harness as an executable program rather than a prompt template.
Experimental Evidence: Outperforming Fixed Frameworks in Most Settings
The researchers evaluated ModHarness-RL on multiple tasks, covering models from 1.5B to 8B parameters:
- CodeSearch: a key analysis task, with in-depth experiments.
- ALFWorld: an embodied decision-making task in a text environment.
- BIRD SQL: a complex text-to-SQL generation benchmark.
Experimental results show that the proposed compression and steering mechanisms improve held-out performance in most settings, outperforming fixed-harness baselines. This result supports the core hypothesis: the harness of agentic RL can be learned from task data and evolve together with the model.
The authors conclude: "These results show that the harness of agentic RL can be learned from task data and evolve together with the model."
Held-out performance refers to performance on an evaluation set that differs from the training data distribution and was not involved in training; using it to measure the value of the harness is particularly critical: if improvements appear only on training tasks, the harness may simply have overfit to specific trajectories; but if it still outperforms fixed baselines on the held-out set, it indicates that the learned compression and steering strategies have some generalization ability. The 1.5B to 8B model span in the paper is also meaningful—it tests whether the method is equally effective on small and large models, rather than holding only for a certain scale.
Industry Implications: From Fixed Scaffolding to Learnable Components
ModHarness-RL's approach touches on a layer of agent training that is often overlooked. The community currently discusses RL algorithm improvements, reward model design, and environment construction extensively, but pays relatively limited attention to the question of "how the model perceives its own history".
Treating the harness itself as a learnable object means that the design space of agent systems expands from "model weights + fixed peripheral logic" to "model weights + evolvable peripheral programs". This brings up several directions worth considering:
- Domain adaptation: different tasks have vastly different needs for context compression and steering, and a learnable harness is expected to reduce manual tuning costs.
- Alignment with training dynamics: models undergo capability leaps or behavioral drift during training, and a fixed harness can easily become a bottleneck, while an evolvable harness can continuously match the model's current state.
- Interpretability challenges: when the harness changes from hand-written rules to learned programs, understanding why the model exhibits specific behaviors becomes more complex, potentially requiring new analysis tools.
At present, the method's validation on CodeSearch, ALFWorld, and BIRD SQL is still preliminary, but its core insight—the harness should not be a constant during training—has general reference value for the system design of agentic RL.
One-line Summary
ModHarness-RL turns the hand-written harness of agentic RL into a learnable program that evolves with the model.
Paragraph Summary
This article introduces ModHarness-RL, a method addressing the bottleneck in agentic reinforcement learning where hand-written fixed harnesses struggle to adapt to dynamic models. The method redefines the harness as a program that can be learned from data and evolves with training; based on a typed structured state representation, it treats a compression program (which determines the context visible to the model) and a steering program (which provides guidance when behavior deviates) as core learnable components. Training uses a propose-verify-replay loop, enabling the harness to track changes in the model's behavioral distribution. On CodeSearch, ALFWorld, and BIRD SQL tasks, models from 1.5B to 8B parameters outperform fixed-harness baselines on held-out performance in most settings, supporting the hypothesis that the harness can co-evolve with the model.
Related articles

AI Abuse Alert: Reports of Child Sexual Abuse Material Surge 8,400% in Two Years
Hacker News reports show AI-related child sexual abuse material reports rose 8,400% in two years. This article analyzes how generative AI lowers the barrier to producing illegal content, the dilemma facing platform detection and legal regulation, and feasible directions for technical countermeasures.

Can Task-Specific 4B Models Replace Large Models?
A developer training Qwen3.5-4B-3D-Coder and LFM2.5-350M finds task-specific small models exceed expectations on 3D scene generation. Insights on epochs, SFT vs RL cost, and full fine-tuning on consumer hardware.
AI Employee Tools Are Everywhere — How Can a 35-Person Startup Pick the Ones That Actually Work?
A 35-person startup struggles with too many AI employee tools. Drawing on real community experience, this article distills three hard criteria—unattended operation, integration depth, and verifiability—to help you pick tools that actually work and avoid shelfware.