NVLink 6 Multi-Layer Resiliency: How NVIDIA Keeps AI Factories Running
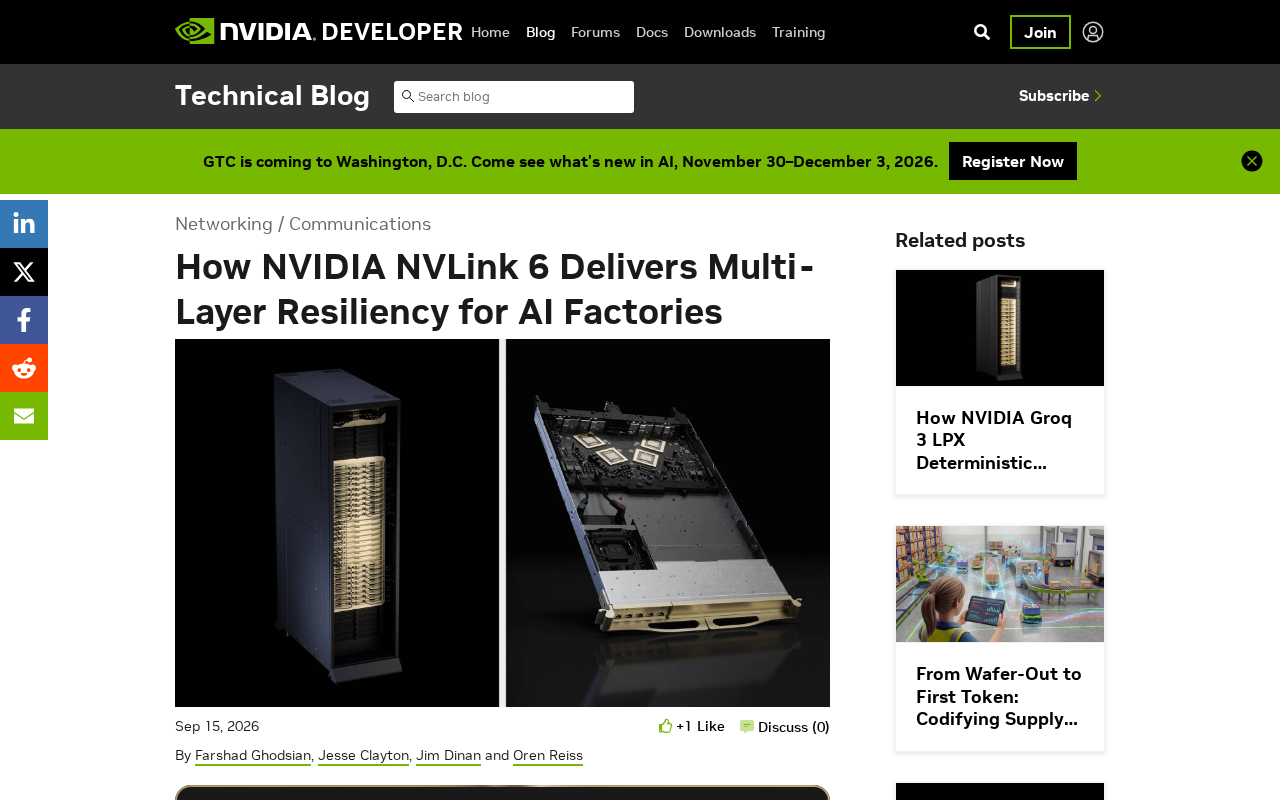
NVLink 6's multi-layer resiliency keeps hyperscale GPU clusters training through localized failures via layered redundancy.
This article examines NVIDIA NVLink 6's Multi-Layer Resiliency design and its practical impact on large-scale AI training clusters. With trillion-parameter models requiring thousands of GPUs, hardware failures are near-constant, making interconnect stability critical to effective compute utilization. NVLink 6 addresses this across three layers: link-level redundancy transparently absorbs transient errors via ARQ and FEC; fault isolation quickly detects and quarantines hard failures to minimize checkpoint rollbacks; and system-level health monitoring enables predictive maintenance to reduce unplanned downtime. The conclusion: AI infrastructure competition is shifting from raw compute stacking to systems-level reliability engineering.
The Core Imperative of AI Factories: Availability Is Productivity
For teams operating large-scale AI factories, sustained compute output is the defining productivity metric. In hyperscale AI training, every GPU in a cluster participates in the same job — when a node or link fails, the entire training run can be forced to halt or roll back to the last checkpoint, at considerable cost.
As model parameter counts cross the trillion-parameter threshold, training clusters routinely span thousands of GPUs. The larger the scale, the higher the probability of hardware failure: link flaps, single-card faults, and switch anomalies are effectively the norm rather than the exception in systems of this size. How to keep the interconnect fabric running in the face of localized failures has therefore become a key measure of AI infrastructure maturity. The Multi-Layer Resiliency mechanisms NVIDIA introduced in NVLink 6 represent a systematic response to exactly this challenge.
Why the Interconnect Layer Is the Key to Resiliency
Conventional thinking tends to focus on raw GPU compute, while the network connecting those GPUs is often overlooked. In large-scale parallel training, GPUs must continuously exchange gradients and parameters, making communication bandwidth and stability directly decisive for training efficiency. NVLink, as NVIDIA's high-speed GPU-to-GPU interconnect technology, carries this responsibility.
As clusters scale to hundreds or thousands of GPUs, interconnect topologies become extremely complex. Any single link failure that cannot be handled gracefully by the system risks cascading into the broader training job. This means the interconnect layer must pursue not only peak bandwidth, but also the ability to maintain service when failures occur — this is the essence of the concept of "Resiliency."
NVLink is NVIDIA's proprietary high-speed GPU-to-GPU interconnect bus technology, first introduced with the Pascal architecture (2016) and evolved through successive generations. Compared to PCIe, NVLink delivers higher bidirectional bandwidth and lower latency, enabling multi-GPU systems to share data in a near-unified-memory fashion. In the Hopper architecture (H100), NVLink 4 already provides 900 GB/s bidirectional bandwidth per GPU; NVLink 6, corresponding to the Blackwell architecture, further increases bandwidth and scalability. In large-scale training scenarios, common parallelism strategies — tensor parallelism, pipeline parallelism, and data parallelism — all require frequent GPU-to-GPU synchronization, and NVLink's bandwidth ceiling directly determines where these synchronization operations bottleneck. NVSwitch is the companion switch chip used to build all-to-all topologies, allowing GPUs within and across racks to communicate at full bandwidth with each other — the foundational interconnect architecture for large-scale clusters such as DGX SuperPOD.
The Design Philosophy Behind Multi-Layer Resiliency
The emphasis in NVLink 6 on "multi-layer" resiliency means building redundancy and fault isolation at different levels of the stack, rather than relying on any single protective mechanism. The logic of this layered design is that different types of failures need to be detected and handled at different layers.
Link-Level Redundancy
At the physical link layer, mechanisms such as redundant channels and automatic retransmission allow the system to self-recover from transient errors on individual links before they propagate upward. These mechanisms are transparent to users and upper-layer applications, capable of absorbing a large volume of transient errors.
ARQ (Automatic Repeat reQuest) and FEC (Forward Error Correction) are the two primary classes of mechanisms in interconnect protocols for handling physical-layer errors. FEC attaches redundant check codes at the sender, allowing the receiver to correct errors within a certain range without retransmission, at very low latency. ARQ triggers a retransmission request when an uncorrectable error is detected, making it well-suited for handling more severe burst errors. NVLink combines both mechanisms at the link layer, making sporadic bit errors caused by signal attenuation, crosstalk, or transient interference nearly invisible to upper layers. The stronger this transparent recovery capability, the less likely errors are to propagate upward and trigger far more costly recovery processes — making it the first line of defense in the entire multi-layer resiliency system.
Fault Isolation and Fast Recovery
When a hard fault occurs that cannot be repaired at the link layer, the system must be able to quickly locate the faulty node, isolate it from the communication topology, and keep the training job progressing on the remaining nodes as much as possible. For large-scale training, reducing the frequency and scope of checkpoint rollbacks has a direct bearing on effective compute utilization.
Checkpointing is the primary mechanism for fault tolerance in large-scale distributed training: the training framework periodically persists model weights, optimizer states, and other data to storage, so that in the event of an interruption, training can resume from the most recent checkpoint without restarting from scratch. However, saving checkpoints consumes I/O bandwidth and causes brief compute pauses; checkpointing too frequently degrades training efficiency, while too infrequently means potentially losing hours or more of compute progress after a failure. As clusters scale to thousands of GPUs, the storage overhead of each full checkpoint also becomes substantial. This is precisely why recovering directly at the link or node layer — without triggering a checkpoint rollback — is the most immediate value of multi-layer resiliency. It minimizes the number of failure events that require rollback, fundamentally improving Model FLOPs Utilization (MFU), the core efficiency metric.
System-Level Monitoring
At the AI factory level, continuous health monitoring and telemetry data collection enable operations teams to identify potential risks early and perform predictive maintenance, keeping unplanned downtime to a minimum.
Real-World Implications for AI Factory Operations
For large-scale training runs, interruptions mean wasted compute and delayed delivery. The value of multi-layer resiliency is fundamentally about improving cluster "effective uptime" — the fraction of time genuinely spent on productive computation.
As model scale continues to grow, training runs routinely need to run continuously for weeks or months at a time. Any unexpected interruption can cause significant losses. By building defense-in-depth at the interconnect layer, NVLink 6 aims to shift hyperscale clusters from a state where "failures inevitably cause outages" to one where "failures can be tolerated and recovered from" — with direct implications for the output stability of AI factories.
Conclusion
The multi-layer resiliency design in NVLink 6 reflects a broader shift in AI infrastructure competition: from pure compute stacking toward systems-level reliability engineering. As cluster scale continues to push limits, keeping a massive interconnect fabric operational in the presence of failures will become an increasingly important factor in AI factory competitiveness. For teams focused on large model training efficiency, the resiliency of the interconnect layer deserves a central place in infrastructure selection criteria.
(Note: This article is based on publicly available information from the NVIDIA developer blog. For specific technical parameters and implementation details, please refer to official documentation.)
Related articles
Capsule: Pack Web Apps and Data into a Single SQLite File
Capsule is a Rust/Tauri 2.0 tool that packs HTML web apps and data into a single SQLite file — privacy-first, local storage, portable sharing, with AI support.
DSH-SUBAGENT-UI Plugin: The Ultimate Sub-Agent Manager for DeepSeek Harness
DSH-SUBAGENT-UI is a DeepSeek Harness browser plugin offering sub-agent overview, search, local categorization, and completion snapshots — install with one command.
RTX 5090 Scalped for $9,000 in the US? Flying to Taipei to Buy One Might Actually Be Cheaper
RTX 5090 scalped for $9,000 in the US — a Reddit user did the math and found flying to Taipei to buy one is actually cheaper. A look at the real supply-demand crisis behind the joke.