Ollama v0.40.10 Updates Gemma Renderer, Adds Speculative Decoding Support
Ollama v0.40.10 adds a Gemma 4 renderer and speculative decoding on MLX—a low-risk maintenance update.
Ollama v0.40.10 (commit f52b9e7) is a maintenance update for the Gemma family: it adds a gemma4-nemotron renderer that places assistant content before tool calls to match Nemotron-style fine-tunes (with a chat template fixture for Jinja parity checks), and enables speculative decoding on the MLX backend with DFlash drafts for Gemma 4, exposing hidden-state taps and decoupling target precision from quantized draft weights. Auto-detection is unchanged, so behavior stays the same for existing users.
A Small but Critical Release
Ollama has released v0.40.10, commit f52b9e7, tagged by developer dhiltgen on October 23. Judging from the commit message, this is not a major feature release but rather two underlying improvements centered on the Gemma model family: a new renderer variant and enabling Gemma 4 to work with DFlash speculative decoding on the MLX backend. For users running local LLMs, updates like this tend to fly under the radar, yet they directly affect output format correctness and inference speed.
New gemma4-nemotron Renderer
The first change in this commit adds a gemma4-nemotron renderer to the renderers module. Its core difference lies in message rendering order: assistant content is placed before the tool call, rather than after the tool response.
This may sound like a mere formatting issue, but for models using structured tool calls, order determines the shape of the context the model sees. Some Gemma 4 fine-tuned models (such as the Nemotron series) adopt this leading layout during training; applying the default renderer can cause tool call format misalignment, parsing failures, and similar issues. Models can explicitly opt into this renderer via RENDERER gemma4-nemotron, while gemma4's auto-detection logic remains unchanged, so existing users will see no behavior change.
The commit also includes a corresponding chat template as a test fixture for Jinja parity checks. This means the renderer's output is validated for consistency against template rendering, reducing the risk of divergence between templates and actual inference behavior.
Chat template is the rules layer through which inference frameworks convert multi-turn conversations, system prompts, and tool call sequences into model input tokens, typically distributed as a Jinja2 template alongside model weights. Different model families have their own conventions for role markers, special tokens, and the arrangement of tool call blocks; templates must strictly match the training-time format, otherwise the model sees out-of-distribution input, manifesting as tool call parsing failures, role confusion, or output truncation. Jinja parity check means rendering the reference implementation and the in-framework renderer with the same template and comparing outputs byte by byte to ensure equivalence. Ollama shipping a test fixture with each renderer is precisely how this consistency check is brought into CI, preventing the renderer and template from silently drifting apart in future changes.
MLX Backend Now Supports Gemma 4 Speculative Decoding
The second change lands on the MLX backend: support for speculative decoding with a DFlash draft model targeting Gemma 4.
Speculative decoding works by using a small, fast draft model to guess several tokens first, which the target model then verifies in a single pass, reducing the number of serial forward passes through the large model. DFlash is the draft model type in this mechanism. This change does several things: when the draft model's config requires a separate output head, it loads the draft's own output head while preserving the target head path used by existing DFlash models to avoid breaking them; it exposes Gemma 4's hidden-state taps and raw logits for speculative decoding; and it decouples safetensors target precision reporting from the quantized draft weights.
The last point is easy to overlook. Draft models are often quantized to save VRAM, but if the target model's precision information is polluted by the draft's quantization state, users cannot judge the actual inference precision. Decoupling the two makes precision reporting more trustworthy.
Speculative Decoding is a technique that accelerates autoregressive generation while preserving the output distribution. The basic process: a small, fast draft model autoregressively generates k candidate tokens, which are then fed along with the original context in a single parallel forward pass through the large target model, which assigns probabilities at each position and accepts or rejects them one by one. Accepted tokens are kept directly; at the first rejection, resampling begins from that point, and the next round continues from there. Because the target model verifies multiple tokens in a single forward pass, the number of serial steps is significantly reduced. The speedup depends on the draft hit rate: the closer the draft and target distributions and the more regular the task (e.g., code completion, summarization), the higher the acceptance rate, typically yielding 1.5–3x speedup; conversely, frequent rejections can let the extra overhead cancel out the gains. Draft models are often quantized to reduce VRAM usage, which is why the article emphasizes decoupling precision reporting from the draft's quantization state.
What This Means for Local Deployment Users
If you run Gemma 4 series models on Ollama, the value of this update is mainly twofold. Users of Nemotron-style fine-tuned models can use the new renderer to get a tool call layout consistent with training, reducing format-related errors; users inferring via the MLX backend on Apple Silicon can potentially accelerate Gemma 4 generation with a DFlash draft model.
It's worth noting that auto-detection logic is unchanged, so ordinary gemma4 users will see no behavior change after upgrading—this is a low-risk update. The actual speedup from speculative decoding depends on how well the draft model matches the target model and on the task type; the commit itself provides no benchmark data, so it's advisable to measure on your own workload before deciding whether to enable it.
Summary
v0.40.10 is a typical maintenance release: one renderer fills in format compatibility for specific fine-tuned models, and a set of MLX changes brings Gemma 4 into the existing speculative decoding pipeline. Neither change alters default behavior, yet both expand the boundaries of Ollama's support for the Gemma ecosystem. For developers following the local inference toolchain, commits like these are more worth reading than version numbers.
One-line Summary
Ollama v0.40.10 adds a Gemma 4 renderer and brings speculative decoding to the MLX backend—a low-risk maintenance update.
Paragraph Summary
Ollama released v0.40.10 (commit f52b9e7), an underlying maintenance update centered on the Gemma model family with two changes. First, the renderers module adds a gemma4-nemotron renderer that renders assistant content before tool calls to match the training-time context layout of fine-tuned models like Nemotron, with a chat template included as a test fixture for Jinja parity checks. Second, the MLX backend now supports speculative decoding with DFlash as the draft model and Gemma 4 as the target, while exposing hidden-state taps and raw logits and decoupling safetensors target precision from quantized draft weights in reporting. gemma4 auto-detection logic is unchanged, so existing users see no behavior change after upgrading—a low-risk update; the actual speculative decoding speedup needs to be measured on your own workload.
Related articles
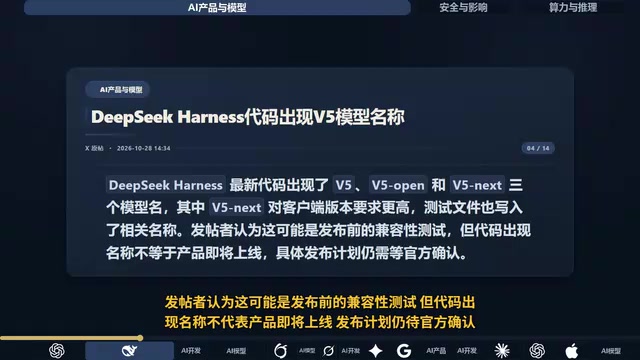
DeepSeek V5 Code Leak? It's Actually a Compatibility Test
AI Evening Report: DeepSeek Harness code shows V5 model names, deemed a compatibility test; Artificial Analysis V5 leaderboard released with DeepSeek tied for first among open-source models; Codex reset complete with news teased for tomorrow; coding agent security risks and OpenAI TPU procurement rumors analyzed.
The AI Coding Terminal Built for DeepSeek: A Deep Dive into the 38K-Star Open Source Project
A deep dive into the open source AI coding terminal built for DeepSeek: 38K stars, 20 parallel agents, three security modes, and OS-level sandbox isolation for fully automated file reading, code editing, and command execution from a single-sentence requirement.
Wuzhen Conference Signals: Open Source Becomes China's Key Card for Changing Lanes and Overtaking in AI
The Wuzhen Internet Conference put open source and openness at center stage, with domestic open-source models from Huawei, Kimi, MiniMax, and DeepSeek showcased together. This article analyzes why open source has become China's key card for changing lanes and overtaking in AI, as well as the ecosystem standards battle, security governance, and commercialization challenges behind open source.