OmniPoser: Flexible Human Motion Recovery via Masked Flow Matching

OmniPoser recovers full-body SMPL motion from any sensor combination with a unified generative framework at over 700 FPS.
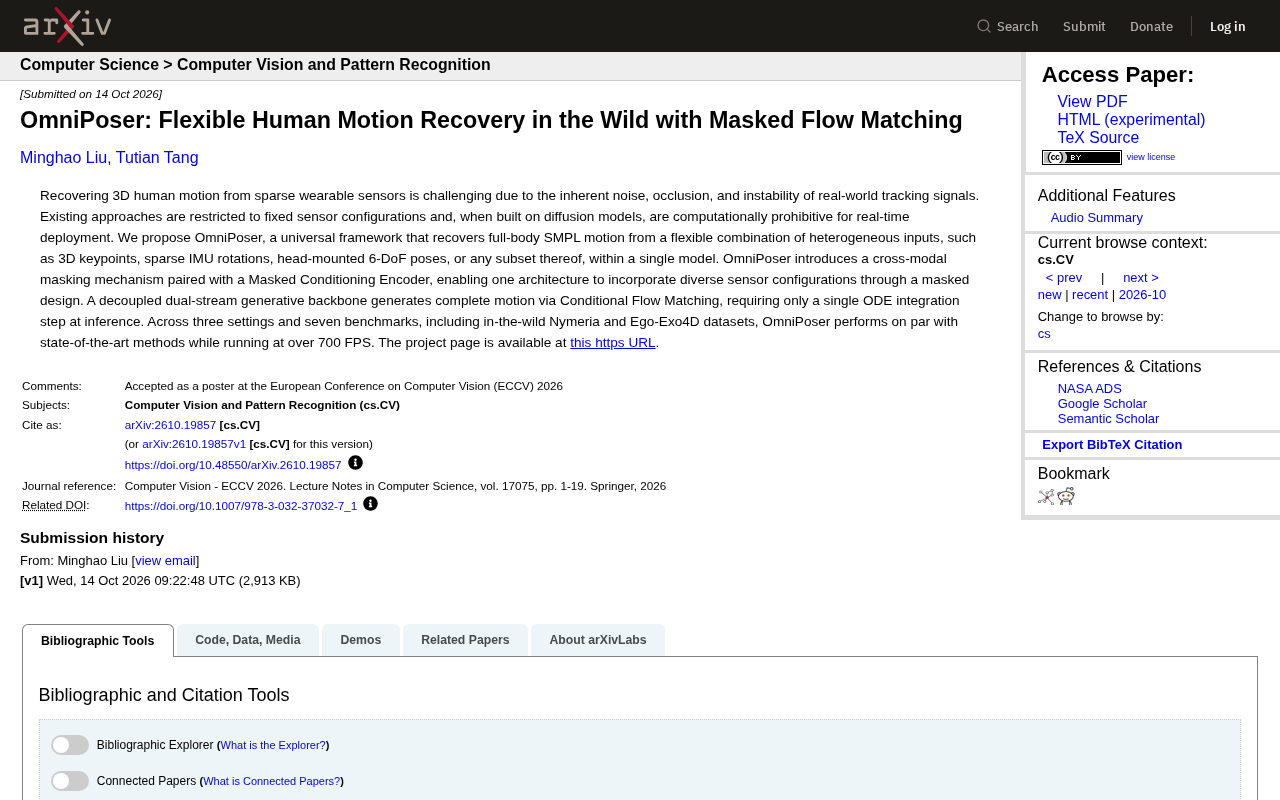
OmniPoser tackles two major pain points in sparse wearable sensor motion recovery—fixed sensor configurations and excessive diffusion model inference overhead—with a unified framework. It accepts 3D keypoints, sparse IMU rotations, head-mounted 6-DoF poses, and any subset thereof, so users don't need to retrain or switch models when sensor count and placement change. The key to universality is a cross-modal masking mechanism and masked conditioning encoder, with a decoupled dual-stream backbone and conditional flow matching for generation, where single-step ODE integration enables over 700 FPS inference. Evaluated on three settings and seven benchmarks (including Nymeria and Ego-Exo4D), it matches current state-of-the-art performance. The abstract omits accuracy numbers, degradation curves under extreme sparse configurations, and test hardware, leaving open whether universality comes at the cost of accuracy in some configurations.
Recovering 3D human motion from sparse wearable sensors has long been plagued by the noise, occlusion, and instability inherent in real-world tracking signals. Existing solutions typically bind to fixed sensor configurations, and diffusion-based implementations are too computationally expensive for real-time deployment. A new paper introduces OmniPoser, which aims to tackle both pain points at once: a unified framework that recovers full-body SMPL motion from arbitrary combinations of heterogeneous inputs.
One Model, Any Sensor Combination
OmniPoser's core claim is "universality." It accepts 3D keypoints, sparse IMU rotations, head-mounted 6-DoF poses, and any subset of these signals. In other words, users don't need to retrain or switch models regardless of how many sensors they wear or where they wear them.
This stands in sharp contrast to existing methods. Most motion recovery systems fix the number and placement of sensors during training, and performance drops significantly when the actual wearing configuration doesn't match the training setup. In consumer-grade VR/AR and motion capture scenarios, sensor configurations are precisely the most fragmented aspect—different devices, different users, and different application scenarios each have their own setup.
The SMPL model is one of the most widely used parametric human body representations in 3D human motion and shape modeling, standing for Skinned Multi-Person Linear Model. It decouples human geometry into two sets of low-dimensional parameters: shape parameters β control static features like height and body type, while pose parameters θ describe the relative rotation of each joint, typically outputting a mesh of 6890 vertices with a standard skeleton structure. Due to its small parameter count, clear semantics, and compatibility with mainstream motion capture data, SMPL has become a universal intermediate representation for tasks such as motion recovery, pose estimation, and human generation. "Recovering full-body SMPL motion" in this article refers to inferring per-frame β and θ from sparse sensor signals to reconstruct continuous 3D human motion sequences, rather than merely outputting discrete joint coordinates.
Masking Mechanism and Dual-Stream Generation Architecture
The key technology enabling universality is a cross-modal masking mechanism combined with a Masked Conditioning Encoder. Through masking design, the same architecture can accommodate vastly different sensor configurations: missing modalities are masked, available modalities participate in conditional encoding, and the model requires no separate adaptation for each combination.
The generation side employs a decoupled dual-stream backbone network, generating complete motion through Conditional Flow Matching. Unlike diffusion models that require multi-step denoising iterations, flow matching needs only a single-step ODE integration during inference—this is the direct reason it can push speed beyond 700 FPS.
Conditional Flow Matching is a class of generative modeling methods based on continuous normalizing flows. Rather than directly learning the data distribution, it learns a time-dependent velocity field that continuously transforms a simple prior distribution (such as Gaussian noise) along a probability path toward the target distribution. The training objective is typically to have the network regress this velocity field, so that sampling requires only numerical integration of an ordinary differential equation to generate samples from noise. Compared to diffusion models, flow matching paths can be designed to be closer to straight lines, thus achieving relatively high quality with few or even single-step integration during inference—this is precisely the key to OmniPoser reaching 700 FPS. It should be noted that single-step ODE integration sacrifices some generation diversity, typically forming a trade-off between generation quality and speed.
Performance: On Par with SOTA, Significantly Faster
The paper evaluates on three settings and seven benchmarks, including real-world datasets Nymeria and Ego-Exo4D. Results show that OmniPoser's performance is comparable to current state-of-the-art methods, but runs at over 700 FPS.
700 FPS means single-frame inference time of approximately 1.4 milliseconds, far below the threshold required for real-time interaction. For latency-sensitive applications such as VR socializing, virtual livestreaming, and robot teleoperation, this order-of-magnitude difference determines whether a solution is viable.
Trade-offs Worth Noting
The abstract does not disclose specific accuracy metrics, nor does it describe the performance degradation curve under extremely sparse configurations (such as single-sensor only). Whether universality comes at the cost of accuracy in certain specific configurations requires reading the full paper to judge. Additionally, the hardware conditions for the 700 FPS test are also not specified in the abstract.
Overall, OmniPoser's approach represents a pragmatic direction: rather than pursuing extreme accuracy under a single configuration, it's better to use a unified generative framework to cover the messy sensor combinations of the real world, while compressing inference costs to a deployable level. The project page is now public, and the code and more experimental details are worth following up on.
Nymeria and Ego-Exo4D are large-scale human motion datasets released in recent years, featuring synchronized first-person and third-person multimodal capture. Nymeria focuses on long-duration motion recordings with wearable devices (including IMUs, head-mounted displays, etc.) in daily scenarios, while Ego-Exo4D provides both egocentric and exocentric video with accompanying motion annotations. The value of such datasets lies in the fact that the signals they collect inherently carry real-world noise, occlusion, and sensor configuration differences, more closely resembling the actual deployment conditions of consumer-grade wearable devices. Therefore, evaluation on Nymeria and Ego-Exo4D better reflects a model's generalization ability to messy input combinations than laboratory-grade motion capture data, and also echoes OmniPoser's emphasis on "real-world fragmented configurations."
One-line Summary
OmniPoser uses a unified generative framework to recover full-body SMPL motion from arbitrary sensor combinations at over 700 FPS.
Paragraph Summary
OmniPoser addresses two major pain points in sparse wearable sensor motion recovery—fixed sensor configurations and excessive inference overhead of diffusion models—by proposing a unified framework. It accepts 3D keypoints, sparse IMU rotations, head-mounted 6-DoF poses, and any subset thereof, so users don't need to retrain or switch models when sensor count and placement change. The key to universality is a cross-modal masking mechanism and masked conditioning encoder, with a decoupled dual-stream backbone on the generation side and conditional flow matching for motion generation, where single-step ODE integration enables inference speeds exceeding 700 FPS. The paper evaluates on three settings and seven benchmarks (including Nymeria and Ego-Exo4D), with performance on par with current state-of-the-art methods. The abstract does not disclose accuracy numbers, degradation curves under extreme sparse configurations, or test hardware conditions, so whether universality comes at the cost of accuracy in some configurations remains to be verified in the full paper.
Related articles

GPT-Next Leak, Gemini 4 Argon Imminent: AI News Roundup
GPT-Next leak suggests extreme efficiency; OpenAI's 28-day shipping pledge boosts speed 50%; Gemini 4 Argon nears release; Anthropic subscription value report sparks debate.

GPT-Next Leaked, Gemini 4 Argon Speeds Up, Fable 5.5 May Launch Today
OpenAI's GPT-Next model leaks, expected to be extremely low-cost and possibly part of the 28-day release plan; Gemini 4 Argon internal testing accelerates, NanoBanana 2.1 is live; Semi Analysis tests show Claude Max's equivalent API value is about 5 times that of ChatGPT Pro; Fable 5.5 may launch today.

Gemini 4 Argon Launches Globally: Key Highlights from the AI Daily Brief
Google opens Gemini 4 Argon globally across Pro and Ultra subscriptions and the API, and demonstrates robot control. This article rounds up open-source models, Agent infrastructure, cost transparency, and safety governance updates.