Perplexity Computer May Switch Default Model: Gemini Neon Reportedly Beats Opus 5.5
Perplexity is rumored to plan switching its default model to Gemini Neon based on retention data, reflecting a shift in model selection logic.
Starting from a social media message, the article notes that Perplexity Computer is said to recommend Gemini Neon, reportedly better than Opus 5.5, and may switch its default model based on retention data. It separates the information into product, capability, and decision layers, arguing that "better" lacks task and metric specifics while "retention statistics" is the real signal—model evaluation is shifting from benchmarks to sustained usage. It cautions that retention is confounded by product guidance and defaults, treats the single-source claim as a signal, and advises developers to keep multi-model flexibility.
Perplexity's product moves have long been seen as a bellwether for competition in AI search and agent products. Recently, a message from social media claimed that Perplexity Computer is recommending that users try Gemini Neon, with word that "it's better than Opus 5.5," and even that there are plans to switch the default model to it based on retention data. The information itself is thin, but the questions it raises are not: as model capabilities converge, choosing a product's default model is becoming a data-driven business.
Three Layers of Information in a Single Tweet
The original information came from Twitter and was very brief: using Gemini Neon on Perplexity Computer, hearing that it performs better than Opus 5.5, and possibly switching the default model to it based on retention data.
This information contains three layers worth unpacking. The first is the product layer: Perplexity Computer, as a product that carries agent-style tasks, is pushing Gemini Neon to users as an option and even a candidate default. The second is the capability layer: "better than Opus 5.5" is a comparative judgment that comes from what users have heard rather than from public evaluations. The third is the decision layer: "based on retention statistics" shows that the choice of default model is no longer judged only by benchmark scores, but by whether users are willing to stay and keep using it.
It should be noted that this is only a single-source social media message, with neither an official announcement nor any disclosed details about evaluation methods or retention data. It is better treated as an observational signal than as an established fact.
Gemini Neon vs. Opus 5.5: The Two Objects Being Compared
Gemini Neon and Opus 5.5 come from two mainstream model families. The original text gives only the vague conclusion of "better," without specifying on which task types or which metrics it is better. In agent-type products, "better" can usually point to several dimensions: completion rate on multi-step tasks, accuracy of tool calls, stability over long contexts, response latency, and per-task cost. Leadership across these dimensions is not consistent, and it is hard for a single model to dominate across all of them.
Therefore, the real value of the sentence "better than Opus 5.5" lies not in the conclusion itself, but in the fact that it comes from the product side's actual usage feedback. Compared with laboratory benchmarks, what the product side sees is how real users perform on real tasks, and this kind of judgment is often closer to actual deployment results.
In agent-type products, Tool Calling / Function Calling is a key point where model capability manifests. It refers to a model's ability to autonomously decide, based on user intent, which external tool to call (such as search, a calculator, or a code executor), with what parameters, and to incorporate the returned results into subsequent reasoning. The accuracy of tool calling has three layers: whether the right tool is selected, whether the parameters are valid, and whether consistent state can be maintained across multiple rounds of calls. A model that performs excellently on single-turn Q&A does not necessarily mean it can reliably complete tool orchestration in complex agent workflows, which is one reason why real-world product testing and benchmark scores often diverge.
Long-context stability also deserves separate mention. A long-context window refers to the upper limit of tokens a model can process in a single pass, but "being able to fit it" does not equal "being able to use it well"—as context grows longer, the model may miss key information, suffer from lost in the middle, or show degraded instruction following. For agent tasks that need to read large numbers of web pages, documents, or historical conversations, long-context stability often determines task success more than window size itself, and it is also harder for standardized evaluations to capture.
Retention Data Becomes the Yardstick for Model Selection
The most noteworthy keyword in this message is "retention statistics." Using retention as the basis for switching the default model means that the coordinate system for model evaluation has changed: from "who has the higher score" to "who can keep users using it."
This shift has its rationale. For agent products, a user's first trial is often driven by novelty, and whether they stay depends on whether the task is done right the first time, whether the wait time is acceptable, and whether it is easy to correct after a failure. These experience metrics are directly reflected in the retention curve, and benchmarks struggle to capture them. Using retention for decisions is essentially letting user behavior vote on model selection.
But this approach also has blind spots. Retention is affected by multiple factors such as product guidance, default settings, and task distribution, and retention alone may not distinguish "the model is better" from "the default entry point is more prominent." If Perplexity really adjusts its default model on this basis, how to strip out these confounding factors will be a question it needs to answer internally.
Retention Rate usually refers to the proportion of users who continue using a product within a certain time window after first use, such as next-day retention, 7-day retention, and 30-day retention. It is a core metric in product growth analysis, reflecting whether users shift from "trying it out" to "using it regularly." In model selection scenarios, retention can serve as an indirect proxy for experience, but it is inherently the result of mixed factors: new-user onboarding flows, the prominence of default entry points, task-type distribution, and even seasonal fluctuations all affect the retention curve. Therefore, when using retention for A/B decisions, it is usually necessary to combine control group design, randomized traffic splitting, and sufficient sample size to separate "model differences" from "product differences."
The Product Logic Behind the Default Model Battle
The choice of default model has a profound impact on agent products. It is the capability ceiling that most users actually encounter, and it also determines the product's cost structure and response speed. Switching the default model from one company to another affects not only experience, but also inference cost, latency budget, and supplier dependence.
For a product like Perplexity that offers both search and agent capabilities, multiple models coexisting is the norm, and the default model is a statement of product positioning. If, as the message says, it is really leaning toward Gemini Neon, it can be understood as the product side believing that it has more advantage in overall experience and retention; but before official confirmation, this remains only a possibility.
The lesson for developers and heavy users is this: there is no need to bind too tightly to a single model. Agent workflows vary in their sensitivity to models depending on the task, so preserving room to switch and choosing models by task type is more prudent than betting on one "strongest model."
Model Routing is a common engineering strategy in current agent products: dynamically distributing requests to different models based on task type, context length, latency requirements, or cost budget. The default model can be seen as a "fallback branch" in the routing strategy, handling most requests that are not specially designated. Alongside it is a degradation mechanism—switching to a backup model when the primary model times out or fails, to ensure availability. The significance of this architecture is that the product does not have to bet on a single model, but instead turns model selection into an adjustable parameter, which also explains why "changing the default model" is not an irreversible decision in engineering terms.
Inference cost and latency budget are hard constraints in default model decisions. Agent tasks often involve multiple rounds of calls and long contexts, and the token consumption per task is far higher than in ordinary conversation, so unit token price and first-token latency are directly amplified. The choice of default model is in effect drawing a baseline among capability ceiling, cost ceiling, and response speed, and any switch requires recalibrating the balance among these three.
Questions to Be Verified
This message leaves several unresolved questions: on which tasks Gemini Neon's advantages over Opus 5.5 are specifically reflected; what the comparison criteria for the retention data are; and whether the default model will really be switched, and when. Before official information appears, it is enough to treat it as a signal worth tracking.
As model competition enters the product deployment stage, similar rumors about "changing the default model" will become more common. The way to judge their credibility is also simple: see whether there are reproducible evaluations, whether the comparison criteria are disclosed, and whether there is official confirmation. Only when all three are present is it worth treating as a conclusion.
One-line Summary
Perplexity is rumored to plan to switch its default model to Gemini Neon based on retention data, reflecting a shift in the logic of model selection.
Paragraph Summary
The article starts from a social media message: Perplexity Computer is said to recommend Gemini Neon, with claims that it performs better than Opus 5.5 and may even switch its default model based on retention data. The author breaks this information into three layers—product, capability, and decision—and points out that "better" lacks specific tasks and metric criteria, while "retention statistics" is the real signal: model evaluation is shifting from benchmark scores to whether users are willing to keep using it. The article also reminds readers that retention is affected by confounding factors such as product guidance and default settings, that a single-source message should be treated as an observational signal rather than fact, and that developers should preserve room for multi-model switching and choose models by task type.
Related articles
Gemini 4 Neon Hands-On: Half the Price vs. Opus 5.5 — Which Is Better?
Based on hands-on developer tests and third-party benchmarks, we analyze the real gap between Gemini 4 Neon and Claude Opus 5.5: intelligence index, coding ability, cost per task, and use cases — revealing the truth behind the 'half price' claim.
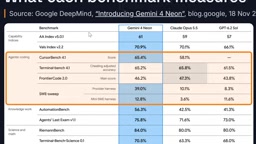
Gemini 4 Neon Benchmarks Fully Explained: Head-to-Head with Opus and ChatGPT 6.2
A detailed breakdown of the Gemini 4 Neon official benchmark tables: slightly ahead of Opus and ChatGPT 6.2 overall, trailing by 0.5 on terminal tasks, with a clear long-context advantage and wins on cost and speed.
The Gemini 4 Neon Coding Test Mystery: 39% vs. 12.8% — Tool Differences or Model Capability?
Gemini 4 Neon scores 39% and 12.8% on SWE-bench, narrowing its gap with GPT-6.2 Sol from 30.7 to 1.2 points. We analyze how agent tools affect coding benchmark scores and offer controlled testing advice.