Positional Encoding in LLMs: From Absolute to Relative and Rotary Mechanisms

A review of absolute, relative, and RoPE positional encoding schemes in LLMs and their extrapolation trade-offs.
Starting from the permutation invariance of Transformer self-attention, the article explains why positional encoding is necessary for models to distinguish word order. It covers three mainstream schemes—absolute positional encoding (simple but weak at extrapolation), relative positional encoding (directly models token distances, more robust to length changes but more complex), and Rotary Positional Encoding (RoPE, which makes attention depend only on relative position and is widely used in open-source LLMs). It concludes with length extrapolation techniques such as position interpolation and frequency adjustment, emphasizing that no scheme is universally optimal and understanding trade-offs matters more than memorizing implementations.
Positional embeddings are the fundamental mechanism that enables modern large language models to understand word order. Without them, the Transformer's attention mechanism is essentially an unordered set operation and cannot distinguish between "the cat chased the dog" and "the dog chased the cat." This article reviews the main categories of positional encoding used in mainstream LLMs, their respective trade-offs, and recent directions of evolution.
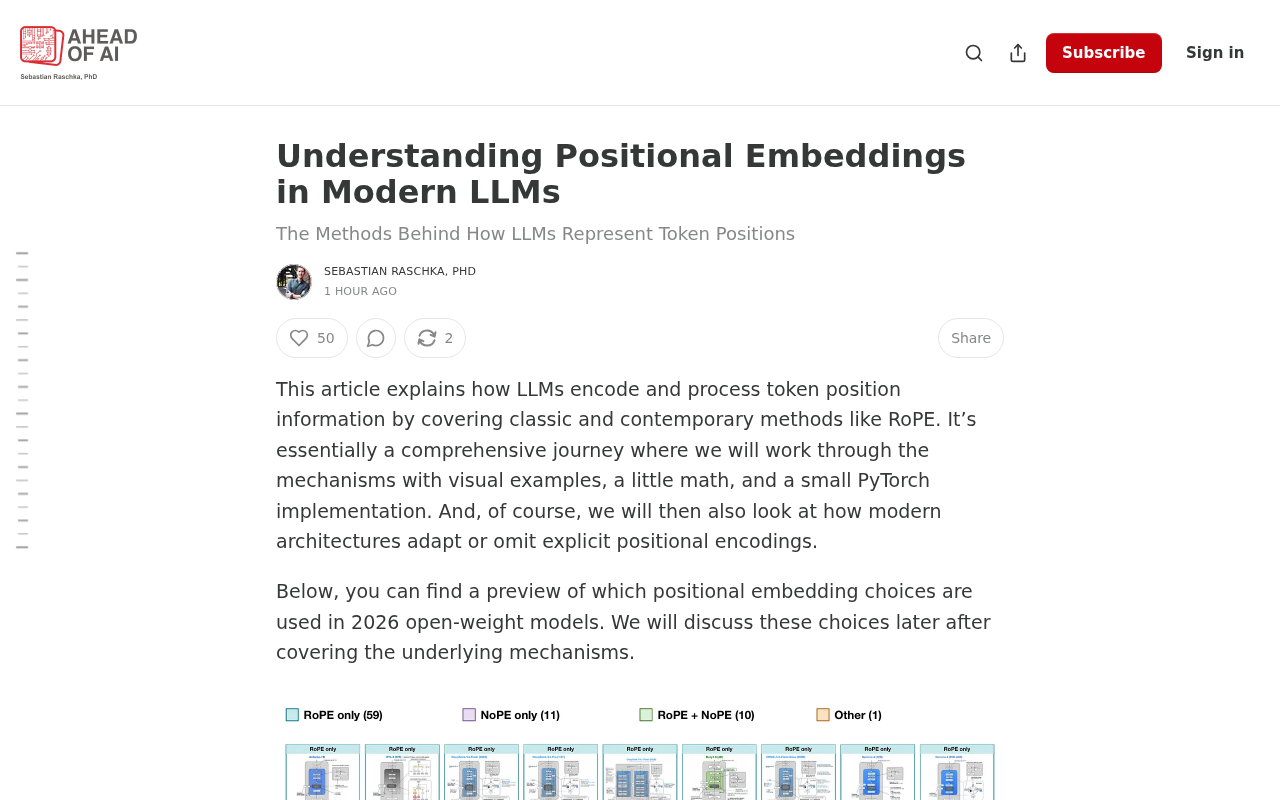
Why Positional Encoding Is Needed
Transformer self-attention is permutation-invariant with respect to the input sequence: if you shuffle the order of tokens, the result of the attention computation depends only on the content itself, not on the positions of the tokens in the sequence. This means the model inherently lacks information about "who comes first, who comes after, and how far apart they are."
The role of positional encoding is to inject positional information into the token representations so that attention can distinguish between different positions. The core differences among positional encoding schemes lie in whether positional information is added to the input or applied within the attention computation, and whether it can naturally extrapolate to sequence lengths unseen during training.
The permutation invariance of self-attention can be understood mathematically: for any permutation matrix (P) applied to the input sequence, the attention output is simply permuted accordingly, with unchanged values. This is because the attention weights (\mathrm{softmax}(QK^\top/\sqrt{d})) only compare the similarity between token contents, and position indices never enter the computation. The essence of positional encoding is to break this symmetry—either by superimposing a positional signal on the input embeddings, or by injecting position-related biases or transformations into the attention scores, so that the model can distinguish between the same content appearing at different positions.
Absolute Positional Encoding: Adding Position as a Vector
One of the earliest schemes is sinusoidal positional encoding. It generates a set of sine and cosine values at different frequencies for each position and adds them to the token's word embedding. This encoding requires no training parameters and can theoretically represent positions of arbitrary length.
Another approach is learnable absolute positional encoding, which trains an independent embedding vector for each position. This is simple to implement, but the number of positions is fixed at training time, and positions beyond the training length have no corresponding parameters, limiting extrapolation capability.
The common problem with absolute positional encoding is that it encodes positional information as an absolute quantity—"which position number"—and the model must infer relative distances from these quantities itself, which is not efficient on long sequences.
The specific form of sinusoidal positional encoding is: for position (pos) and dimension index (i), even dimensions use (\sin(pos/10000^{2i/d})) and odd dimensions use (\cos(pos/10000^{2i/d})). Different dimensions correspond to different wavelengths, forming a geometric progression from high to low frequency, so that each position obtains a unique encoding vector. One of its design motivations is that the positional encoding at any fixed offset (k) can be expressed as a linear transformation of the original positional encoding, which theoretically facilitates the model's learning of relative relationships; however, this property holds only under ideal conditions, and in practice the model still needs training to exploit it.
Relative Positional Encoding: Modeling Distance Directly
Relative positional encoding no longer cares about "which position number I am" but focuses on "how far apart you and I are." Works such as Transformer-XL and T5 incorporate relative distance as part of the attention scores, enabling the model to directly exploit the interval information between tokens.
The advantage of relative encoding is that the same relative distance shares the same set of parameters across different absolute positions, making it more robust to changes in sequence length. The cost is greater implementation complexity: the attention computation must additionally handle relative position terms, and sometimes distances beyond a certain range must be truncated or bucketed.
Rotary Positional Encoding: Rotating Position into Attention
Rotary Positional Encoding (RoPE) is a widely adopted scheme in recent years. Its idea is to rotate the query and key vectors by an angle according to their positions, so that the dot product of the two depends only on their relative position difference. In this way, positional information enters the attention scores directly without needing to be added to the input embeddings.
RoPE's appeal lies in two points: first, it builds the property of relative position into attention, consistent with the goal of relative encoding; second, the rotation angle varies with position and can be adjusted through rotation frequencies and other means to explore length extrapolation, which makes it the choice of many open-source large models.
The mathematical core of RoPE is the two-dimensional rotation matrix. The dimensions of the query and key are grouped in pairs, with each group rotated by an angle (m\theta_i) according to position (m), where (\theta_i) is a base frequency that decreases with dimension. Since the rotation matrix satisfies (R_m^\top R_n = R_{n-m}), the dot product of the rotated query and key depends only on the relative position (n-m), thereby naturally encoding relative distance in the attention scores. This property does not change the computational structure of attention and introduces no additional parameters, which is an important reason why RoPE is easy to deploy.
Length Extrapolation and Engineering Trade-offs
The choice of positional encoding scheme often depends on the application scenario. When training and inference lengths are the same, learnable absolute encoding is simple and effective; when inference on longer sequences is required, relative encoding and RoPE are preferred. Techniques such as frequency adjustment and position interpolation around RoPE are also intended to keep the model usable on sequences beyond the training length.
No single scheme dominates in all dimensions. Absolute encoding is simple to implement but weak at extrapolation; relative encoding is flexible but computationally complex; RoPE expresses relative position at the attention level but also requires additional extrapolation strategies. Understanding these trade-offs is more valuable than memorizing any single implementation.
There are mainly two categories of length extrapolation techniques around RoPE. Position Interpolation compresses position indices beyond the training length proportionally into the training range, avoiding rotation angles the model has never seen; frequency adjustment methods (such as NTK-aware scaling) change the base frequency distribution across dimensions, letting low-frequency dimensions handle longer-distance discrimination. The common idea behind these techniques is: rather than retraining the model, adjust the mapping between positions and rotation angles so that the model maintains a reasonable distribution of attention scores on longer sequences.
One-line Summary
A review of absolute, relative, and RoPE positional encoding schemes in LLMs and their extrapolation trade-offs.
Paragraph Summary
Starting from the permutation invariance of Transformer self-attention, the article explains that positional encoding is a necessary mechanism for models to distinguish word order. It then covers three mainstream schemes: absolute positional encoding (sinusoidal and learnable encoding) is simple to implement but has a fixed number of positions at training time and weak extrapolation; relative positional encoding directly models distances between tokens, shares parameters across different absolute positions, and is more robust to length changes but more complex to implement; Rotary Positional Encoding (RoPE) rotates queries and keys so that the dot product depends only on relative position, making it the choice of many open-source large models. The article concludes by discussing length extrapolation and engineering trade-offs, noting that techniques such as position interpolation and frequency adjustment extend RoPE's usable length, and emphasizing that there is no universally optimal scheme and that understanding trade-offs is more valuable than memorizing implementations.
Related articles
No Coding Required: He Shipped an App Store App by 'Cutting Features' and Nitpicking with AI
A game designer with zero frontend/backend skills shipped a dual-platform App Store app with AI—not via one-click generation, but by cutting scope and nitpicking like a demanding client.
What Is Harness Engineering? From Concept Origins to Enterprise-Level Agent Implementation
What is Harness Engineering? This article traces the concept's origins and analyzes enterprise-level Agent requirements for tool call fault tolerance, data security, tenant isolation, and memory gaps.
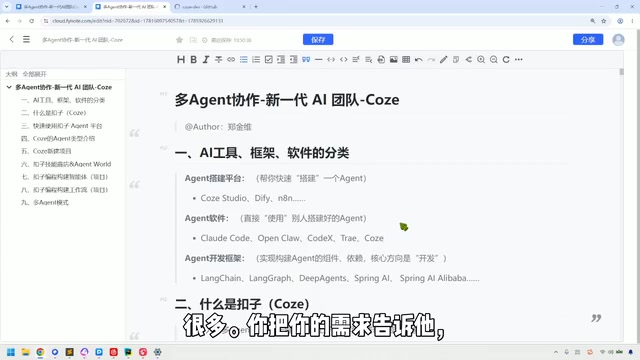
Coze in Practice: A Three-Tier Agent Classification and a Multi-Agent Collaboration Guide
A Bilibili tutorial breaks down the multi-agent collaboration toolchain into three categories: building platforms like Coze Studio and Dify, Agent software like Claude Code, and development frameworks like LangChain—plus a Coze demo of industry templates, three-platform interoperability, local Agent integration, and the trade-offs of credit consumption.