Predicting Invoice Late Payments with TabPFN: A Locally-Run Receivables Cash Forecasting Tool

Cashcast uses TabPFN v2 on local CPU to predict invoice lateness and eight-week cash flow; backtesting shows accuracy on par with linear regression but better calibration.
Cashcast is an open-source receivables forecasting tool that reads invoice CSV exports and outputs lateness probabilities, expected payment dates with 80% intervals, collection advice, and an eight-week cash forecast, all running locally so client data never leaves the machine. Technically it uses TabPFN v2 classifiers and regressors to judge lateness and predict the payment-day distribution, with strict feature engineering to exclude leak-prone columns known only after settlement. In month-by-month backtesting on 1,075 invoices from the IBM public dataset, TabPFN's AUC was 0.882, roughly on par with plain logistic regression's 0.890 but clearly better than gradient boosted trees' 0.864, whose 80% interval hit only 57.5%. Its distinctive value is generating an independent distribution per invoice, narrowing intervals for stable payers, though it still under-covers the most volatile customers, and the weekly cash forecast is too narrow because it assumes invoices are independent.
Predicting Invoice Late Payments with TabPFN: A Locally-Run Receivables Cash Forecasting Tool
One of the scariest scenarios for freelancers and small agencies: invoices go out and sit unpaid, while rent and bills keep coming due. Cashcast is an open-source tool that uses the TabPFN tabular foundation model to predict, on your own laptop, which unpaid invoices will be late, when they're likely to be paid, and what the next eight weeks of cash flow look like — with your client list and amounts never leaving your machine.
What Problem Cashcast Solves
Cloud accounting suites offer payment reminders and cash-flow views, but they expect the whole ledger in their cloud and a monthly subscription. Cashcast is positioned as a single-purpose tool that reads the CSV export you already have. One row per invoice, containing customer, invoice date, due date, amount, and payment date, and it outputs four judgments: the probability of lateness, an expected payment date with an 80% interval, a recommended next action (contact today / chase now / remind at due date / no action needed), and a weekly cash forecast for the next eight weeks.
The target users are freelancers, small agencies, and bookkeepers managing receivables for multiple small clients. For these people, lateness isn't an abstract metric — it determines whether rent can be transferred on time, and how many hours each week go into writing chase emails.
Demo: Replaying the IBM Public Dataset
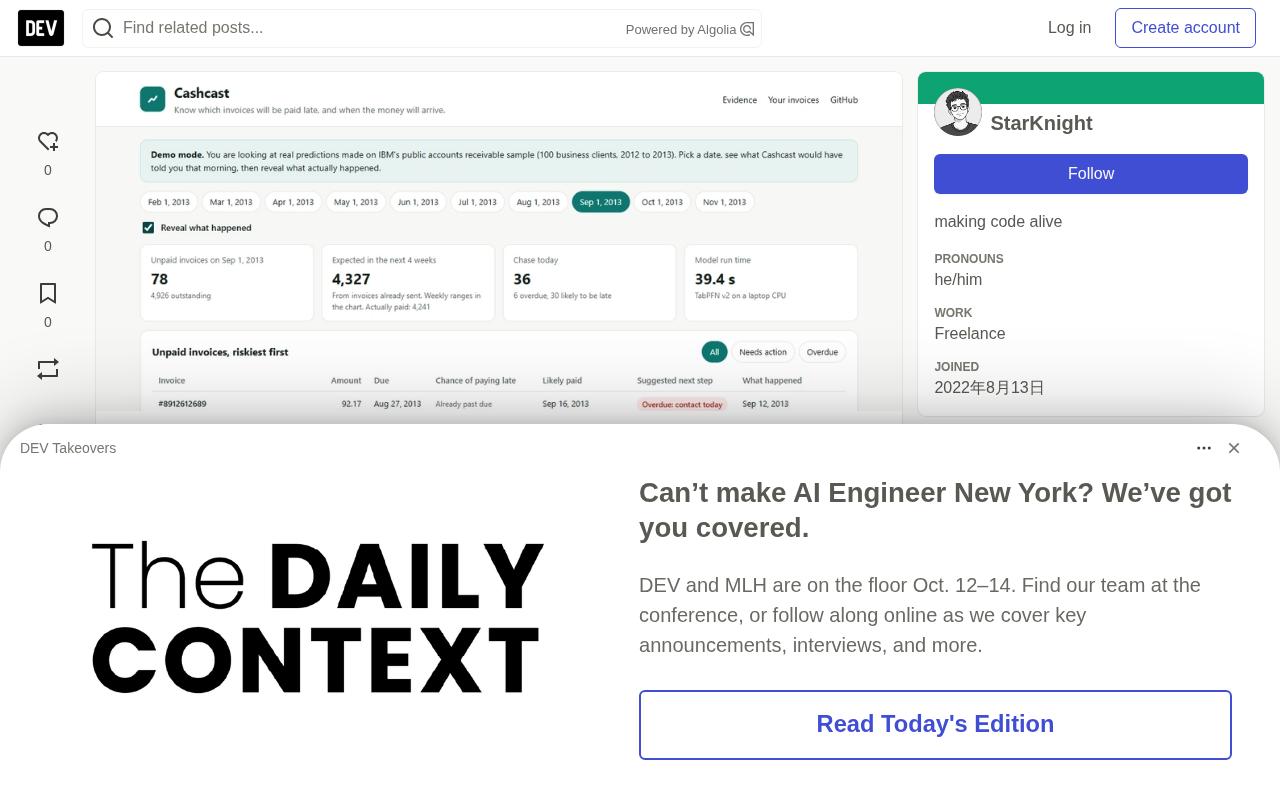
The online demo page is a replay feature. The data comes from IBM's publicly available accounts receivable sample: 100 commercial customers, 2,466 invoices, records from 2012 to 2013, of which 36% were paid late. Pick a date, and the page shows what Cashcast would have told you that morning, using only invoices paid before that date. Check "Reveal what happened" and the true payment dates appear alongside the predictions.
A few scenarios worth trying: select September 1, 2013 — 78 invoices are unpaid, and Cashcast expects 4,327 to arrive over the next four weeks (the sample has no currency unit). Reveal the actuals: 4,241 actually arrived. Click "Needs action" to see only the invoices recommended for chasing, each with a one-line historical summary computed from the data, e.g., "13 of the past 15 invoices were paid late, average payment cycle 36 days."
Using your own invoices locally requires Python 3.10+ and runs on CPU. python -m cashcast.serve opens the same page in local mode, with a file picker. Files travel from the browser to a Python process on 127.0.0.1 and go nowhere else. On the bundled 404-row sample ledger, scoring takes about 7 to 9 seconds.
Technical Implementation: TabPFN Does the Prediction
TabPFN is Prior Labs' tabular foundation model, pretrained on millions of synthetic tables. You hand it your table, and it predicts in a single forward pass. For small businesses with only a few hundred to a few thousand invoices, this means no training loop to tune and no model to babysit.
Cashcast uses two TabPFN v2 models on the same feature set: a classifier that decides "will this invoice be paid after its due date," and a regressor that answers "how many more days until payment." It requests 49 quantiles, returning a full distribution per invoice rather than a single number.
Feature Engineering and Leakage Prevention
This kind of data is the easiest to fool yourself with. The IBM sample contains columns like DaysToSettle and Disputed, which are only known after an invoice settles — using them would make the task look far easier than it really is. So features.py builds each row from information known on the day the invoice went out: how many invoices this customer has had paid, their late frequency, average and most recent payment days, how many remain outstanding, and how the current amount compares to their historical level. Invoices paid after the invoice date are invisible to that row.
From Distributions to Decisions
The regressor's quantiles are the most useful part. An invoice already 25 days overdue and one sent out yesterday are entirely different bets, so forecast.py conditions each distribution on the invoice's current age and reads from it: P(paid after due date | still unpaid today) as the lateness probability, the 10th, 50th, and 90th percentile payment dates, and a cash forecast that aggregates 2,000 simulated payment schedules per date into weekly totals. The next-action labels are simple rules (overdue: contact today; probability above 50%: remind now; above 30%: remind at due date). The historical summary line next to each invoice is computed, not generated, so it's impossible for it to state something the data doesn't support.
Tabular Foundation Model represents a shift from the traditional paradigm of "train one model per dataset." Classic supervised learning requires gradient descent on a training set for the target task, and with little data and few features it overfits easily; a foundation model, by contrast, is pretrained on vast synthetic or real tabular tasks and learns the general capability of "how to do conditional inference on tables." TabPFN's core mechanism feeds the training set and the sample to be predicted together as input to a Transformer, and outputs a predictive distribution directly through approximate Bayesian inference implemented inside the network — hence the name "Prior-Data Fitted Network." This has two direct consequences: inference is a single forward pass with no training loop, runnable on CPU; and the model size has a hard cap relative to the training data volume, which shows up directly in the backtesting section below.
Quantile regression and prediction intervals need to be distinguished from "confidence intervals." A confidence interval describes uncertainty about estimating some parameter, whereas a prediction interval describes uncertainty about a single future observation — the latter is naturally wider. When a model outputs the full conditional distribution of payment days, the distance between the 10th and 90th percentiles forms an 80% prediction interval, whose meaning is "over long-run repeated sampling, about 80% of true payment dates will fall within this interval." Interval hit rate therefore becomes a key calibration metric: if a nominal 80% interval actually hits only 57.5%, the model is overconfident and will lead you to underestimate cash-flow risk; a hit rate above 80% means the interval is too wide and loses its value for guiding action. Cashcast's cash forecast is precisely this: Monte Carlo sampling of each invoice's distribution, aggregated by week.
Month-by-Month Backtesting: The Month TabPFN Didn't Win
From January to October 2013, each month the model was trained only on invoices paid before that month began, then used to predict invoices issued during that month — 1,075 predictions in total. TabPFN on CPU accepts a maximum of 1,000 rows of training data by default, so the most recent 1,000 paid invoices were used each month.
| Model | AUC | Brier | Collection recall | Payment-day error | 80% interval hit |
|---|---|---|---|---|---|
| TabPFN v2 | 0.882 | 0.127 | 51.0% | 5.92 days | 79.1% |
| Logistic/linear regression | 0.890 | 0.122 | 50.4% | 5.81 days | 79.3% |
| Customer's own history | 0.870 | 0.135 | 50.7% | 6.54 days | N/A |
| Gradient boosted trees | 0.864 | 0.154 | 49.9% | 6.23 days | 57.5% |
| Base rate | 0.5 | 0.218 | 18.4% | 10.11 days | N/A |
"Collection recall" answers the business question: if you only chase the highest-risk 20% of invoices each month, how many late invoices do you catch? Lower Brier and payment-day error are better.
An honest reading: on this dataset, plain logistic and linear regression are as accurate as TabPFN. The author originally expected TabPFN to win clearly, and it didn't. But it clearly beats gradient boosted trees trained on the same data — whose 80% interval captured only 57.5% of true payment dates.
Probability calibration is good. Of the 586 invoices TabPFN gave below-20% probabilities, 8.7% were actually late (model average prediction 6.2%). Of the 116 given above-80%, 90.5% were actually late (model prediction 87.4%).
AUC, Brier score, and calibration measure different facets. AUC is a ranking metric: it answers "if you randomly draw one late invoice and one on-time invoice, what's the probability the model scores the late one higher" — 0.5 is a coin flip, 1.0 is perfect ranking, but it's insensitive to the absolute value of the probabilities. The Brier score is the mean squared error between predicted probabilities and true 0/1 outcomes; lower is better, and it penalizes both ranking errors and probability distortion. Calibration specifically examines whether "invoices the model says are 20% likely" are in fact late about 20% of the time. The figures here — below-20% group actually 8.7% (model mean 6.2%), above-80% group actually 90.5% (model mean 87.4%) — show the probability values themselves are trustworthy. Collection recall translates ranking ability into business language: under a budget constraint of handling only the highest-risk 20% of invoices, how many genuinely late invoices can you cover.
TabPFN's Distinctive Value: Every Invoice Gets Its Own Uncertainty
A linear model with residual noise gives every invoice an uncertainty interval of the same width; TabPFN gives each invoice its own distribution. Testing by three groups split according to the volatility of customers' past payment times: on stable customers, TabPFN's 80% interval hit 80.5% with a width of 16.0 days, while linear regression hit 83.8% with a width of 18.4 days; the middle group was 83.3%/17.7 days and 84.2%/18.5 days respectively; on volatile customers, TabPFN hit 73.3% with a width of 19.9 days, while linear regression hit 69.7% with a width of 18.4 days.
TabPFN narrows intervals for reliable payers and widens them for unreliable ones — the direction you want — but the effect is limited, and both under-cover the most volatile third of customers. The distributional capability also lets Cashcast answer "this invoice has been unpaid for 20 days past due, what now" without needing a separate model.
Validating the Replay Itself
The online page's numbers come from scoring real outcomes (10 dates, 905 unpaid-invoice records): of the 296 "send reminder now" flags, 78% were indeed paid late, versus a 43% late rate among all not-yet-due invoices in the same period. The share of true payment dates falling inside the 80% interval was 77.1%, with a typical deviation of 5.78 days. The weekly cash forecast is the weak spot: out of 80 weeks, only 67.5% had actual amounts inside the 80% interval — the simulation treats invoices as independent, making intervals too narrow. Each date takes about 40 seconds on a laptop CPU.
Limitations and Open-Source Business Considerations
The sample contains only invoices that were eventually paid; Cashcast has never seen a written-off invoice. All invoices in the sample have 30-day terms — other terms are unverified. It advises who to contact but sends nothing itself. The online page is a replay of a public dataset; before trusting it on your own ledger, run the same backtest on your own historical data.
Open source matters enormously for this small product. An invoice ledger is a list of who pays you, how much, and how reliably — open weights let Cashcast run on the laptop that already holds that file, the local server binds to 127.0.0.1, and after a one-time weight download, scoring still works even if you block all network traffic. A one-time-license tool can't afford per-prediction API bills; with open weights, the marginal cost of each prediction is just a few seconds of CPU time.
The license must permit commercial sale. Prior Labs recommends using its newest model, TabPFN-3.5, via API, under a free non-commercial license — a good choice for research, but a side business is by definition commercial. The TabPFN v2 weights are released under the Prior Labs License 1.1 (Apache 2.0 with an added attribution requirement, hence the page's "Built with PriorLabs-TabPFN" label); they download from Hugging Face without an account and run offline. For this product, the openness of the license matters as much as the openness of the weights. The trade-off is possibly sacrificing some accuracy by not using the newest model.
Openness makes evaluation possible. The model, data, and code are all inspectable, allowing the author to run all baselines on exactly the same rows and publish results where TabPFN didn't win. A black-box API gives you a number to trust, not a number to check.
The commercial constraints of open-source licenses are often misread as "open source means free to use commercially." Apache 2.0 allows free use, modification, and commercial distribution, but the added attribution requirement carries over into derivative works; Prior Labs License 1.1 belongs to this "Apache 2.0 + attribution" structure, so the source must be labeled on the product page. By contrast, a model offered only through an API can still restrict commercial use via its terms of service even if its weights are public, and every call incurs a charge. For a tool that embeds predictions into daily bookkeeping workflows, per-call marginal costs directly conflict with the availability of "open your laptop and run it." Choosing the older open weights is a typical trade-off: some accuracy exchanged for offline capability, auditability, and zero marginal cost.
One-line Summary
Cashcast uses TabPFN v2 on local CPU to predict invoice lateness and eight-week cash flow; backtesting shows accuracy on par with linear regression but with better calibration.
Paragraph Summary
Cashcast is an open-source receivables forecasting tool that reads invoice CSV exports and outputs lateness probabilities, expected payment dates with 80% intervals, collection advice, and an eight-week cash forecast — all running locally, with client data never leaving the machine. Technically it uses TabPFN v2 classifiers and regressors to judge lateness and predict the payment-day distribution, with strict feature engineering to exclude leak-prone columns known only after settlement. In month-by-month backtesting on 1,075 invoices from the IBM public dataset, TabPFN's AUC was 0.882, roughly on par with plain logistic regression's 0.890 but clearly better than gradient boosted trees' 0.864, whose 80% interval hit only 57.5%. Its distinctive value is generating an independent distribution for each invoice, narrowing intervals for stable payers, though it still under-covers the most volatile customers, and the weekly cash forecast is too narrow because it assumes invoices are independent.
Related articles

Gmod TTT: Boba's Winning Streak and Game Design Insights
An in-depth analysis of Gmod TTT's role system, creative items, and social gameplay mechanics, exploring the relationship between randomness design and game balance through Boba's winning streak phenomenon.

FlexBudget: Fair Comparison of KV Cache Eviction Strategies Under a Unified Compute Budget
AMD engineer proposes FlexBudget at PyTorch Conference: a training-free fair comparison method for KV cache eviction rules using fixed kernels and memory budgets, all in core PyTorch.
