PrismML Bets on Tiny LLMs: Can Small Models Reshape How We Use AI?
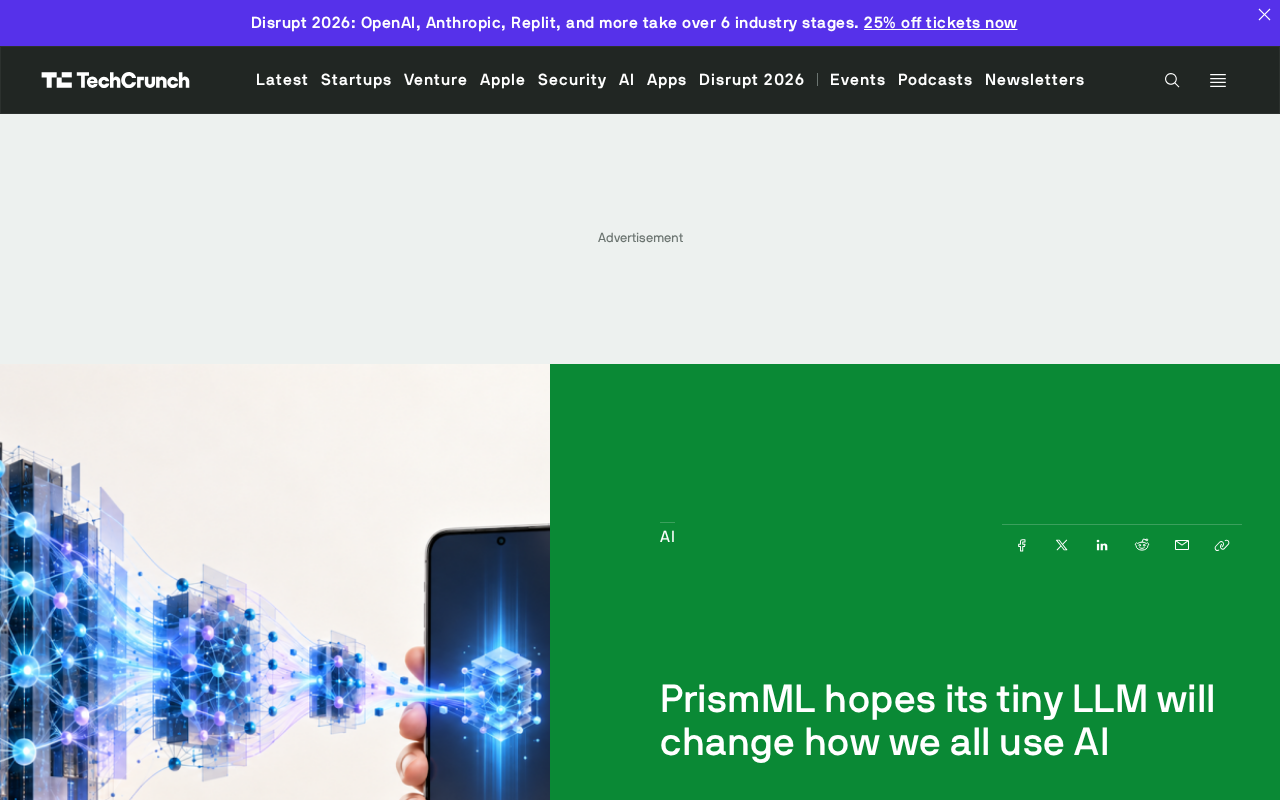
PrismML bets on tiny LLMs for local, low-cost, privacy-friendly AI — challenging the dominance of massive cloud-based models.
PrismML is an AI lab focused on tiny large language models (tiny LLMs), arguing that extremely compact models can fundamentally change how AI is used. Unlike massive models with hundreds of billions of parameters, tiny LLMs can run locally on phones and laptops without cloud APIs, offering lower latency, stronger privacy, and reduced deployment costs. The approach aligns with a broader industry shift from capability-limit competition toward efficiency and accessibility — backed by mature techniques like knowledge distillation, quantization, and pruning. PrismML's specific parameter counts and benchmark results have yet to be disclosed, so its vision remains to be validated, but the "small model deployment" thesis it represents is already a critical direction in AI's evolution.
Why PrismML Deserves Your Attention
AI lab PrismML is attempting to disrupt the industry's dominant usage paradigm with an extremely compact large language model (LLM). The original report put it plainly: if PrismML hasn't been on your radar yet, it should be now.
Behind that verdict lies a trend that's been quietly gaining momentum. While the mainstream continues to compete on models with hundreds of billions — or even trillions — of parameters, a growing cohort of research teams is taking the opposite approach, betting on the "small but capable" path. PrismML is one of the most visible representatives of this movement.
It's worth noting that the publicly available information on PrismML remains quite limited, conveying little more than its core vision and market positioning. The analysis below draws on broader industry context to help readers understand the significance of this direction. Specific technical specs and benchmark results have yet to be officially disclosed.
The Promise of Tiny LLMs
A "tiny LLM" refers to a language model that has been significantly compressed in terms of parameter count, memory footprint, and inference cost. Its value isn't in topping leaderboards — it's in bringing AI capabilities down from cloud data centers and closer to where users actually are.
The appeal of small models plays out across several dimensions. They can run locally on smartphones, laptops, or even embedded devices without requiring a persistent connection to a cloud API. Local inference means data never needs to leave the device, which translates naturally into stronger privacy protections. Lower compute requirements also directly reduce the cost of deployment and ongoing operation.
When PrismML talks about "changing how we use AI," it's almost certainly pointing toward a shift from centralized cloud services toward distributed, local intelligence. If a sufficiently small model can be embedded into everyday tools while remaining genuinely useful, AI's reach could expand dramatically.
In terms of scale, the industry generally classifies models with fewer than 1 billion (1B) parameters as "tiny," the 1B–7B range as "small," and GPT-4-class models are estimated to exceed one trillion parameters. There are three primary technical approaches to making models smaller: knowledge distillation (training a small model to mimic the output distribution of a larger one, transferring its "knowledge"), quantization (compressing model weights from 32-bit floats to 8-bit or even 4-bit integers to dramatically reduce memory usage), and pruning (removing neural network connections that contribute little to the final output). These techniques are often used in combination. Meta's Llama series, Microsoft's Phi series, and Google's Gemma series are all notable recent examples of the small/tiny model approach. Phi-2 (2.7B parameters), for instance, has matched models several times its size on multiple benchmarks — validating the feasibility of the "small but capable" strategy.
The Industry Logic Behind Smaller Models
Over the past year or two, model compression has become an important subplot in the broader AI race. Large models are undeniably capable, but their high inference costs, latency, and steep deployment requirements make them a poor fit for many scenarios. For a large class of specific, domain-focused tasks, a carefully trained and distilled small model can deliver results that are simply "good enough."
The business case is equally compelling. For developers and enterprises, locally runnable small models reduce dependence on expensive GPU clusters and cloud API calls, making it far more economically viable to deploy AI features at scale. PrismML's decision to enter the market now reflects a clear read on this gap — the value of efficiency and cost that giant models have largely left on the table.
At a higher level, the AI industry is bifurcating: one branch chases the upper limits of capability; the other pursues efficiency and accessibility. These aren't competing visions — together, they form a complete ecosystem.
Knowledge distillation deserves a closer look, because it's the key mechanism behind the capability gains of small models. The core idea: a large "teacher model" doesn't just output a final answer — it also outputs a probability distribution over all possible tokens (called "soft labels"). These distributions carry far richer information than a single correct answer. They reveal what the model considers the second most likely response, and the relative confidence between different options. A small "student model" trained on these soft labels can acquire a portion of the teacher's reasoning ability at a fraction of the cost of training from scratch. This explains why some models with just one-thousandth of GPT-4's parameter count can still approach its performance on specific vertical tasks. For PrismML, its technical moat likely lies precisely in the precision with which its distillation strategy is matched to target tasks.
Key Questions That Still Need Answers
A compelling vision still requires hard metrics to back it up. How small is PrismML's tiny model, exactly? Which tasks can it match against larger models? What does real-world inference speed and power consumption look like? None of these core questions have been answered in the materials currently available.
For any product claiming to "transform an industry," the real test comes from reproducible benchmark results, real-world performance, and genuine feedback from the developer community. Until that data is public, cautious optimism is the more rational stance.
For readers tracking AI deployment, PrismML offers a worthwhile case study to follow. The proposition it represents — that small models can change how AI gets used — is itself one of the most significant directions in AI's current evolution. The story will only come fully into focus once more detailed technical disclosures arrive.
Related articles
NVIDIA cuML Accelerates Spectral Clustering: 100x+ Speedup Over Scikit-Learn Benchmarked
NVIDIA cuML lets Scikit-Learn spectral clustering run on GPU without code changes, delivering 200x+ speedups on large datasets. Learn how it works and how to use it.
Google DeepMind Launches New Institute to Bring the AGI Debate into the Open
Google DeepMind has launched a new institute to bring AGI debate into the public sphere. We analyze what this signals about the shift from technical competition to AI governance.
How Cooley Is Reinventing IPO Legal Workflows with ChatGPT: A Look at the GO Public Tool
Cooley built GO Public on ChatGPT Work to accelerate IPO legal workflows, helping lawyers catch issues earlier and focus judgment where it matters most.