Process Mining + Federated Learning: A New Breakthrough in Industrial IoT Anomaly Detection
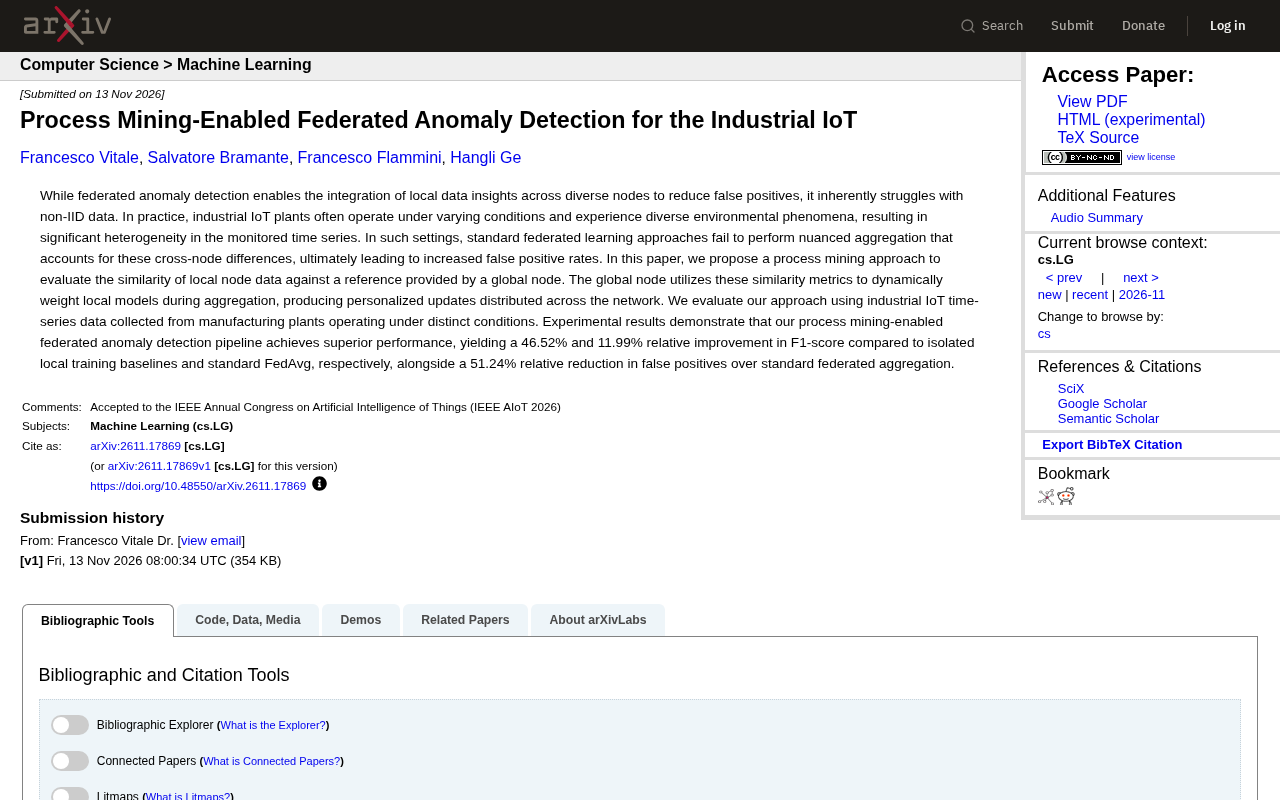
Using process mining to quantify node similarity and dynamically weight aggregation, alleviating non-IID false positives in industrial IoT federated anomaly detection.
The article presents a federated anomaly detection study for IIoT. Industrial time-series data is highly non-IID due to differing operating conditions, and standard FedAvg's uniform aggregation cannot capture cross-node distribution differences, increasing false positives. The paper uses process mining to extract behavioral patterns from local event sequences, compute similarity to a global reference baseline, and dynamically weight aggregation accordingly: higher similarity gets greater weight, while more different nodes receive personalized updates. On real industrial data from plants under different conditions, the method improves F1 by 46.52% over isolated local training and 11.99% over standard FedAvg, while reducing false positives by 51.24%, all without sharing raw data. The article also notes that reliance on a reliable global reference and scaling costs remain to be verified.
Time-series data generated by Industrial IoT (IIoT) devices often exhibits highly non-independent and identically distributed (non-IID) characteristics due to differences in operating conditions and environments. This makes it difficult for standard federated learning to account for heterogeneity across nodes when aggregating local models, which in turn drives up false positive rates. A recent paper proposes using Process Mining to quantify the similarity between local node data and a global reference, and to dynamically weight aggregation accordingly, achieving significant improvements on real industrial time-series data.
The non-IID Dilemma of Federated Anomaly Detection
Federated learning allows multiple nodes to collaboratively train models without sharing raw data, and in theory can integrate scattered insights to reduce false positives. However, the paper points out that in industrial settings, different factories differ greatly in operating conditions, environmental interference, and operating-mode patterns, causing the distributions of monitoring time-series data to differ significantly. Standard FedAvg (Federated Averaging) aggregates local models using uniform or simple weighting and cannot capture such cross-node differences; the aggregated global model may instead amplify false positives.
This problem is especially prominent in anomaly detection tasks: anomalies themselves are scarce and diverse in form, and models need to finely distinguish normal fluctuations from real faults. When node data distributions shift, crude aggregation blurs local features and raises the false positive rate.
FedAvg (Federated Averaging) is the most basic model aggregation algorithm in federated learning, proposed by McMahan et al. in 2016. Its procedure is: the central server sends the current global model to selected clients; each client trains locally on its own data with stochastic gradient descent for several rounds and uploads model parameters; the server performs a weighted average of the parameters according to each client's share of sample volume to obtain a new round of the global model. The core assumption of FedAvg is that each node's data is approximately independent and identically distributed, so simple averaging can approximate the effect of centralized training. But in non-IID scenarios, the directions of each node's local optimal parameters differ considerably; direct averaging biases the global model toward nodes with large sample volumes, blurs the local features of small nodes, and can even cause "client drift" leading to slow convergence or oscillation. This is precisely the core problem that this paper aims to solve by introducing process mining for dynamic weighting.
How Process Mining Quantifies Node Similarity
The core idea of the paper is to introduce process mining to evaluate the similarity between local node data and a reference provided by a global node. The global node maintains a reference baseline; each local node periodically compares its own data features against it, and the process mining algorithm extracts behavioral patterns from event sequences and computes similarity metrics.
These similarity measures are then used for dynamic weighting: local models more similar to the global reference receive higher weights during aggregation, while nodes with larger differences receive personalized updates. In this way, the aggregation process is no longer one-size-fits-all but makes nuanced adjustments based on each node's actual data characteristics. Finally, the global node distributes the personalized updates back to the network, balancing global consensus and local adaptability.
Process Mining is a class of techniques that extract, analyze, and improve actual business processes from event logs recorded by information systems. Representative methods include process discovery (reconstructing processes with models such as Petri nets and BPMN), conformance checking (comparing logs against reference models), and process enhancement. Its input is usually an event sequence containing case IDs, activity names, and timestamps. In industrial settings, equipment sensors and MES/SCADA systems leave behind a large number of timestamped operation and state events, which naturally constitute event logs. This paper leverages exactly this characteristic: it transforms a node's time-series data into event sequences, then uses process mining to extract their behavioral patterns (such as activity order, branch frequencies, and loop structures), and measures the degree of similarity between local and global references using indicators such as behavioral profiles and alignment. In this way, "whether data distributions are close" is transformed into a computable process similarity.
Experimental Results: F1 Improvement and False Positive Reduction
The research team evaluated the approach using industrial IoT time-series data from manufacturing plants under different operating conditions. The results show that, compared with an isolated local training baseline, the process-mining-driven federated anomaly detection pipeline achieves a 46.52% relative improvement in F1 score; compared with standard FedAvg, the F1 relative improvement is 11.99%. At the same time, compared with standard federated aggregation, the false positive rate is relatively reduced by 51.24%.
These data indicate that the similarity measures provided by process mining can effectively guide the allocation of aggregation weights and alleviate the performance degradation caused by non-IID. You may not have noticed that this method does not rely on sharing raw data, which meets the strict data privacy requirements of industrial scenarios.
F1 score is a commonly used comprehensive evaluation metric in anomaly detection. It is the harmonic mean of precision and recall, ranges from 0 to 1, and the closer to 1 the better. Precision is the proportion of samples judged by the model as anomalies that are truly anomalous, while recall is the proportion of all true anomalies that are successfully detected. In industrial anomaly detection, anomalous samples are extremely scarce; if only accuracy is considered, a model that classifies everything as normal can still obtain a very high score, so F1 better reflects true detection capability. The harmonic mean is more sensitive to the lower of the two, which avoids the imbalance of "reporting only a few high-confidence anomalies" or "trading a large number of false positives for high recall." The relative F1 improvement reported in this paper means a proportional improvement in this metric over the baseline, and together with the reduction in false positive rate, it shows that the method achieves a better balance between missed detections and false positives.
Implications for Industrial Deployment
Industrial IoT anomaly detection has long faced the dual challenges of data silos and heterogeneous distributions. This study introduces process mining, a business process analysis tool, into the federated learning aggregation stage, providing a lightweight means of similarity assessment. For manufacturing enterprises with multiple production sites, this means they can train detection models that better fit each plant's actual operating conditions without centralizing data.
However, the method relies on a global node providing a reliable reference, and how its computational overhead behaves as the number of nodes scales still needs further verification. The paper does not disclose the specific number of nodes or deployment costs, so practical deployment requires trade-offs based on the scenario.
Overall, this research provides a new idea for applying federated anomaly detection to non-IID industrial data, and the experimental data demonstrate considerable performance gains. Future work could focus on dynamic updating mechanisms for the reference baseline and generalization capability for cross-industry transfer.
One-line Summary
Using process mining to quantify node similarity and dynamically weight aggregation, alleviating the non-IID false positive problem in industrial IoT federated anomaly detection.
Paragraph Summary
This article introduces a study on federated anomaly detection for the Industrial Internet of Things. Time-series data from industrial equipment exhibits highly non-IID characteristics due to differences in operating conditions and environments; standard FedAvg's uniform aggregation cannot capture distribution differences across nodes and instead drives up false positive rates. The paper introduces process mining to extract behavioral patterns from local nodes' event sequences, compute their similarity to a global reference baseline, and dynamically weight local model aggregation accordingly: more similar models receive greater weight, while more different ones receive personalized updates. On real industrial time-series data from manufacturing plants under different operating conditions, the method achieves a 46.52% relative F1 improvement over isolated local training and an 11.99% relative improvement over standard FedAvg, while reducing the false positive rate by 51.24%, all without sharing raw data, in line with industrial privacy requirements. The article also notes that its reliance on a reliable global reference and the computational overhead at scale remain to be verified.
Related articles
ClawDOS: Bringing AI Coding Capabilities to DOS
ClawDOS is an AI coding agent project for DOS, exploring the possibility of bringing AI coding assistance into resource-constrained retro computing environments. This article analyzes its positioning, use cases, and community response.

Baseten Releases Bison-1 and Groundhog-1, Topping the Decision Model Leaderboard
Baseten releases open-weight decision models bison-1 and groundhog-1 built on Gemma 4; bison-1 scores 76 on the AA Decision Index v2.1 to top the leaderboard. Both support 128k context and image input—here we analyze their capability combination, benchmark significance, and selection advice for developers.

Cline CLI v3.0.75 Released: Yolo Mode Now Default for One-Shot Runs
Cline CLI v3.0.75: one-shot runs now default to yolo mode, --timeout and Ctrl+C can interrupt the first round, read_files is no longer truncated to 8k chars, plus reasoning parameter fixes and 94 new providers.