Q3 Global Trade Dynamics: The Scourge of Auto-Generated Content in Geopolitical and Macroeconomic Analysis

An article claiming global trade analysis is actually three crypto affiliate links, revealing how auto-generated content arbitrages via formal disguise.
Using an RSS article titled 'Global Trade Dynamics Q3 2026' as a sample, this piece notes its body contains no trade data or macroeconomic analysis—only three affiliate links (Binance, Ledger, Crypto.com) and a disclaimer that it was generated by 'Nexus Intelligence.' It dissects three layers: the SEO title shell, tool-recommendation monetization logic, and misuse of 'autonomous research' labels. It further analyzes why RSS aggregators are hotspots due to open protocols and lack of content verification, and lists five identification features. Finally, it highlights triple erosion for readers, platforms, and genuine analysts, with the core contradiction being marginal production cost nearing zero while filtering costs rise.
When "Global Trade Analysis" Becomes a Recommendation Link Show
An RSS article titled Global Trade Dynamics Q3 2026 — Geopolitical & Macroeconomic Analysis was scraped by an automated tool and pushed into a content system. Upon opening the original, readers were greeted with: a list of recommended tools—three ads for Binance, Ledger, and Crypto.com, each with affiliate links—plus a small disclaimer stating "This article was generated by the Nexus Intelligence autonomous research system."
No trade data, no geopolitical reasoning, no macroeconomic models. The "Q3 2026 global trade dynamics" promised in the title went entirely unmentioned in the body.
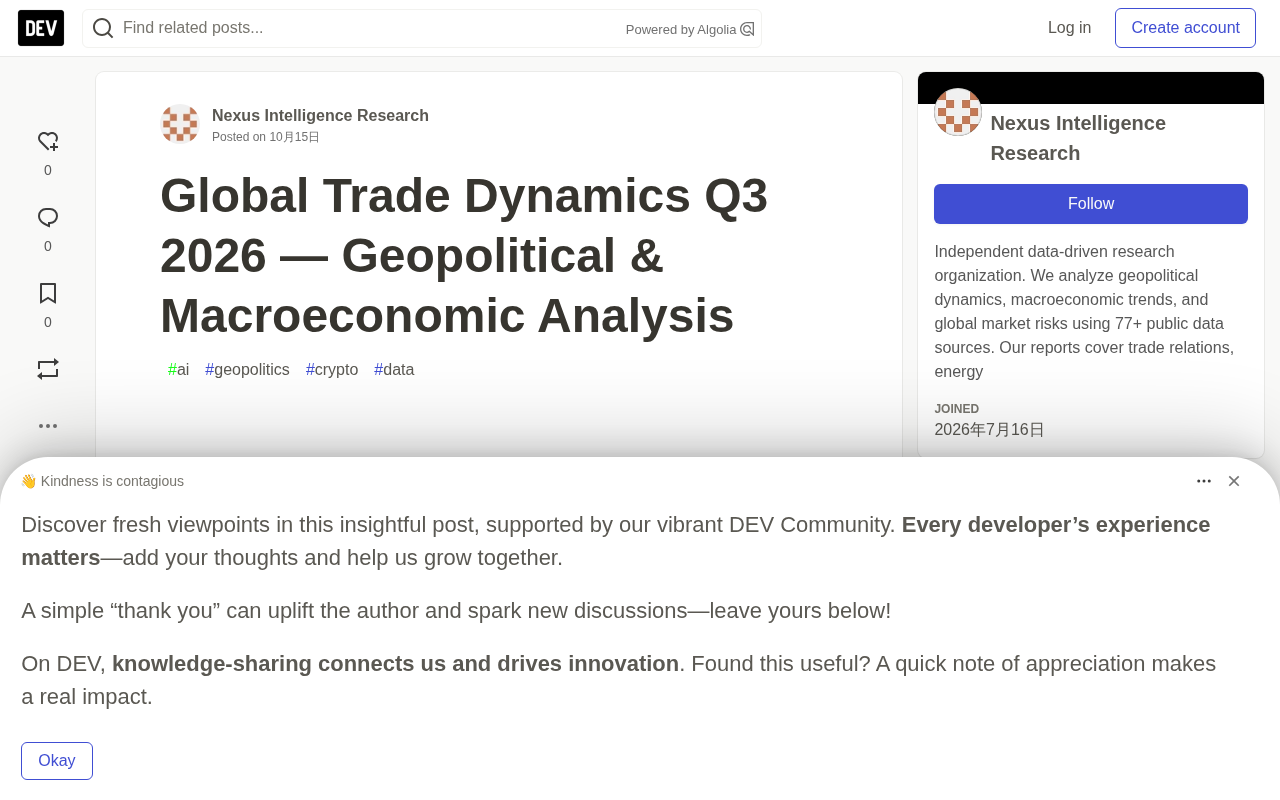
This is not an isolated case but a spreading content production pattern: wrapping low-information-density monetization pages in high-value keywords, then spreading them to aggregator platforms via RSS and automated publishing pipelines. It formally satisfies the minimum requirements of content distribution (title, body, structural tags) while substantively generating information noise.
A Three-Layer Dissection of Auto-Generated Content
Layer One: The "SEO Shell" of the Title
"Global Trade Dynamics" is itself a high-quality keyword combination that naturally attracts readers interested in international trade, supply chain restructuring, and geopolitical risk pricing. Add the time constraint "Q3 2026" and the professional suffix "Geopolitical & Macroeconomic Analysis," and the title becomes click-attractive in both search and RSS readers.
The problem is that there is no content contract between the title and the body. This is not clickbait—it is a complete severance between title and content: the title comes from a topic bank, the body from an affiliate marketing template, and the two are stitched together by an automated script, each unaware of the other's existence.
An SEO Shell refers to content whose title, summary, and structural tags (H1/H2, meta description) are optimized in isolation to maximize clicks on search and aggregation platforms, while the body carries no corresponding information. Common tactics include: extracting keyword combinations from high-search-volume topic banks (e.g., "geopolitics" + "macro" + "2026"), appending time qualifiers and professional suffixes to convey expertise, and using schema.org structured data and OG tags to render a complete summary card in aggregators. This strategy works because ranking and recommendation algorithms have long relied on surface-level signals such as title-click-through rate and keyword matching rather than semantic consistency. When titles and bodies are decoupled, the search engine's "title-body relevance" weight is systematically arbitraged.
Layer Two: The Monetization Logic of Tool Recommendations
The core structure of the body consists of an H2 heading "Recommended Tools" and three list items pointing to Binance (cryptocurrency trading), Ledger (hardware wallet), and Crypto.com (crypto asset buying/selling). All three links contain ref=YOUR_REF or similar parameters, indicating the standard format of affiliate links.
This pattern is especially prevalent in the cryptocurrency content space: use any title capable of driving search traffic to attract users, then insert affiliate links in the body to capture conversions. Trade analysis is merely the outer garment; crypto trading traffic is the core. The bridge between them is the assumption that "anyone following global macro likely also has allocation needs for crypto assets."
Affiliate Marketing refers to content publishers directing users to merchants via tracking-parameter links (e.g., ref=, utm_source=), earning commissions when users complete registrations or transactions. In crypto, commission rates from trading platforms and hardware wallets are typically a percentage of trading fees or fixed referral rewards, with a single valid conversion worth tens to hundreds of dollars—making it a primary monetization outlet for automated content. Accompanying this are "tracking pixels" and "conversion postbacks," enabling publishers to evaluate per-title/per-page conversion rates in real time and reverse-optimize title selection. This closed loop explains why high-traffic but low-relevance titles are reused: the KPI is not informational value but the click-to-registration conversion funnel.
Layer Three: The Attribution Paradox of the "Autonomous Research System"
The article ends with "This article was generated by Nexus Intelligence autonomous research system." A tool claiming to be an "autonomous research system" produces three ad links and a one-line disclaimer.
This exposes an industry-wide problem: labels like "autonomous research" and "intelligent generation" are being abused as quality endorsements. When readers see such attribution, they often assume a complete chain of data collection, analysis, and writing exists behind it—but what is actually delivered may be an empty shell. The easier automation becomes, the cheaper it is to fill in the minimum content that "looks like an article."
Why RSS Aggregators Become the Epicenter
RSS was designed to let readers subscribe to updates from trusted sources, but its open protocol also means that any address parseable as XML can enter the aggregation pipeline. This yields two consequences:
- Verification gap: Aggregators typically only check whether the feed format is valid, not content quality or source credibility
- Scale effect: A single auto-generation script can produce hundreds or thousands of "articles," and as long as one is subscribed to or indexed, it can continuously reach readers
For content moderation systems, the detection difficulty lies in this: it has a title, a body, links, and a closing statement—formally complete. What is truly missing is information gain: readers finish without acquiring any valid understanding of global trade, geopolitics, or macroeconomics.
This also explains why simple keyword filtering and length checks cannot solve the problem: a 200-word ad and a 2,000-word in-depth analysis—the latter is not necessarily more valuable, but the former is easier to identify; and as auto-generated content begins mimicking long-form structure, identification costs rise further.
RSS (Really Simple Syndication) is an XML-based subscription protocol in which publishers provide a feed address and aggregators or readers parse and display entries by format. Its protocol only specifies field structure (title, link, description, pubDate, etc.) and includes no source authentication, content signing, or quality rating mechanism—so any address conforming to the XML spec can be indexed. Historically RSS relied on "editor recommendations" and domain reputation to filter sources, but with the rise of automated aggregation and algorithmic recommendation, this human step has been greatly weakened. Moreover, feeds can be mirrored, proxied, and republished, often masking the original domain—making it difficult for aggregators to trace sources or assess content quality before indexing.
Two-Way Erosion for Readers and Platforms
For readers: Trust is consumed. When someone clicks on "global trade analysis" and is directed to crypto affiliate links, they will hesitate more next time they see a similar title—regardless of whether that one is real or fake.
For platforms: The content pool is diluted. Once recommendation systems and search rankings incorporate such pages, additional signals (dwell time, bounce rate, social sharing) are needed to correct course—and these signals themselves can be manipulated.
For genuine analysts: Attention is squeezed. Geopolitical trade and macroeconomic analysis are high-barrier fields requiring data sources, models, and historical context. When low-cost auto-generated content occupies the same distribution pipeline, the marginal exposure returns of quality content decline.
Content Farm and "information gain" are key terms for understanding this erosion. Information gain refers to the valid cognition or actionable conclusions readers acquire that they did not previously possess—distinct from formal metrics like word count or paragraph count. A content farm is an operating model that mass-produces formally acceptable content at low cost and monetizes through advertising or affiliate marketing, with economics built on "marginal production cost below per-conversion revenue." When generative tools drive the per-piece cost close to zero, farm-style expansion rapidly dilutes the platform content pool and raises the cost for recommendation systems to identify real value; meanwhile, negative signals like high bounce rates and short dwell times, once used as training data, may contaminate ranking models and further limit exposure for quality content.
A Checklist for Identifying Auto-Generated Content
From this sample, several practical identification features can be distilled:
- Extremely specific title, extremely hollow body—the title includes a specific time, specific field, and specific analysis type, yet the body contains no corresponding details
- The body is mainly a list of tools/products—and the links carry obvious affiliate parameters
- The ending has an "auto-generated" or "AI research system" disclaimer—but no explanation of data sources or methodology
- Complete page structure but extremely short paragraphs—H2/H3 in place, but each subsection is only one or two sentences
- Unclear source—distributed via RSS, but the original domain is inconsistent with or unverifiable against the attribution system name
Any one of these features alone does not necessarily indicate a problem, but when they stack up, the content's informational value is highly likely to be lower than its formal value.
Who Benefits, Who Suffers
Back to this sample itself: it is not a trade report to be "analyzed" but a content sample to be "identified." Its significance is not in conveying information but in testing the filtering capacity of the content ecosystem—from RSS scraping to aggregator indexing, from title generation to link insertion, every step tests automated systems' tolerance for "formally acceptable but substantively hollow" content.
For content creators, the value of this sample is inverse: it clearly demonstrates what kind of content should be avoided. For platforms, it raises a persistent problem: when the marginal cost of producing content approaches zero, the marginal cost of filtering content must rise.
Global trade analysis requires real trade data, geopolitical event tracking, and macroeconomic frameworks. Automated generation systems can assist with information organization but cannot replace analysis itself. When the words "autonomous research" are used to wrap three affiliate links, what suffers is not only readers' attention but the entire credibility foundation of automated content tools.
Related articles

LLaMA-Factory in Practice: A Complete No-Code Guide to Fine-Tuning Large Models
An introduction to LLaMA-Factory, the open-source fine-tuning tool: its 60.1K-star background, supported models and algorithms, local vs. cloud deployment, and CUDA setup steps.

Zeng Ming's Deep Retrospective: Why OpenAI May Not Be the Ultimate Winner — and Why the Corporate System Will Disappear
Zeng Ming's deep retrospective on the AI endgame: model companies are just infrastructure, OpenAI and Anthropic won't be the final winners; the next battle is the Agent entry point standard; the corporate system will disappear as AI restructures collaboration, and only mission-driven companies can survive the cycle.

OpenHands v1.28.0: OpenCode and PI Added as Built-in Agents, API Keys Requestable In-Conversation
OpenHands ships 5 releases in 21 days: v1.27.0 adds OpenCode and PI as built-in agents, v1.28.0 enables in-chat key requests. ACP integration, credential reuse, model list changes, and upgrade advice.