Running a 125B-Parameter LLM on a 12GB GPU: Strata Local Deployment Hands-On

Open-source Strata uses MoE to run a 125B-parameter LLM locally on a 12GB gaming GPU, free of API fees.
The article introduces Strata, an open-source project with 26,000 GitHub stars, demonstrating how to run a 125B-parameter MoE LLM locally on a 12GB-VRAM gaming GPU—escaping per-token cloud billing, data uploads, and peak-hour throttling. The cost: ~70GB model downloads and 58GB RAM usage. An RTX 5070 hits 94 tokens/s; dual RTX 3080s reach 109 tokens/s. Installation is a double-click script or AI-assisted, and the OpenAI-compatible API on localhost:8080 connects to coding agents. The article also covers RAM-based model selection, troubleshooting, and two hidden flags for 4%–10% extra speed.
Cloud models charge per token; local inference is free
Still paying per token for cloud models? Bilibili creator FT recently got hands-on with Strata, an open-source project that has already racked up 26,000 stars on GitHub, and successfully ran a 125-billion-parameter model on a gaming PC with 12GB of VRAM. The most striking contrast is: cloud models deduct money per token, require uploading your data, and get rate-limited during peak hours; meanwhile, Strata runs locally as much as you want, for free.
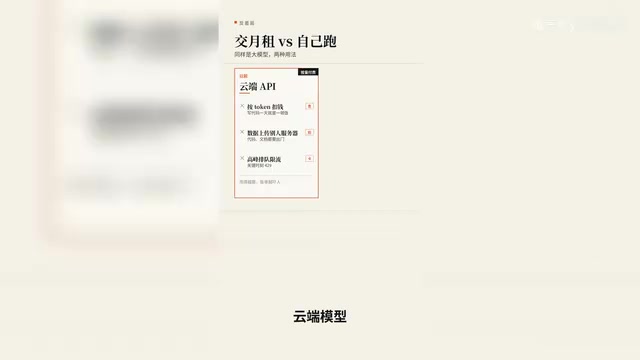
The trade-off is clear too—roughly 70GB of model downloads, plus a GPU with 12GB of VRAM. The creator's summary in the video nails it: "What's lacking isn't the model—it's that you're still paying a monthly subscription."
The benchmark data comes from its built-in monitoring page, not a slide-deck benchmark: an RTX 5070 spits out 94 tokens per second, and an AMD 9070 XT manages 60 per second (note: the original text also contained a garbled phrase about "2650 per second" that was not adopted). VRAM usage hits 11.2GB, just filling up a 12GB card; memory usage is 58GB. A single request holds steady at around 50 tokens per second.
Installation is absurdly simple: double-click a script, or let AI install it for you
Installation is absurdly simple. After downloading and extracting, double-click the startup script on Windows, or run setup on Linux. It only asks three things: which model to pick, how long the context should be, and whether you want image support. Just press Enter the whole way through. The 70GB download auto-resumes if interrupted, and the browser pops up on its own once it's done—you don't even have to type a command.
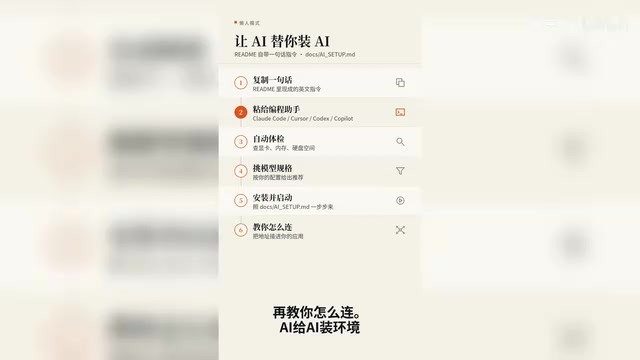
Even more interesting is the "AI sets up the environment for AI" path: paste that one line from the README directly into cloud code, and it will check your GPU, memory, and disk on its own, pick the right model, finish the install and launch, then teach you how to connect. The creator's verdict: "absolutely ridiculous."
Once installed, it handles chatting, coding, and image understanding with ease. Thinking intensity has four levels; turning it off is fastest, and the "Gundam" level is for chewing through hard problems. The video's spec recommendations are based on RAM: 32GB of memory → choose Coder (specialized for coding, scoring 91% of the full write-up version); 48GB → 2-bit; 64GB → install whatever you like; 96GB+ → go straight to the largest. Note: don't pick Coder if you're chatting in Chinese.
The cloud code and Codex mentioned repeatedly in the article belong to the "coding agent" category of tools: they don't produce intelligence themselves; rather, they act as a shell that calls the underlying LLM API to read files, modify code, execute commands, and so on. These tools generally comply with OpenAI's Chat Completions interface spec, so as long as you point the base URL at your local service and fill in any API key, you can swap the backend from the cloud to the model running locally. That's why "set the address to localhost:8080 and type any key" works—the agent no longer pays the cloud per token; the cost shifts to your own electricity bill and GPU.
How does it fit: 24,000 tiny experts, only 10 woken up per word
Stuffing 125 billion parameters into 12GB of VRAM relies on the MoE architecture. The model contains over 24,000 tiny experts, and each word only wakes up 10 little assistants. First guess with a big model, then verify—speeding things up 6 to 1.8 times. Frequently used parts go on the GPU, everything goes in RAM—the more memory, the more you can fit.
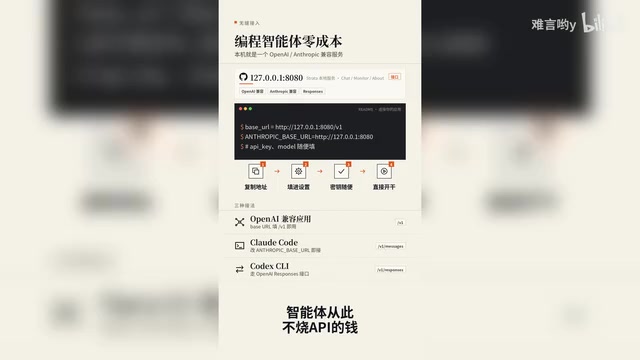
The interface supports OpenAI applications: set the address to localhost:8080, type any key, change one environment variable in cloud code and you're connected—Codex works too. From now on, agents can write without burning API money.
MoE (Mixture of Experts) is an architecture that splits a large model into multiple "expert" sub-networks. Unlike traditional dense models that activate all parameters for every inference, MoE has a router at each layer that computes a match score for each expert for every token, activating only the few highest-scoring experts to participate in computation. Therefore, the model's total parameter count and the number of parameters actually used per inference are two different things: the former determines the model's capability ceiling and storage requirements, while the latter determines compute and VRAM overhead. This is precisely the key to fitting a 125-billion-parameter model into 12GB of VRAM—only the currently active experts need to reside in VRAM, while the rest can live in RAM or even on disk and be swapped in on demand. The cost is that memory bandwidth becomes the new bottleneck, and since different tokens go to different experts, batching efficiency suffers.
The phrase "first guess with a big model, then verify" refers to Speculative Decoding. It works by first using a small, fast draft model to guess several tokens in a row, then handing them to the large model to verify all the guesses in parallel at once—accepting the correct prefix and discarding the wrong parts. Since the large model can validate multiple positions in a single forward pass, this effectively trades a small amount of extra compute for more useful output, boosting throughput without changing the output distribution. This is also a common speedup technique for local inference, and it can be stacked with MoE's sparse activation.
The community is going wild: dual-GPU rigs, old cards grinding it out
The community has already taken configurations to creative extremes. Two RTX 3080s stitched together hit 109 tokens per second; officially, a single 3090 is expected to reach 100 to 140. Some people are even forcing it to run on old Macs.
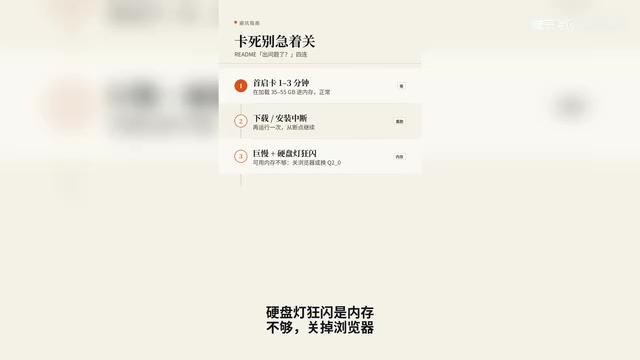
A few common pitfalls are worth knowing in advance: don't panic if the first launch seems frozen—it's stuffing tens of GB into memory, so wait one to three minutes; if the download breaks, just rerun it; a frantically blinking disk light means insufficient memory; close the browser; if it says port 8080 is in use, that means it's already running.
There are also two hidden speed-up switches: add "adaptive" to the parameter in the config file, and add "lock on demand" to the environment variable—generation gets 4% to 5% faster, and coding gets 7% to 10% faster. Windows prompt reading gets another 4.4% faster. The first load of the 70GB model takes several minutes, but after that it opens instantly on double-click without re-downloading, and closing the window stops it. To upgrade, run the update script; to add models, run the installer again.
Getting-started checklist
Key points to highlight: 12GB of VRAM plus 32GB of RAM is enough to get started; double-click to install, or let AI install it for you; point the interface at localhost:8080; don't just hit like—make your gaming GPU work for you tonight.
Related articles

Bilibili's Hit Dify Tutorial: A Practical Guide to Building 20+ AI Apps from Scratch
A distilled guide to Bilibili's top-rated Dify tutorial: Windows + Docker deployment, MySQL connection, five app types, model integration strategy, and publishing.

Agent Skills Beginner's Guide: From Concepts to Multi-Agent Collaboration in Practice
A comprehensive guide to Agent Skills: core concepts, components, the importance of Description, standardization, beginner learning paths, and multi-agent collaboration.

One Neuron Detects Both Cats and Cars? We Reproduced It and Found a New Explanation
The cat-car neuron reinterpreted: researcher Cammarata argues it distinguishes pointy from round, not cats from cars. We reproduced the experiment and found the new explanation holds on most inputs—but cars are the exception. The interpretability debate continues on language models.