Scientific Liquidity Agents: How Knowledge Arbitrage Reshapes Research Communities

SLA models knowledge arbitrage with agents, showing connectivity relies on intermediaries and the bottleneck is verification.
A paper on Scientific Liquidity Agents (SLA) proposes an agent-based model making "knowledge liquidity" simulatable and measurable. It introduces domain specialists and epistemic arbitrageurs, linking individual decisions to collective states via BDI architecture, a precondition problem graph, a dynamic interaction network, and a publication registry. Simulations show arbitrageurs connected the community into one component, while topic similarity alone fragmented it into seven. Papers were abundant but reproduction successes were zero, locating the bottleneck at verification. SLA's core contribution is making the arbitrageur role and transfer friction explicit, offering an actionable lens for research policy and platform design.
In research communities, a long-overlooked role is being reexamined through computational models: "knowledge arbitrageurs"—those who don't directly produce knowledge but instead move ideas, methods, and results across domains. A paper on Scientific Liquidity Agents (SLA) proposes an agent-based model that attempts to turn "knowledge liquidity" into something simulatable and measurable.
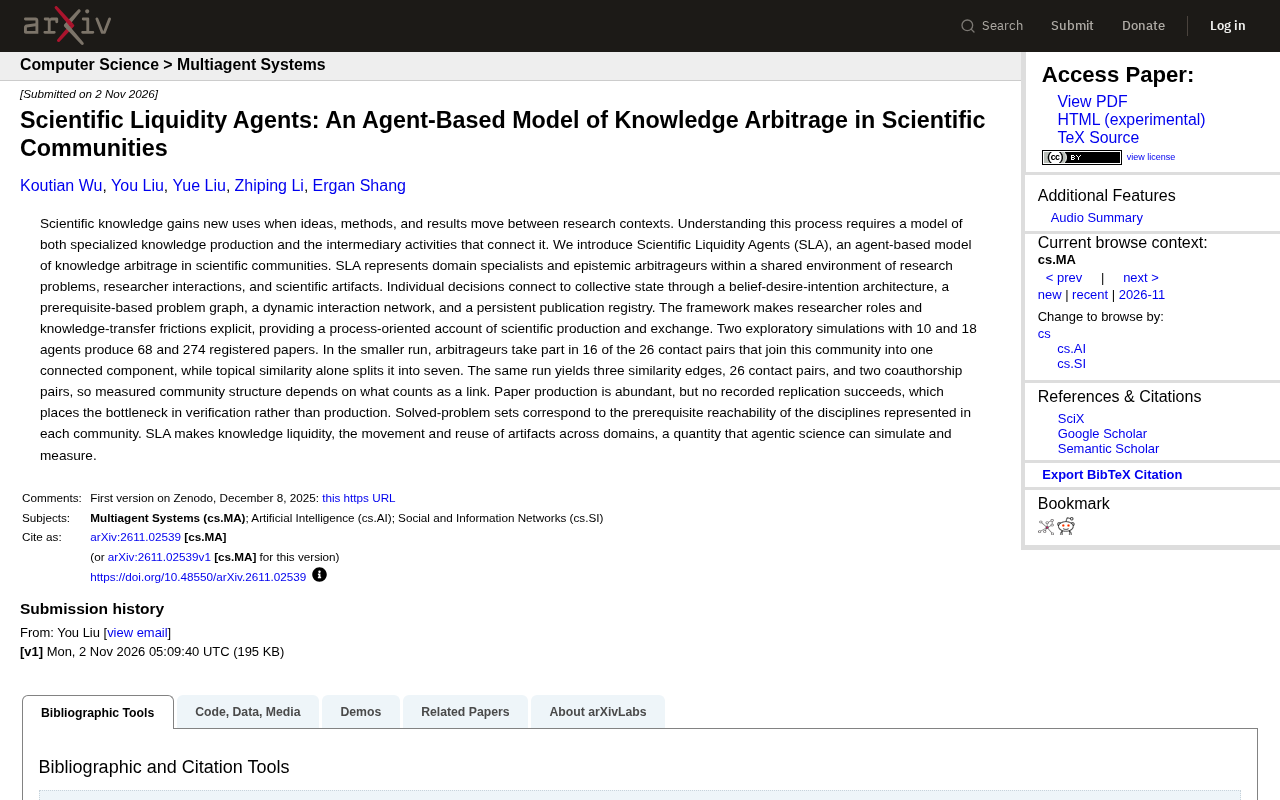
Knowledge Arbitrage: The Invisible Connector in Research
Scientific knowledge generates new uses when it flows across contexts. The paper argues that understanding this process requires modeling two things simultaneously: the production of specialized knowledge, and the intermediary activity that connects knowledge. The SLA model therefore introduces two types of roles—domain specialists and epistemic arbitrageurs. The latter do not focus on a narrow field but instead seek "knowledge spreads" that can be transferred across domains within the shared environment of research questions, researcher interactions, and scientific artifacts.
The value of this perspective lies in reframing the research community from "a group of independent researchers" into a network with intermediary nodes. Knowledge does not diffuse automatically; the presence of arbitrageurs reduces the friction of knowledge transfer.
Model Architecture: Belief-Desire-Intention Driven Research Behavior
SLA's individual decision-making connects to collective states through four core components:
- Belief-Desire-Intention (BDI) architecture: provides goal-directed behavioral logic for each agent;
- Precondition problem graph: research problems have dependencies—solving one problem requires first satisfying its preconditions;
- Dynamic interaction network: contact relationships among researchers evolve over time;
- Persistent publication registry: records produced papers, forming a trackable stock of collective knowledge.
This combination allows the model to explicitly represent researcher roles and knowledge transfer friction, offering a process-oriented explanation of scientific output and exchange rather than focusing solely on final paper counts.
The BDI architecture originates from rational agent theory in artificial intelligence, decomposing an agent's behavioral choices into three levels: Belief (cognition about the world), Desire (goals one hopes to achieve), and Intention (plans one commits to executing). In SLA, each simulated researcher forms research desires based on beliefs about the problem graph and interaction network, then selects the next action through the intention mechanism—such as solving a precondition or initiating a cross-domain contact. The advantage of BDI is that it captures goal-directed behavior while retaining responsiveness to changes in the external environment, making it suitable for simulating "strategic but not fully rational" individual decision-making in research.
The precondition problem graph is a directed graph structure where nodes represent research problems and edges indicate that solving one problem is a prerequisite for solving another. This representation draws on the idea of "problem dependence" in the philosophy of science and is also similar to task dependency graphs in project management. In SLA, the problem graph determines the paths of knowledge exploration: agents must first satisfy preconditions before unlocking subsequent problems. Therefore, reachability on the problem graph becomes a key indicator of knowledge liquidity—even if a community produces many papers, if preconditions on the problem graph are difficult to satisfy, its knowledge flow remains constrained.
Simulation Experiments: Plentiful Papers, But Verification Absent
The paper conducted two sets of exploratory simulations, using 10 and 18 agents respectively, producing 68 and 274 registered papers. The larger run clearly generated more output, but the key finding is not about quantity.
In the smaller run, arbitrageurs participated in 16 of 26 contact pairs, and these contact pairs connected the entire community into a single connected component; whereas partitioning by topic similarity alone would split the community into seven parts. The same run also produced three similarity edges, 26 contact pairs, and two co-authorship pairs. This means that the measured community structure depends heavily on "what counts as a link." Measured by topic similarity, the community is fragmented; measured by actual contact, arbitrageurs are the force holding the fragments together.
Another notable result: paper output was abundant, but no documented reproduction successes occurred. The authors conclude that the bottleneck lies in verification, not production. In other words, the scientists in the model are good at writing papers but not at confirming whether those papers hold up.
The set of solved problems corresponds to the precondition reachability of the disciplines represented by each community. This suggests that knowledge liquidity is not just about paper counts but about reachability on the problem graph.
Reproduction success in computational science refers to the process by which independent researchers using the same data and code obtain results consistent with the original paper. It is a core element of science's self-correction mechanism, but in agent-based simulations, reproduction requires additional modeling of verification behaviors—such as repeating experiments, checking code, or cross-comparing results. The zero reproduction success in SLA simulations does not necessarily mean the scientists in the model are "dishonest"; rather, it indicates that the model does not allocate sufficient incentives or resources to verification behavior. This result echoes research on the real-world reproducibility crisis: when output metrics (paper counts) dominate verification metrics, the system systematically favors production over confirmation.
Knowledge Liquidity: A Measurable Variable in Agent-Based Science
SLA's core contribution is turning "knowledge liquidity"—the degree to which artifacts move and are reused across domains—into a quantity that agent-based science can simulate and measure. The paper makes the arbitrageur role and transfer friction explicit, allowing the tensions among community connectivity, reproduction failure, and problem reachability to be discussed within a single framework.
For research policy or platform design, this suggests an actionable direction: if arbitrageurs are key nodes of community connectivity, then mechanisms that encourage cross-domain contact may do more to change the structure of knowledge flow than simply increasing paper output. At the same time, the revelation of the reproduction bottleneck reminds us that there may be a systematic disconnect between output metrics and verification capacity.
Agent-based Science refers to the computational modeling paradigm that uses autonomous agents to simulate researcher behavior, interactions, and knowledge evolution within scientific communities. Unlike traditional scientometrics, it does not rely on retrospective statistics of papers and citations but instead generates collective patterns bottom-up from individual decision rules. SLA belongs to this paradigm, and its value lies in enabling researchers to conduct counterfactual experiments: changing the proportion of arbitrageurs, adjusting the connectivity of the problem graph, or introducing verification incentives to observe how community structure changes. The credibility of such models depends on the empirical basis of behavioral rules and calibration methods, so they are typically regarded as exploratory tools rather than predictive ones.
One-line Summary
SLA models knowledge arbitrage with agents, revealing that community connectivity relies on intermediaries and the reproduction bottleneck lies in verification.
Paragraph Summary
A paper on Scientific Liquidity Agents (SLA) proposes an agent-based model that turns "knowledge liquidity" into something simulatable and measurable. The model introduces two role types—domain specialists and epistemic arbitrageurs—and connects individual decisions to collective states through a BDI architecture, a precondition problem graph, a dynamic interaction network, and a publication registry. Simulation experiments show that arbitrageurs participated in 16 of 26 contact pairs, making them key to connecting the community into a single connected component; by topic similarity alone, the community would split into seven parts. Meanwhile, paper output was abundant but reproduction successes were zero, pinpointing the bottleneck at verification rather than production. SLA's core contribution is making the arbitrageur role and transfer friction explicit, offering an actionable perspective for research policy and platform design.
Related articles

9 AI Subscription Plans Compared: The Real Cost Per 100M Tokens Revealed
Bilibili creator tests 9 AI subscription plans from Volcano, Alibaba, Tencent, Baidu, Zhipu, Xiaomi, MiniMax and more, converting them all to real cost per 100M tokens, breaking down fixed-quota vs. three-tier coefficient billing and how caching, time-of-day discounts, and window limits affect actual quota.

Vibe Coding for Beginners: Expressing Intent Instead of Handwriting Code
What is Vibe Coding? A 137-episode Bilibili course defines it: the core is expressing intent, not writing code. This article analyzes Vibe Coding's productivity logic, target audience, and entry expectations to help beginners decide if it's worth learning.

LangChain Beginner's Guide: An Agent Development Roadmap from LangGraph to Deep Agents
Clarify the encapsulation relationship among LangChain, LangGraph, and Deep Agents, and master the learning path and selection logic for agent development frameworks—suitable for beginners in large model development.