Security Researchers Used Claude to Hack Into OpenAI Employee Accounts
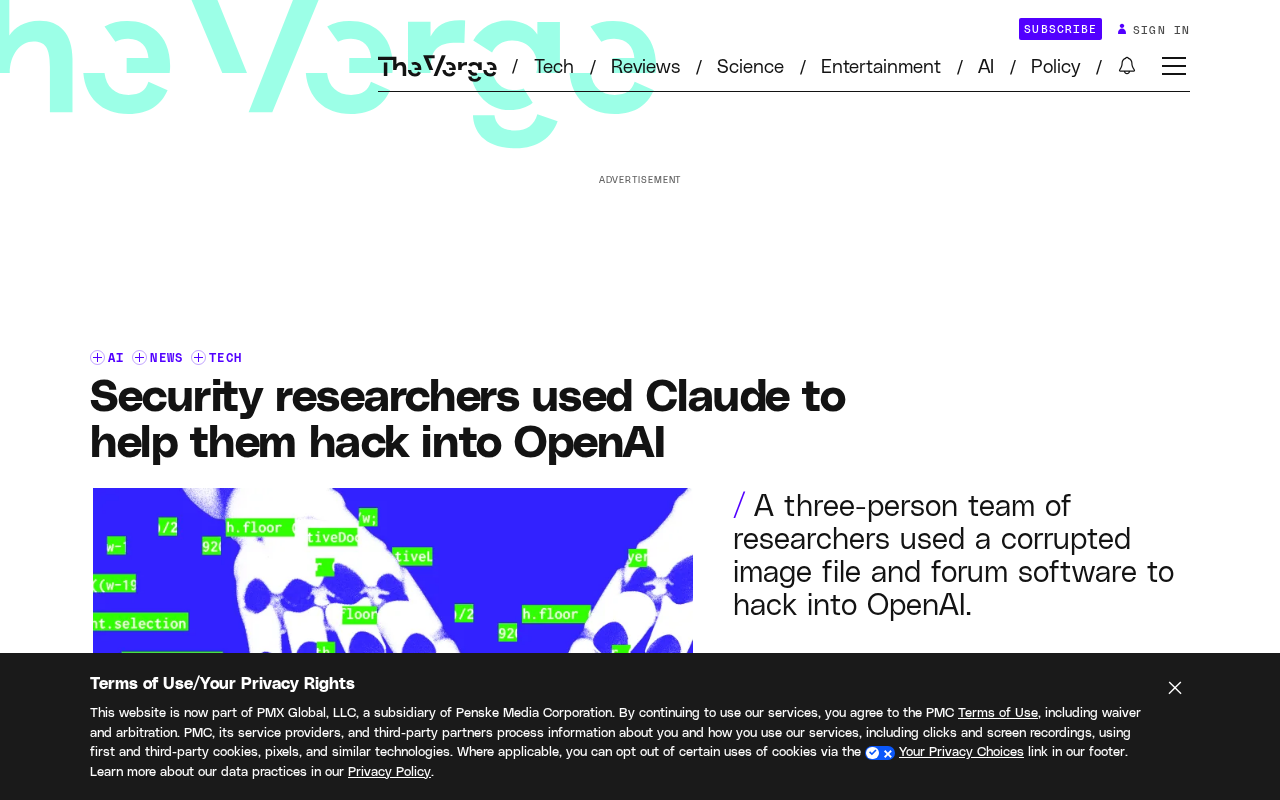
Security researchers used Claude to breach OpenAI's core code repository in under 72 hours, revealing a new AI-assisted attack paradigm.
According to The Wall Street Journal, three Hacktron security researchers used Anthropic's Claude Opus 4.8 and Claude 5 models to breach OpenAI employee accounts in under 72 hours, gaining access to a Monorepo allegedly containing algorithmic secrets. The core warning isn't that OpenAI was compromised, but that LLMs are becoming efficiency accelerators in the attack chain — helping generate social engineering scripts, map attack paths, and write exploit code, compressing weeks-long penetration efforts into days. The incident also exposes two industry pain points: current model safety guardrails can still be bypassed in real-world scenarios, and enterprise account security and code repository access controls urgently need reassessment.
Overview
According to a report by The Wall Street Journal, three independent security researchers from Hacktron claim they successfully breached OpenAI employee accounts in under 72 hours using Anthropic's Claude Opus 4.8 and Claude 5 models. The incident not only exposed gaps in internal security at a major AI company, but also thrust the topic of "AI-assisted attacks" back into the spotlight across the industry.
The researchers claim they ultimately gained access to OpenAI's internal GitHub repository known as "Monorepo." This repository reportedly contains "OpenAI's algorithmic secrets" — the kind of core assets whose exposure would be catastrophic for any frontier AI company.
A New Attack-Defense Paradigm: AI as an Offensive Tool
What makes this incident most noteworthy isn't just that OpenAI was compromised — it's the tool the attackers used: Claude, a large language model developed by rival Anthropic. Historically, penetration testing and vulnerability research relied heavily on a researcher's experience and manual effort. Today, large language models are becoming "accelerators" within the attack chain.
Based on publicly available information, the research team went from initial access to reaching the core code repository in under 72 hours. This dramatic efficiency gain is one of the most alarming signals in current AI security discussions: the same model capabilities can be used for both defense and offense. When a model can help write exploit code, analyze attack paths, and generate social engineering scripts, the barrier to entry and time cost of attacks are being significantly reduced.
Why "72 Hours" Should Alarm Everyone
For an intrusion targeting a leading AI company, 72 hours is an extremely short window. It means that even organizations at the forefront of the industry in terms of security awareness and resources may have significant gaps when facing AI-augmented attacks. This is a reminder to all enterprises: the traditional security model — premised on "human vs. human" — is being broken.
In the security research field, the framework of AI-assisted attacks is often called AI-augmented penetration testing. Traditional penetration testing requires researchers to manually write exploit scripts, consult CVE databases, and advance the attack chain step by step — a process heavily dependent on individual experience. The introduction of large language models changes several critical steps in this workflow: they can rapidly generate targeted spear phishing content for specific targets, assist in analyzing a target system's tech stack and recommending attack paths, and help write code for privilege escalation or lateral movement after initial access is gained. This "human-led decision-making, model-accelerated execution" model makes it possible to compress attack chains that once took weeks into days or even hours. It's worth noting that these same capabilities can be applied defensively — blue teams can use the same models to automate vulnerability scanning and threat modeling, which is why the industry broadly believes AI will amplify capabilities on both sides of the offense-defense equation, rather than exclusively empowering attackers.
Potential Impact of the "Algorithmic Secrets" Leak
The Monorepo repository allegedly contains OpenAI's algorithmic secrets. For a company whose core competitive advantage lies in model technology, a code repository is not just an engineering asset — it also contains training methodologies, architectural details, and commercial moats. The risks of unauthorized access to such information include:
- Technology leakage: Core algorithms and engineering implementation details could be copied or reverse-engineered.
- Supply chain risk: Code repositories are often connected to numerous internal systems and credentials.
- Trust crisis: For an AI company serving large numbers of enterprise clients, a security incident directly undermines customer confidence.
It should be noted that this operation was conducted by an independent security research team, and its nature is closer to security research and vulnerability disclosure than to a purely malicious attack. However, the attack feasibility revealed by their findings is what the industry truly needs to confront.
Monorepo (monolithic repository) is an engineering practice in which a company stores all or most of its code in a single version-controlled repository. It is widely used by major tech companies like Google, Meta, and Microsoft. Its advantages include simplified dependency management and cross-team collaboration, but the security trade-offs are significant: once an attacker gains access to the repository, they can often simultaneously access source code across multiple product lines, embedded API keys and service account credentials, CI/CD pipeline configurations, and Infrastructure-as-Code (IaC) files. For a company like OpenAI, the Monorepo may store model training scripts, data processing pipelines, evaluation frameworks, and other high-value assets. This explains why "accessing the Monorepo" is regarded as an extremely high-severity attack outcome in security circles — not an ordinary code leak — because it provides a "god's-eye view" of the entire technology ecosystem.
Implications for AI Industry Security Governance
This incident puts two long-discussed but slow-to-materialize issues back on the table.
Model Abuse Prevention Remains an Unsolved Problem
Major vendors have implemented safety guardrails for their models in an attempt to prevent them from being used to generate offensive content or code. Yet researchers were still able to leverage Claude to carry out a real-world intrusion, indicating that existing abuse prevention mechanisms can still be bypassed in genuine, complex attack-defense scenarios. Balancing model utility against restricting its offensive applications remains a challenge shared by all frontier labs.
The safety guardrails in mainstream AI models primarily rely on refusal policies instilled during the RLHF (Reinforcement Learning from Human Feedback) training phase, along with content filters at the inference layer. However, the security research community has documented numerous bypass methods, including roleplay prompt injection (getting the model to output restricted content under the guise of a "fictional scenario"), multi-step request decomposition (splitting a single dangerous instruction into multiple seemingly harmless subtasks), and adversarial prefixes. Anthropic's Claude series is generally considered to have a relatively strict safety policy on public benchmarks, but this incident demonstrates that in the complex context of real-world attack-defense scenarios, no single guardrail mechanism can be made airtight. This is precisely why the industry is increasingly emphasizing "defense in depth" — you cannot rely solely on the model's own refusal capabilities; additional monitoring must be layered at the API call level and user identity verification level.
Enterprise Internal Security Needs Reassessment
Compromised employee accounts are typically the result of social engineering, phishing, or credential leakage. AI's involvement makes these classic attack techniques faster and more convincing. For AI companies and tech enterprises alike, strengthening multi-factor authentication, least-privilege access management, and code repository access auditing has never been more urgent.
Conclusion
Using one company's model to breach another company's systems is, in itself, deeply symbolic. It marks a moment where AI is simultaneously the object being protected and an emerging capability resource being contested by both attackers and defenders. For the entire industry, how to keep pushing the boundaries of model capabilities while holding the security line is a question that must continue to be answered.
(Note: This article is based on reporting from The Wall Street Journal and publicly available information. Specific technical details are subject to future official disclosure.)
Related articles
GPT-6 Controls Blender to Generate Grey-Box Previz: A New Approach to Controllable AI Video
How a Bilibili creator used GPT-6 via Codex to control Blender for grey-box previz, then rendered final video with Seedance 2.5 — achieving highly controllable AI video shots.
GPT-6 Astra Tested: 5 Real-World Cases That Put the 'AGI' Claim to the Test
GPT-6 Astra vs Kimi K3 vs GLM 5.3: a hands-on benchmark across 5 cases — universe browser, Apple-style product page, Plants vs. Zombies, Blender 3D modeling, and Xiamen city flythrough.
Masayoshi Son's All-In Bet on OpenAI: The Unicorn Hunter from Yahoo to GPT-6
SoftBank surged $70B in 4 days after GPT-6 Astra launched. Behind it: Masayoshi Son's decades-long bet from Yahoo and Alibaba to ARM and OpenAI.