Seq2Seq Model Only Predicts Padding Tokens? Common Causes and Fixes

Unmasked padding in the loss function is the #1 reason seq2seq models only output padding tokens.
A student with no formal neural network training encountered a classic beginner trap while building a seq2seq model: it kept predicting padding tokens instead of meaningful output. The core cause is a loss function that doesn't mask padding positions, letting the model exploit padding as a shortcut to lower loss. High padding ratios in training data make things worse. Fixes span multiple levels: loss masking, teacher forcing, and gradient clipping during training; beam search and length constraints during inference. Beginners are advised to start with toy datasets and treat each failure as a chance to understand the fundamentals.
A Common Beginner Struggle
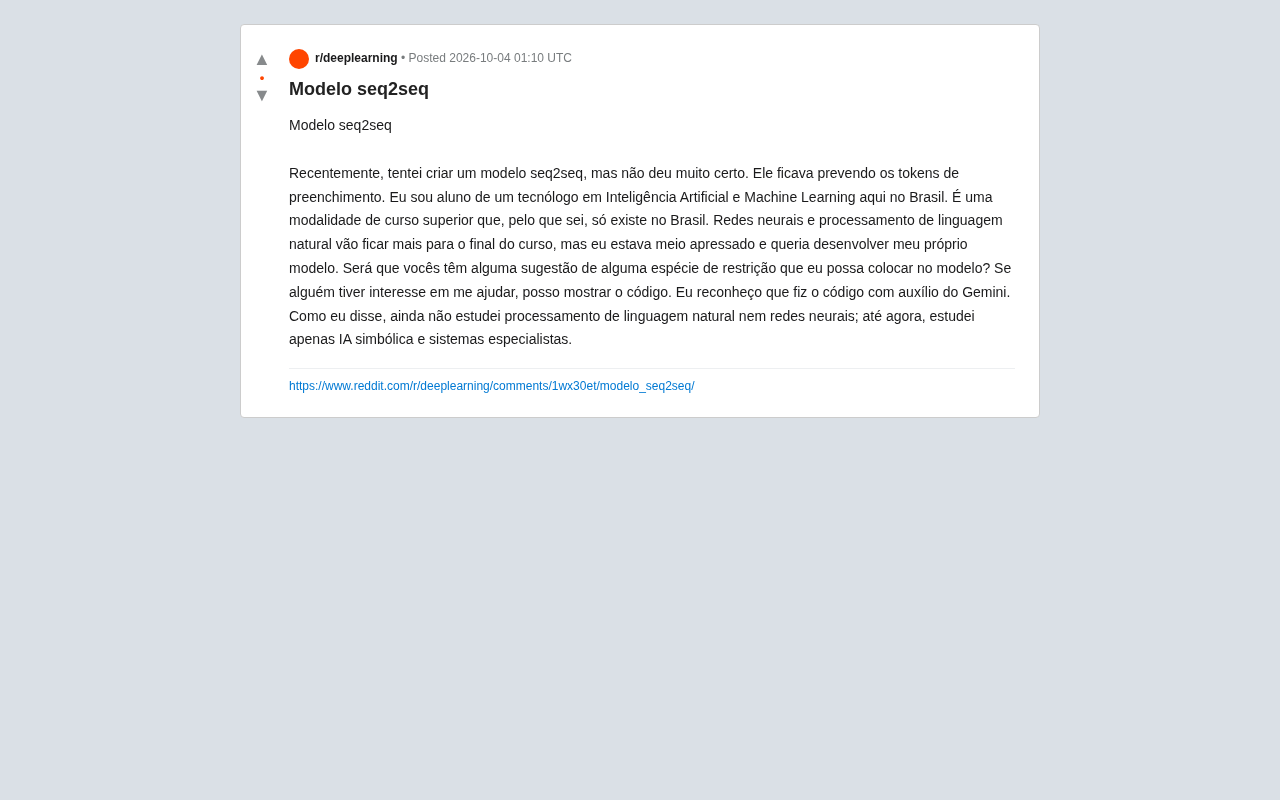
A Brazilian AI and machine learning student posted on Reddit asking for help: they had tried building their own seq2seq (sequence-to-sequence) model from scratch, only to run into a classic training failure — the model kept predicting padding tokens instead of generating meaningful output.
The student admitted that their coursework hadn't yet covered neural networks or natural language processing, and that they had only studied symbolic AI and expert systems so far. They wrote the code with the help of Gemini, but the model wasn't performing as expected. This is actually a classic problem that many beginners encounter when first working with deep learning sequence models, and the underlying causes are worth examining systematically.
Why the Model Only Predicts Padding
Seq2seq models are widely used in NLP tasks such as machine translation, text summarization, and dialogue generation. They typically consist of an encoder and a decoder. When a model "takes the lazy route" and only outputs padding tokens, the problem usually isn't in the model architecture itself — it's in a few critical parts of the training pipeline.
Loss Function Not Masking Padding Positions
The most common root cause is failing to ignore padding tokens when computing the loss. In sequence tasks, sentences of varying lengths within a batch are aligned by padding shorter sequences with a special token. If you don't mask these padding positions when computing cross-entropy loss, the model quickly discovers that blindly outputting padding yields very low loss across all those padded positions. It learns this shortcut.
The fix is to set ignore_index to the padding token's index in your loss function (PyTorch's CrossEntropyLoss supports this parameter), or manually construct an attention mask and loss mask to ensure padding positions don't contribute to gradient updates.
Severely Imbalanced Data Distribution
If padding tokens make up an excessively large proportion of the training data — for example, if many short sentences are padded out to a very long fixed length — the model will also tend to predict this high-frequency symbol. Keeping the maximum sequence length reasonable and using length-based bucketing when forming batches can significantly mitigate this issue.
The seq2seq (Sequence-to-Sequence) architecture was introduced by Sutskever et al. in 2014, originally for machine translation. The encoder compresses the input sequence step by step into a fixed-dimensional context vector, and the decoder uses this as a starting point to generate the output sequence token by token. Early implementations were based on LSTMs or GRUs; modern implementations heavily adopt the Transformer architecture's attention mechanism, which handles long-range dependencies more effectively and avoids the information bottleneck of compressing everything into a single vector. Understanding how information flows between the encoder and decoder is essential for diagnosing abnormal model outputs — when the decoder goes off track at the very first step, the problem usually lies in how the training signal (i.e., the loss function) is designed, not in the architecture itself.
Constraints and Improvements to Try
The original poster specifically asked whether some kind of "constraint" could be added to the model. "Constraint" can be understood at several levels.
Training-Level Constraints
- Loss masking: This should be your first priority — directly exclude padding tokens from contributing to the loss.
- Teacher forcing: When training the decoder, use the ground-truth target token as the input at each step rather than the model's own previous prediction. Without teacher forcing, early training becomes highly unstable.
- Learning rate and gradient clipping: Sequence models are prone to exploding or vanishing gradients. Appropriate gradient clipping and a sensible learning rate schedule make training much more stable.
Teacher Forcing is a core technique for training sequence generation models, introduced by Williams and Zipser in 1989. The key idea is that during decoder training, each step's input is the actual ground-truth token from the target sequence rather than the model's prediction from the previous step. This stabilizes gradient signals and prevents errors from snowballing across time steps due to poor early predictions — a phenomenon known as "exposure bias." However, Teacher Forcing has a downside: the input distribution during training differs from that during inference, which can hurt inference-time performance. To address this, researchers proposed Scheduled Sampling and similar approaches that gradually introduce the model's own predictions as inputs during later stages of training, helping the model adapt to the inference setting.
Decoding-Level Constraints
During inference, you can restrict output behavior in the following ways:
- Suppress or reduce the probability of generating padding or special tokens;
- Use beam search instead of greedy decoding to improve output quality;
- Set minimum and maximum generation lengths to prevent the model from outputting an end token too early.
Beam Search is the most commonly used decoding algorithm in sequence generation tasks. Compared to greedy decoding (which only keeps the single highest-probability token at each step), beam search explores a wider candidate space. It maintains K candidate sequences (where K is the beam width) with the highest scores at each time step, ultimately selecting the output with the highest overall probability. A larger beam width generally improves output quality but increases computational cost linearly. In practice, a beam width of 4 to 10 is a common choice. Additionally, a length penalty parameter can prevent the model from favoring overly short sequences, while a repetition penalty can suppress the tendency to repeatedly generate the same token — a particularly common issue when the model is undertrained.
Advice for Self-Learners Starting from Scratch
This student's situation is quite representative: their coursework hasn't reached neural networks yet, but their curiosity drove them to dive in early. That hands-on spirit deserves credit, but it's also worth recognizing that seq2seq involves a significant amount of prerequisite knowledge — backpropagation, word embeddings, and how RNNs/LSTMs or Transformers work are all foundational to understanding "why the model behaves this way."
Using AI assistants like Gemini to generate code is an efficient way to learn, but if you don't understand what each line does, pinpointing the source of a bug becomes very difficult. A more reliable path is to start with a tiny toy dataset, make sure you can correctly run through the simplest possible translation or copy task, and then gradually increase complexity. Many well-established tutorials — such as PyTorch's official seq2seq translation tutorial — provide runnable, well-commented reference implementations that are great for comparing against your own code when debugging.
Summary
A model that only predicts padding tokens is almost certainly caused by a loss function that doesn't mask padding — this is the number one pitfall at the seq2seq beginner stage. Combined with teacher forcing, gradient clipping, and a reasonable decoding strategy, most issues of this kind can be resolved. For self-learners who haven't yet studied NLP systematically, treating these "failures" as opportunities to deeply understand the underlying mechanics is far more valuable than simply copying working code.
Related articles

Multi-Agent Voice Command Center in Practice: Deconstructing the VAPI + Supabase Architecture
Deconstructing the Load Bearing Empire multi-agent voice command center: VAPI voice pipeline, Supabase Edge Functions for Webhooks, 8 Postgres tables tracking agent state, and Vercel-managed frontend design.

Astro 7 Rewrote Every Page, So IndexNow Now Hashes What a Crawler Reads
NeuraGrowth documents how an Astro 7 upgrade caused 273 pages to be misjudged as updated, and switched IndexNow hashing from file bytes to crawler-readable content—text, links, title, meta, and JSON-LD only.

From Python to AI Agents: A Full-Stack Learning Path with 488 Lessons and 23 Projects
A Udemy course covering Python, machine learning, deep learning, LLMs, RAG, and AI Agents, with 488 lessons and 23 real-world projects. This article analyzes the logic of this full-stack AI learning path, who it suits, and self-study advice.