Should Claude Code Read AGENTS.md by Default? A Debate Over Who Owns the Complexity
Shopify's potential Claude Code ban exposes who should own rule complexity in AI coding tools.
Shopify CEO Toby is considering banning Claude Code internally because the tool doesn't default to reading the widely adopted `AGENTS.md` convention file — while most other AI coding tools do. On the surface, it's a one-line manual import decision. But in large enterprise repositories with hundreds of rule files across directory levels, missed manual syncs can create two conflicting sets of rules, threatening security and compliance. The product team counters that `AGENTS.md` and `CLAUDE.md` use fundamentally incompatible priority models, so silently defaulting to reading both means making high-risk decisions on behalf of customers. At its core, this is a debate about whether AI tools entering enterprise environments should absorb rule complexity centrally, or require teams to explicitly own it.
A Single File Sparks a Potential Ban
Shopify CEO Toby is reportedly considering banning Claude Code internally — and the trigger isn't pricing or model capability. It's a project rules file written specifically for AI agents: AGENTS.md.
The controversy is surprisingly subtle. Claude Code isn't incapable of reading this file — teams can manually import it inside CLAUDE.md. The real disagreement is whether the tool should automatically scan directories and read AGENTS.md without any explicit declaration.
That sounds like something a single line of code could fix. So why is it escalating to the point of banning an entire tool? The answer lies in a deeper question: who should bear the complexity?
AGENTS.md is an informal standard collaboratively established by mainstream AI coding tools like Cursor, Windsurf, and Codex. It communicates project-level behavioral rules to AI agents — things like code style requirements, prohibited operations, testing workflows, and security baselines. Its design intent is tool-agnostic: place it in any directory of a repository, and every compatible AI tool should automatically recognize and follow it. Similarly, CLAUDE.md is Anthropic's proprietary configuration file for Claude Code, serving a similar function but only natively recognized by Claude Code. When both files coexist, a repository effectively has two potentially conflicting instruction entry points — and that's the technical root of this dispute.
Manual Import Doesn't Scale
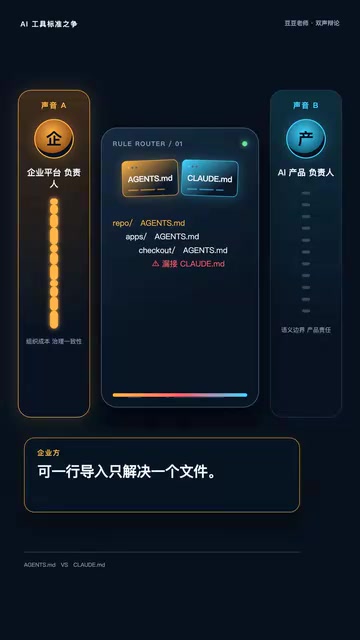
The enterprise perspective is straightforward: a single manual import only solves one file. In large codebases, nearly every directory level has its own rules — a single repository might contain hundreds or even thousands of rule files scattered across its hierarchy.
What makes this more pressing is the current ecosystem reality: over 60,000 open-source projects already use AGENTS.md as a de facto standard, and most other AI coding tools read it by default. If only Claude Code requires manually wiring each level, missing any one directory means a single company could end up running "two sets of rules" — some directories follow the standard, others don't.
For enterprises, this isn't a convenience issue — it's a reliability commitment. Security tests and release gates should live in shared files that all tools follow uniformly, not depend on every team remembering to manually sync them.
Is "Default Read" Really Just One Line of Code?
The product side pushes back with equal force: default reading is far more complex than adding one line of code.
The prevailing AGENTS.md convention is "the rule closest to the code takes precedence," while Claude Code's mechanism concatenates multiple levels of CLAUDE.md files sequentially into context. When these two rule sets coexist and conflict, should one override the other, or should they merge?
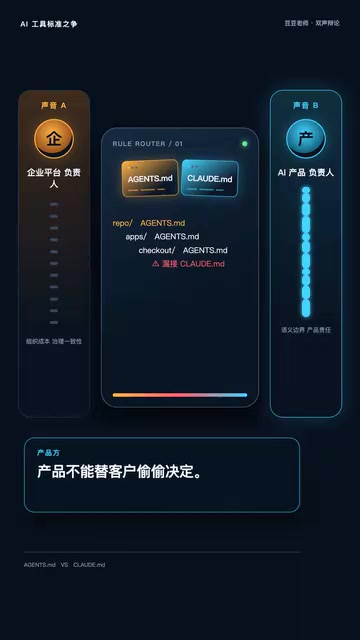
The product team's position is that the tool cannot make this decision quietly on behalf of customers. The truly responsible approach is to declare priority rules explicitly: surface which files were read, proactively flag conflicts, and let teams decide how the two relate. Silently defaulting to reading both means "defaulting to the risk as well" — before rules are aligned, auto-reading means silently absorbing the potential conflicts that come with it.
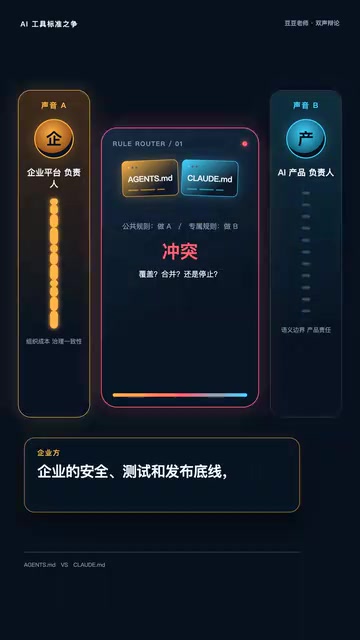
"Proximity-based precedence" is the core mechanism in AGENTS.md conventions for resolving multi-level directory rule conflicts: subdirectory rules override parent directory rules of the same type, allowing each module to autonomously define its own behavioral constraints. Claude Code's multi-level CLAUDE.md mechanism, by contrast, appends files from different levels sequentially into context — it doesn't natively support "override" semantics. These two priority models are fundamentally different: one operates as "nearest wins," the other as "cumulative append." When both are active simultaneously, which file governs any given instruction becomes nearly unpredictable without explicit declaration — and that's the real technical reason the product team insists on not reading silently.
Layered Conflicts: Explicit Import as a Prerequisite
Even setting aside the mechanism question, layering itself creates conflicts. If a shared rule requires action A and a Claude-specific rule requires action B, which one wins?
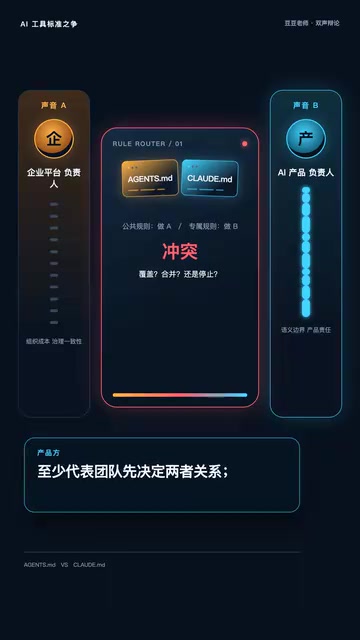
A telling value gap emerges here. The product team argues: explicit import at least signals that the team has actively thought through and decided the relationship between the two files. Skip even that step, and conflicts happen invisibly.
The enterprise side fires back: would you rather let thousands of companies each write their own sync scripts and patch their own gaps, instead of having one vendor implement and test it once? Centralizing implementation at one vendor is far easier to audit than thousands of enterprises each writing their own sync logic. The economics are clear — the ecosystem gains lower switching costs, but customer support and reputational risk mostly lands on Anthropic.
Who Actually Pays for This Complexity?
Strip away all the technical details and this debate comes down to one sentence: who should pay for this complexity?
The enterprise logic: security baselines belong in shared files and should be uniformly handled by the tool. Vendors can continue competing on Claude-specific optimizations inside CLAUDE.md, but reading shared rules shouldn't be a per-company burden.
The product logic: defaulting to absorbing conflicts on everyone's behalf means being responsible for wildly different rule combinations across thousands of enterprises. Explicit import returns both the decision-making authority and the accountability to the team.
Neither position is without merit. One prioritizes ecosystem reliability and low migration costs; the other holds the line on not making decisions on behalf of customers. When a single repository contains both file types, would you want Claude to read them automatically, or require the team to import them explicitly? There may be no single right answer — but the question exposes a governance challenge that AI coding tools cannot avoid as they move into enterprise environments.
This debate has a broader parallel in the software industry, commonly framed as the "platform responsibility boundary" question: to what extent should a tool platform preemptively absorb users' diverse needs, rather than pushing all choices down to users? Being too opinionated lowers user control and auditability; being too unopinionated externalizes integration costs to every enterprise in the ecosystem. For AI coding tools in high-security-sensitivity contexts, this boundary is especially fraught — if default behavior causes a security incident, the vendor's brand reputation takes a direct hit. That's a concrete commercial reason for Anthropic to be exceptionally cautious here.
Final Thoughts
The AGENTS.md dispute looks like a technical squabble about file-reading mechanics, but it touches the deeper contract between AI tools and enterprise collaboration: as AI becomes more deeply embedded in production workflows, how it handles "rules" directly shapes security, auditability, and trust.
For developers, the most pragmatic near-term approach may be: put security and release baselines in shared convention files, while explicitly importing critical rules inside CLAUDE.md — getting ecosystem compatibility without surrendering control over conflicts. For vendors, finding the right balance between "absorbing complexity on behalf of everyone" and "respecting customer decision-making" will be the defining test of their enterprise reputation.
Related articles
AI Agent Practical Guide: Three Levels of Use to Double Your Productivity
A practical guide to AI Agent usage across three levels: delegating routine tasks, stacking capabilities via CLI/Skills/plugins, and achieving complex goals autonomously.
Building Enterprise-Grade AI Agents from Scratch: A Complete Three-Phase Learning Path
A 748-episode AI Agent tutorial covering ReAct, LangChain, AutoGen, RAG hybrid architecture, and three enterprise projects: customer service, data analysis, and multi-Agent collaboration.
Hollywood's Take on AI Doomsday Warnings: Immediate Threats Matter More Than Existential Ones
Hollywood labor groups push back on AI doomsday narratives, urging focus on real, immediate threats: generative AI's impact on creative jobs, copyrights, and actor likeness rights.