The AI Era: A Recursive Starting Point
AI development shows recursive loops; beware of error amplification and recursive contamination.
Starting from a philosophical Reddit title, the article explores the growing recursive loop phenomenon in AI: synthetic data training new models, AI writing training code, models evaluating other models, forming a directional spiral. Community consensus is that human guidance still dominates, but views differ on the speed of recursive self-improvement—singularitarians are optimistic, gradualists emphasize physical and data bottlenecks. The article highlights the risk of recursive contamination: AI-generated errors may be amplified or hidden in the loop, requiring stricter verification. For developers and content creators, maintaining review awareness and critical thinking is key to avoiding blind trust in the recursive chain. The conclusion calls for ongoing discussion of transparency, verifiability, and accountability at this recursive starting point.
Introduction: When AI Starts Talking About "Beginnings"
On Reddit, a short title sparked widespread discussion: "The beginning of the becoming of the beginning begins." This sentence is full of philosophical意味 (philosophical flavor) and perfectly echoes a collective feeling in the current AI field: we seem to be standing at the starting point of a recursive loop—AI is creating new AI, models are training better models, and tools are generating more efficient tools. The title itself offers no specific technical details, but the "recursiveness" it points to is precisely the key clue to understanding current AI progress.
Recursive Loops: A New Paradigm for AI Development
Looking back at the history of AI, every major breakthrough has been accompanied by some enhancement of "self-reference." Early machine learning relied on manual feature engineering, while deep learning allowed models to automatically learn features; today, large models are beginning to participate in data generation, code writing, and even architecture search. This recursiveness of "the becoming of the beginning" manifests at several levels:
- Data level: Synthetic data is used to train new models, forming a closed loop of data generation.
- Code level: AI programming assistants help developers write more efficient AI training code.
- Evaluation level: Models are used to evaluate the output quality of other models.
This recursion is not a simple loop, but a directional spiral—each iteration amplifies certain capabilities while also introducing new biases and risks.
Synthetic Data refers to data artificially created by algorithms or generative models, rather than data directly collected from the real world. In the AI recursive loop, as high-quality real data gradually runs out or is subject to privacy restrictions, synthetic data becomes an important substitute for training new models. For example, large language models generate dialogue corpora to fine-tune smaller models, or diffusion models generate images to expand visual training sets. However, synthetic data also brings the risk of "model autophagy": if a new generation of models relies excessively on data generated by the previous generation, biases and errors in the original data will be inherited and even amplified, leading to distribution drift and performance degradation. Therefore, current practice emphasizes mixing real and synthetic data, and imposing diversity constraints and authenticity filters on synthetic data.
Recursive Self-Improvement is a core concept in AI safety and superintelligence discussions, referring to an intelligent system's ability to modify its own code or architecture to become more powerful in the next iteration. Theoretical complete recursive self-improvement would lead to an intelligence explosion, but current large models do not possess this capability: their "improvement" still relies on humans designing training pipelines, filtering data, and evaluating results. However, partial automation has emerged, such as AI participating in hyperparameter search, neural architecture search (NAS), and generating training code. Distinguishing "human-guided recursive enhancement" from "fully autonomous recursive self-improvement" is key to understanding the boundaries of current AI progress.
Consensus and Divergence Across Multiple Perspectives
Although the original material consists of only a title, combined with recent community discussions (such as the MachineLearning subreddit and related posts on Hacker News), some consensus views can be observed. Most practitioners believe that AI's "self-improvement" is still primarily human-guided and has not yet reached fully autonomous recursive self-improvement. The divergence lies in speed: one side believes the recursive loop will accelerate the arrival of the technological singularity, while the other emphasizes the constraints of the physical world and data bottlenecks.
You may not have noticed that this recursiveness also brings new uncertainties. When AI-generated code is used to train the next generation of AI, errors may be amplified or hidden, forming "recursive contamination." This is why many researchers call for stricter verification mechanisms within the loop.
Technological Singularity is a hypothetical point in time when technological growth becomes uncontrollable and irreversible, and AI intelligence will far exceed human intelligence and may cause civilization-level upheaval. In the context of recursive loops, singularitarians believe that the acceleration of AI self-improvement will suddenly break through a critical point; critics point out that physical resources, data bottlenecks, energy constraints, and verification costs constitute real constraints, making recursive loops more likely to manifest as an S-shaped curve rather than exponential explosion. This divergence directly affects policy discussions: singularitarians tend to emphasize risk prevention and governance frameworks, while gradualists focus more on engineering optimization and responsibility allocation in existing systems.
Implications for Developers and Content Creators
For technical practitioners, understanding this recursive loop helps adjust working methods. For example, when using AI programming tools, one must maintain awareness of reviewing generated code and avoid blindly trusting every link in the recursive chain. For content creators, AI-assisted writing and editing tools similarly constitute a recursive loop: you use AI to optimize text, and AI continues to improve based on human feedback. Maintaining critical thinking is key to breaking blind loops.
Recursive Contamination refers to the phenomenon where errors, biases, or low-quality information are continuously inherited and amplified as AI-generated content is repeatedly used to train subsequent models. Unlike single-generation errors, recursive contamination is insidious and cumulative: a code vulnerability overlooked in an early model may enter training data through an AI programming assistant, then be learned and spread by the next generation of models. In content creation, recursive contamination manifests as semantic drift, factual distortion, and stylistic homogenization. Mitigation measures include: retaining human review steps, establishing data provenance mechanisms, introducing independent validation sets in the training pipeline, and explicitly labeling AI-generated content.
Conclusion: After the Beginning, We Need Clarity
The title "The beginning of the becoming of the beginning begins" is like a metaphor: we are at a recursive starting point, but a starting point does not mean the direction is automatically correct. The tech community needs continuous discussion about transparency, verifiability, and accountability in recursive loops. Only then will this "beginning" lead to a more robust future.
One-line Summary
AI development exhibits recursive loop characteristics, and we must guard against error amplification and recursive contamination risks.
Paragraph Summary
Starting from a philosophical title on Reddit, the article explores the increasingly evident recursive loop phenomenon in AI: synthetic data training new models, AI writing training code, and models evaluating other models, forming a directional spiral. Community consensus is that human guidance still dominates, but there is divergence on the speed of recursive self-improvement—singularitarians are optimistic, while gradualists emphasize physical and data bottlenecks. The article particularly points out the risk of recursive contamination: errors generated by AI may be amplified or hidden within the loop, thus requiring stricter verification mechanisms. For developers and content creators, maintaining awareness of reviewing AI-generated code and text and critical thinking is key to avoiding blind trust in the recursive chain. The conclusion calls for continuous discussion of transparency, verifiability, and accountability at the recursive starting point.
Related articles
GitHub Daily · November 16: Agent Skills Explode, Evaluation and Security Become the New Battleground
GitHub Daily Nov 16: NVIDIA's SkillEvaluator leads growth, Claude-BugHunter packs 82 security skills, and ggml anchors local inference—agent ecosystem is stratifying.
I Built an AI Skill That Edits Videos End to End
A YouTuber turned video post-production into an AI skill: automatic denoising, audio optimization, retake removal, transcription, subtitles, plus YouTube titles/descriptions and Instagram captions and covers. This article breaks down the seven-step human-AI division of labor and how to replicate it.
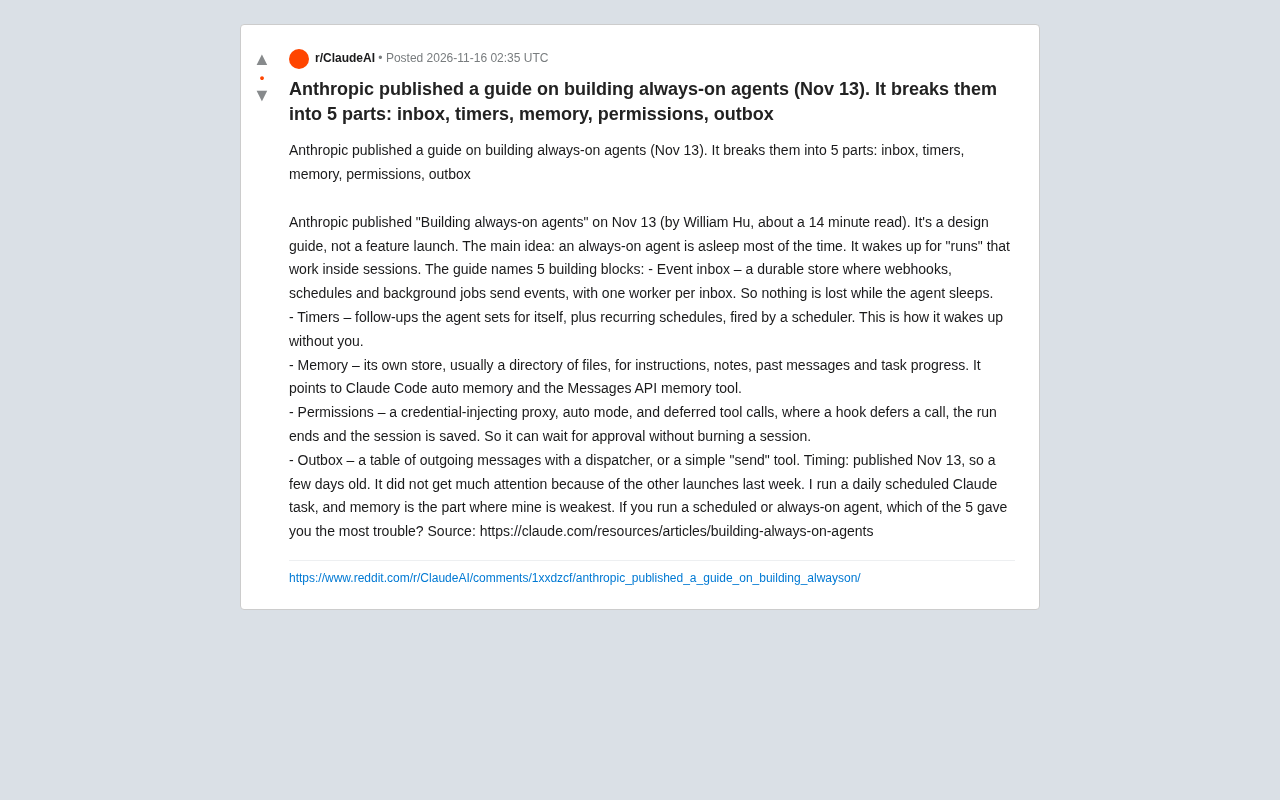
Anthropic's Always-On Agent Design Guide: Breaking Down the Five Core Modules
Anthropic's *Building always-on agents* design guide breaks always-on agents into five modules: event inbox, timers, memory, permissions, and outbox. Here's a module-by-module breakdown of their roles and engineering trade-offs, plus why developer feedback on Reddit points to memory as the weakest link.