The Hidden Risks of Context Optimization: Who Tests the Evidence You Throw Away?

Average metrics hide the hidden cost of context pruning — the critical evidence you discard needs its own tests.
In LLM application engineering, context compression reduces token costs but carries hidden risks: stable average accuracy doesn't mean low-frequency critical scenarios are unaffected. An evaluator that only rewards conciseness is blind to whether discarded evidence mattered. Reef Infra's experiment loop compares compression against task outcomes in controlled runs with publish/revert mechanics — but it can't replace manually designed test sets covering long-tail cases. Coverage-sensitive systems should adopt a conservative "zero regression" acceptance policy rather than the default win-count approach.
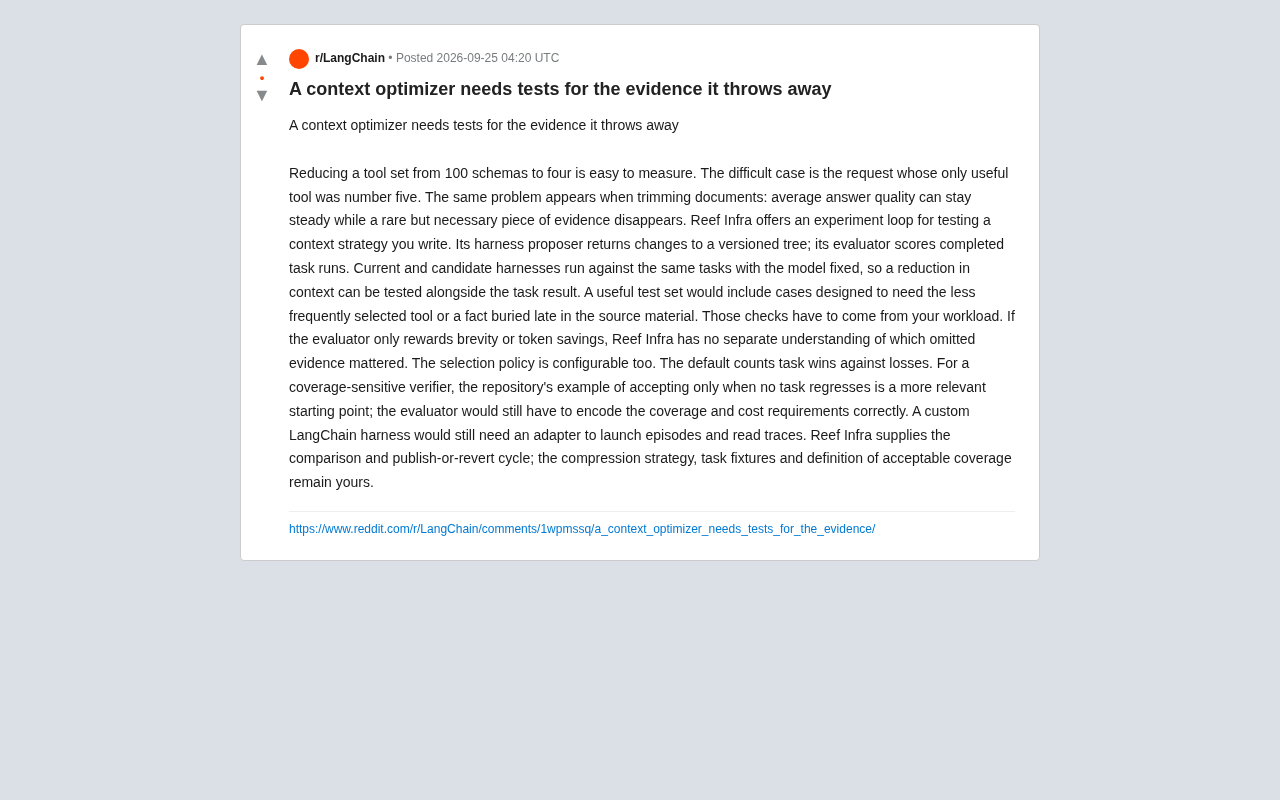
In the engineering of LLM applications, context optimization is a challenge nearly every team faces. Trimming a set of 100 tool schemas down to 4 looks like a clean, efficient performance win — until the one tool a request actually needs turns out to be the fifth one you cut.
A discussion on Reddit highlights a widely underestimated blind spot in context compression: we can easily measure the gains from pruning, but the hidden losses are much harder to quantify.
Average Metrics Hide Long-Tail Failures
Tool set pruning is just one facet of the problem. The same dilemma appears in document pruning: when you compress input content, average answer quality may hold steady, but a rare yet critical piece of evidence may have quietly vanished.
The core tension lies in how you choose your evaluation metrics. If an overall accuracy score doesn't drop noticeably after applying a context strategy, teams often declare the optimization a success. But aggregate metrics naturally dilute long-tail failures — those low-frequency, high-stakes requests are exactly the ones that get swallowed up by the average.
In other words, the deterministic gains from reducing tokens and shortening context are easy to quantify, while the sporadic losses from discarding critical evidence are hard to catch. An evaluator that only rewards conciseness or token savings is fundamentally blind to which omitted evidence actually mattered.
This phenomenon is sometimes described in statistics as an engineering variant of Simpson's Paradox: aggregate metrics can mask dramatically different performance across subgroups. For LLM applications, the peculiarity of long-tail scenarios is their low frequency but high value. In a legal contract analysis system, 99% of queries might rely on just 5 standard tools — but that 1% involving unusual clause interpretation may require precisely the sixth tool that was pruned away. In RAG (Retrieval-Augmented Generation) systems, a similar issue manifests as survivorship bias: the document chunks that survive filtering look fine on average, but the ones that were filtered out may contain the only correct answer for a rare query. This is why evaluating context compression strategies with aggregate metrics like BLEU, ROUGE, or overall accuracy alone is insufficient — these metrics are designed to measure "average performance in typical cases," not "coverage guarantees in worst-case scenarios."
The Experiment Loop Offered by Reef Infra
Addressing this problem, the discussion references Reef Infra's experiment loop — a framework for testing your own context strategies.
Its mechanism breaks down into several components:
- Harness proposer: Returns modification suggestions against a versioned strategy tree;
- Evaluator: Scores completed task results;
- Controlled runs: The current harness and the candidate harness run in parallel on a fixed model with an identical task set.
The value of this design is that it places the degree of context reduction and the task outcome into the same experiment for side-by-side comparison. Instead of looking at compression rate in isolation, you simultaneously observe whether task performance degrades after compression. This transforms optimization decisions from "feels leaner" into "data-backed trade-offs."
The Real Question Is How You Design Your Test Set
But the tool itself can't solve the fundamental problem for you. Reef Infra provides the comparison mechanism and the publish-or-revert loop, but the compression strategy, task fixtures, and the definition of acceptable coverage remain entirely in your hands.
A genuinely useful test set must include cases specifically designed to require low-frequency tools, or facts buried toward the end of a source document. These checks can't be conjured from thin air — they must come from your own real-world workload. If your test set has no coverage of these long-tail scenarios, even the most sophisticated evaluator has no way to determine which discarded evidence is fatal.
Task fixtures are a concept from software testing: fixed combinations of input data and expected outputs prepared for specific test scenarios. In the context of LLM engineering, task fixtures typically include a specific user request, the tool set or document corpus required to handle that request, and the ground truth used to judge whether the output is correct. The challenge in building high-quality task fixtures lies in the "known unknowns" — teams naturally write tests for scenarios they're familiar with, while organically overlooking edge cases that haven't caused problems yet. One practical approach is mining production logs: cluster historical requests, identify low-frequency request types in the distribution's tail, and manually construct or semi-automatically generate fixtures for those types. Another approach is failure-driven testing: whenever a wrong answer caused by context pruning appears in production, immediately distill that case into a permanent regression test, ensuring the same class of problem never recurs.
The Trade-off Between Selection Policy and Coverage
Reef Infra's selection policy is configurable — a feature that's especially important for coverage-sensitive scenarios.
The default policy tallies wins and losses across tasks: if the candidate wins more than it loses, it gets adopted. This is fine for scenarios optimizing overall quality, but it's risky for a coverage-sensitive validator: it may sacrifice a few critical long-tail cases in exchange for winning a few more average-case ones.
The discussion mentions that the repository includes a more conservative example policy — accepting a candidate only when no task shows any regression. For coverage-sensitive requirements, this is a more appropriate starting point. Even so, the evaluator still needs to correctly encode coverage requirements and cost requirements, or it still won't truly protect critical evidence.
The Real Cost of Engineering Integration
Engineering teams should also pay attention to integration costs. If you're using a custom LangChain harness, you'll still need an adapter to launch episodes and read traces. Reef Infra handles the comparative evaluation and the publish/revert loop — but wiring up the pipeline, reading traces, and other engineering details are still your responsibility to sort out.
The "publish-or-revert" pattern is an application of continuous delivery (CI/CD) thinking to LLM context strategy management. The core idea is that every change to a context strategy is treated as a measurable experiment, not an irreversible deployment. A candidate strategy runs in parallel with the current production strategy in a shadow environment, and only if the candidate passes a threshold on predefined metrics does it get promoted to the new production version; otherwise it automatically rolls back. The "zero regression to accept" conservative policy is formally analogous to the "zero-tolerance regression" principle in software engineering — no already-covered test case may fail due to a new change. This policy is especially appropriate in high-risk domains like healthcare, finance, and law, where the cost of a single missing critical piece of information far outweighs any token savings gained from more aggressive compression.
Implications for AI Engineering Practice
While this discussion focuses on a specific tool, the principle it reveals is broadly applicable: context optimization should not be treated purely as a compression problem, but as a trade-off problem with explicit coverage constraints.
For teams building RAG systems, agent tool-calling pipelines, or long-context applications, several points are worth putting into practice:
- Don't evaluate compression effectiveness with average accuracy alone — build dedicated test cases for long-tail, low-frequency, and buried-evidence scenarios;
- An evaluator's reward function determines what it "sees" — if it only rewards conciseness, it will be blind to hidden losses;
- Adoption policies should match your business's tolerance for failure; coverage-sensitive systems should use the conservative "zero regression to accept" policy;
- Tools can provide an experimental framework, but designing the test cases is always the team's own responsibility.
Ultimately, the maturity of a context optimizer isn't reflected in how much content it can cut — it's reflected in how rigorously it scrutinizes what gets thrown away.
Related articles

Free Unlimited Claude Code Solution: Agnes AI + CC Switch Setup Guide
No paid subscription needed — pair the free AI platform Agnes AI with the open-source tool CC Switch to provide a backend for Claude Code, enabling unlimited free calls to text, image, and video models. This guide covers the full setup, test results, and usage boundaries.

A Complete Zero-Cost Guide to Getting Started with Claude Code for Beginners in China
A beginner's guide to Claude Code for users in China: two installation methods (command line and IDE plugin), full configuration steps for replacing the official API with the free domestic LongCat model, and a hands-on demo of building a small tool with natural language, plus tips.

When the NSA Gets Involved: The AI Supply Chain Crisis Behind Open-Source CVEs and API Key Hijacking
Multiple open-source projects disclosed severe CVEs in one day, PHP flaws alarmed the FBI, and Railway and OpenCode were breached with API keys stolen. This article breaks down the vulnerability window, AI-accelerated exploitation, and the AI supply chain crisis behind the API key black market, with a developer defense checklist.