Theory of Expert Sharing: Local Error Reduction ≠ Final Output Improvement, MoE Multi-Step Reasoning Risk Reversal
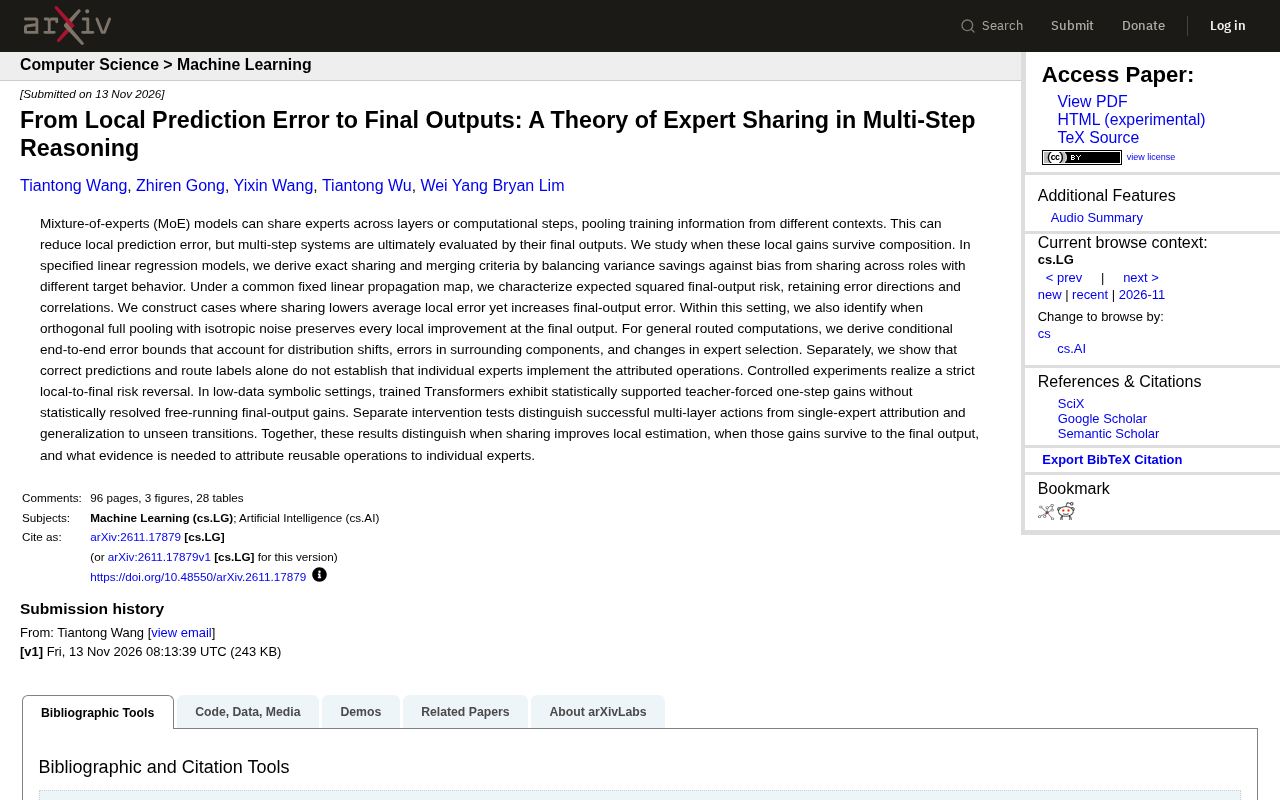
MoE shared experts reduce local error but may increase final output risk, requiring end-to-end evaluation.
This study systematically analyzes how expert sharing strategies in Mixture of Experts (MoE) models affect the final output quality of multi-step reasoning. Theoretical derivations show that variance savings from shared experts may be offset by bias introduced by cross-role sharing, leading to a risk reversal where local prediction error decreases but final output error increases. The study provides exact sharing criteria in a linear regression model and identifies that orthogonal full pooling with isotropic noise preserves all local improvements. Controlled experiments on Transformers achieve strict local-to-final risk reversal: single-step gains under teacher forcing are not statistically significant under free-running. Moreover, the study warns that correct predictions and routing labels are insufficient to prove that a single expert implements the attributed operation; expert function attribution requires intervention verification. The conclusion emphasizes that evaluating expert sharing should focus on end-to-end final output risk rather than merely optimizing local prediction accuracy.
When MoE Shares Experts: Why Local Improvements May Not Benefit the Final Output
Mixture of Experts (MoE) models share experts across layers or computational steps, aggregating training information from different contexts. This design is often used to reduce local prediction error, but multi-step reasoning systems are ultimately judged by the quality of the complete output. A study titled From Local Prediction Error to Final Outputs: A Theory of Expert Sharing in Multi-Step Reasoning systematically analyzes when local gains survive composition, revealing a possible reversal between local error reduction and final output risk.
The core insight of the study is that the variance savings brought by shared experts may be offset by the bias introduced by sharing across roles. In a specified linear regression model, the authors derive exact sharing and merging criteria that trade off variance savings against bias. This framework provides a theoretical tool for understanding the costs and benefits of expert reuse in MoE architectures.
Mixture of Experts (MoE) is a neural network architecture whose core idea is to decompose the model into multiple "expert" sub-networks and use a routing mechanism to dynamically select or weighted-combine the outputs of some experts based on the input. This design allows the model to greatly increase parameter count while keeping computational cost manageable, since only a few experts are activated per forward pass. Expert sharing refers to reusing the same set of expert parameters across different layers or computational steps, thereby reducing total parameter count and promoting information reuse across contexts. However, sharing also introduces new challenges: different roles (such as different layers or different reasoning steps) may have different requirements for expert behavior, and sharing a single expert means these roles must compromise, potentially introducing bias. The final output quality of multi-step reasoning systems (such as chain-of-thought, iterative generation) depends on the cumulative effect of the entire sequence, so improvements in local single-step prediction do not necessarily guarantee a better final output—this is precisely the core issue the study addresses.
Risk Reversal Between Local Error and Final Output
Under a fixed linear propagation mapping, the researchers characterize the expected squared final output risk while preserving error direction and correlation. They construct explicit cases where sharing reduces average local error yet actually increases final output error. This shows that using local prediction accuracy alone as the optimization objective for expert sharing may mislead architecture design.
For general systems employing routed computation, the authors further derive conditional end-to-end error bounds that account for distribution shift, errors of surrounding components, and changes in expert selection. These bounds show that final output risk depends not only on the experts' own accuracy but is also deeply affected by routing decisions and interactions with upstream and downstream components.
Interestingly, the study also identifies a special case: when orthogonal full pooling is used with isotropic noise, every local improvement is preserved at the final output. This provides theoretical conditions for designing "lossless sharing" mechanisms.
In statistical learning theory, the bias-variance tradeoff is a fundamental framework for understanding model generalization performance. Bias measures the gap between the expected model prediction and the true value, while variance measures the fluctuation of predictions as training data varies. Expert sharing reduces variance (i.e., reduces fluctuations in local prediction error) by aggregating data from different contexts, but if the true functions corresponding to different contexts differ, sharing introduces bias. The study precisely characterizes this tradeoff in a linear regression model: the balance between variance savings from shared experts and cross-role bias determines whether final output risk rises or falls. The risk reversal phenomenon refers to the situation where, when bias is sufficiently large, the final output error increases despite a decrease in average local error. Orthogonal full pooling is a special sharing approach in which data from different roles are orthogonal in feature space and noise is isotropic (i.e., noise variance is the same in all directions); in this case, sharing introduces no additional bias, and local improvements are transferred losslessly to the final output. This condition provides a theoretical benchmark for designing safe sharing mechanisms.
Experimental Evidence: Strict Reversal and Attribution Challenges
In controlled experiments, the researchers achieved strict local-to-final risk reversal. Under a low-data symbolic setting, the trained Transformer exhibited statistically supported teacher-forced single-step gains, but the final output gains under free-running were not statistically significant. This means that improvements in one-step prediction did not automatically translate into improved multi-step generation quality.
Furthermore, through separate intervention tests, the authors distinguished successful multi-layer actions from single-expert attribution and generalization to unseen transitions. They point out that correct predictions and routing labels alone are insufficient to prove that a single expert implements the attributed operation. This finding raises warnings for interpretability and expert function localization: routing selection and expert function are not in one-to-one correspondence.
Teacher forcing is a technique commonly used in training sequence generation models, where the true previous-step output is used as input at each prediction step rather than the model's own generated output. This approach stabilizes training and accelerates convergence but causes a mismatch between training and inference: the model never sees its own errors during training, so it may accumulate errors during free-running (i.e., autoregressive generation). The study trained Transformers under a low-data symbolic setting and found that single-step prediction gains under teacher forcing were statistically significant, but final output gains under free-running were not—precisely reflecting the gap between local improvements and end-to-end performance. In addition, intervention testing is a causal inference method that actively intervenes in the model's internal state (such as forcing selection of a certain expert or modifying routing) to observe output changes, thereby distinguishing correlation from causation. The study points out that the simultaneous occurrence of routing labels and correct predictions does not prove that the expert performed the attributed operation, because routing decisions may merely be concomitant phenomena, and the true function may be implemented by other components.
Implications for MoE Design and Evaluation
This study conveys several key messages. First, when evaluating expert sharing strategies, one must focus on end-to-end final output risk rather than merely optimizing local prediction error. Second, sharing criteria need to explicitly balance variance savings against cross-role bias, especially when the target behaviors of different roles differ. Third, error propagation in routing systems is complex, and distribution shift and changes in expert selection can amplify final risk.
For practitioners, this means that when increasing the degree of expert sharing, one should verify through intervention experiments whether local gains survive to the final output, and treat expert function attribution based on routing labels with caution. Theoretical conditions suggest that orthogonal full pooling combined with isotropic noise is a promising sharing approach, but more general scenarios require specific end-to-end error analysis.
The study connects three levels—local estimation improvement, final output risk, and expert operation attribution—providing a more rigorous evaluation framework for the design of MoE multi-step reasoning systems.
Related articles
A Billion-Dollar Deal: A Turning Point for the U.S. Battery Market?
Sila and Panasonic Energy sign a billion-dollar silicon-carbon anode supply deal. This article analyzes its impact on the U.S. next-gen battery market, supply chain localization, and commercialization prospects.
Holiday Extras Employee Treats AI Assistant Like a Pet: The Real Daily Work Life of Brian and Beast
Holiday Extras employee names AI assistant Beast, chats morning, noon and night, preps meeting data in advance and monitors tasks. A real user's workflow and low-barrier start tips.
New AI Governance Initiative: Mandatory Independent Audits and Pre-Deployment Safety Proof
Macron convened government leaders, AI company executives, and researchers to discuss advanced AI risks. Statements call for a rigorous governance framework requiring mandatory independent audits and pre-deployment safety proof.