Three Paths to Local LLM Deployment: How to Choose Between Personal, Enterprise, and Specialized Engines
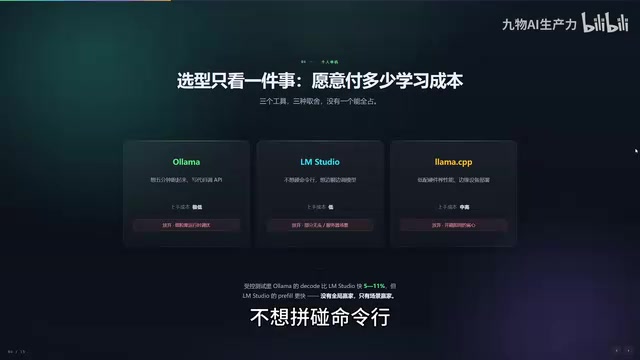
Local LLM deployment has three battlegrounds—personal, enterprise concurrency, and specialized engines—and picking the wrong one wastes your effort.
Borrowing a Bilibili creator's taxonomy chart, this article divides local LLM deployment into three progressive battlegrounds. On the personal side, LLaMA.cpp, Ollama, and LM Studio share the same origin but sit at different layers—engine, service wrapper, and desktop GUI—with the choice depending on how much learning cost you're willing to pay. On the enterprise side, the watershed shifts from 'can it run' to 'how KV Cache is allocated': vLLM uses PagedAttention for breadth in VRAM management, while SGLang uses RadixAttention to reuse repeated prefixes. Choose the former for diverse, broad traffic; the latter for prefix-dense traffic. Specialized engines NIFL, Halogen, and Strix actively abandon generality for extreme performance, but their hidden costs are high, making them suitable only as second engines. The final choice comes down to three questions: how many users, whether traffic repeats prefixes, and whether you have a fixed model-plus-hardware combo worth sacrificing generality for.
Many people trying local LLMs for the first time run into the same confusion: the same model takes one person five minutes to get running, while another struggles for five days and still hits errors. The problem usually isn't the operator's skill level—it's that local deployment actually contains three completely different battlegrounds: personal single-machine, enterprise concurrency, and specialized engines. Pick the wrong battleground, and no amount of effort will help.
A Bilibili creator laid this out clearly with a single taxonomy chart: from left to right, the capabilities get stronger, but the road gets narrower. Understanding this spectrum can save you at least six months of detours.
Personal Single-Machine: LLaMA.cpp, Ollama, and LM Studio Are Not Competitors
On the far left are the three personal-use tools: LLaMA.cpp, Ollama, and LM Studio. Many people mistakenly think they're three competing products, but they actually run on the same underlying foundation.
According to the creator, LLaMA.cpp itself is the inference engine, responsible for running GGUF-format models, with all control in your hands. Ollama is a background service plus model manager built on top of the engine, managing models and their lifecycle for you. LM Studio is a desktop GUI application that packages everything into a visual interface. To use an analogy: LLaMA.cpp is the engine, Ollama is the car with the engine installed, and LM Studio is the car with a dashboard and infotainment screen—underneath, it's all the same machinery.
So how do you choose on the personal side? It mainly depends on how much learning cost you're willing to pay.
- Want to get running in five minutes and casually write code to call APIs: Choose Ollama. The barrier to entry is extremely low—a single
ollama rungets your model going. The trade-off is you can't fine-tune granular runtime behavior. - Don't want to touch the command line and want to tweak the model while chatting: Choose LM Studio. It offers the highest level of visualization. The trade-off is that headless scenarios and server scenarios aren't as smooth.
- Want to squeeze every drop of hardware performance, or deploy on edge devices: Use LLaMA.cpp. It gives you maximum control. But you lose the out-of-the-box convenience.
There's also a counterintuitive point: although Ollama and LM Studio are both based on LLaMA.cpp, Ollama's decode is 5% to 10% faster than LM Studio's, while LM Studio's prefill is faster. So there's no global winner—only scenario winners.
Enterprise Concurrency: The Watershed Between vLLM and SGLang Is in Memory Reuse Patterns
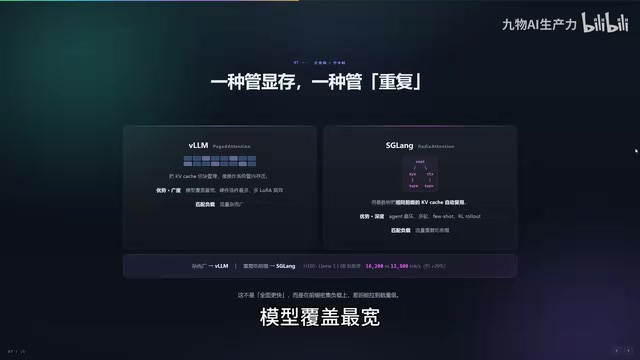
When should you switch from personal to enterprise? The creator's criterion is simple: when you start locking down concurrency. Ollama's service mode is inherently designed for low-concurrency scenarios with one person and one request. Once it becomes ten people using it simultaneously, or an agent repeatedly hitting the same model in a loop, the bottleneck immediately shifts—from "can it run" to "how exactly is each block of KV Cache in VRAM allocated." This cliff is the entire enterprise-side experience.
On the enterprise side, don't rush to pick sides. The consensus between vLLM and SGLang is more fundamental than their differences: both are Apache 2.0 licensed, both provide OpenAI-compatible interfaces, and both support Prefix Cache, speculative decoding, multi-GPU parallelism, and more. So it's not a question of "whether it exists." What you really need to ask is: which memory reuse pattern do you want to bet your money on?
vLLM manages VRAM. Its PagedAttention slices KV Cache into blocks, similar to how an operating system manages memory pages. Its strengths are breadth and predictability: the widest model coverage, hardware plugins from TPU all the way to Ascend, and efficient multi-LoRA. If your traffic is diverse and broad, choose vLLM.
SGLang manages repetition. It uses RadixAttention to reuse KV Cache for identical prefixes. Agent loops, multi-turn conversations, and other operations that repeatedly hold the same prefix can extract maximum value from it. If your traffic repeatedly holds prefixes, choose SGLang.
The creator provided a reference data point: running Llama 3.1 8B on an i7-100, SGLang delivers roughly 16,200 tokens/s while vLLM delivers about 12,500 tokens/s—a gap of around 30%. But note that this isn't uniformly faster; it's faster on the prefix-dense workloads it excels at—where the gap can reach orders of magnitude. So the conclusion is: choose vLLM for diverse and broad traffic, choose SGLang for repetitive prefix-holding traffic.
KV Cache (Key-Value cache) is key to understanding enterprise-side selection. When an LLM generates autoregressively, each new token requires recomputing the attention Key and Value matrices for all previous tokens. Without caching, generating the Nth token would require recomputing the previous N-1, with computation growing quadratically with length—completely unacceptable. KV Cache stores the already-computed K and V in VRAM for direct reuse. The cost is that it's very VRAM-hungry—the longer the context and the higher the concurrency, the larger the footprint. Therefore, the core contradiction on the enterprise side isn't insufficient compute—it's how to partition KV Cache in VRAM. vLLM's PagedAttention and SGLang's RadixAttention both solve this problem, just with different approaches: the former manages fragmentation like OS paging, the latter shares identical prefix blocks like a trie.
Prefill and Decode are two stages of the inference process with completely different performance characteristics. In the Prefill stage, the model processes the entire input prompt at once, computing all tokens in parallel—this is compute-intensive, can saturate GPU compute, and is typically measured in tokens/s throughput. The Decode stage generates tokens serially one at a time, computing only one token per step, but each step must read all model weights and KV Cache—this is memory-bandwidth-intensive and latency-sensitive. This also explains the earlier phenomenon: although Ollama and LM Studio share the same origin, different scheduling strategies give each an edge in different stages. For enterprise selection, long-prompt scenarios should look at prefill throughput, while long-output scenarios should look at decode speed—evaluate them separately.
Specialized Engines: Trading Compatibility for Extreme Performance
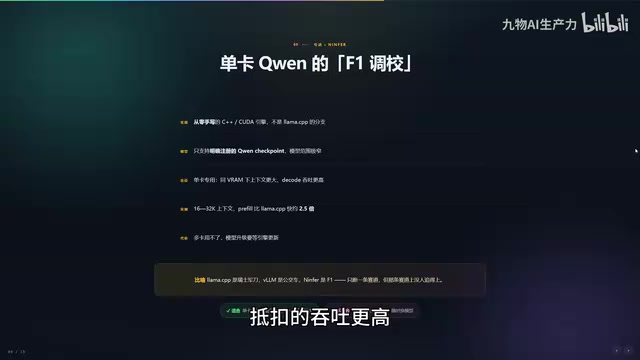
On the far right are specialized engines. They're not faster general-purpose engines—more precisely, they're engines that have actively abandoned generality. The creator gave three examples:
NIFL: A pure C++ inference engine, not a fork of LLaMA.cpp nor a replacement for it. Its positioning is dedicated cards for dedicated tasks, with value in extreme single-GPU scenarios—more context for the same VRAM and higher decode throughput. In tests, prefill at 16 to 32K context is about 2.5x faster than LLaMA.cpp. The trade-offs are clear: no multi-GPU support, extremely narrow model range, and when models upgrade you're still waiting for the engine to update. LLaMA.cpp is a Swiss Army knife, vLLM is a bus, NIFL is an F1 car—it only runs one track, but on that track nobody can catch it.
Halogen: Even more extreme in its specificity. It's precisely optimized for AMD's Strix Halo chip (GFX1151) plus one model family, with no browser UI, a pure API backend, and native implementation of the Anthropic API—Cloud Code can connect directly to local models. At 32K context, it's 1.4 to 2.1x faster end-to-end than the fastest public solution on the same platform, with better accuracy. Its weights use a proprietary .HGN format that neither vLLM nor LLaMA.cpp can load. The official description is blunt: no general-purpose runtime, no portability layer, no fallback path. So it can do what general-purpose engines can't—and that's why it only runs on one piece of silicon.
Strix: The logic is different again. NIFL and Halogen optimize for speed, but Strix optimizes for the "can it even run" question—for example, running a 125B-parameter model on consumer GPUs with 12 to 20GB of VRAM. It mainly does three things: tiered caching of MoE experts by frequency (high-frequency experts in VRAM, all experts in RAM), static routing tables stored on SSD, plus sparse attention and speculative decoding. It's almost tailor-made for a single model, not a general framework.
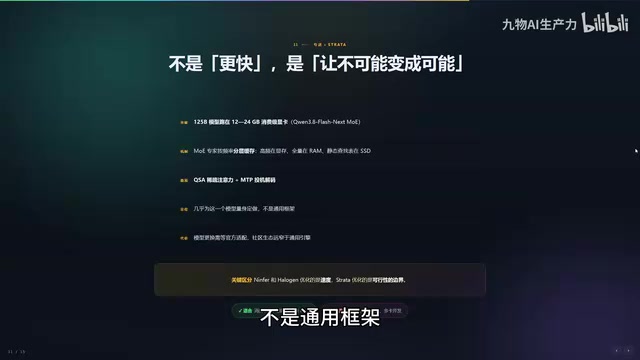
Currently it supports relatively few models—mainly one model family—and it solves the "can it run" question without necessarily running particularly fast. Especially for some newer models, it's very slow, but at least it runs.
MoE (Mixture of Experts) is the prerequisite for Strix to break through the VRAM ceiling of consumer GPUs. Traditional dense models must load all parameters for every inference, and a 125B model far exceeds 20GB VRAM even after quantization. MoE splits the model into multiple expert sub-networks, activating only a few of them per token, so the computation per pass is far smaller than the total parameter count. But all expert weights still need to be stored, and Strix's approach leverages the "uneven expert activation frequency" characteristic for tiered caching: high-frequency experts stay resident in VRAM, low-frequency experts remain in RAM or even SSD, with static routing tables predicting activation paths—thus running large models with limited VRAM. The cost is extra overhead from routing and swapping, so speed isn't necessarily fast, but at least it "runs."
The Hidden Costs of Specialized Engines and the Logic of Selection
The hidden costs of specialized engines are actually quite high—otherwise this explainer would become a recommendation. The creator listed three: when models upgrade, you have to wait for the engine to update—it's not just swapping a model file; change the hardware and the engine becomes immediately unusable; multi-GPU, multi-user, and dynamic model routing were never design goals. The community ecosystem and documentation paths are also far narrower than those of LLaMA.cpp and vLLM.
So the most reasonable position for a specialized engine is as a second engine. Use a general-purpose engine as your primary to cover breadth, and place specialized engines as acceleration endpoints in extremely narrow scenarios you're confident you'll reuse long-term. The criterion is very simple: if you need to ask it "can it run other models," the answer is already no.
The essential difference between specialized and general-purpose engines is whether a portability layer is retained. General-purpose engines like vLLM and LLaMA.cpp maintain abstraction layers between model formats, hardware backends, and scheduling strategies, sacrificing some peak performance for broad compatibility. Specialized engines delete this layer entirely: Halogen only recognizes Strix Halo's GFX1151 instruction set and proprietary .HGN weight format, NIFL targets only specific single cards and a narrow model range, and Strix is almost custom-built for a single model family. Removing the abstraction layer lets the compiler perform more aggressive operator fusion, memory layout, and kernel specialization—this is the real source of their multiple-x speedups. But it also means any change at any layer—swapping cards, swapping models, adding concurrency—can render the entire engine unusable rather than requiring a simple configuration tweak.
Three Questions Determine Your Path
Finally, don't ask which is best—answer three questions first:
- How many people are using it? One person: stay on the personal side. A group: move down the line.
- Does your traffic repeatedly hold prefixes? Yes: choose SGLang. Diverse and broad traffic: prioritize vLLM.
- Do you have a fixed model plus fixed hardware combination worth sacrificing generality for? If yes and you can accept a narrow ecosystem, use a specialized engine as an acceleration endpoint. If not, stay with general-purpose engines.
The maturity of local deployment isn't about finding a universal tool—it's about knowing which tool to switch to at which boundary. The creator summed it up with a quick-reference card: Ollama is a one-command model-serving wrapper, LM Studio is a desktop lab bench, LLaMA.cpp is an inference engine where you can tighten every screw by hand, vLLM is a breadth-first general high-throughput server, SGLang is a deep optimization for prefix reuse, NIFL is a single-GPU extreme specialized endpoint, Halogen is a silicon-dedicated engine for Strix Halo, and Strix uses MoE tiered caching to break through the consumer GPU ceiling.
Related articles
Complete Tutorial: Configuring Ollama Local Models in Director Master
A complete Bilibili tutorial on configuring Ollama local models in Director Master: from installation and model path setup to downloading Qwen and running topic, outline, script, and storyboard workflows.

Director Master Integrates Ollama Local Models: Configuration and Full Workflow Creative Practice
Bilibili tutorial explains how Director Master integrates Ollama local models: install Ollama, set model storage path, pull Qwen via command line, add provider in Agent settings, and run the full short film workflow from topic to storyboard with local Qwen 3.8.
A Week of Coding with Local LLMs: Can They Replace Cloud Claude?
Can a 64GB consumer mini PC replace cloud Claude for coding with open-source local LLMs? A week of testing Qwen 3.8, Muse Glimmer, and GLM 4.7 Flash in VS Code, CLI, and AI agents reveals the real limits of local models and hybrid architectures.