Underrated Machine Learning Resources: Hidden Gems You Wish You'd Found Sooner

Discover hidden gem ML learning resources that deserve far more attention than they get.
This article explores underrated machine learning learning resources highlighted in a Reddit community discussion, covering visualization tools like Distill.pub, niche YouTube channels offering deep explanations, and quality blogs. It analyzes why great resources get buried due to recommendation algorithms and the Matthew Effect, discusses how individual learning style differences are overlooked, and provides actionable advice for building a personalized, problem-driven resource discovery system.
Introduction: Why We Need an "Off the Beaten Path" Resource List
On the machine learning learning journey, almost everyone gets recommended the same handful of names: Andrew Ng's Coursera course, fast.ai's practical courses, and the classic Hands-On Machine Learning. These resources are undeniably excellent, but when they're mentioned over and over again, it also means a wealth of truly transformative "hidden gem" resources get buried beneath the flood of mainstream recommendations.
Recently, the Reddit machine learning community sparked a widely resonant discussion: "What's an ML resource that deserved way more hype?" The poster explicitly excluded the well-known options, instead seeking resources that "you wish you had found sooner" — perhaps a niche YouTube channel, a GitHub repository, a visualization tool, a blog post, or an underrated set of course notes.
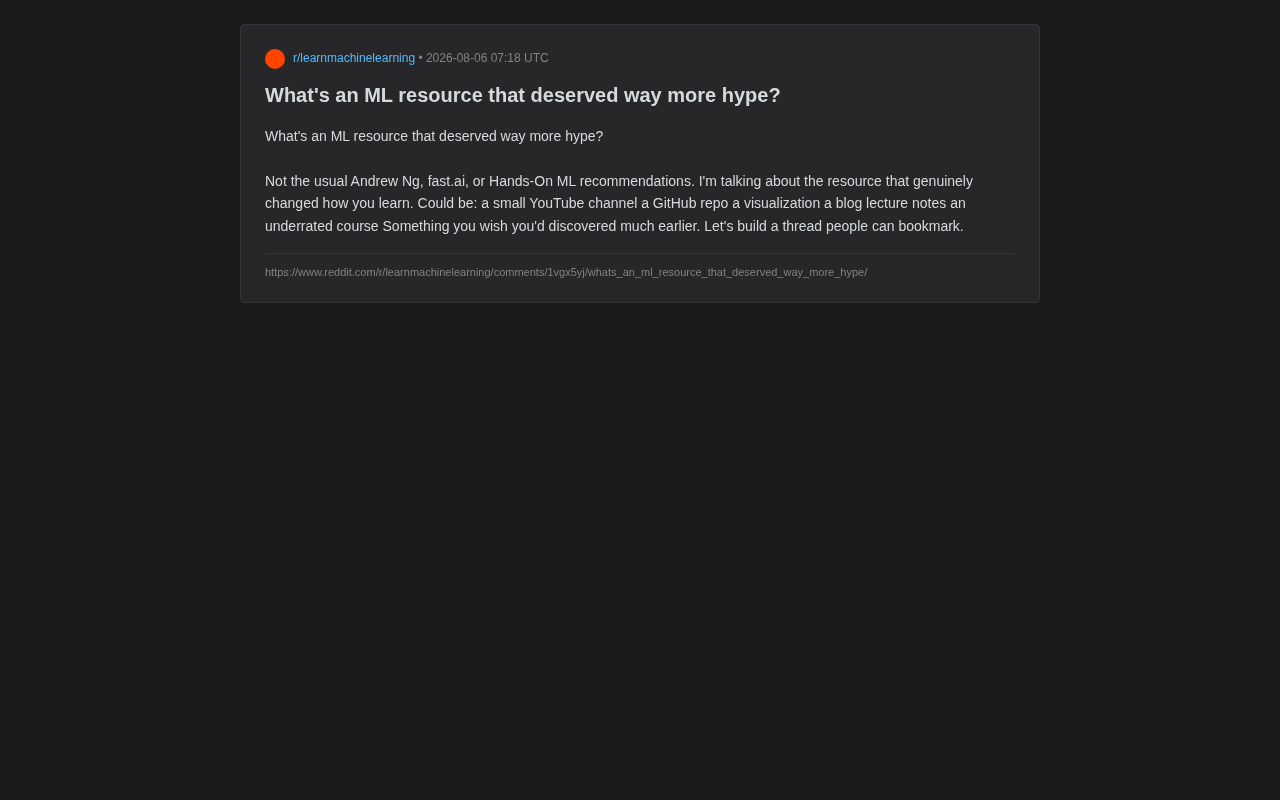
The reason this topic gained traction so quickly reflects a deep-seated learning pain point: the discoverability of quality content is far lower than its actual value. This article draws on that discussion to categorize underrated resource types and analyze why they can genuinely transform how learners think.
Typical Categories of Underrated Machine Learning Resources
Visualization Tools: Making Abstract Concepts "Visible"
One of the biggest learning barriers in machine learning is that many concepts remain at the level of mathematical formulas and abstract descriptions. Excellent visualization resources can transform these abstract concepts into intuitive visual experiences.
For example, platforms like Distill.pub, known for interactive visualizations, have used dynamic diagrams to explain complex topics such as momentum optimization and attention mechanisms. Distill.pub was founded by members of the Google Brain team in 2016 as an online academic journal focused on presenting machine learning research through interactive visualizations. Unlike traditional static PDF papers, Distill articles leverage frontend visualization libraries like D3.js, allowing readers to drag sliders and adjust parameters to observe model behavior changes in real time. Although the platform announced a hiatus in 2021, its published content — including deep visual explanations of Feature Visualization, attention mechanisms, and Activation Atlas — is still regarded as the gold standard for visual academic communication.
The value of this type of content lies in the fact that it doesn't simply tell you "what gradient descent is" — it lets you watch parameters rolling across the loss surface and converging with your own eyes. For visual learners, a single interactive diagram is often worth ten pages of formula derivations.
Visualization resources tend to be underrated because their production costs are extremely high and their update frequency is low, making it difficult to maintain a steady content stream — which puts them at a natural disadvantage in algorithmic recommendation systems.
Niche YouTube Channels: Hidden Treasures of Deep Explanation
One category of resources repeatedly mentioned in the discussion is YouTube channels with modest subscriber counts but exceptionally high content quality. Unlike educational influencers with millions of followers, these channels are often run by researchers or engineers in a specific field, focused on explaining one particular topic thoroughly.
The common trait of these channels is: they don't pursue breadth, but depth. They might spend an entire hour deriving every step of Backpropagation, or walk through the code implementation of a paper line by line. Backpropagation is the core algorithm for training neural networks, essentially a systematic application of the chain rule of calculus on computation graphs. Common points of confusion for learners include: the relationship between dynamic computation graph construction and gradient flow direction, intuitive understanding of vanishing and exploding gradients, and dimension alignment issues when generalizing from scalar cases to tensor operations. Many niche channels are willing to spend considerable time unfolding the gradient computation process for every intermediate variable step by step, combined with concrete numerical examples for learners to verify by hand — this kind of patient, line-by-line derivation is extremely rare in mainstream educational content that prioritizes "efficiency" and "highlights."
It is precisely this "slow content" that helps many learners bridge the gap from "knowing" to "understanding."
Why Quality Machine Learning Resources Get Buried
Recommendation Algorithms Favor "Safe Choices"
When beginners search engines or communities asking "how to learn machine learning," the answers they receive are highly homogeneous. This is because mainstream resources have higher search weight, more citations, and stronger brand effects. Algorithms tend to recommend content that "most people are using," creating a Matthew Effect where the strong get stronger.
The Matthew Effect was a concept originating from sociologist Robert Merton's observations of unequal prestige accumulation in the scientific community. In content recommendation, it reinforces itself through multiple mechanisms: search engine PageRank algorithms use link count as a weighting factor, giving highly-cited content higher rankings; social platform recommendation systems use engagement metrics (likes, comments, shares) as distribution criteria, making content that has already gained initial traffic more likely to enter the recommendation pool; at the user psychology level, the Social Proof effect makes people inclined to choose resources that "most people are using." These three layers of mechanisms combined create a severe cold-start problem for emerging or niche content, even when its quality is outstanding.
The result is that a set of notes or a blog that might be better suited for certain types of learners — even if the quality is outstanding — struggles to break through the initial traffic barrier.
Individual Differences in Learning Paths Are Ignored
Another key reason is that no single resource suits everyone. Some people prefer a top-down, project-driven approach (like fast.ai), others prefer a bottom-up mathematical derivation approach, and still others need extensive visual aids.
These two learning methodologies have deep cognitive science foundations. The Top-Down approach, championed by fast.ai founder Jeremy Howard, centers on letting learners gain a complete end-to-end experience through actual projects before gradually diving into underlying principles — the advantage being rapid establishment of global understanding and practical confidence. The Bottom-Up approach, represented by courses like Stanford CS229, starts from mathematical foundations such as linear algebra, probability theory, and optimization theory, gradually building up to complete machine learning algorithm systems. Cognitive science research suggests that the two approaches suit different levels of prior knowledge and learning goals: learners with programming experience but lacking mathematical background often benefit from the former, while those with backgrounds in mathematics or physics may prefer the latter.
Mainstream recommendations often assume a "standard learner," when in reality everyone's background, goals, and cognitive style differ vastly. This is precisely the unique value of community crowdsourced discussions: they provide a diverse resource map that allows different types of learners to find entry points that align with their cognitive styles.
How to Build a Machine Learning Resource List That Suits You
Start from "Solving Specific Problems"
Rather than blindly bookmarking "must-read lists," it's better to search for resources based on the specific confusion you're currently facing. When you're stuck on a concept, searching for niche content that specifically explains that concept often yields unexpected insights. This "problem-driven" approach to resource discovery is more efficient than passively accepting recommendations. The "spacing effect" and "desirable difficulty" theories in cognitive psychology both suggest that actively seeking answers driven by genuine confusion produces deeper memory encoding than passively absorbing information without a clear question.
Value the Wisdom of Community Crowdsourcing
Reddit discussions like "let's build a thread worth bookmarking together" are essentially a form of decentralized Knowledge Curation. Knowledge curation refers to the process of filtering, organizing, and presenting scattered information resources. Traditional models rely on authoritative individuals or institutions (such as university course syllabi, publishing house editors) for centralized curation, while communities like Reddit and Hacker News offer decentralized alternatives.
The advantages of this model are: contributors have real usage experience rather than theoretical speculation; the resource types covered are more diverse (from papers to podcasts to code snippets); the evaluation dimensions are richer (considering not just academic authority but also actual learning effectiveness). Its limitations include survivorship bias and echo chamber effects, so learners need a certain level of critical thinking ability to assess information quality.
Compared to single authoritative recommendations, the experiences contributed by large numbers of real learners in a community can cover a wider range of scenarios and more granular needs. Being adept at leveraging this bottom-up collective intelligence is an important pathway to discovering underrated resources.
Establish a Personal Knowledge Management System
Discovering good resources is only the first step; more importantly, you need to establish a system for continuous accumulation and retrieval of knowledge. Categorizing and organizing those resources that genuinely changed your understanding, and reviewing them regularly, is what allows these "hidden treasures" to continue delivering value. In practice, consider using methods like Zettelkasten (slip-box note-taking), linking each resource to the specific problem it helped you solve, building a networked connection between knowledge nodes rather than simple linear bookmark collections.
Conclusion
The significance of this Reddit discussion goes far beyond compiling a resource list. It reveals a widely overlooked reality: in an age of information overload, what's truly scarce is not content, but the ability to discover quality content.
The reason those underrated visualization tools, niche channels, and quality blogs can transform how learners think is precisely because they break out of the homogenized recommendation loop and offer differentiated learning perspectives. For every machine learning learner, actively breaking out of the recommendation algorithm's comfort zone to explore resources that "deserved way more hype" may well be the key step to accelerating growth.
Related articles

Apple HomeView Hands-On Review: Is the $300 Smart Home Hub Worth It?
Apple HomeView hands-on: a $300 smart home hub with facial recognition for quick account switching, but no App Store or voice recognition. Is the wall-mounted version worth it? Should you buy the first generation?

Meta Muse Wonder Launch: What It Means for Meta's Return to the Frontier AI Race
Meta releases Muse Wonder and WonderFull, benchmarks reach the frontier, community feedback is polarized. An in-depth look at Meta's return to the frontier AI race, its personal agent strategy, and Zuckerberg's different path.

Apple Home Smart Home Lineup Leaked: LG and Schneider Team Up, UWB Door Lock on Board
Apple Home ecosystem gains new LG and Schneider devices: UWB smart lock with proximity unlock, 2.5K dual-camera doorbell, privacy indoor camera, and AirPods-like seamless pairing.