UPenn's Mao Jiayuan: One-Shot Demonstration Generalization to Crack the Embodied AI Data Dilemma

From data fitting to world models and constraint planning, the TR metric reveals video-action model disconnect, raising real-robot generalization success rate to 83%.
The article reviews two technical routes for general physical intelligence. Pure data fitting relies on massive teleoperation data with low efficiency and poor generalization, as shown by π0.5 on an excavator needing 200 trajectories for one task. The other route treats intelligence as world modeling and planning, using neuro-symbolic abstraction and constraint optimization to generate actions. The RAPID framework turns skill learning into a coding-agent and physical-verifier closed loop, achieving strong generalization across 8 non-prehensile tasks from a single demonstration. The team also found that joint video-action models do not automatically gain compositional ability: vision generalizes but execution fails. They proposed the Temporal Ratio (TR) metric and TR-based adaptive guidance, raising the dual-arm robot's OOD success rate from 71.8% to 83%.
In real-world robotic arm testing, many teams have encountered a similar frustration: to teach a robot to grasp a particular mug, humans often have to physically guide the arm to record hundreds of demonstration trajectories. Yet simply swapping in an unseen mug design or slightly shifting its position causes the policy's success rate to plummet. This approach of brute-forcing skills with massive amounts of teleoperation data makes it very difficult for robots to genuinely generalize to new environments.
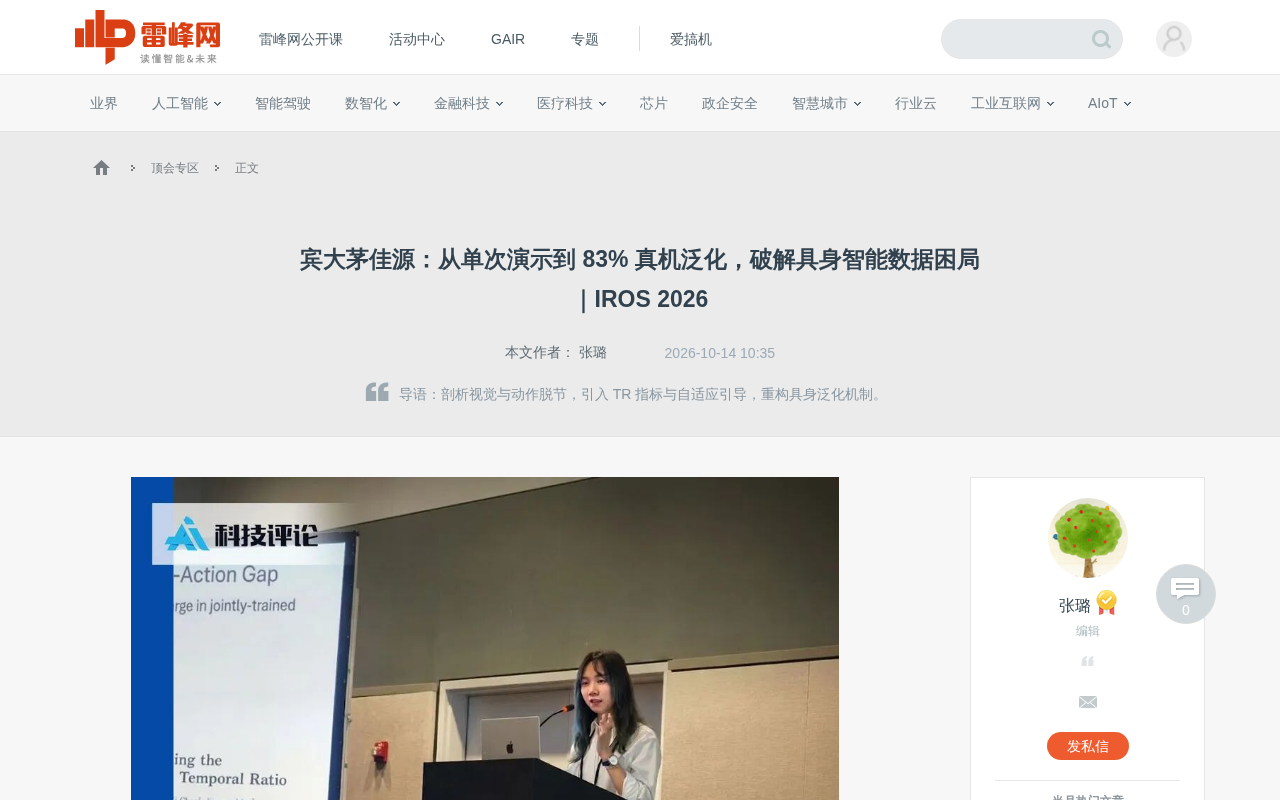
At IROS 2026, Mao Jiayuan from a joint team of UPenn, MIT, and Stanford shared their thinking. She presented the RAPID closed-loop framework, which can generalize to multiple non-prehensile tasks from just a single human demonstration, and introduced for the first time the TR metric that diagnoses the mechanistic disconnect where "vision gets it, but the hand doesn't." Leveraging a TR-based adaptive guidance mechanism, the team ultimately raised the real-robot generalization success rate on complex compositional tasks with a dual-arm robot to 83%.
A Hundred Trajectories for One Skill: The Physical Generalization Dilemma of Pure Data Fitting
Over the past few years, the dominant approach to building general physical intelligence has been "data fitting"—end-to-end learning that maps directly from visual observations to control actions. This path has driven a great deal of research, but it quickly hits a bottleneck when facing real, complex physical interactions.
In her talk, Mao Jiayuan cited Actor Labs' excavator experiment: the team deployed Physical Intelligence's π0.5 onto an excavator, training the policy with large-scale real data from industrial operators. Although the demonstration completed a task with only 200 trajectories, this precisely exposes the shortcomings of the purely data-driven route—extremely low data efficiency and limited multi-task capability.
If mastering each single skill requires hundreds of hours or hundreds of trajectories of data accumulation, the scalability of this paradigm of stacking data is clearly questionable. In contrast, humans can understand the physical logic behind an action from just a single demonstration, and easily transfer it to objects of different sizes and materials, or even entirely new tasks.
When end-to-end models repeatedly fail in out-of-distribution (OOD) scenarios, researchers are forced to reconsider: beyond blindly piling up data volume, is there a more fundamental path to building intelligence? This leads to the second route—treating intelligence as world modeling and planning.
Neuro-Symbolic: Replacing Pixel-Level Prediction with a Reasonable World Model
To achieve planning-based intelligence, one must first build a "world model"—enabling the agent to establish an internal representation of the physical world and to reason about subsequent actions based on that representation.
However, the physical environment is extremely complex. Predicting future states and details directly at the pixel level incurs very high computational cost and makes it difficult to support real-time planning of long action sequences. The key to solving this problem lies in introducing compositional abstract representations. The agent need not memorize all pixel details; instead, it extracts abstract attributes such as shape, pose, and material, and explicitly establishes "action-state" evolution mechanisms using state transition graphs. This is the core of the neuro-symbolic concept:
- "Neural" layer: use neural networks for visual perception, extracting geometric and physical attributes of objects;
- "Symbolic" layer: use symbolic logic to combine these attributes and define transition rules between actions and states.
By combining the two, the agent breaks free from end-to-end black-box mapping and instead learns a structured model of how the physical world operates. With such abstract representations, the robot can internally simulate before execution (e.g., the state evolution after pushing a cup or flipping a bottle cap) and autonomously plan action sequences. This is precisely the foundation for "learning from a single demonstration with strong generalization."
Out-of-distribution (OOD) refers to samples a model encounters outside its training data distribution. In robot learning, if the training set is limited to cups of a certain material and size, then when the cup is swapped for a glass one or when lighting and occlusion change, the input falls outside the training distribution. End-to-end models often suffer a cliff-like drop in performance in OOD scenarios, because what they learn is more the statistical correlations in the training set rather than transferable physical laws. Measuring OOD generalization ability usually requires distinguishing in-distribution (ID) from compositional OOD: the former consists of objects and task combinations seen during training, while the latter involves recombinations of unseen objects, goals, or primitives. It is precisely the huge gap in OOD performance that has driven researchers toward world models and structured representations.
From Policy Networks to Constraint Solving: Why Action Generation Cannot Be Stitched Together
With a composable world model in hand, the next question is: how do we translate high-level logical plans into concrete actions executable in the physical world?
In traditional reinforcement learning and end-to-end paradigms, policy networks (π) generally cannot be directly stitched together. For example, if you separately train three networks for grasping (π1), moving (π2), and placing (π3), it is extremely difficult to chain them directly to complete long-horizon tasks, because the observation spaces, action spaces, and intermediate states are hard to align.
To address the dilemma of non-composable policies, the alternative is not to train a larger end-to-end network, but to redefine action generation as a constrained optimization problem. Under this framework, given an initial state s0, the agent must solve for a trajectory that minimizes action cost (such as trajectory length) while satisfying two key types of constraints:
- Path constraints: including dynamic constraints and collision-free constraints; the trajectory must obey physical laws and the robot must not interfere with the environment;
- Subgoal constraints: including stage-wise contact goals (e.g., stably grasping an object) and the final task goal (e.g., precisely placing the object on a specified shelf).
This design explicitly decouples learning into two levels: the constraint set and the constraint values. The robot does not need to learn physical laws from scratch (these are handled by known physical models and optimization solvers); the neural network only needs to focus on task-relevant key constraints, greatly reducing the data burden.
Take the "object hanging" task in the team's MAGIC project as an example. Such manipulation requires simultaneously satisfying the joint constraints of grasping, hanging pose, and motion trajectory. Traditional model-based planning, due to the enormous search space, often takes over 5 minutes per solve; while representative methods based on unsupervised feature learning and policy learning, even when trained on 100,000 synthetic cup data, achieve only a 42% one-shot demonstration generalization success rate. In contrast, this framework, by using visual correspondence to guide constraint optimization, raised the success rate to 93% from just a single demonstration.
Classifier-free guidance (CFG) originally comes from diffusion generative models. The approach is to compute both conditional and unconditional predictions during sampling, then use a weight w to amplify their difference, thereby strengthening the generated result's adherence to the condition (such as a text prompt): ε = ε_uncond + w·(ε_cond − ε_uncond). The larger w is, the more closely the generation follows the condition, but if it is too large, it easily leads to oversaturation and distortion. In video-action models, CFG has been adapted as guidance for action generation, used to reinforce the action's reference to future visual plans. Traditional approaches use a fixed weight, treating all denoising steps equally, and are therefore called "flat guidance." While it improves OOD generalization, it often comes at the cost of ID performance, because not every moment requires guidance of equal strength.
RAPID Architecture: 1 Human Demonstration + Coding Agent to Handle Non-Prehensile Interaction
If we push the above idea of "constraints + contact sequences" further, we can build a general architecture for more complex physical interactions: RAPID. In the RAPID architecture, skill learning is transformed into a closed-loop programming cycle composed of a coding agent and a physical verifier:
- Demonstration parsing and primitive decomposition: extract actions from a single demonstration and automatically segment them into basic operation primitives such as pushing, flipping, pivoting, and grasping;
- Object-centric program generation: the Coding Agent converts primitives into object-centric constraint programs, decoupled from specific geometric parameters, making them naturally reusable and composable;
- Simulation verification and closed-loop iteration: the verifier validates the program in a Real2Sim simulation environment and feeds back collision, physical feasibility, and other feedback to the Coding Agent for correction, filtering out a large number of physically infeasible programs before deployment.
Across 8 complex non-prehensile real-robot tasks covering bookshelves, partitions, and other scenarios (flexibly combining primitives such as pushing, flipping, pressing-sliding, pivoting, tipping, and grasping), RAPID demonstrated extremely high robustness and generalization solving ability from just a single human demonstration. This shows that combining the code generation capability of a Coding Agent with physical model verification can achieve strongly generalizable one-shot learning through symbolic constraint optimization.
The Blind Spot of Large Models: Why Video-Action Models Cannot Automatically "Emerge" Compositional Ability
RAPID itself is a modular system, and its capabilities come from collaboration between the Coding Agent and different functional modules. This shows that compositionality is reflected not only in the combination of motor skills, but also in how the system organizes and invokes different capability modules. However, the limited information flow between modules in a modular system makes it difficult to fully absorb the synergistic effects across different tasks.
This raises a deeper question: can neural networks directly integrate perception, memory, planning, and control into one? If we abandon manually predefined primitives and module divisions and turn to an end-to-end unified multimodal large model, jointly training video prediction rich in physical laws with action generation, can compositional ability automatically "emerge" in the model? Around this topic, the team conducted two attempts.
Attempt One: Translating Visual Prediction into Action Commands Struggles with Contact-Rich Manipulation
The first attempt used a general video generation model to predict future frames, then translated the visual prediction into concrete robot actions. This route corresponds to the team's AVDC framework published at ICLR 2024 (Spotlight), whose action extraction pipeline consists of three stages: video prediction, dense motion estimation, and Cartesian control mapping.
The greatest advantage of this architecture is that it breaks free from dependence on explicit action labels; the model can directly use video data without action labels for pretraining. At the same time, because it extracts the 3D motion of the object itself rather than joint positions of a specific robotic arm, it has excellent cross-embodiment generalization ability.
However, real-robot testing revealed a clear limitation of this decoupled paradigm: it mainly supports basic grasping, moving, and placing skills. When facing complex contact-rich operations such as flipping, pressing, and pivoting, pure pixel-level video prediction struggles to capture real physical forces and precise contact points. The decoupling must be broken, and video prediction must be deeply combined with action generation for joint training.
Attempt Two: It Sees the Future Frame, but the Action Head Is Still "Driving Blind"
The second attempt built a joint video-action model, allowing the network responsible for action generation to directly "see" and leverage the video model's physical predictions of the future. The team used the pretrained video prediction model Cosmos Predict 2.5-2B as the backbone, extracting intermediate latent features during the video generation denoising process, feeding them together with the robot's proprioceptive state and noisy action tokens into the Gemma Action Head, and finally jointly generating denoised action control tokens through Flow Matching.
However, real-robot and simulation experiments produced an unexpected conclusion: a unified joint video-action model does not automatically "emerge" compositional generalization ability. The team observed two thorny problems: first, vision generalizes but execution fails—the video prediction model can generate reasonable future frames for unseen instructions, but once connected to the Action Head to drive the robotic arm for actual execution, the policy's success rate on compositional out-of-distribution tasks drops sharply; second, extremely high hyperparameter sensitivity—for example, LoRA joint training can achieve a certain trade-off between ID and compositional OOD, while full-parameter fine-tuning is more prone to favoring ID performance at the expense of generalization.
After deeply analyzing the "generalization gap," the team found that when generating control actions, the Action Head often tends to directly "ignore" the future features predicted by the video model. In comparative experiments, even if the video model predicted a completely wrong future frame, the Action Head might still occasionally complete the action; conversely, when the video model generated a perfectly correct future frame, the Action Head instead produced incorrect action control. This confirms a severe "mechanistic disconnect" between action generation and future prediction.
LoRA (Low-Rank Adaptation) is a parameter-efficient fine-tuning method that freezes the pretrained backbone and injects low-rank decomposition matrices A and B beside some weights, updating only these small matrices during training. This greatly reduces the number of trainable parameters, saving GPU memory and lowering the risk of overfitting on small-scale robot data. In contrast, full-parameter fine-tuning updates all weights of the backbone; it has stronger fitting capability but is more prone to favoring data within the training distribution (ID) at the expense of compositional generalization. This also explains the phenomenon observed by the team: LoRA joint training can achieve a certain balance between ID and compositional OOD, while full-parameter fine-tuning tends to chase higher ID performance at the cost of lower OOD success rate.
The TR Metric and Adaptive Guidance: Raising Real-Robot Generalization Success Rate to 83%
To precisely quantify how much the Action Head relies on the video model's future predictions when making decisions, the research team proposed an intuitive diagnostic metric: the Temporal Ratio (TR), i.e., the attention weight on future frames divided by the attention weight on the current frame.
This metric directly reflects the Action Head's decision preference. The higher the TR, the more seriously the Action Head is "looking" at the future frames predicted by the video model and guiding actions accordingly; the lower the TR, the more the Action Head is essentially "driving blind." By analyzing TR curves under different models and hyperparameter configurations, the team found that peak TR precisely predicts the model's compositional generalization ability—models with higher TR have stronger success rates on out-of-distribution tasks; models with extremely low TR have generalization success rates near zero.
Having found the root cause of the "mechanistic disconnect," the team proposed a solution that bridges the generalization gap without retraining the model: adaptive guidance. The team extended classifier-free guidance (CFG) into two dimensions: language guidance and plan guidance. Unlike traditional guidance with fixed weights, adaptive guidance monitors the TR metric in real time: when a TR peak is detected, indicating that the Action Head is actively referencing future plans, the system automatically increases the weights of plan and language guidance to reinforce future physical constraints; during stable phases where TR is low, no additional guidance is applied.
This mechanism of "precisely applying force at key decision points" avoids the damage to in-distribution (ID) performance caused by excessive guidance, while greatly improving the model's compositional generalization ability on spatial, object, and goal out-of-distribution (OOD) tasks. On the LIBERO simulation benchmark, traditional "flat guidance" can improve OOD success rate but severely harms ID performance; adaptive guidance, through dynamic adjustment based on TR, achieves a better trade-off between ID and OOD performance.
In a real physical environment with a dual-arm robot, the team evaluated 8 complex tasks, ranging from taking a bottle out of a paper bag, organizing snacks onto shelves, to folding T-shirts. On unseen compositional out-of-distribution tasks (such as "put the fruit into the paper bag"), the comparison model Cosmos-Policy achieved an average success rate of only about 12%, while the team's own model achieved an average success rate of 71.8% before guidance; after introducing TR-based adaptive guidance, the real-robot generalization success rate further rose to 83%.
Attention weights are normalized values in a Transformer that measure the relevance between a query and a key. In video-action models, when the Action Head generates action tokens, it assigns attention to the intermediate latent features produced by the video model: current-frame features and future-frame features each receive a certain weight. Dividing the future-frame weight by the current-frame weight gives TR. A high TR means the Action Head places more attention on the model's predicted future frames when making decisions, and actions are more likely to follow the physical plan; a low TR means the Action Head is almost only looking at current observations, ignoring future predictions. TR thus becomes a "mechanistic coupling" diagnostic that requires no additional labels and can be observed through forward inference alone, providing a real-time trigger signal for adaptive guidance.
Conclusion: The Core Is Not Blindly Stacking Data
The synergy between video prediction and action control does not automatically "emerge" during joint training. Different model architectures and training recipes yield different levels of compositional generalization ability, often accompanied by a trade-off between in-distribution and out-of-distribution performance. TR provides a precise diagnostic tool, but to truly bridge the generalization gap, we must re-examine "compositionality" itself—reconstructing it fundamentally from architecture, optimization objectives, and data definition.
Returning to the most essential paradigm choice, modular systems remain very powerful: they inherently possess explicit structural compositionality, high data efficiency, and asynchronous control capabilities that are crucial for real-time robotic systems, but their limitation is that they cannot fully absorb deep synergistic effects across different tasks. How to organically combine the advantages of modular systems—"strong compositionality and high data efficiency"—with the potential of unified large models to "globally absorb synergy" is the most core research direction going forward.
One-line Summary
From data fitting to world models and constraint planning, the TR metric reveals the mechanistic disconnect in video-action models, raising real-robot generalization success rate to 83%.
Paragraph Summary
The article reviews two technical routes for general physical intelligence. Pure data fitting relies on massive teleoperation data, with low data efficiency and poor generalization; π0.5 deployed on an excavator needing 200 trajectories for a single task is an example. The other route treats intelligence as world modeling and planning, using neuro-symbolic compositional abstraction and constraint optimization to generate actions, making policies composable. The RAPID framework turns skill learning into a closed loop of coding agents and physical verifiers, demonstrating strong generalization across 8 non-prehensile real-robot tasks from a single human demonstration. The team further attempted joint video-action models and found that compositional ability does not automatically emerge: vision generalizes but execution fails. To address this, they proposed the Temporal Ratio (TR) metric to quantify the Action Head's reliance on future predictions, and designed TR-based adaptive guidance, raising the dual-arm robot's OOD success rate from 71.8% to 83%, far exceeding the comparison model's roughly 12%.
Related articles

"Black October": Did AI Uncover 3% of All Critical Vulnerabilities Ever?
A Reddit post claims 3% of all critical software vulnerabilities ever were found in the past month, dubbed 'Black October.' We break down the statistical issues, how AI-assisted code auditing accelerates discovery, and how developers should respond.

Microsoft Project Gecko: Using AI to Bridge Language Gaps for African Farmers
Microsoft's Project Gecko launches PharmaChat, letting African farmers ask questions in their native language and get precise video clips and farming book chapters via AI. The project also releases three interactive manuals to advance inclusive AI.

Musk's Space Dominance: How Starlink Throttling Undermines Ukraine's Defense
SpaceX's Starshield throttling disabled Ukraine's high-speed interceptor drones, exposing how Musk's private control over low Earth orbit communications affects battlefield dynamics and national security, and highlighting the risks of commercial space militarization and space governance dilemmas.