vid2vid-long: Solving Long-Range Consistency in Video-to-Video with Explicit Correspondences
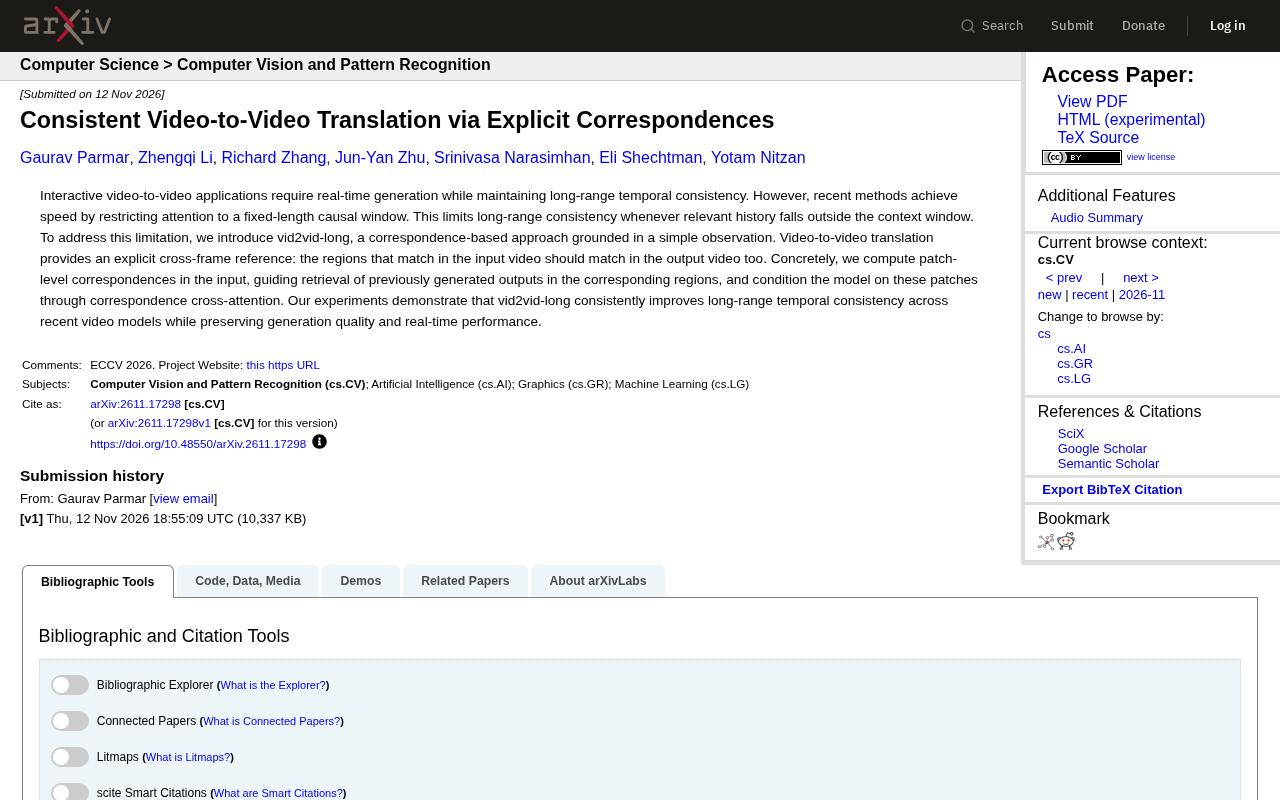
vid2vid-long retrieves historical output via input-video patch correspondences, cracking real-time video-to-video long-range consistency.
Real-time video-to-video methods typically restrict attention to a fixed-length causal window, discarding history outside it and causing texture flickering, color drift, and identity jumps. vid2vid-long exploits the cross-frame correspondences naturally carried by the input video: it computes matches between each patch of the current frame and historical frames on the input, then retrieves how those regions were generated in previous frames and injects them via correspondence cross-attention. Since matching occurs on the input rather than generated output, errors do not accumulate and drift; retrieval is sparse and targeted, keeping computational overhead manageable. Experiments show the method consistently improves long-range temporal consistency across multiple recent video models while maintaining generation quality and real-time performance, turning long-range consistency from a "memory" problem into a "retrieval" problem.
Video-to-video generation is moving from "it works" to "it works well," but the tension between real-time performance and long-range temporal consistency has never truly been resolved. A recent paper titled Consistent Video-to-Video Translation via Explicit Correspondences proposes the vid2vid-long method, which attempts to sidestep this tension in a cleverer way: since the input video itself provides a natural reference, why not use it directly to guide the model in remembering what it should remember?
The Cost of Real-Time Generation: Truncated Memory
Current mainstream interactive video-to-video approaches, in order to meet real-time requirements, universally restrict attention to a fixed-length causal window. The model can only see the most recent few frames of generated output, and historical information outside the window is completely discarded.
The side effects of this design are direct: once the relevant history for some region in the frame falls outside the window, the model "forgets" what it previously looked like. In the output, this manifests as texture flickering, color drift, and object identity jumps—in other words, long-range temporal consistency is broken. Longer windows improve consistency but also increase latency, which is simply unacceptable in real-time interactive scenarios.
The core contradiction the paper identifies is this: speed and memory length are bound to the same parameter, when the two should not constrain each other.
Causal window is a common design in autoregressive video generation: the model generates output frame by frame, and each frame can only attend to a fixed number of preceding (causal) frames, ensuring that generation can proceed in a streaming fashion with controllable latency. Window length is a direct trade-off between speed and memory—the longer the window, the more history the model can reference, but the larger the context each frame must process, and the higher the latency. In contrast, bidirectional attention allows the model to see all frames of the entire video, yielding better consistency, but it must wait until all frames are ready before generating, making it unsuitable for real-time interaction. vid2vid-long targets precisely the causal window paradigm: it retains the streaming generation framework but "restores" historical information from outside the window through external retrieval, thereby extending effective memory without increasing window length.
Core Insight: The Input Video Is a Free Reference Frame
The starting point of vid2vid-long is a simple but overlooked observation: video-to-video tasks differ from pure generation tasks in that they naturally carry an explicit cross-frame reference—regions that match each other in the input video should also match each other in the output video.
In other words, if frame 1 and frame 50 in the input video show the same wall or the same piece of clothing, then these two locations in the output video should also maintain the same appearance. This correspondence does not need to be "guessed" by the model; it can be computed directly on the input.
Based on this observation, the method reframes the long-range consistency problem from "how to make the model remember longer history" to "how to precisely retrieve from history the parts that the current frame actually needs." The former is constrained by window length; the latter has no such constraint.
Method Breakdown: Patch-Level Retrieval + Correspondence Cross-Attention
The vid2vid-long pipeline can be broken down into two steps.
Step 1: Compute Patch-Level Correspondences on the Input
For each patch of the current frame, find matching patches in historical frames of the input video, yielding a set of patch-level correspondences. Since matching occurs on the input video rather than on generated output, this step does not depend on what the model has already generated, and therefore does not drift as generation errors accumulate.
Patch-level correspondence refers to dividing an image or video frame into small patches, then finding the position with the most similar content for each patch in another frame, thereby establishing a block-by-block matching relationship. Traditional approaches perform matching on generated output, but the generated output itself carries errors that accumulate over frames, causing matching to gradually drift. vid2vid-long moves matching to the input video because the input is given and does not change with the generation process, so matching results are naturally stable and will not become inaccurate due to the model "generating poorly." This idea is similar to optical flow, but optical flow typically only estimates pixel-level motion between adjacent frames, whereas the correspondences here are patch-level semantic matches across long-distance frames, making them better suited for retrieving distant history.
Step 2: Retrieve Historical Output by Correspondence
With input-side correspondences in hand, the method can locate the generated output patches corresponding to these matched regions in previous frames, retrieve them, and inject them into the current frame's generation process via correspondence cross-attention. The model can therefore directly "see" how the relevant regions were generated in the past, rather than relying on a fixed-length causal window to indirectly recall.
The key to this design is that retrieval is sparse and targeted: only the patches that the current frame actually needs are taken, rather than feeding the entire historical window into attention, keeping computational overhead manageable and preserving real-time performance.
Cross-attention is an attention mechanism in Transformers: the query comes from the frame currently being generated, while the keys and values come from another information source. In vid2vid-long, the keys and values of correspondence cross-attention are the retrieved historical output patches, and the query is the current frame's patch; the model uses this to decide how much information to "draw" from history. Unlike self-attention, cross-attention's information source is external retrieval results rather than frames within a fixed window, so its effective context length is not limited by the causal window. This mechanism is also the video-domain counterpart of the retrieval-augmented generation (RAG) idea: rather than stuffing all history into the context, retrieve first and then inject.
Experimental Results: Improved Consistency Without Sacrificing Quality or Speed
The paper's experimental conclusions can be summarized in three points:
- When vid2vid-long is integrated into multiple recent video models, long-range temporal consistency improves consistently;
- Generation quality does not degrade due to the introduction of the retrieval mechanism;
- Real-time performance is maintained; the method does not trade latency for consistency.
Together, these three points directly address the contradiction raised at the outset—vid2vid-long does not lengthen the causal window but takes a different path around the window limitation, so it does not need to choose between speed and consistency.
Why This Idea Is Worth Watching
From a broader perspective, this work represents an emerging trend in video generation: turning the "memory" problem into a "retrieval" problem. Rather than forcing the model to memorize with a larger context window, it leverages the task's own structural priors to fetch information on demand.
The input video in video-to-video is exactly such a nearly zero-cost structural prior, yet most prior methods treat it only as content to be transformed, without fully exploiting its cross-frame correspondence information. vid2vid-long explicitly connects this prior into the generation pipeline, and the idea is transferable—similar correspondence retrieval may also appear in other video tasks requiring long-range consistency.
Of course, the method's effectiveness depends on the reliability of input-side patch matching. When the input video itself contains occlusions, severe motion, or large illumination changes, the accuracy of correspondences will be affected. This is not elaborated upon at the abstract level of the paper and merits further observation in practical deployment.
Summary
The value of vid2vid-long lies not in stacking larger models or longer windows, but in re-examining the explicit information that has been overlooked in video-to-video tasks. Using patch correspondences from the input video to guide the retrieval of historical output gives real-time interactive scenarios a solution for long-range consistency without sacrificing speed. For teams working on productizing video-to-video, this is a direction worth following.
One-line Summary
vid2vid-long uses patch correspondences from the input video to retrieve historical output, cracking the long-range consistency challenge in real-time video-to-video.
Related articles
Harvard AI Safety Course CS 2881R Sparks Discussion
Harvard's CS 2881R AI Safety course was mentioned on Hacker News. This article covers the course background, core AI safety topics, and takeaways for learners, helping readers understand how top universities cultivate AI safety talent.

Expanding Your Social Circle: Friend-Making Apps Worth Trying
How to choose a friend-making app? This article reviews friendship apps like the friend-discovery platform BFF and activity-oriented Timeleft, analyzing which approach suits whom and offering practical tips on offline meeting safety and expectation management.
Why You Shouldn't Run the Hermes Agent on Your Personal Computer
Why shouldn't you run autonomous AI agents like Hermes on your personal computer? This article analyzes why agents should be deployed to a dedicated VPS instead of your primary device, from four angles: security risks, resource consumption, credential leakage, and autonomy requirements—plus the practical logic of isolated deployment.