vLLM v0.32.0rc0 Update: HiSparse Adds Host Pool Reporting to KV Cache Capacity Logs

vLLM commit #60285 makes KV cache capacity logs additionally report the host memory pool, completing tiered cache observability.
Commit #60285 in the vLLM repository was merged into v0.32.0rc0, signed by Red Hat engineer Matthew Bonanni with a human-AI collaboration credit. The change itself does not alter the scheduling algorithm; it only makes KV cache capacity logs report one additional memory pool — the host pool. The article explains the background: vLLM manages KV cache as blocks based on PagedAttention, and when growing context and concurrency exhaust VRAM, some blocks can be swapped out to a host pool built on CPU DRAM, making the actual cache capacity the sum of multiple pools. If logs report only VRAM capacity, capacity planning, hit-rate analysis, and long-context trend observation all incur systematic bias. The article also discusses the AI co-authorship trend reflected in such commits and notes that the source material contains only commit metadata, with change details being reasonable inference.
A seemingly minor logging change hides a deeper accounting problem between KV cache VRAM and host memory
In the GitHub repository of the large-model inference framework vLLM, a commit numbered #60285 was merged into the v0.32.0rc0 tag, titled "[HiSparse] Report host pool in KV cache capacity logs." The commit is signed by Red Hat engineer Matthew Bonanni and carries a co-authorship credit for Claude Opus 5.5, indicating a change completed through human-AI collaboration.
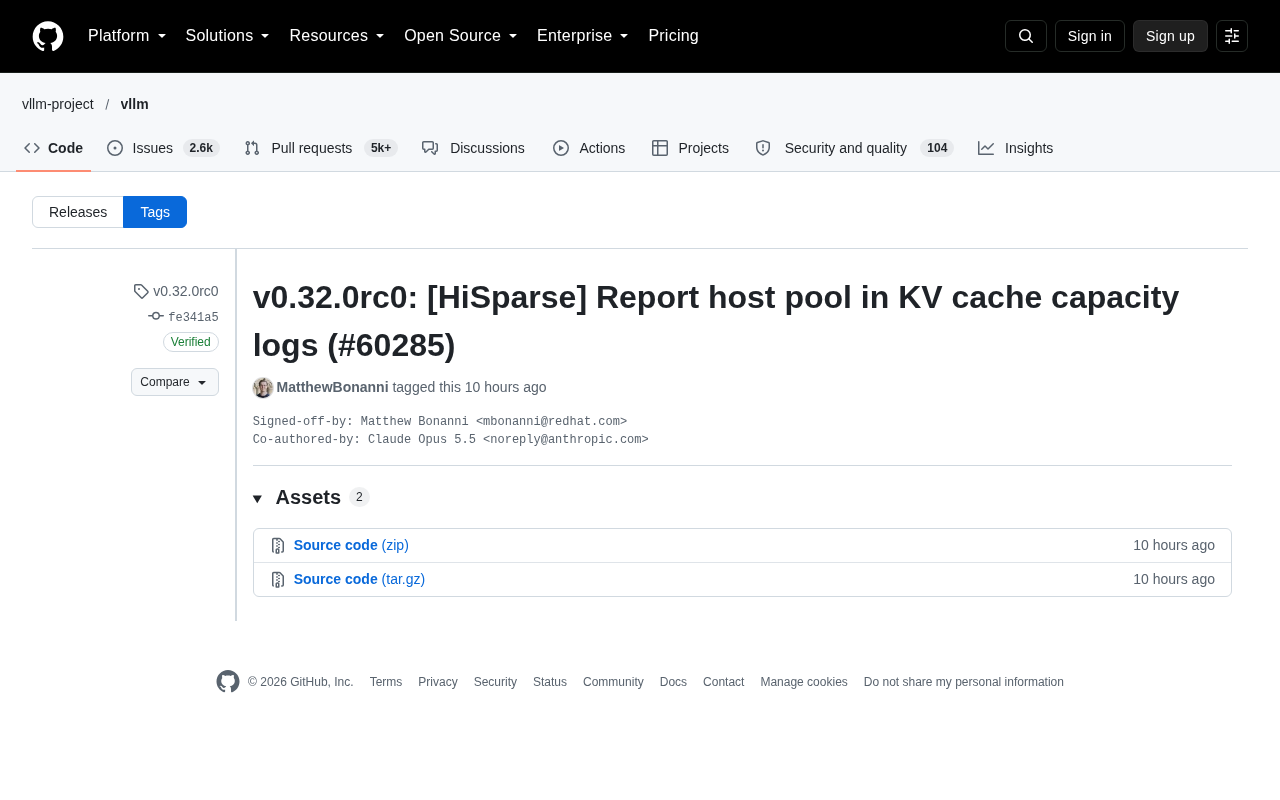
The title alone reveals the boundary of the change: it does not alter the inference scheduling algorithm or introduce new KV cache management strategies. Instead, it makes the capacity log report one additional type of memory pool — the host pool. To understand the value of this change, we first need to clarify where KV cache actually lives in vLLM.
KV cache doesn't live only in VRAM: understanding vLLM's pooled memory design
vLLM's PagedAttention mechanism manages KV cache by splitting it into fixed-size blocks, an approach close in spirit to virtual memory paging in operating systems. As context length and concurrent request counts grow, the size of the KV cache quickly exceeds the VRAM capacity of a single GPU, forcing the framework to introduce additional storage tiers.
The host pool refers to the cache tier based on host memory (CPU DRAM). When the GPU VRAM pool fills up, some KV blocks can be swapped out to the host pool and swapped back into VRAM when needed. This mechanism lets vLLM serve longer contexts or more concurrent requests using capacity beyond VRAM, at the cost of data round-trips over the PCIe bus.
Around this design, the vLLM community has accumulated a number of related components, such as KV connectors for offloading, schemes that extend cache capacity with CPU memory, and various tiered cache implementations. What these components share is that they make the effective KV cache capacity no longer equal to "the chunk inside VRAM," but rather the sum of multiple pools stacked together.
PagedAttention is the attention computation and VRAM management scheme proposed by vLLM, whose core idea borrows from the paging mechanism of operating system virtual memory. In traditional implementations, each request's KV cache requires a contiguous span of VRAM; because sequence length is not known in advance, frameworks often reserve for the maximum possible length, causing severe internal fragmentation, and idle blocks are also hard to share across requests. PagedAttention splits each sequence's KV cache into blocks of a fixed number of tokens (typically 16). These blocks need not be contiguous in physical VRAM; instead, a block table records the mapping from logical positions to physical blocks. During attention computation, the kernel reads the K and V tensors block by block according to the block table to complete the weighted sum.
This design brings two direct benefits: first, VRAM fragmentation is greatly reduced, and block-level on-demand allocation pushes VRAM utilization close to its theoretical limit; second, different sequences can share the same physical blocks, which significantly saves VRAM in scenarios such as beam search, parallel sampling, and prefix sharing. PagedAttention is also the foundation for vLLM's subsequent prefix caching, copy-on-write, and block swap-in/swap-out — precisely because the cache is already managed in blocks, moving blocks from VRAM to host memory or other storage tiers becomes a low-cost block-level operation.
What problems arise when the log omits the host pool
Capacity logs are the most direct observation entry point for operations and tuning. The KV cache capacity figures in startup logs usually tell users "how many tokens can be cached under the current configuration." When a system has both a VRAM pool and a host pool, if the log reports only the former, the observed data will systematically deviate from the actual available capacity.
Several practical problems follow. For capacity planning, users estimating throughput and maximum concurrency from the VRAM capacity in the logs may underestimate the system's true carrying capacity; for hit-rate analysis, it becomes impossible to distinguish between "VRAM misses" and "host pool hits," distorting judgments about swap-in/swap-out overhead; for trend observation, the host pool often accounts for an increasing share in long-context scenarios, and the absence of this data obscures capacity change trends.
HiSparse is the feature module to which this commit belongs. Bringing the host pool into the capacity log essentially makes the log faithfully reflect the real occupancy structure of the KV cache, rather than presenting only one of its tiers.
The reason KV cache swap-in/swap-out works at all is that the interconnect bandwidth between host memory and GPU VRAM is sufficient to cover the transfer overhead. Taking the common PCIe 4.0 x16 as an example, the one-way effective bandwidth is on the order of about 25 GB/s, while the HBM bandwidth of a single data-center GPU can reach 2–3 TB/s — a gap of about two orders of magnitude. CPU-GPU coherent memory architectures such as NVLink and Grace Hopper can significantly narrow the gap, but most deployments still rely primarily on PCIe.
This means the benefits of the host pool depend heavily on the access pattern: when swapped-out KV blocks are not referenced again for a long time, the swap-in overhead is amortized and tiered caching yields a net gain; if the working set thrashes frequently between VRAM and host memory, the transfer cost may offset or even exceed the gains from capacity expansion. Therefore, judging whether the host pool is in a healthy state cannot rely solely on how many tokens it caches; it must also incorporate hit rates and the frequency and latency of swap-ins and swap-outs. This is the deeper reason capacity logs need to distinguish between the two pool tiers — only by knowing which tier a token actually resides in can the above overheads be estimated.
vLLM's collaborative development model, as seen from commit metadata
Another observable aspect of this commit is its authorship structure. The commit message lists both a human author and an AI assistant (Claude Opus 5.5) as collaborators — a pattern that is gradually increasing in open-source projects. GitHub's Verified badge and GPG key information confirm the integrity of the commit's origin.
The change appears on the release candidate version v0.32.0rc0, consistent with vLLM's usual iteration rhythm — first releasing an rc version, gathering feedback, then moving to a formal release. For teams relying on vLLM for inference services, this version is worth watching if they have previously encountered capacity logs that did not match measured performance.
AI co-authorship credit is not decorative information in this commit; it touches on two increasingly prominent issues in open-source projects: contribution attribution and code responsibility. Traditional open-source collaboration relies on DCO or CLA to declare that contributors have the right to submit code, and uses GPG signatures to verify the origin of commits. When code is generated by AI or completed jointly by humans and machines, the attribution method determines whether future maintainers can trace the intent and origin of a given piece of logic. Common practices include noting collaborators in the commit message, using Co-Authored-By trailers, or listing a separate credit line for the AI assistant.
At the same time, open-source communities do not take a uniform stance on AI-generated code: some require explicit disclosure, some restrict its scope of application, and some projects ban it entirely due to copyright and license uncertainty. Changes to high-performance inference frameworks like vLLM, once they involve kernel and scheduling logic, carry high costs when they go wrong, so making AI participation transparent both records the contribution chain and helps reviewers quickly locate suspicious changes when regressions occur. This commit's choice to publicly credit Claude Opus 5.5 can be seen as a practical response to that trend.
Directions worth watching going forward
A single commit can offer only limited information, but the problem it points to is universal: as tiered KV cache storage becomes more common, the observability system needs to keep pace. VRAM, host memory, and even remote storage can all become landing spots for KV blocks, and logs, metrics, and monitoring dashboards should all cover these tiers.
For teams using HiSparse or similar offloading schemes, it is worth checking whether the capacity log output of their current vLLM version includes a host pool field, and calibrating it against actual cache hit behavior in production.
It should be noted that the available material for this piece includes only the commit title, version tag, author attribution, and screenshot; the full diff, scope of code changes, and actual log output format are not reflected in the source material. Therefore, the description of change details in this article is a reasonable inference based on vLLM's existing tiered cache mechanism.
Related articles

How Big Can Stars Really Get? The Physical Limits of the Largest Stars
Red supergiants are the largest stars by volume, with radii up to 2,000 times the Sun, engulfing the inner solar system. But there is no precise upper limit on stellar size—models predict up to 15,000 solar radii. The most massive blue stars are far smaller than red supergiants—biggest and heaviest are two different things.

Apple HomeView Smart Display Full Feature Breakdown: Wall-Mount or Desktop, $299
Apple launches HomeView, a $299 smart display with wall-mount and desktop options, 12MP camera for facial recognition, smart home control, music playback, and recipe step-by-step cooking. Full breakdown of watch faces, apps, privacy, and cooking integration.

Where Did the Promised New Studio Go? Craft Computing Answers After Five Years
Craft Computing's host responds to viewer questions: the new studio promised five years ago was shelved as construction costs soared from $30,000 to $75,000, and was replaced by a 168-square-foot garage conversion.