When Distribution Shift Severity Scores Fail: A New Stress-Testing Perspective on Frozen Time-Series Forecasters
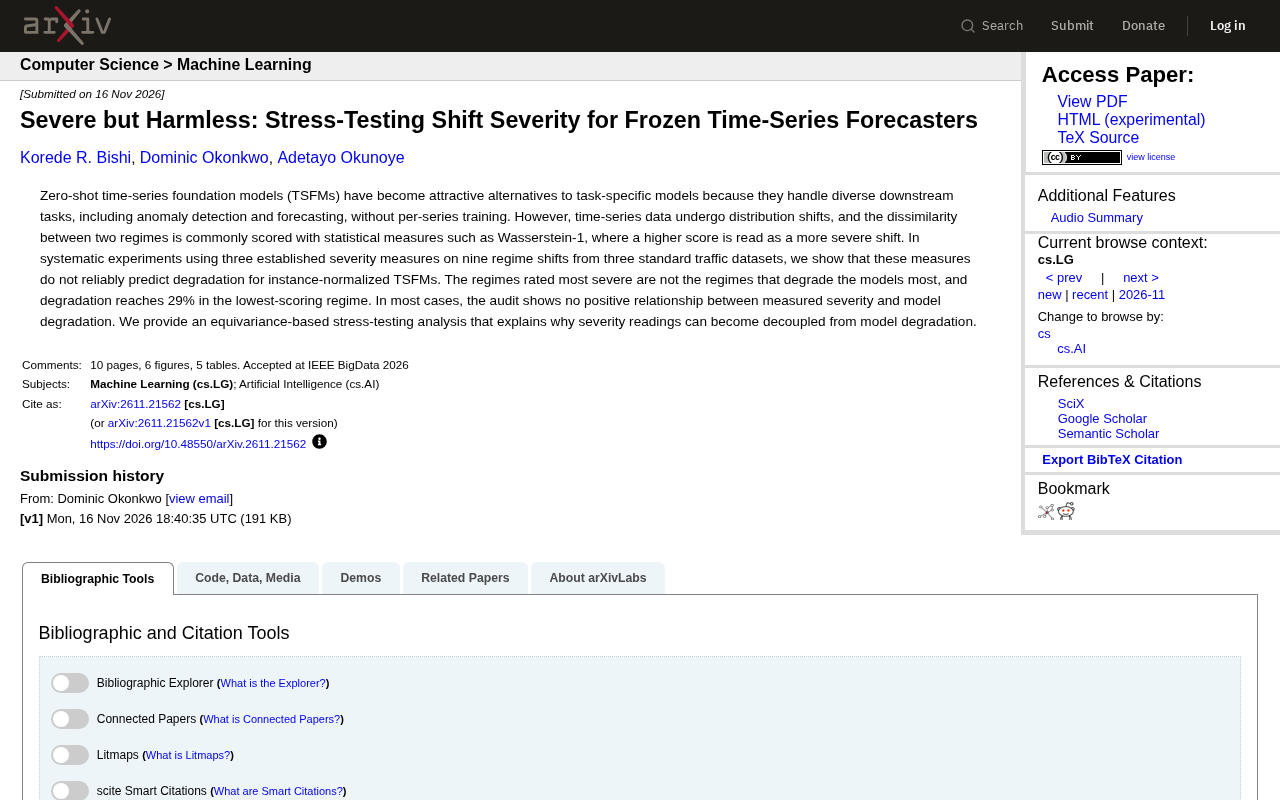
Statistically severe distribution shifts don't cause large degradation in frozen TSFMs—severity metrics fail.
A systematic study of frozen time-series foundation models (TSFMs) finds that common distribution shift severity metrics (such as Wasserstein-1 distance) cannot reliably predict model degradation. Across three traffic datasets and nine regime shifts, the shift rated most severe was not the one with the greatest degradation; degradation still reached 29% in the lowest-rated regime, and severity was mostly uncorrelated with degradation. The study proposes an equivariance-based stress-testing framework to explain the decoupling: instance normalization makes models immune to some statistically large shifts, while small-distance shifts may fall along sensitive directions. Robustness evaluation of zero-shot TSFMs should shift from data-side metrics to model-side evidence.
Introduction
Zero-shot time-series foundation models (TSFMs) are becoming a general-purpose solution for downstream tasks such as anomaly detection and forecasting, without requiring per-series training. However, time-series data is subject to distribution shift, and common metrics for measuring the difference between two data regimes (such as Wasserstein-1 distance) are widely interpreted as: the higher the score, the more severe the shift. A systematic set of experiments on frozen TSFMs, however, yields a counterintuitive conclusion: a statistically severe shift does not equal a large degradation in model performance.
Time-series foundation models (TSFMs) are models pretrained on large-scale, multi-domain time-series corpora that can be transferred zero-shot to downstream tasks, with typical representatives such as Chronos, TimesFM, and Moirai. Like NLP foundation models, TSFMs usually adopt a Transformer architecture, learning general time-series representations through masked reconstruction or autoregression. Zero-shot means the model performs inference directly on the target series without any parameter updates, so its performance depends heavily on the consistency between the pretraining distribution and the target distribution. Distribution shift refers to a mismatch between the training and test data regime (e.g., sensor replacement, changing road conditions), and is a core source of risk in zero-shot evaluation.
Wasserstein-1 distance (also known as earth mover's distance) measures the minimum transport cost between two probability distributions, is sensitive to shifts and shape changes in the distribution, and is often used as a proxy for shift severity. Its intuitive meaning is "the minimum amount of work required to turn one distribution into another," with larger values indicating more significant distributional differences.
Core Finding: Severity Scores Decoupled from Model Degradation
The study selected nine regime shifts across three standard traffic datasets and conducted systematic experiments using three well-established severity measures. The results show that for instance-normalized TSFMs, these measures cannot reliably predict drops in model performance.
- The shift regime rated as the most severe was not the one that caused the greatest model degradation.
- Even in the lowest-rated regime, model degradation still reached 29%.
- In most cases, the audit results show no positive correlation between the measured severity and model degradation.
This finding directly challenges the default assumption that "the larger the statistical distance, the more the model suffers," and suggests that researchers and engineers cannot judge a model's robustness under shift based on metrics such as Wasserstein-1 alone.
Why Do Severity Readings Decouple from Degradation?
The paper proposes a stress-testing analysis framework based on equivariance to explain this decoupling. Its core insight is that preprocessing steps such as instance normalization change the way the model is sensitive to the input distribution, so that some shifts that are statistically very different are "neutralized" by the model; conversely, some shifts with small statistical distances may happen to fall along directions the model is sensitive to, causing significant degradation.
This means that severity metrics measure the overall difference between data distributions, whereas model degradation depends on whether that difference occurs along a subspace the model is sensitive to. The two are not problems on the same dimension.
Instance normalization is a common preprocessing step in time-series models: for each input series, the mean is subtracted and the standard deviation divided out independently, standardizing the statistics of each sample. This operation endows the model with equivariance to shifts and scale changes—that is, when the input is shifted or scaled as a whole, the model output changes equivariantly, making it naturally immune to certain distribution shifts. Equivariance here means that the model output changes according to a deterministic rule as the input transforms (e.g., shift equivariance: add a constant to the input, and the output also adds the same constant), rather than remaining unchanged. It is precisely this equivariance that allows shifts with large statistical distances to be "absorbed," while shifts with small statistical distances that break the equivariance assumption (e.g., changing the shape or frequency structure of the series) instead cause significant degradation.
Implications for Evaluating Time-Series Foundation Models
The methodological significance of this study outweighs any single conclusion. It reminds the community:
- Stress testing should be model-oriented, not just data-oriented: when designing shift scenarios, one must consider the equivariance of the model architecture and normalization strategy, rather than ranking solely by statistical distance.
- Zero-shot evaluation requires cross-validation with multiple metrics: a single severity score is insufficient as a proxy for risk; it should be audited together with the model's actual degradation behavior.
- Robustness evaluation of frozen models needs recalibration: for instance-normalized TSFMs, traditional severity rankings of shifts may produce misleading conclusions.
Limitations and Outlook
The experiments cover three traffic datasets and nine regime shifts, and the generality of the conclusions still needs to be validated in more domains (such as energy, finance, and medical time series). In addition, the equivariance analysis currently provides more of an explanatory framework and cannot yet directly replace severity metrics. Future work could turn the equivariance perspective into actionable guidelines for shift design, helping to build stress-test sets that truly expose model weaknesses.
Conclusion
"Severe but harmless" captures the core tension of this study: statistically drastic distribution shifts may do little harm to a frozen time-series forecaster, while seemingly mild shifts may cause significant degradation. For engineering practice that relies on zero-shot TSFMs, this means robustness evaluation must shift from data-side metrics to model-side evidence.
One-line Summary
Statistically severe distribution shifts do not cause large degradation in frozen TSFMs, and severity metrics fail.
Paragraph Summary
A systematic set of experiments on frozen time-series foundation models (TSFMs) finds that common distribution shift severity metrics (such as Wasserstein-1 distance) cannot reliably predict model performance degradation. Across three traffic datasets and nine regime shifts, the shift rated most severe was not the one with the greatest degradation; even in the lowest-rated regime degradation still reached 29%, and in most cases severity was not positively correlated with degradation. The study proposes an equivariance-based stress-testing framework to explain this decoupling: preprocessing such as instance normalization makes the model immune to some statistically very different shifts, while shifts with small statistical distances may fall along directions the model is sensitive to. The conclusion suggests that robustness evaluation of zero-shot TSFMs needs to shift from data-side metrics to model-side evidence.
Related articles
Gemini 4 Neon Tested in Blender: Cheap but Not the King
Bilibili creator tests Gemini 4 Neon in Blender across five rounds vs Claude Fable, Opus, and GPT. Neon's detail nears Fable but animation still lags; at $44 vs Fable's $52, cheaper Argon under $14 is the value surprise.
Gemini 4 Neon Hands-On: Can It Challenge Opus 5.5?
Google released 4 Gemini 4 models in 49 days. We test whether Neon can challenge Opus 5.5 across benchmarks, real video tasks, and subscription costs.
Former Inmate Reveals Psychopath Ratio in Prison: About 200 Out of Every 880
Former inmate Larry Lawton shares on Lex Fridman's podcast that about 200 of 880 life-sentence inmates are psychopaths—a 23% ratio. He explores the blurred line between good and evil, social dynamics in prison, and wisdom from dark experiences.