Why Local AI Models Are Slow: Memory Bandwidth Is the Real Ceiling

Local LLM speed is capped by memory bandwidth divided by model size—bandwidth, not compute, is the bottleneck.
The article explains that the speed bottleneck for running large models locally is memory bandwidth, not chip compute. Each generated token requires re-reading all model parameters from main memory, which can't be cached. This gives a simple formula: max speed (tokens/sec) ≈ memory bandwidth ÷ model size. Running a 17GB model on the M5 Max's 614 GB/s yields ~36 tokens/sec theoretical and ~31 measured, with the 14% gap from sub-peak bandwidth, attention overhead, and software scheduling. The ceiling is nearly unbreakable without optimization, so choose hardware by bandwidth rather than core count, and use quantization, speculative decoding, and KV cache optimization to partially break through.
Many people assume that the speed of running large models locally depends on chip compute power, but the truth is: memory bandwidth is the hard upper limit that determines token generation speed. This metric, which most people overlook, explains why the high-end hardware you spent a fortune on still doesn't run fast enough.
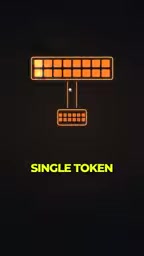
Core Mechanism: Every Token Generated Requires Reading the Entire Model Again
LLM inference has a counterintuitive characteristic: for every token generated, the model must re-read all parameters from memory. A 17GB model means that for every word output, those 17GB of data must be fully shuttled between memory and the compute units once.
Unlike traditional programs, this data cannot be cached and reused. Model parameter sizes are often tens of GB, far exceeding CPU cache capacity, so every inference pass must reload from main memory. The bottleneck isn't compute power—it's the speed of data movement.
Memory bandwidth refers to the total amount of data memory can transfer per unit of time, usually measured in GB/s. It's distinct from memory capacity: capacity determines how large a model you can fit, while bandwidth determines how fast data can be moved. LLM inference is a classic "memory-bound" workload—the compute units spend most of their time waiting for data to arrive from memory rather than actually computing. In contrast, "compute-bound" workloads, such as large-scale batched matrix operations, are limited by compute power. Understanding this distinction is essential for judging whether a hardware configuration is reasonable: local single-user inference is almost always memory-bound.
The Formula: Bandwidth Divided by Model Size
According to analysis from a YouTube tech channel, there is a theoretical upper limit to local AI token generation speed, and the formula is remarkably simple:
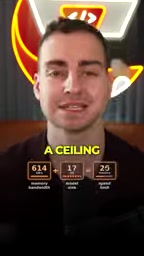
Maximum speed (tokens/sec) ≈ memory bandwidth ÷ model size
Take the M5 Max chip, for example, whose memory bandwidth reaches 614 GB/s. Running a 17GB model, the theoretical speed ceiling is about 36 tokens/sec. Actual benchmark results come in at roughly 31 tokens/sec—the theoretical and measured values are quite close, showing that this formula predicts real-world performance well.
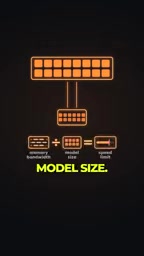
Where the Gap Between Theory and Measurement Comes From
Theoretical prediction is 36 tokens/sec, measured is 31 tokens/sec. The roughly 14% gap comes from multiple factors: memory reads don't always hit peak bandwidth, the computational overhead of the attention mechanism, and scheduling overhead in the software stack.
But the key point is that this formula's ceiling is nearly impossible to break without further optimization. You can upgrade the CPU and add more cores, but if memory bandwidth stays the same, speed won't improve substantially. This also explains why some seemingly luxurious configurations still run local models slowly.
The computational overhead of the attention mechanism comes mainly from the KV cache: when generating each token, the model must perform attention operations against the key-value vectors of all previous tokens. The longer the sequence, the larger the KV cache, and the more extra bandwidth is consumed reading it, which dilutes the effective available bandwidth. In addition, speculative decoding lets a smaller model draft multiple tokens first, then has the large model verify them in parallel, merging multiple serial reads into a single batched read—thereby improving effective throughput without changing bandwidth. Such optimizations can partially exceed the formula's ceiling, but the gains depend on the draft model's hit rate and don't apply unconditionally.
Practical Implications for Local AI Deployment
Once you understand this formula, hardware choices become clear:
- Focus on memory bandwidth rather than core count. For local inference scenarios, high-bandwidth memory (such as Apple's unified memory architecture or high-end GPU HBM) matters more than a many-core CPU.
- Model size directly determines the speed ceiling. Quantized compressed models (e.g., 4-bit quantization can reduce 17GB to about 5GB) can significantly boost speed, at the cost of precision loss.
- Optimization techniques exist but have limited headroom. Techniques like speculative decoding and KV cache optimization can break through some limits, but the underlying formula still holds.
This simple division formula is a quick ruler for judging whether any local AI hardware configuration is reasonable. When buying equipment or evaluating performance expectations, calculating the ratio of bandwidth to model size reflects real-world experience better than looking at benchmark scores.
One-line Summary
Local LLM generation speed is capped at roughly memory bandwidth divided by model size—the bottleneck is bandwidth, not compute.
Paragraph Summary
The article points out that the speed bottleneck for running large models locally isn't chip compute power but memory bandwidth. The reason is that for every token generated, the model must fully re-read all parameters from main memory and cannot cache and reuse them like traditional programs. This yields a simple formula: maximum speed (tokens/sec) ≈ memory bandwidth ÷ model size. Running a 17GB model on the M5 Max's 614 GB/s, theory predicts about 36 tokens/sec and measurement shows about 31 tokens/sec; the 14% gap comes from bandwidth not reaching peak, attention overhead, and software scheduling. This ceiling is nearly unbreakable without optimization, so when choosing hardware, prioritize bandwidth over core count, and use techniques like model quantization, speculative decoding, and KV cache optimization to partially break through.
Related articles

GPT-Next Leak, Gemini 4 Argon Imminent: AI News Roundup
GPT-Next leak suggests extreme efficiency; OpenAI's 28-day shipping pledge boosts speed 50%; Gemini 4 Argon nears release; Anthropic subscription value report sparks debate.

GPT-Next Leaked, Gemini 4 Argon Speeds Up, Fable 5.5 May Launch Today
OpenAI's GPT-Next model leaks, expected to be extremely low-cost and possibly part of the 28-day release plan; Gemini 4 Argon internal testing accelerates, NanoBanana 2.1 is live; Semi Analysis tests show Claude Max's equivalent API value is about 5 times that of ChatGPT Pro; Fable 5.5 may launch today.

Gemini 4 Argon Launches Globally: Key Highlights from the AI Daily Brief
Google opens Gemini 4 Argon globally across Pro and Ultra subscriptions and the API, and demonstrates robot control. This article rounds up open-source models, Agent infrastructure, cost transparency, and safety governance updates.