#RAG
287 related articles

A Practical Guide to RAG Failure Modes: Scan Corruption, Duplicate Chunks, and Index Leakage
A deep dive into three upstream RAG failure modes — scan OCR corruption, duplicate chunks crowding the retrieval window, and chunk-level index permission leakage — plus a three-stage clean-mask-compress-index fix and its quantified impact on storage and token costs.

Databricks AI Data Preparation Tools Compared: Mosaic AI Vector Search and Data Quality Solutions
A deep comparison of five AI data preparation tools on Databricks: SqlDBM semantic modeling, Mosaic AI Vector Search, Unstructured document parsing, Soda and Monte Carlo data quality monitoring—analyzing their strengths, weaknesses, pricing, and use cases.

PDF to Markdown for LLMs and RAG: Real-World Tests and Pitfall Guide
Tested NIST Cybersecurity Framework PDF-to-Markdown: 1.53M bytes compressed to ~65K chars (~16K tokens) in 1.7s. Learn why XFA and scans fail, plus 5 core rules for LLM document processing.

Local Embedding Model Selection Guide: Hardware Requirements and Cost Analysis
A practical 2026 guide to choosing local embedding models: Qwen3-Embedding vs EmbeddingGemma 2 hardware needs, VRAM, storage costs, API pricing, indexing speed, quantization, and migration.

Tired of Cobbling Together Local RAG Stacks, I Built a 100% Offline Enterprise-Grade RAG Scaffold
A developer integrated Ollama, FastAPI, LangChain, and React into VaultRAG, a 100% offline enterprise-grade RAG scaffold, solving the time-consuming problem of building local RAG full stacks, and shares practical experience with Docker networking and chunking parameter tuning.

7 Evaluation Dimensions to Test Before Launching RAG: A Practical Checklist
A RAG evaluation checklist covering retrieval, generation, complex scenarios, and reproducibility, with 7 must-test dimensions including Recall@K, faithfulness detection, and multi-document QA.

Understanding RAG: How to Make AI Answer Questions Using Your Own Data
A deep dive into how RAG (Retrieval-Augmented Generation) works: from document chunking and embedding to semantic retrieval and LLM answer generation, plus common pitfalls and real-world use cases.

Embeddings from First Principles: How a Kitten Finds a Cat, and Even Crosses Languages to Find Gato
Embeddings explained from first principles: how text becomes vectors, how cosine similarity measures semantic distance, why multilingual RAG fails silently when you pick the wrong model, plus twenty lines of runnable code and a pitfalls checklist.

Running RAG in the Browser: Field Tests and Reflections on Small Language Models
A full browser-side RAG pipeline: a sub-600MB model runs retrieval-augmented generation on local GPU. Testing 30 questions reveals small models' lack of refusal ability and ineffective relevance gating.

RAG Chatbot Pre-Launch Checklist: Six Critical Dimensions
A pre-launch checklist for first-production RAG chatbots covering six dimensions: use case boundaries, document chunking, separate retrieval and generation evaluation, evidence grounding, access control and timeliness, and workflow measurement—plus an end-to-end test.

Spring AI in Practice: A Full-Chain Optimization Guide to the 10 Major Pain Points of RAG Knowledge Bases
Based on a Spring AI hands-on course, this guide systematically explains the 10 major pain points in RAG knowledge base development: chunking strategy, Top-K optimization, cross-vector retrieval, permission security, and production deployment, helping Java developers quickly master core AI application development skills.

LangChain and LangGraph in Practice: End-to-End Implementation of a Production-Grade RAG System
A complete guide to building a production-grade RAG system with LangChain and LangGraph: semantic chunking, hybrid retrieval, RRF fusion, Cross-Encoder reranking, guardrails, orchestration, FastAPI deployment, and monitoring.

RAG Access Control: 3 Ways to Enforce Document Permissions in AI Applications
An in-depth analysis of three mainstream RAG access control approaches: on-behalf-of tokens, live ACL re-checks, and parent-level fine-grained authorization, examining their use cases and selection logic to help AI applications avoid document permission overreach.

Hands-On RAG Project: A Guide to Building from Scratch and Benchmarking Retrieval Strategies
From a real Reddit request, this guide offers actionable RAG project directions, public datasets (Wikipedia, arXiv, BEIR, MS MARCO), and retrieval strategy benchmarking methods, covering multi-format ingestion (PDF/HTML/CSV/Markdown) and evaluation pipeline setup.

AI Python Mentor: Building an AI Programming Learning Platform with FastAPI and RAG
AI Python Mentor is an open-source AI programming platform built with FastAPI, Next.js, and RAG, combining structured courses, coding exercises, and an AI mentor. This article analyzes its architecture, RAG integration, code execution security boundaries, and engineering lessons.

Vector Databases 101: The Core Principles Behind Storing and Retrieving Enterprise Knowledge
How do vector databases store and retrieve enterprise knowledge? This article breaks down vector database principles, HNSW approximate nearest neighbor indexing, pgvector in PostgreSQL, and a comparison of purpose-built vector databases Milvus/Qdrant/Pinecone to help you understand the technical foundation of semantic search and RAG.

Prompting, RAG, or Fine-Tuning? Diagnose the Failure First
When LLMs fail, don't rush to swap models or fine-tune. This diagnostic-first guide compares prompting, RAG, and fine-tuning boundaries with a decision flow and evaluation checklist.

Why OCR Remains the Cornerstone of Enterprise Document Processing in the Generative AI Era
Is OCR obsolete in the generative AI era? This article analyzes how OCR and generative AI complement each other through field extraction, RAG document Q&A, and content normalization, with a production-grade architecture and reliability testing strategies.

Building a FAQ Knowledge Base with Supabase Vector Store: n8n Automated Q&A in Practice
Learn how to build an FAQ knowledge base with n8n, Supabase pgvector, Google Sheets, and OpenAI Embeddings — covering SQL setup, API credentials, and data loading.
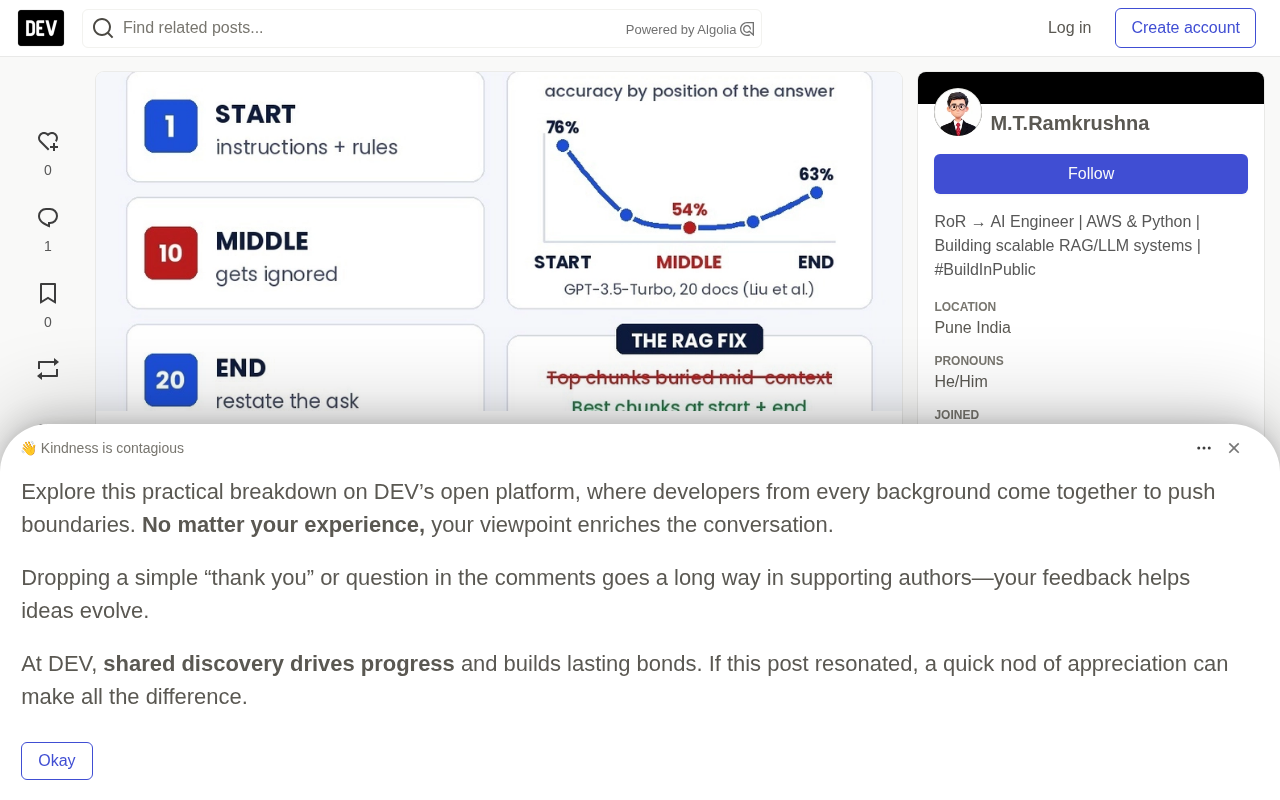
Lost in the Middle: Why LLMs Miss Critical Information in Long Prompts — and What to Do About It
LLMs show a U-shaped accuracy curve on long prompts — middle content gets ignored. Learn what the Lost in the Middle research found and how to fix prompt layout and RAG placement.