AI Large Model Zero-Basics Introduction: Analysis of a 749-Episode Full-Stack Practical Course

Bilibili's 749-episode AI large model tutorial offers a structured path from zero-basics to practical application, but its "get a job upon completion" claim should be viewed rationally.
This article introduces a 749-episode AI large model zero-basics introductory tutorial on Bilibili, designed to help beginners systematically master large model development and applications. The course covers three levels: foundational understanding (Transformer, prompt engineering), framework application (LangGraph), and advanced practical application (RAG, Agent, fine-tuning), following a progressive logic from environment setup to advanced practice, and includes multiple project landing scenarios. The article acknowledges the course's structured value in reducing material filtering costs but notes that the "get a job upon completion" promise is exaggerated, as actual employment also requires computer fundamentals, algorithm skills, and engineering experience. It recommends using the course as an introductory guide alongside official documentation and project practice to gradually build a technical system.
In today's rapidly evolving AI large model technology landscape, how to systematically master large model development and applications from scratch has become a real challenge for many developers. This "749-episode full course" on Bilibili, billed as an AI large model zero-basics introduction, attempts to answer this question with a complete curriculum system.
Course Positioning and Target Audience
This course explicitly targets zero-basics learners, with its core selling point being "from zero-basics beginner to 50k"—according to the instructor, you can get a job upon completion. From the course design logic, it attempts to solve a real pain point: knowledge in the AI large model field is severely fragmented, and beginners often need to piece together materials across different platforms, lacking a clear learning path.
The course claims to deliver high-density knowledge points throughout, being extremely beginner-friendly, and promises to guide learners hand-by-hand through environment setup and landing their first AI large model application project. This combination of "environment deployment + project practice" is indeed attractive to learners without engineering experience.
Breaking Down the Core Knowledge System
From the course outline, this tutorial covers a fairly broad range of knowledge, roughly divided into three levels.
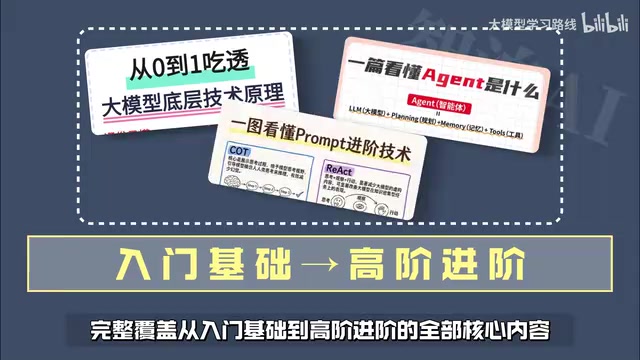
Foundational Understanding Level includes basic AI large model cognition and core operating principles, helping learners build a preliminary understanding of underlying concepts such as Transformer architecture and attention mechanisms. Prompt engineering appears as an independent module, indicating that the course treats prompt design as a core skill requiring systematic training, rather than a simple usage technique.
Framework Application Level involves the use of the LangGraph framework. As an important tool for building stateful, multi-step AI applications, LangGraph has been widely adopted in Agent development scenarios in recent years. The course's inclusion of it in the teaching system reflects its adherence to the current tech stack.
Advanced Practical Level includes RAG knowledge base construction, Agent intelligent agent development, model fine-tuning, and multi-model collaboration and task scheduling logic. According to discussions on Bilibili UP creators and YouTube channels about this course, the application of RAG retrieval-augmented technology in intelligent Q&A scenarios is one of the course's highlight modules, achieving the connection between private knowledge bases and large models through the combination of vector databases and retrieval strategies.
Transformer architecture is the cornerstone of the vast majority of current large language models, proposed by Vaswani et al. in the 2017 paper "Attention is All You Need." It completely abandoned the sequential dependency of recurrent neural networks (RNNs), instead adopting the Self-Attention mechanism to allow each position in a sequence to directly interact with all other positions, thereby supporting large-scale parallel computation. A standard Transformer is composed of stacked encoders and decoders, each layer containing multi-head attention sublayers and feed-forward network sublayers, supplemented by residual connections and layer normalization. The GPT series uses only the decoder part, achieving autoregressive generation through masked attention; BERT uses the encoder part and excels at understanding tasks. Understanding the Transformer's input embeddings, positional encoding, multi-head attention, and feed-forward networks is the first step to comprehending the internal operating logic of large models.
Prompt engineering refers to the systematic method of guiding large models to generate desired outputs through carefully designed input prompts. It is not simply a "questioning technique," but a set of engineering practices covering instruction design, context construction, output format constraints, and example selection. Common techniques include: zero-shot prompting (directly giving the task), few-shot prompting (providing a few examples), Chain-of-Thought (requiring the model to reason step by step), Self-Consistency (multiple sampling and voting), and the ReAct pattern (alternating reasoning and action). In large model application development, prompt engineering directly affects the accuracy, stability, and controllability of model outputs, so it is often used in combination with RAG, Agent, and other technologies—it is the lowest-cost but most significantly beneficial optimization method.
LangGraph is a framework launched by the LangChain team for building stateful, multi-step AI applications, particularly suitable for developing complex Agent systems. Unlike traditional linear chains, LangGraph models applications as graphs, where nodes represent computation steps (such as calling models or executing tools) and edges represent control flow (including conditional branches and loops). It has built-in state management mechanisms, allowing context persistence across multiple steps, and supports human intervention, breakpoint resumption, and streaming output. LangGraph's core advantage lies in its ability to clearly express loops, branches, and parallel logic, which is crucial for implementing patterns like ReAct, Plan-and-Execute, and multi-agent collaboration. Compared to LangChain's AgentExecutor, LangGraph provides more fine-grained control and higher observability, thus becoming a popular choice for building production-grade Agents after 2024.
Practical Path from Knowledge Base to Project Landing
The course's application scenarios cover the mainstream directions of current large model implementation: building large model Q&A applications, automated task processing, large model tool development, private knowledge base construction, and large model robots. This project-driven teaching approach is closer to actual work needs than pure theoretical explanations.
RAG knowledge base construction, as the core content of the advanced module, involves document chunking, vectorized storage, retrieval strategy optimization, and integration with generative models. Agent intelligent agent development further requires learners to understand design patterns for tool calling, task planning, and multi-turn interaction. The course places model fine-tuning in the final stage, conforming to the progressive learning logic of "application first, training later."
Vector databases are the core storage component in RAG architecture, specifically designed for efficiently storing and retrieving high-dimensional vectors. After text is converted into dense vectors by embedding models (such as OpenAI text-embedding, BGE, etc.), vector databases use approximate nearest neighbor (ANN) algorithms (such as HNSW, IVF, PQ) to find the most similar segments to a query from massive vectors within milliseconds. Unlike traditional keyword retrieval, vector retrieval is based on semantic similarity and can capture synonyms and contextual associations. In the RAG process, typical steps are: document chunking → vectorization → storing in vector database → vectorizing user query → similarity retrieval → injecting retrieval results as context into the large model to generate answers. Common vector databases include Milvus, Pinecone, Weaviate, Chroma, and FAISS, etc. Selection requires weighing scale, latency, cost, and operational complexity.
Course Value and Rational Assessment
The value of this tutorial lies in providing a structured learning path, reducing the time cost for beginners to filter materials. The scale of 749 episodes is indeed impressive, but the actual learning outcome depends on content depth and the instructor's teaching quality. It should be noted that the promise of "get a job upon completion" contains exaggeration—positions in the AI large model field usually also require computer fundamentals, algorithm skills, and engineering experience, which a single introductory tutorial cannot fully cover.
For zero-basics learners, it is recommended to use this course as an introductory guide, combined with official documentation and actual project practice, to gradually build your own technical system. The core competitiveness of large model application development is ultimately reflected in the ability to solve real problems, not the number of courses completed.
One-line Summary
Bilibili's 749-episode AI large model tutorial provides a structured path from zero-basics to practical application, but "get a job upon completion" should be viewed rationally.
Paragraph Summary
This article introduces a 749-episode AI large model zero-basics introductory tutorial on Bilibili, aimed at helping beginners systematically master large model development and applications. The course covers three levels: foundational understanding (Transformer, prompt engineering), framework application (LangGraph), and advanced practical application (RAG, Agent, fine-tuning), following a progressive logic of "environment setup → basic application → framework usage → advanced practice," and includes multiple project landing scenarios. The article affirms the course's structured value in reducing material filtering costs, but also points out that the promise of "get a job upon completion" is exaggerated; actual employment also requires computer fundamentals, algorithm skills, and engineering experience. It is recommended to use the course as an introductory guide, combined with official documentation and project practice, to gradually build a technical system.
Related articles

AI-Powered SRC Vulnerability Hunting: A Hands-On Guide to Building the Hermes Agent Workbench
Based on a hands-on Bilibili video: how to build an AI-powered SRC vulnerability hunting workbench—three-step method, four report elements, Agent mode vs web chat, and tool selection.

CLI-Anything Complete Beginner's Guide: How AI Operates Software — Principles and Practice
A complete beginner's guide to CLI-Anything: how AI Agents operate professional software via the command line, covering the three-layer architecture, CLI Hub installation, DrawIO practice, generator principles, and limits.

Carbon-X: A 14.8B Open-Source Model That Handles DNA and Text Simultaneously
Carbon-X is a 14.8B open-source multimodal model on Hugging Face where DNA and text share a token stream. 6-mer tokenization, 302B token mid-training, deployable on a single 80GB GPU, 66.7% average on five DNA benchmarks, Apache 2.0 license.