Fit Receipt: A Privacy-First Virtual Try-On Agent That Knows When to Call JEV

Fit Receipt demonstrates how AI agents should invoke judgment models responsibly, isolate sensitive data, and protect facts with code.
Fit Receipt is an open-source reference implementation that debuted at Vercel Day — a virtual lingerie try-on tool on the surface, but in reality a technical demonstration of AI agent engineering patterns. Its innovations span three layers: a JEV judgment model invoked only when needed, with calibrated confidence that stays unresolved rather than forcing low-confidence answers; a layered architecture where the agent handles chat while code protects facts and pricing; and client-side photo processing so JEV only sees structured fields, not images. A high-value reference for teams building vertical AI agents.
At Vercel Day on Product Hunt, a product called Fit Receipt landed in 19th place with 73 upvotes. It tackles two seemingly unrelated problems: how to make virtual try-on more trustworthy, and how to draw a clear line between "conversation" and "fact" in AI Agent products. As a reference implementation, the answers it offers are worth paying attention to.
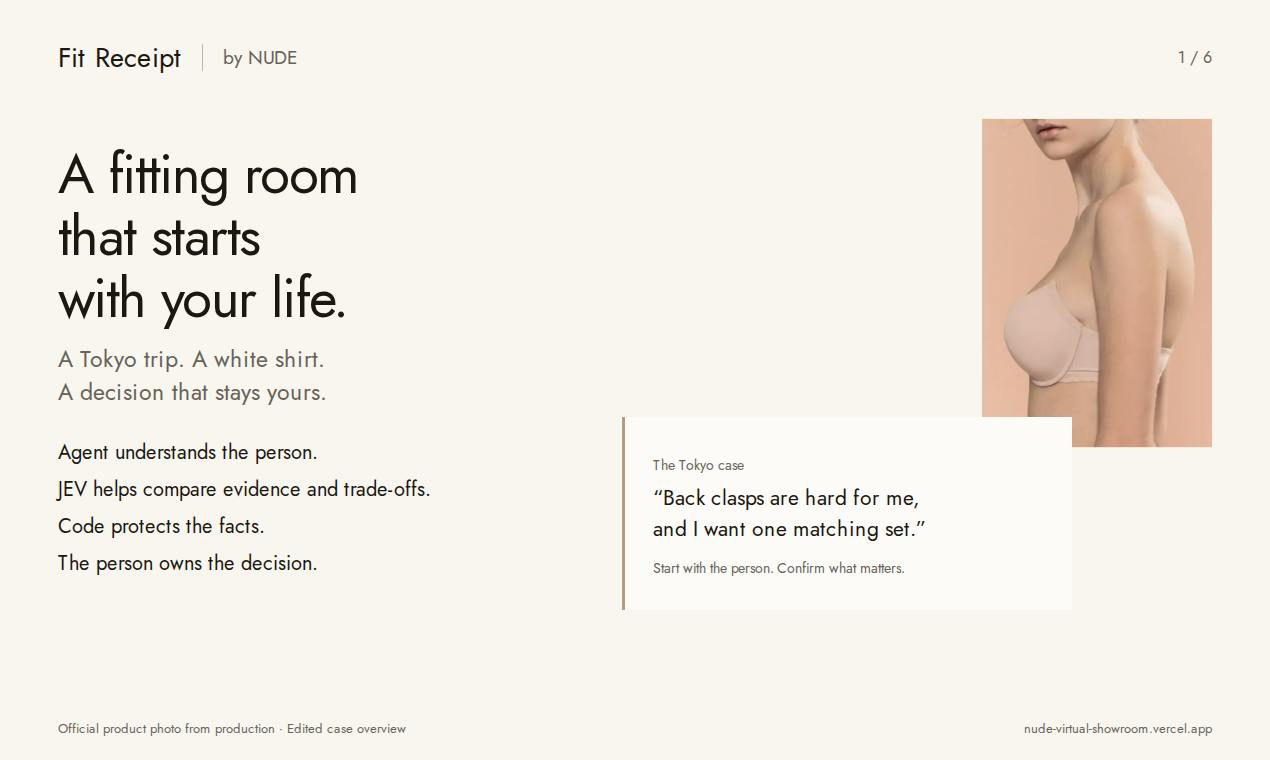
A Virtual Try-On Tool That Comes with a "Judgment Receipt"
Fit Receipt's core feature is virtual bra try-on in the browser — but its real selling point isn't the try-on itself. It's that every selection comes with an AI judgment receipt. In other words, the product doesn't just tell you whether something fits; it records the reasoning behind that judgment, creating an auditable trail.
This design transforms "recommendations" from a black box into an accountable process. For a category like lingerie — where sizing and personal preference are everything — a system that can explain why it recommends something is far more convincing than one that just outputs a result. The product spans three categories: Productivity, Fashion, and Developer Tools, which signals that it's not a pure e-commerce play but a clear technical demonstration.
JEV: A Judgment Model Called Only When Needed
JEV (TypeSafe), embedded in the product name, is the technical core of the entire system. According to the official description, JEV is a judgment model purpose-built to score trade-offs and deliver calibrated confidence. It responds in roughly 300 milliseconds and outputs concise scoring results rather than lengthy explanations — "scores trade-offs, not essays."
More importantly, it's the invocation logic that matters. The product tagline emphasizes this is an agent that "knows when to call JEV," meaning JEV isn't triggered every time. When confidence is too low, the system stays in an unresolved state rather than forcing an unreliable answer. All judgments are logged, and the entire pipeline can run without JEV if needed.
This mechanism reflects a pragmatic Agent design philosophy: the model only intervenes when it has something valuable and reliable to contribute. When confidence is low, it's better to admit uncertainty than to manufacture a hallucination. For products that depend on large language model outputs, the ability to "know when not to act" is often more important than "being willing to answer anything."
What is "calibrated confidence"? Calibrated confidence is a core concept in probabilistic prediction. It refers to the alignment between a model's stated confidence scores and its actual accuracy. A well-calibrated model that says "I'm 80% confident" should be correct roughly 80% of the time across many such predictions. Uncalibrated models, by contrast, tend to be overconfident — outputting near-100% confidence even when internally uncertain. This can cause serious problems in medical diagnosis, financial decisions, or product recommendations. JEV's emphasis on calibrated confidence means it honestly reflects its own uncertainty when scoring, enabling the system above it to make rational decisions: accept the judgment when confidence is high, stay unresolved when it's low — rather than masking uncertainty with a forced answer.
The Agent Handles Chat; Code Protects Facts
Fit Receipt establishes a clear division of responsibility: the agent handles chat; code protects facts and pricing.
This is an increasingly critical issue in AI product engineering. Large language models excel at natural interaction but are poorly suited for outputting error-intolerant information like prices, inventory, and factual data. Handing pricing over to a model that can "make things up" is a recipe for disaster. Fit Receipt's approach locks these critical facts behind deterministic code logic, leaving the agent responsible only for the conversational layer — eliminating hallucination risk at the architectural level.
This layered approach — "conversation to the agent, facts to the code" — offers a replicable pattern for teams building vertical AI agents.
The "deterministic guardrails" pattern is the engineering term for this design. One of the core flaws of large language models is hallucination — generating fluent-sounding but factually incorrect information. For structured facts like prices, inventory counts, legal terms, or medical dosages, the cost of an error far exceeds that of a conversational mistake. The standard engineering practice is to store such data in databases or config files, read and validate it through deterministic code logic, and give the model only a read-only view — preventing any "creative interpretation." By explicitly building this principle into its product narrative, Fit Receipt gives developers a clear architectural decision framework: information that cannot afford to be wrong should never be generated by a model — it should be queried by code.
Privacy by Design: Photos Never Leave the Browser
Virtual try-on inevitably raises a sensitive question: what happens to user photos? Fit Receipt takes a notably restrained approach to privacy:
- Photos stay in the browser locally — no server-side photo storage;
- JEV only sees typed (structured) fields, never the photo itself;
- The API is rate-limited.
For something as intimate as lingerie try-on, keeping image processing client-side and exposing the judgment model only to anonymized structured data is a principled engineering choice aligned with data minimization. It preserves the AI's ability to make judgments while eliminating any path for photos to leak.
Data minimization is one of the core principles in regulations like GDPR, requiring that systems collect and process only the minimum personal data necessary to accomplish their goal. In this case, the principle is enforced through technical architecture rather than legal declarations: images are processed on the client, and only structured feature fields extracted from the image (such as body measurements or estimated size parameters) are sent to the server — never the photo itself. This "process locally, transmit only metadata" pattern echoes Apple's differential privacy approach: even if the server is compromised, there's no original image to recover. For a category as sensitive as lingerie — which involves body images — this architectural choice is both a privacy engineering best practice and a pragmatic strategy for reducing compliance risk.
A Reference Implementation for Developers
It's worth emphasizing that Fit Receipt repeatedly positions itself as a "reference implementation" — open source and deployed on Vercel. Its appearance at Vercel Day, with 11 comments and 73 upvotes, reads more like a technical demonstration for the developer community than a polished consumer product.
The message it's trying to send is clear: here's how to use a judgment model responsibly in a real product — call it on demand, calibrate confidence, acknowledge uncertainty, isolate sensitive data, and use code to protect factual integrity. The value of these design principles likely far exceeds the specific use case of "virtually trying on lingerie."
For teams building AI agents, Fit Receipt doesn't offer a product to copy directly. It offers a thinking framework for "when AI should intervene — and how it should be constrained."
Related articles

Free Unlimited Claude Code Solution: Agnes AI + CC Switch Setup Guide
No paid subscription needed — pair the free AI platform Agnes AI with the open-source tool CC Switch to provide a backend for Claude Code, enabling unlimited free calls to text, image, and video models. This guide covers the full setup, test results, and usage boundaries.

A Complete Zero-Cost Guide to Getting Started with Claude Code for Beginners in China
A beginner's guide to Claude Code for users in China: two installation methods (command line and IDE plugin), full configuration steps for replacing the official API with the free domestic LongCat model, and a hands-on demo of building a small tool with natural language, plus tips.

When the NSA Gets Involved: The AI Supply Chain Crisis Behind Open-Source CVEs and API Key Hijacking
Multiple open-source projects disclosed severe CVEs in one day, PHP flaws alarmed the FBI, and Railway and OpenCode were breached with API keys stolen. This article breaks down the vulnerability window, AI-accelerated exploitation, and the AI supply chain crisis behind the API key black market, with a developer defense checklist.