Ollama v0.35.0-rc1 Released: MLX Pull Retry Optimization

Ollama v0.35.0-rc1 improves MLX pull stability with bounded retries and a watchdog interrupt mechanism.
Ollama has released v0.35.0-rc1, marking the final testing phase before a stable release. The key change focuses on the MLX backend: pull stall retries are now bounded, and a watchdog mechanism can actively interrupt deadlocked retries — resolving long-running hangs during model downloads on unstable networks. MLX is Apple's machine learning framework for Apple Silicon, and Ollama's continued investment in it reflects strong support for local inference on Mac. The release is GPG-signed via GitHub for authenticity, but as a release candidate, it is primarily intended for advanced testers — production users should wait for the official stable release.
Ollama Releases v0.35.0-rc1 Preview
Ollama, the local large language model runtime framework, recently tagged a new release candidate — v0.35.0-rc1 — on GitHub. As a tool that has garnered over 182,000 stars and is widely used for deploying open-source LLMs locally, every version iteration from Ollama draws close attention from the developer community. The rc1 (Release Candidate 1) designation signals that this version has entered its final testing phase before an official stable release.
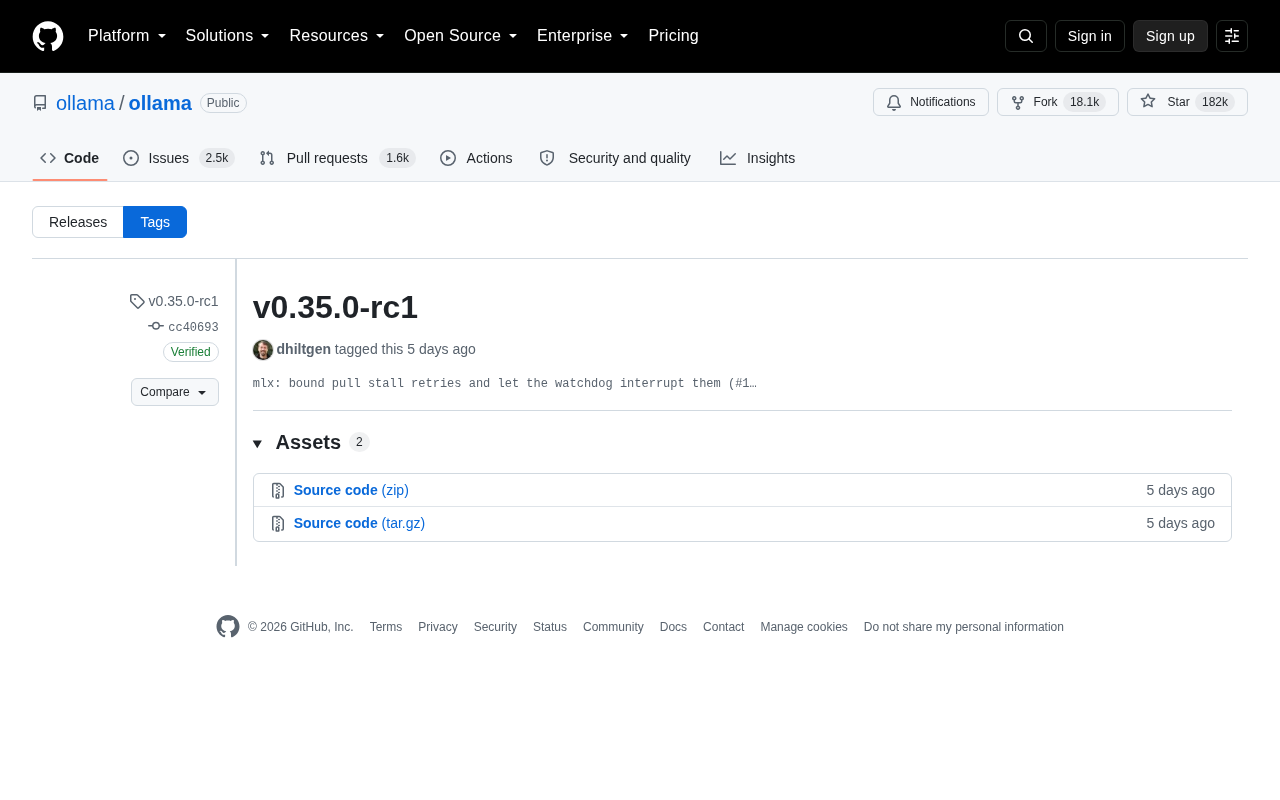
Based on GitHub's commit history, the tag was created by maintainer dhiltgen and verified with GitHub's signature mechanism (GPG key ID: B5690EEEBB952194). This signing process ensures the authenticity of the release artifacts — an important security guarantee for users deploying in production environments.
Key Changes in This Release
From the public commit messages, one notable change in this release candidate is related to the MLX backend:
mlx: bound pull stall retries and let the watchdog interrupt them
This change targets stall issues that can occur during model pulls. In real-world usage, when the network is unstable or a remote repository responds slowly, model downloads can get stuck in a cycle of repeated retries without making any progress. This update introduces a hard limit (bound) on the number of retries and adds a watchdog mechanism that can actively interrupt retries when they become deadlocked — preventing processes from hanging indefinitely.
Why MLX Matters
MLX is Apple's machine learning framework designed specifically for Apple Silicon, taking full advantage of the unified memory architecture of the M-series chips. Ollama's continued optimization of the MLX backend reflects its commitment to local inference on the Mac platform. For users running local models on a MacBook or Mac Studio, the stability of the pull process directly impacts the deployment experience.
The Unified Memory Architecture of MLX is key to understanding its performance advantages. On traditional desktop platforms, the CPU and GPU each have their own dedicated memory, and transferring data between them introduces latency and bandwidth bottlenecks. Apple Silicon consolidates the memory for the CPU, GPU, and Neural Engine into a single unified memory pool, eliminating data-copy overhead. This allows LLM weights to be directly accessed by the GPU — particularly beneficial when running larger models (e.g., 7B or 13B parameter scale). MLX is designed specifically around this architecture, supporting lazy evaluation and function transformations, with an API style that blends NumPy and PyTorch conventions to make it easy for developers to migrate existing code. With Ollama's MLX backend integration, Mac users can bypass the general CPU path during local inference and directly leverage the hardware advantages of M-series chips for lower latency and higher throughput.
The watchdog mechanism is a classic reliability pattern in software engineering, originally rooted in embedded systems. The core idea is to set up an independent monitoring process or timer — if the monitored task fails to complete or send a heartbeat within a specified time window, the watchdog actively intervenes to forcibly terminate or restart it. In network I/O scenarios, retry logic without upper-bound constraints can easily fall into a "livelock" state — the process keeps running but makes no progress, consuming resources while failing to surface as an error to the outside world. This Ollama update combines two layers of protection: a hard retry limit (bound) to prevent infinite loops, and watchdog interrupt authority to ensure that even if the retry logic itself encounters an anomaly, it can still be handled as a fallback. This dual mechanism is a best practice in both distributed systems and client-side tooling, and significantly improves the user experience predictability in unstable network environments.
What a Release Candidate Means
It's worth clarifying that rc1 is a release candidate, not a stable release. These builds are primarily aimed at advanced users willing to test new features early and help identify issues. For production environments where stability is paramount, it's generally advisable to wait for the official stable release before upgrading.
The release page provides the corresponding build artifacts (Assets) for download and testing. Community feedback at this stage often determines whether the final release can ship smoothly or requires additional fixes.
What This Means for Developers
As one of the leading tools for locally deploying large language models, Ollama's strength lies in simplifying the entire workflow of model downloading, management, and inference. While this improvement to pull stability is an under-the-hood refinement, it offers real value for developers who frequently pull and switch between models — effectively reducing hangs and wait times caused by network issues.
Given the high demands that local LLM inference places on both hardware and network environments, this kind of foundational reliability improvement can be just as valuable as new features. Users following Ollama are encouraged to keep an eye on the upcoming official release notes for the complete changelog.
Note: This article is based on publicly available information from Ollama's official GitHub release page. Since rc1 is a release candidate, the complete update details should be confirmed against the final stable release notes.
Related articles

Free Unlimited Claude Code Solution: Agnes AI + CC Switch Setup Guide
No paid subscription needed — pair the free AI platform Agnes AI with the open-source tool CC Switch to provide a backend for Claude Code, enabling unlimited free calls to text, image, and video models. This guide covers the full setup, test results, and usage boundaries.

A Complete Zero-Cost Guide to Getting Started with Claude Code for Beginners in China
A beginner's guide to Claude Code for users in China: two installation methods (command line and IDE plugin), full configuration steps for replacing the official API with the free domestic LongCat model, and a hands-on demo of building a small tool with natural language, plus tips.

When the NSA Gets Involved: The AI Supply Chain Crisis Behind Open-Source CVEs and API Key Hijacking
Multiple open-source projects disclosed severe CVEs in one day, PHP flaws alarmed the FBI, and Railway and OpenCode were breached with API keys stolen. This article breaks down the vulnerability window, AI-accelerated exploitation, and the AI supply chain crisis behind the API key black market, with a developer defense checklist.