#OCR
13 related articles

InvoiceSnap AI: Local AI Turns Receipt Photos into Structured Expense Sheets
InvoiceSnap AI is an open-source local receipt scanner combining Tesseract OCR with Gemma via Ollama to extract merchant, date, amount, and category, with editing and CSV export—privacy-focused and low-cost.

How Agentic OCR Tackles Three Million Pages of Messy Scanned Documents
Reducto shares how agentic OCR handles 3 million pages of messy scanned documents behind J-Mail—covering rasterization, extraction schemas, redaction failures, and evaluation challenges.

Strukku: A Receipt Bookkeeping Tool for Freelancers Powered by Open-Weight Models
Strukku is an open-source receipt bookkeeping tool for freelancers, using the Gemma open-weight vision model to extract vendor, date, and amount from photos and export CSV ledgers.

Datalab Open-Sources OmniParseBench: 16,288 OCR Tests to Audit Document Parsers
Datalab releases open-source OCR benchmark OmniParseBench with 16,288 test items across 2,937 pages and 92 languages. Pass rates are sliceable by tag, script, or language, making document parser evaluation auditable and reproducible.

Document Conversion: The Overlooked Productivity Tool and How It Fits Into AI Workflows
Document conversion is overlooked in developer productivity, yet it directly impacts data entry efficiency. This article analyzes OCR's role in developer workflows, the fit of lightweight solutions like LoveOCR, and three principles for integrating image-to-structured-data into automation.

The Data Trap in Screenshots: How OCR Turns Images Back Into Usable Data
Screenshots make saving information easy but using it hard. This article breaks down a complete OCR workflow: from image extraction and format conversion (JSON/CSV/XML/YAML) to result validation, showing why format conversion is the key step to turning screenshot data into usable data.

Verdandi: An Open-Source Document Intelligence Tool at One-Tenth the Cost of Azure
Former EY analyst open-sources Verdandi, a document intelligence platform benchmarked against Azure Content Understanding: 97% vs 96.2% field accuracy, 9.7x lower cost, local OCR, cross-document validation, and human review.
OpenDocRouter Launches: A Unified API Aggregating 130+ Document Parsing Models
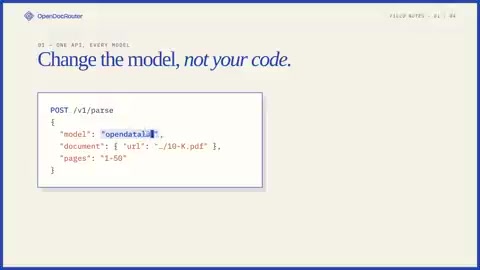
OpenDocRouter launches a unified document parsing API aggregating 130+ frontier and open-weight OCR/VLM models, with at-cost pricing, rate limit management, bounding box layout services, and automated routing.

A New Approach to Document Grounding: PDF Geometry + OCR + Visual Evidence Achieves 72.6% Word F1
A developer built a document grounding system using PDF geometry, OCR spatial info, format matching, and visual evidence — achieving 72.6% Word F1 with no external LLMs.

GAD-RL: Improving OCR Transcription Faithfulness with Gated and Attenuated Distillation
GAD-RL uses gated and attenuated on-policy distillation to improve VLM OCR faithfulness, outperforming GRPO by 8.45 points on CHAOS-Bench.

Korean Invoice OCR Model: Deep Learning + Image Preprocessing Achieves 87% F1 Score
An arXiv study proposes a Korean invoice OCR model combining deep learning and image preprocessing, achieving 87% F1 on real invoice data with minimal latency.

How Empty Table Cells Undermine AI Agent Decision Accuracy
Empty table cells cause OCR value misalignment, corrupting AI Agent decision accuracy. Learn why this hidden trap matters and how tools like LlamaParse address it.
