All articles
38472 articles

User Embeddings Are Sparse Superpositions of Interpretable Behavioral Patterns
New research on user embedding interpretability: user embeddings are sparse superpositions of interpretable behavioral patterns, recovered and named automatically via SAEs, enabling zero-shot audience retrieval. Post-hoc and model-agnostic.

XStack Benchmark: A Touchstone for Cross-Framework ML Code Migration
XStack is a benchmark for evaluating agents migrating ML codebases between PyTorch and JAX. Claude Opus 5 passes 75%, GPT-5.6-sol 45%, others at most 40%. Learn the details and significance of this cross-framework challenge.

How Token Caching Can Save You 98% on Your DeepSeek Bill
The root cause of DeepSeek API bills varying by dozens of times lies in token cache hit rates. This article breaks down LLM input/output pricing, disk caching, and the 1/50 price gap, with practical money-saving strategies.
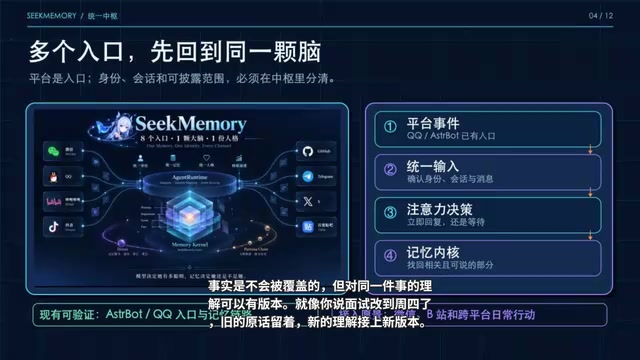
Token-Saving Memory Plugin Sick Memory: Just ¥0.9 per Day
Bilibili creator 大肥鱼呀 introduces Sick Memory, a memory plugin using a unified hub, relevance-ranked memory, and Dream organization to let AI characters remember you selectively with evidence, cutting the token cost of reloading old content—about ¥0.9 per day.
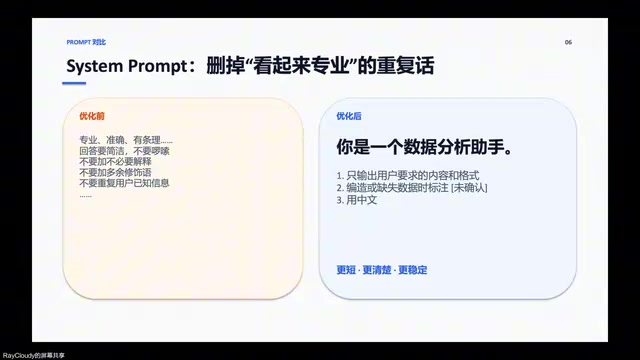
Always Running Out of Tokens? This Five-Layer Methodology Saves You Real Money
Tokens getting expensive? This five-layer optimization methodology covers streamlined input, model tiering, context bloat control, cache reuse, and systematic measurement, plus open-source tools like kintestmode and CodeGraph and a 30-second self-check list.

OpenAI Abandons Data Center NDAs: A Key Step Toward Rebuilding Community Trust
OpenAI announces it will no longer sign NDAs with public officials for data center projects, responding to midterm voter opposition. This article analyzes the policy shift's industry impact and significance for rebuilding community trust.

Bypassing DeepSeek Detection: Sneaky Reverse-Proxy Tricks to Avoid Bans and Their Risks
A Bilibili creator shares a DeepSeek reverse-proxy scheme to avoid bans: evading XML tags, using a single English word as trigger, and registering with overseas emails. This article breaks down the technical approach, Harness integration results, and the real risks of this "unlimited tokens" game in terms of rule confrontation, account stability, and compliance.

4 Must-Have Plugins for Saving Tokens in DSH — Stop Installing Blindly
A detailed guide to 4 must-have DSH token-saving plugins: DSH Shops shortens tool output, Billion Context compresses early context, Vision Router converts images to text, and Thinking Levels auto-adjusts thinking depth — plus backup and verification tips before installing.
Retested 51 Times: DeepSeek Harness Token-Saving Plugins — Use Them Right and Save Half, Use Them Wrong and Pay More
51 test runs of three DeepSeek Harness token-saving plugins: Ops saves half only in PTC mode, Flash Presets saves ~20% via rules, Billion Context saves context space but not money. Includes selection guide and pitfalls.

QQ Bot Burning Through Tokens Too Fast? Engineering Layering and Cost-Saving Tips
QQ bot burning tokens too fast? Bilibili creator Da Fei Yu shares an engineering layering solution: separate deep and shallow memory, switch to coding plans, and add basic RAG—estimated to save 10x to 100x tokens.

AstrBot Plugin in Practice: Advanced Optimization Strategies to Drastically Cut Token Consumption
A Bilibili creator shares advanced AstrBot plugin optimizations: context window compression, shallow/deep memory separation, on-demand story packs, group chat read frequency control, and non-reasoning judgment mode to drastically cut token consumption.

LangChain 1.3 Systematic Tutorial: Hands-On RAG/Agent/MCP/LangGraph in Practice
Bilibili creator Loulan's LangChain 1.3 systematic tutorial covers architecture fundamentals, RAG, Agent, MCP, and LangGraph multi-agent projects, emphasizing systems and practice over tools and theory to build transferable AI development skills.
Cult.fit Uses Codex to Build Operation…
Cult.fit Uses Codex to Build Operational Tools, Accelerating Cross-Functional Teams
Cult.fit is using OpenAI Codex to help cross-functional teams build internal tools, speed up work pace, and change how they work. This article analyzes implementation scenarios, value, and governance boundaries of cross-functional AI programming.

Google Releases Gemini Omni 1.2 Flash: 15-Second AI Video at $0.07 per Second
Google releases Gemini Omni 1.2 Flash video generation model with native 15-second clips and multi-turn conversational editing, cutting 720p pricing 30% to $0.07 per second.

Ollama v0.40.15 Released: Adds Kimi Code CLI Support
Ollama v0.40.15 released, adding Kimi Code CLI support to cmd/launch, commit #19506 GPG-verified. This article covers the update's impact on AI coding workflows and version verification details.
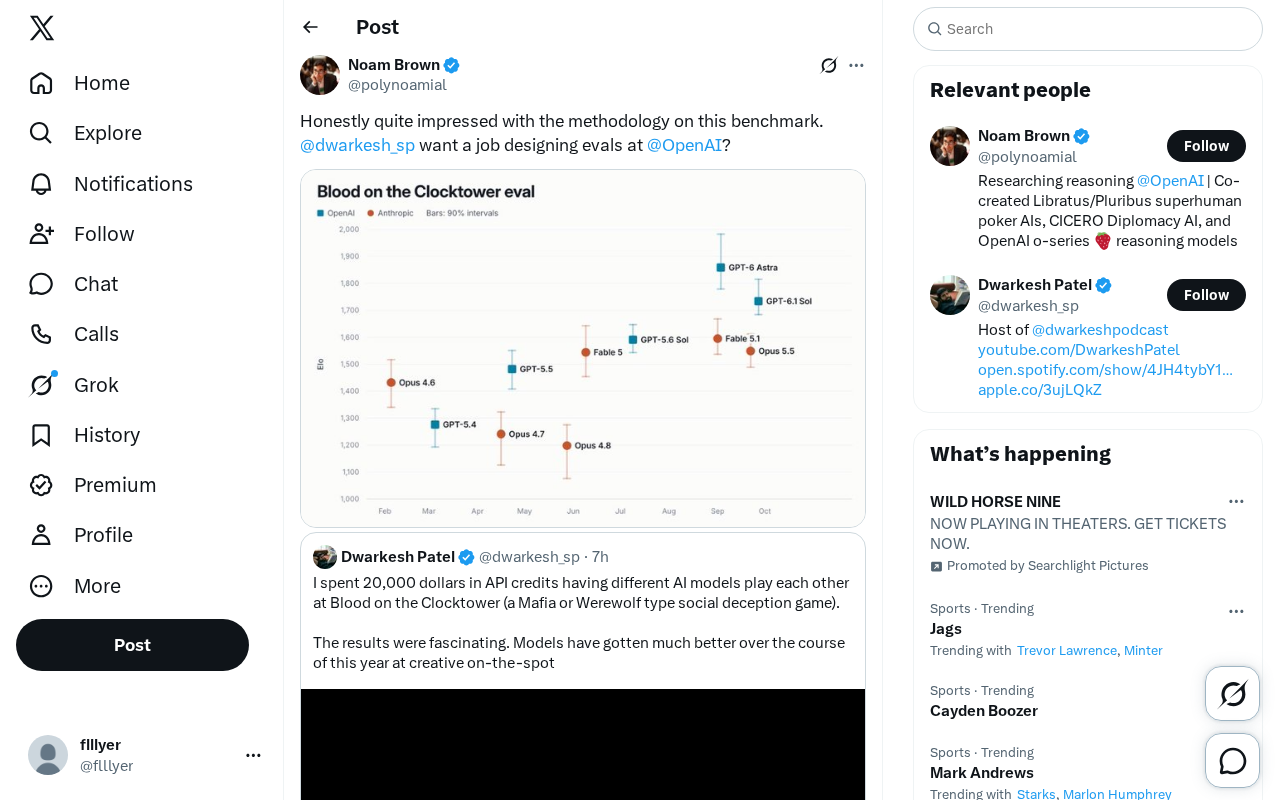
OpenAI Recruits Dwarkesh to Design Evals? Benchmark Methodology Sparks Discussion
OpenAI staff publicly praised a benchmark's methodology and invited Dwarkesh Patel to design evals. This article explains why eval design has become a key link in AI competition and a new path for talent mobility.

Anthropic IPO at $1.5 Trillion? Why Major Investors Are Skeptical
Anthropic's IPO is being discussed at a $1.5 trillion valuation, but major investors are skeptical. This article analyzes the gap between valuation and fundamentals, AI lab revenue-cost structures, and what public market pricing logic signals for AI companies.
Nasdaq Erases $2.5 Trillion: The 'Blue Wave' Triggers AI Panic
Nasdaq market cap evaporates $2.5 trillion as the 'blue wave' political shift sparks market panic over AI regulation and policy outlook. This article analyzes the policy expectation changes behind the sell-off, the fragility of the AI narrative, and implications for investors and practitioners.
Franklin Templeton Rebuilds Investment…
Franklin Templeton Rebuilds Investment Research Workflow with OpenAI
Franklin Templeton is developing AI workflows based on OpenAI technology, starting with equity research to help portfolio managers compare research views and examine investment risks. This article analyzes its workflow approach, risk review boundaries, and signal significance for the asset management industry.

EnvOpt: A New Direction for Agent Environment Optimization, Cutting Costs by 72.7%
EnvOpt proposes a third direction for agent optimization: automated optimization of static environments. On AutomationBench, it cuts costs by 72.7% and improves pass rate by 14.34%, transfers across models and harnesses, and requires no graders or reference answers.