All articles
39633 articles
Can the Skill Documents Hidden in LoRA Weights Be Read Back Out?
Research explores recovering skill documents from LoRA adapters: reading weights directly is nearly useless, but an executing writer recovers 39-44% of key instructions; behavioral adapters require reconstructing skills by comparing base and adapted model outputs, enabling cross-model transfer.
LEMMO: Leveraging Pretrained LLMs for Million-Scale Electromagnetic Signal Understanding
LEMMO is a large electromagnetic model for long raw IQ recordings, combining a linear-attention encoder with a pretrained LLM to process up to eight million complex samples, significantly outperforming MERLIN-LoRA on EM-Bench and LEMMO-ShortQA, with a 1.38TB open-source corpus.
Auditing LLM Annotation: Do Definitions, Label Names, or Demonstrations Drive Model Judgments?
A counterfactual audit shows LLM annotation accuracy may stem from label-name associations or demonstration proximity, not definition understanding. Fine-tuning reinforces original mappings, and retrieval gains mainly come from neighborhood labels.
RidgeFill: Training-Free Later-Layer Cache Filling, Up to 1.6x Prefill Speedup
RidgeFill proposes a training-free later-layer cache filling approach: closed-form ridge regression fits inter-layer mappings, skipping most later-layer prefill to achieve up to 1.6x first-token speedup in long-context scenarios, with honest accuracy costs on RULER and LongBench.

ENGRAM: A Verified Consolidation Framework for Baking Agent Experience into Weights
The ENGRAM framework consolidates agent experience into model weights, separating training from memory release via demonstration-aware admission and a verification gate, improving performance on interaction and reasoning benchmarks while compressing retrievable footprint and reducing token usage and model calls.

ROSE: Risk-Aware Orthogonal Subspace Navigation for Lifelong Knowledge Editing in Multimodal LLMs
ROSE uses risk-aware orthogonal subspace navigation to solve catastrophic forgetting and locality erosion in lifelong knowledge editing for multimodal LLMs, staying stable after 1,000+ sequential updates. Code is open-sourced.

MemoryDojo: A Benchmark for Memory Poisoning in LLM Agents
MemoryDojo is the first benchmark for memory poisoning in LLM agents across memory architectures, with 155 multi-session trajectories covering four domains and five memory systems. Evaluations show all memory systems are vulnerable, with significant differences in downstream impact, and propose memory-aware poisoning optimization.
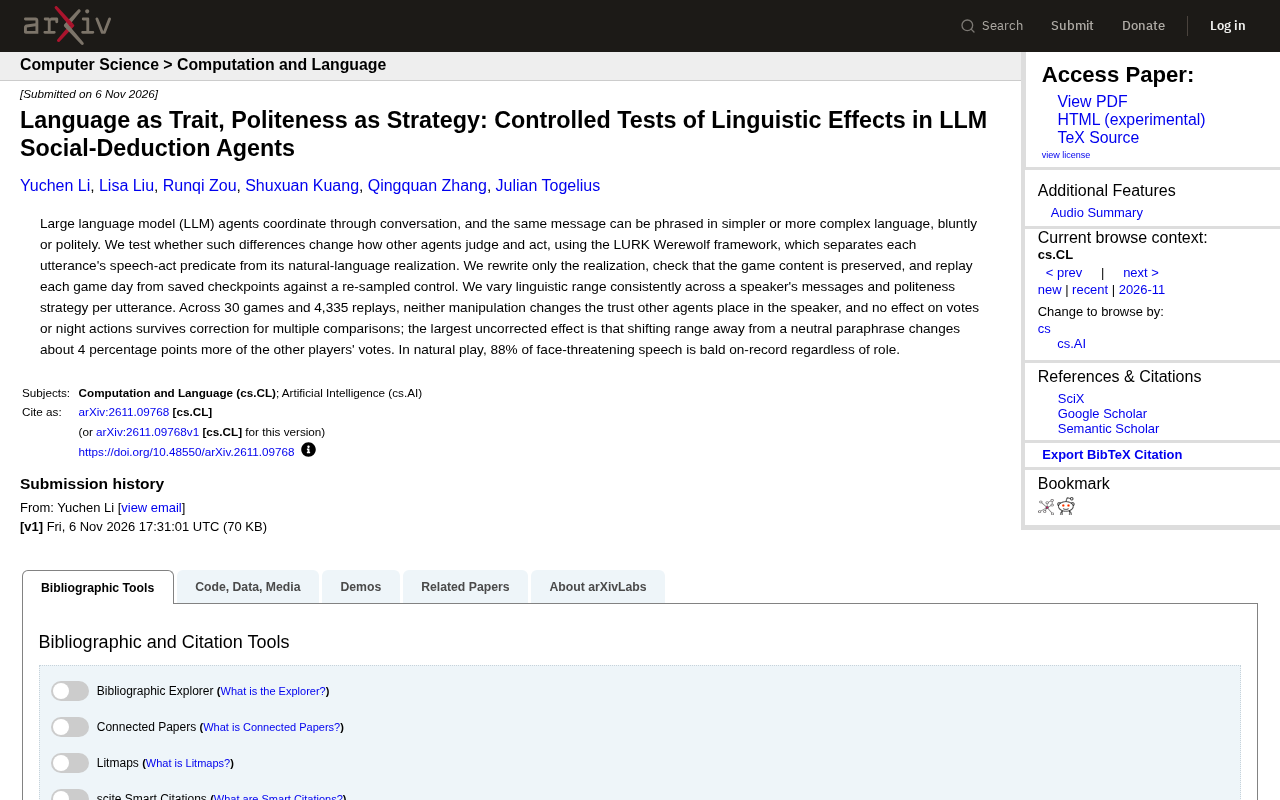
How Do Language Style and Politeness Strategies Affect LLM Social Reasoning? Controlled Experiments Reveal Limited Effects
A controlled experiment in the LURK Werewolf framework tests how language style and politeness strategies affect LLM social reasoning agents. Across 30 games and 4,335 replays, linguistic manipulation did not significantly change trust or behavior, with the largest uncorrected effect at only about 4 percentage points.
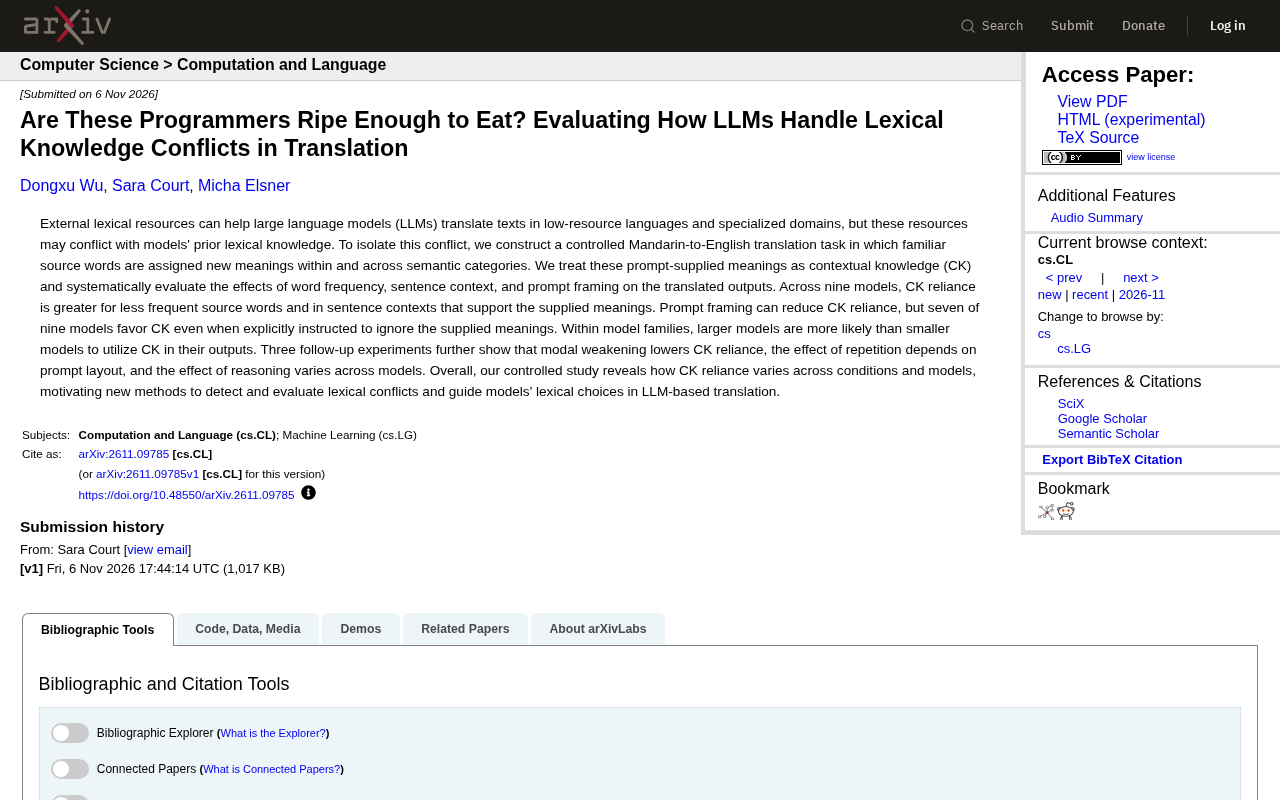
Lexical Conflicts in LLM Translation: Can Prompt Definitions Override a Model's Prior Knowledge?
A controlled Chinese-English translation study finds LLMs rely more on prompt-provided contextual knowledge (CK), especially for low-frequency words and supportive contexts; seven models still prioritize it even when told to ignore the definitions. Larger models use CK more, and prompt framing offers only partial mitigation.

BitDecoding-FP4: Algorithm-System Co-Design for Native FP4 KV Cache Decoding
BitDecoding-FP4 introduces an algorithm-system co-design with dual-residual query quantization, underflow-aware probability scaling, and outlier-aware key quantization, keeping FP4 KV decoding accuracy gaps within 0.5 points and achieving 2.4-3.0x throughput gains on NVIDIA B300.

A New Take on Conversational Memory: Paired Evaluation of Fact Compression and Retrieval Augmentation
A paired evaluation on the LoCoMo dataset compares retrieval-augmented generation and fact compression for conversational memory, finding compression wins on factual questions with fewer tokens but lags on adversarial questions requiring precise wording, revealing the boundaries of memory design choices.

Can a Hash-Only Sender Beat Classic Compression? A Pre-Registered Experiment Maps the Boundary
A pre-registered experiment compares a hash-only sender with a PPM compressor for short-text transmission. The hash sender costs 18.4 more bits per message and lags in airtime, yet has the lowest bit cost in a specific memory range. The study maps the boundary between sender memory and bits.
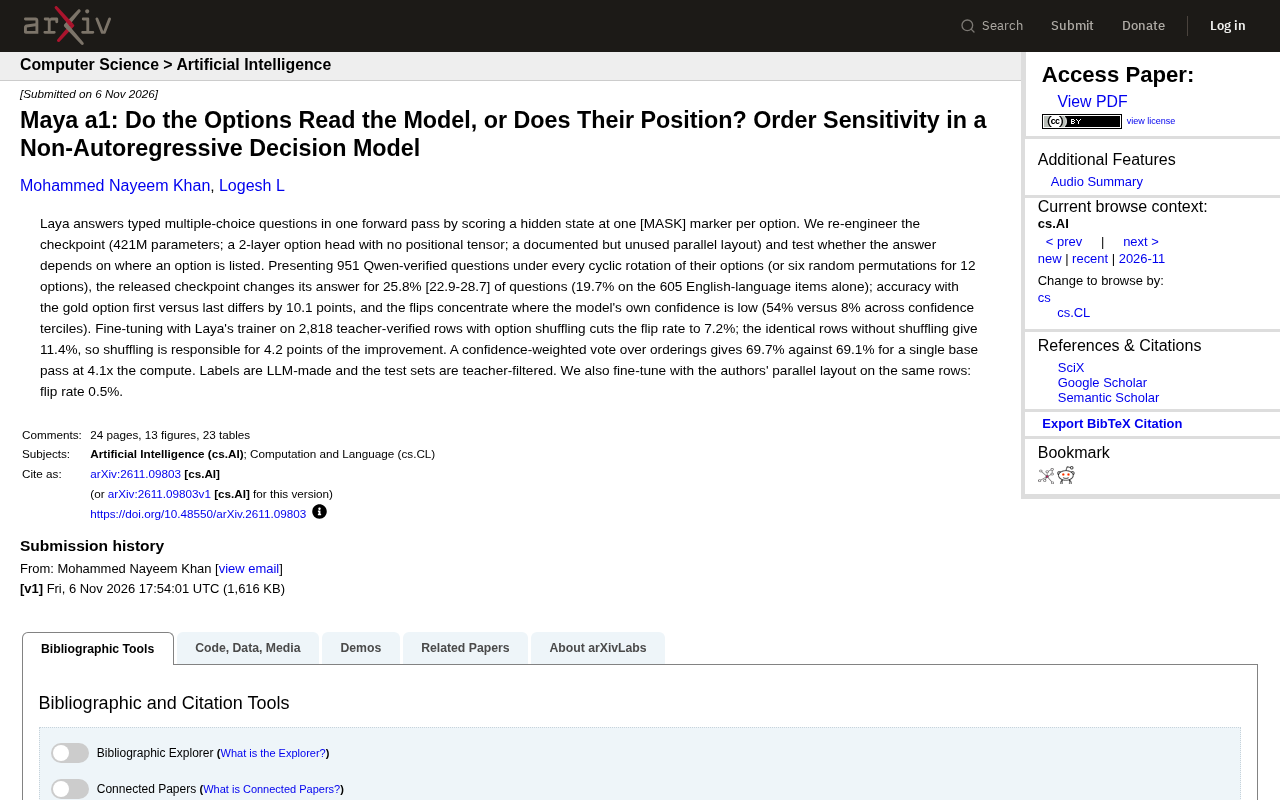
Maya a1 Option Order Sensitivity Study: The Hidden Bias of Non-Autoregressive Models
New research reveals that the Laya non-autoregressive model is highly sensitive to option order: 25.8% of answers change when options are rearranged, with a 10.1 percentage point accuracy gap between first and last positions. Fine-tuning with shuffling reduces the flip rate to 7.2%.
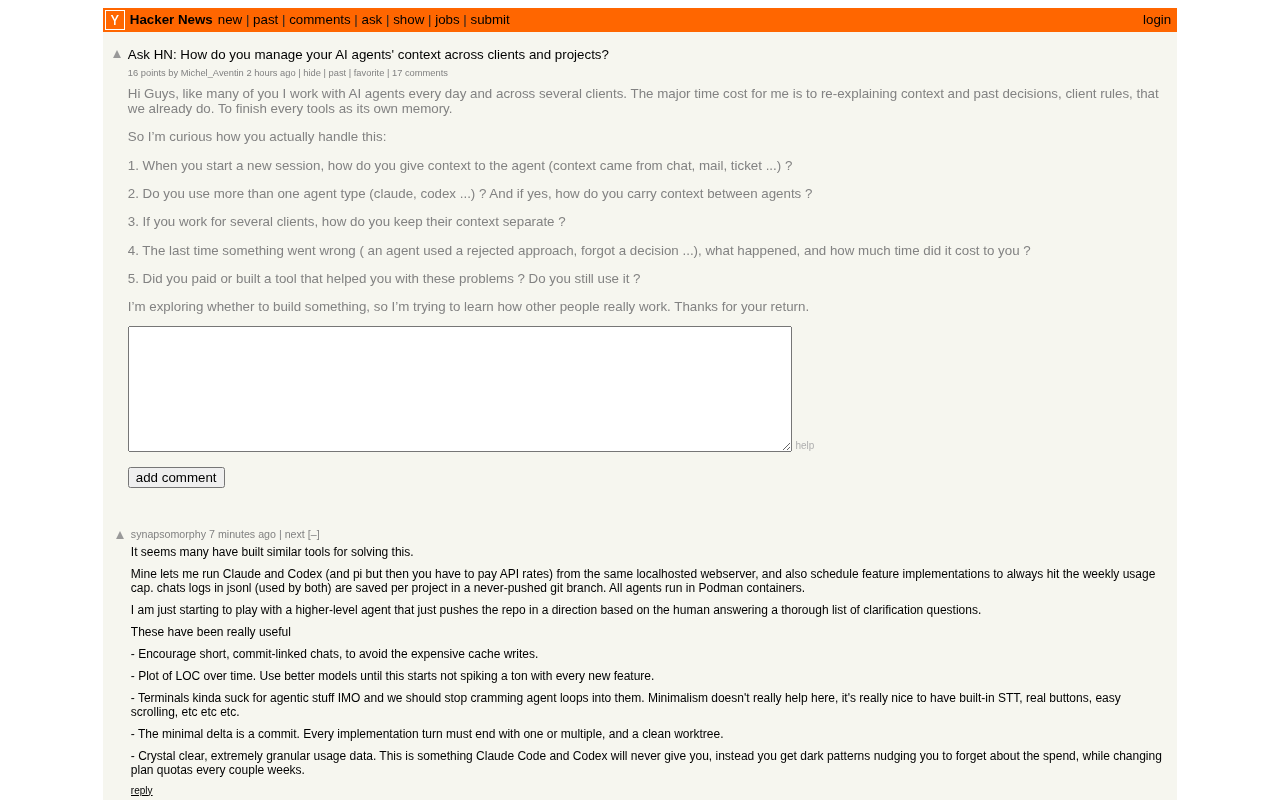
AI Agent Cross-Project Context Management: Practical Lessons from the HN Community
Hacker News community discusses AI agent context management across client projects, covering project isolation, dynamic injection, tool practices, and security considerations for developers.

CodeQuant2: A New Breakthrough in Low-Precision Quantization for Reasoning Models, Achieving Up to 2.85x Inference Speedup
CodeQuant2 is a clustering-based LUT quantization framework designed for low-precision large reasoning models. By suppressing outliers through rotation and scaling, adaptively sizing codebooks, and improving calibration strategies, it significantly boosts accuracy on reasoning benchmarks and achieves up to 2.85x speedup compared to BF16.
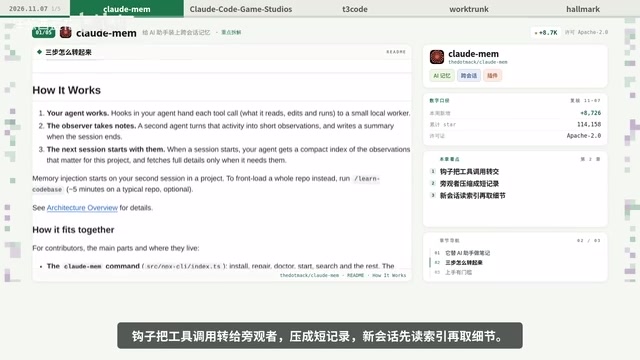
GitHub Weekly Highlights: Five High-Star Projects for Different Development Needs
This week's GitHub highlights: claude-mem memory plugin, Claude-Code-Game-Studios game studio template, t3code mobile remote control, worktrunk directory manager, and anti-AI-slop design standards—five high-star projects solving AI memory, multi-agent isolation, remote coding, and design verification, with cost analysis for each.

Training a PPO Agent for the Hidden-Information Card Game Cabo on a MacBook
A developer trained a self-play PPO agent for the hidden-information card game Cabo on a MacBook. The article covers training configuration, slot symmetry handling, emergent strategies, and plateau challenges.

Training PPO on a MacBook: A Browser-Based Cabo Card Game with Hidden Information
A Reddit developer trained a self-play PPO AI for the hidden-information card game Cabo on a MacBook and made it playable in the browser, offering insights for AI app development.
Jensen Huang's Internal Letter on Rumors: An Unpublicized PR Crisis?
A Hacker News post claims Nvidia CEO Jensen Huang sent staff a letter about an affair, but lacks the original text or official confirmation. This article examines the background, community discussion, and potential impact on investors and employees, urging caution with unverified information.
 Tech Frontiers
AI Agent Approval Workflows: Why Human Confirmations Always Get Mindlessly Clicked
Why do AI agent approval workflows always get mindlessly clicked? A Reddit discussion shows that separating rules from keys, low-frequency high-risk approvals, and GitHub Environments-style gates are the keys to effective approvals.