#Qwen
35 related articles
 Tutorials
oMLX + MTP + Qwen3.6: Local AI Coding Speed Breaks New Records
Using oMLX with MTP and Qwen3.6 35B on Apple Silicon Mac to achieve 86.7 tokens/s local coding speed, building a full-stack app in under 5 minutes.
 Product Reviews
Qwen 3.6 vs Gemma 4: In-Depth Comparison of Local AI Coding Models Through Real-World Development
Real-world comparison of Qwen 3.6 and Gemma 4 local AI models building a Markdown editor with Tauri, testing planning ability, code generation, and development efficiency.
 Tutorials
Qwen + VS Code in Practice: The Full Process of Using AI to Revamp a Webmaster Networking Platform
A blogger uses VS Code and Alibaba Cloud Qwen 3.6 to completely revamp a six-year-old webmaster networking feature. This article details the tech stack, prompt engineering, and practical insights from AI-powered feature renovation.
 Product Reviews
QwenCoder Local Deployment Review: Can It Replace Paid AI Coding Assistants?
Hands-on review of QwenCoder 80B deployed locally, compared to Gemini and Claude. Covers hardware setup, LM Studio deployment, and real coding test results to help you decide if local models can save on AI subscriptions.
 Product Reviews
DeepSeek V4 vs Qwen3.6 Real-World Testing: In-Depth Comparison Across 8 Categories and 150 Scenarios
BenchLocal real-world testing of DeepSeek V4 Pro, V4 Flash vs Qwen3.6 27B across 8 categories and 85 scenarios. V4 Pro leads by 6% but stumbles on math reasoning. Qwen3.6 Q6 rivals V4 Pro in agent tasks.
 Product Reviews
Qwen3.6-27B Open-Source Model Review: Flagship-Level Code and Multimodal Capabilities with Just 27B Parameters
Deep dive into Alibaba's Qwen3.6-27B: a 27B dense model delivering flagship-level code generation and multimodal capabilities on a single GPU with INT4 quantization.
 Product Reviews
Open-Source AI Desktop Pet Cat: Qwen 3.5 Omni + ESP32 Create a Full-Modal Intelligent Companion
Open-source AI desktop cat project built with Qwen 3.5 Omni and ESP32-S3, featuring emotional voice interaction, visual perception, gesture control, and daily life logging with intelligent review.
 Tutorials
Hermes + Qwen3.6 Local Deployment Tutorial: Build Your Private AI Agent at Zero Cost
Step-by-step tutorial to deploy Hermes Agent with Qwen3.6 open-source LLM locally. Covers WSL setup, model download, Telegram bot integration for a zero-cost private AI Agent.
 Product Reviews
Qwen3.6 27B: Real-World Testing of Three Unconventional Quantized Models — Code Performance +15.8PP, 40B Distillation, 16GB Adaptation
Real-world comparison of three community-built Qwen3.6 27B variants: OmniMerge V4 with +15.8pp code gains, 40B OPUS distilled for roleplay, and a 16GB-optimized version for limited VRAM.
 Product Reviews
Qwen 3.6 MTP Real-World Test: The Secret to a 20% Speed Boost with Just Three Parameters
Real-world test of Qwen 3.6 Multi-Token Prediction (MTP): boost inference speed from 34.2 to 41 tokens/s with just three parameters in ik_llama.cpp — zero quality loss, zero extra models.
 Tech Frontiers
Qwen Continues to Lead on SWE-bench: The Rise of Open-Source AI Coding Models
Qwen team leads open-source models on SWE-bench, demonstrating strong software engineering capabilities. This article analyzes SWE-bench standards, Qwen's progress, and the value of open-source AI coding tools.
 Tutorials
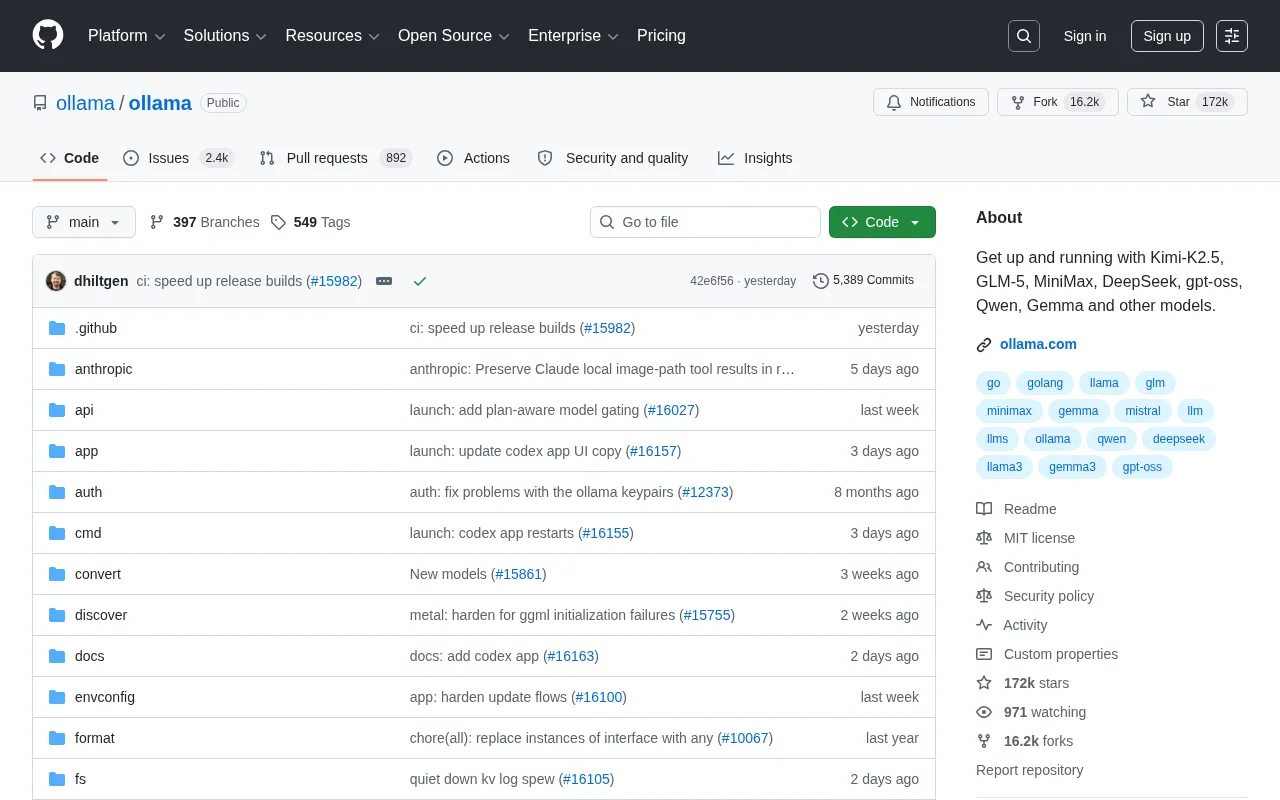
Ollama Tutorial: One-Click Local Deployment of DeepSeek, Qwen, and Other LLMs
Complete guide to running LLMs locally with Ollama. Supports DeepSeek, Qwen, Kimi-K2.5 & more. Covers installation, model ecosystem, privacy benefits & enterprise deployment. 170K+ GitHub Stars.
 Tutorials
Ollama Tutorial: Complete Guide to Running DeepSeek, Qwen, and Other LLMs Locally with One Click
Complete guide to Ollama: install and run DeepSeek, Qwen, Kimi-K2.5, GLM-5 and more LLMs locally. 170K+ GitHub Stars, the most popular local LLM framework for offline AI inference and privacy.
 Product Reviews
Ollama: The Ultimate Tool for Running Large Models Locally
Ollama is an open-source tool with 170K+ GitHub stars that lets you run LLMs like DeepSeek, Qwen, and Gemma locally with just a few commands.
 Tutorials
Ollama Tutorial: One-Click Local Deployment of DeepSeek and Other LLMs
Ollama is an open-source tool with 170K+ GitHub Stars for running DeepSeek, Qwen, Gemma and other LLMs locally. Learn installation, supported models, use cases and core advantages.