Deep Dives
In-depth AI analysis, industry observations, and technical insights — slow down and read.

Every Token Needs Its Own Teacher: A New Multi-Teacher Adaptive Self-Distillation Method
The paper proposes MTA-OPSD, the first token-level adaptive on-policy self-distillation method. A multi-teacher pool lets each token choose its own teacher, achieving up to +5.9 average gain on Qwen3 mathematical reasoning and outperforming existing OPSD methods.
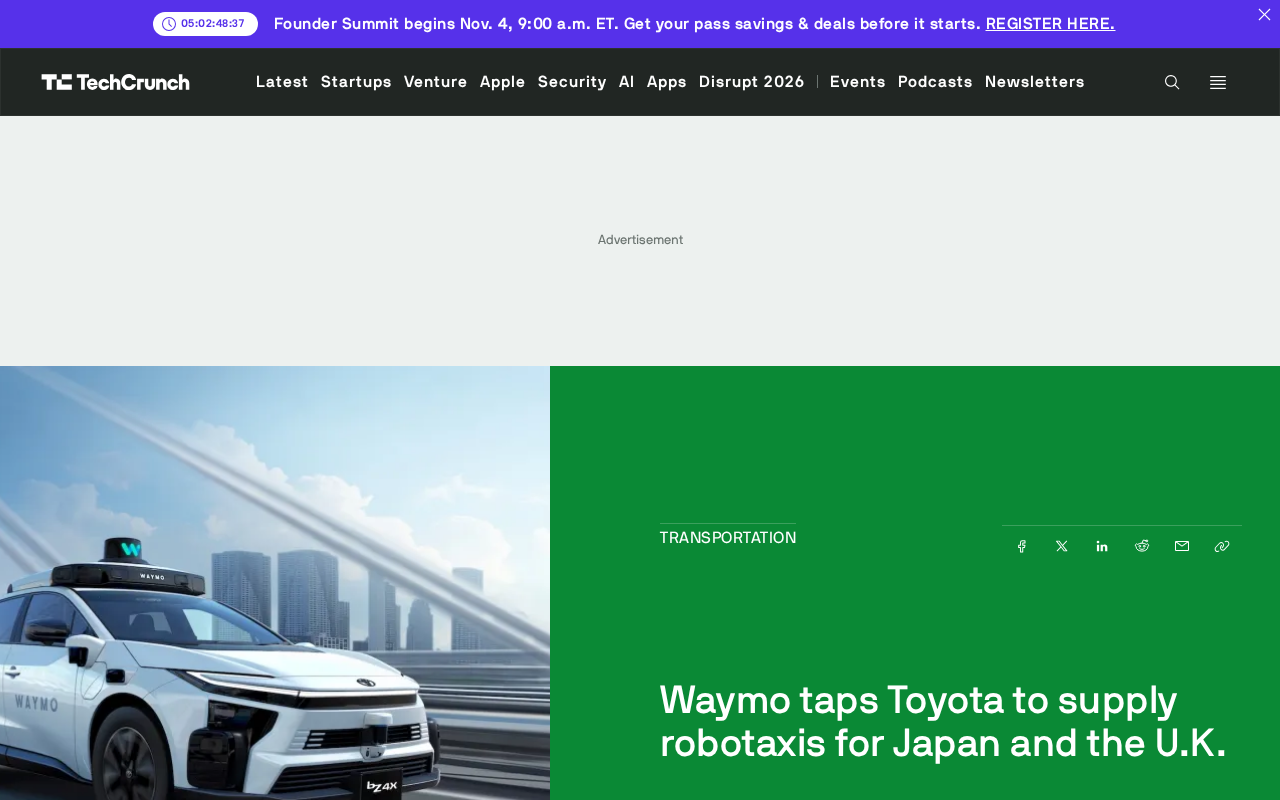
Waymo Teams Up with Toyota: Robotaxis to Launch in Japan and the UK
Waymo partners with Toyota to use the electric bZ4X for robotaxis, starting tests in Japan next year with plans to extend to the UK. Analysis of the model and impact.

Human vs. LLM-Simulated Clients: Comparing Dialogue Patterns in Online Counseling Training
A study compares dialogue patterns of human role-players versus Mixtral 8x7b simulated clients in online counseling training, analyzing at the sentence level whether LLMs can reproduce real conversational dynamics and how counselors' communication differs with humans versus AI, exploring the potential and limits of LLM role-play training.

GPT 6.2 Leak Rumors: Doubts About the Leaker's Credibility
A GPT 6.2 leak rumor is circulating on Reddit, claiming X leakers confirmed it and once predicted Gemini 4 Carbon. This article analyzes the rumor's source, the leaker's credibility, and the missing evidence chain, advising developers to follow official channels.
Why Are Brutalist Fast Food Restaurant Designs Sparking Debate?
Reddit's Brutalist fast food restaurant concept designs blending McDonald's, KFC with Brutalist architecture spark debate on cyberpunk, wasteland aesthetics, and consumer culture.
Switching from Cursor to Claude: A Developer's Hands-On Experience
A Reddit user shares their experience switching from Cursor to Claude, praising Claude with the Opus model and its longer 5-hour and weekly usage limits. This article analyzes the motivations behind developer migration and competition trends in AI coding tools.
64GB RAM + 16GB VRAM: Which Open-Source Models Have Fewer Restrictions?
Reddit user asks which open-source models with fewer restrictions suit 64GB RAM and 16GB VRAM. This article covers community-mentioned low-refusal fine-tuning directions like Mistral, Llama, Yi, Qwen, and analyzes the real risks and hardware bottlenecks of unaligned models to help you choose based on your use case.

Monocular Depth Estimation on Raspberry Pi 4: Is DINO + Depth Anything V2 Viable?
Analyzing the feasibility of DINO + Depth Anything V2 monocular ranging on a Raspberry Pi 4 for a vine-spraying robot, covering compute, accuracy, and real-time challenges, with alternatives like lightweighting, geometric priors, and low-cost active ranging.

The Reading Order Challenge in PDF Parsing: How the 1.3B Model OXR Breaks Through
SoMarkAI open-sources OXR, a 1.3B document parsing model that jointly predicts recognition and reading order, ranking first on olmOCR-Bench and solving sentence fragmentation from two-column PDF layouts. Includes code, weights, and a free test API.
Caphlon-Model: Pruning + Vocabulary Shrinking Packs a 27B Model into 8GB of RAM
Caphlon-Model compresses Qwen 3.8 27B into a 6.87 GiB GGUF file via vocabulary shrinking, layer pruning, and IQ2_S quantization, running on an 8GB RAM laptop with 96.7% HumanEval and 92.9% MMLU subset retention.

How to Get a Perplexity Invite Code? Reflections on a Reddit User's Plea
A Reddit user's plea for a Perplexity invite code reflects the referral mechanism and community code-begging culture of AI search products. This article analyzes why Perplexity Pro invite codes are popular, the Reddit code-seeking ecosystem, and practical tips for legally getting Pro access.
Reddit Users Confused: Is It a Free Year Extension or Just a Student Discount?
Reddit users question whether an offer is a free year extension or a student discount, sparking community discussion. This article analyzes the causes of promotional ambiguity and user response strategies.

The End of Free Cloud Models: Pay-as-You-Go Starts November 9
A platform announces that Free plan accounts will automatically switch to pay-as-you-go starting November 9, 2026, with gemma4:31b, gpt-oss, and nemotron series requiring credits, while local execution remains free.
Seven Key Questions Startups Must Consider Before Launching an AI Product
What should startups consider before launching an AI product? Based on a Reddit discussion, this article covers seven key decision points: problem validation, data availability, model choice, development and operating costs, infrastructure, security, and MVP validation.

Ollama Finishes Thinking But Doesn't Output an Answer? Causes and Solutions
Ollama runs Qwen 3.5 9B: thinking ends but no answer? This article analyzes this typical Reddit user issue, offering troubleshooting ideas and solutions from model templates, stop words, and generation parameters to help local deployment users pinpoint output truncation problems with thinking models.

Stop Using Giant Questions: Break Down Problems and Ask Follow-Ups for Better Results
A Reddit user shares: breaking a big question into smaller follow-ups yields more focused answers with more relevant sources than one giant query. This article analyzes the traps of giant queries, the advantages of decomposition, and an actionable workflow.

Fabricated Data in an Accepted AAAI Paper Sparks Doubts About Academic Review
A Reddit tip alleges a friend fabricated data to get a paper into AAAI, sparking debate on peer review blind spots and distorted academic incentives. This article analyzes why fabrication is hard to detect and the trust crisis facing academic evaluation.

Mistral's New Open-Weight Models and Highlights from the AI Coding Agent Conference
Mistral releases open-weight models, and the AIE CODE coding agent conference focuses on engineering implementation. This article covers what open-weight models mean for AI coding, frontier monitoring, and the day's community discussions.

3B Activated Model Sterling Beats Claude: 11x Cost Reduction for Financial Research Agents
Samaya AI releases Sterling, a finance research model built on Nemotron 3.5 Lightning with ~3B active parameters, scoring 58.9% on FrontierFinance vs Claude Fable 5.1's 55.9% at $0.61/question—about 1/11 the cost.

Burnout in the AI Era: Collective Exhaustion Beneath the Tech Feast
A Hacker News post "Are you tired too in this AI era?" resonates widely. This article analyzes the sources of collective burnout among tech professionals—information overload, tool adoption pressure, and value uncertainty—and explores how to maintain a sustainable pace amid rapid change.