All articles
38460 articles
 Tech Frontiers
Qwen3.6 35B Open-Source Model Approaches Claude in Tests, xAI Voice Cloning API Officially Launches
Alibaba open-sources Qwen3.6 35B with 256-expert MoE architecture needing only 3B active params, scoring 73.4% on SWE-Bench near Claude Opus. xAI launches Voice Cloning API supporting 28 languages.
 Tutorials
Hermes + Qwen3.6 Local Deployment Tutorial: Build Your Private AI Agent at Zero Cost
Step-by-step tutorial to deploy Hermes Agent with Qwen3.6 open-source LLM locally. Covers WSL setup, model download, Telegram bot integration for a zero-cost private AI Agent.
 Product Reviews
Qwen3.6 27B: Real-World Testing of Three Unconventional Quantized Models — Code Performance +15.8PP, 40B Distillation, 16GB Adaptation
Real-world comparison of three community-built Qwen3.6 27B variants: OmniMerge V4 with +15.8pp code gains, 40B OPUS distilled for roleplay, and a 16GB-optimized version for limited VRAM.
 Tutorials
vLLM and SGLang Local Deployment Tutorial: A Practical Guide to 3-8x Performance Gains
Complete guide to deploying vLLM and SGLang locally. Compare performance vs LM Studio, deploy in 3 steps with Docker + AI assistant. Covers SGLang vs vLLM selection, 5090 VRAM optimization, and Cherry Studio integration.
 Research
PhyAR from Shanghai Jiao Tong University: Solving the Semantic Prior Hijacking Problem in Video-LLM Physical Reasoning
Shanghai Jiao Tong University proposes PhyAR with PACC dataset and VARC mechanism to fix Video-LLMs' inability to detect physical anomalies due to semantic prior hijacking.
 Tech Frontiers
Wukong 2.2P Open Source: 35B MOE Model Outperforms Qwen3.6-27B at 3–5x the Speed
Wukong 2.2P 35B MOE model is now open source. Using adversarial hybrid distillation, it outperforms Qwen3.6-27B. Runs at 158 tokens/s on RTX 4090 with only 8.9GB VRAM. Supports 256K context.
 Tech Frontiers
Qwen3.6 MTP Acceleration Benchmarked: Single GPU Inference Hits 220 token/s
Qwen3.6 experimental MTP-GGUF benchmarked: single GPU pushes 35B-A3B model to 220 token/s, 1.4x faster with zero accuracy loss. Covers MTP principles, optimal Draft Tokens strategy, and RTX 5090 results.
 Industry Insights
Enterprise LLM Selection Guide: In-Depth Comparison of Llama 3.1, Qwen 2.5, and DeepSeek
How should enterprises choose open-source LLMs? This guide compares Llama 3.1, Qwen 2.5, DeepSeek, and Mistral across model capabilities, hardware requirements, and business scenarios.
 Deep Dives
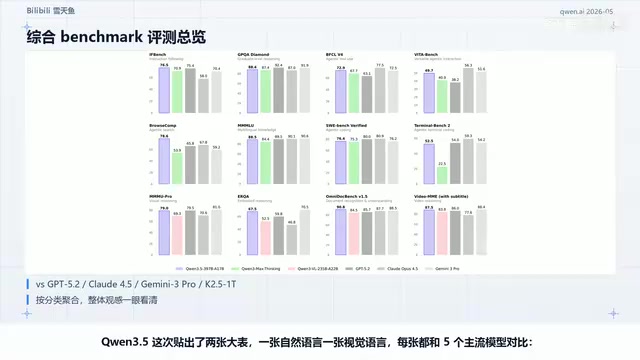
Qwen3.5 Deep Dive: Hybrid Attention Architecture Achieves 19x Speedup for Long Context
Deep analysis of Alibaba's open-source Qwen3.5 hybrid attention architecture, how Gated Delta Net achieves 19x speedup at 256K context, and multimodal results surpassing Gemini 3 Pro and GPT-5.2.
 Product Reviews
Qwen 3.6 MTP Real-World Test: The Secret to a 20% Speed Boost with Just Three Parameters
Real-world test of Qwen 3.6 Multi-Token Prediction (MTP): boost inference speed from 34.2 to 41 tokens/s with just three parameters in ik_llama.cpp — zero quality loss, zero extra models.
 Product Reviews
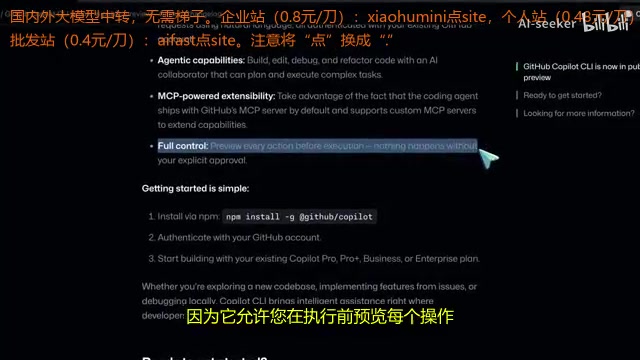
GitHub Copilot CLI In-Depth Review: A Free Terminal Coding Agent Powered by Claude Sonnet
In-depth review of GitHub Copilot CLI public preview: a free terminal coding agent powered by Claude Sonnet with no rate limits, tested against Claude Code across four real coding tasks.
 Tech Frontiers
GitHub Universe 2024: Full Breakdown of Copilot Multi-Model Support, Multi-File Editing & Spark
Deep dive into GitHub Universe 2024: Copilot adds Claude 3.5 Sonnet, Gemini multi-model support, VS Code multi-file editing rivaling Cursor, and the new AI micro-app tool Spark launches.
 Industry Insights
The Truth About Data Center Water Usage: Real Data from Abilene, a Small West Texas City
How much water do data centers really use? Real data from Abilene, TX shows annual data center water usage is less than one day of local residential use. A rational analysis of AI data centers' true environmental costs.
 Tutorials
GitHub Copilot CLI Hands-On Tutorial: Complete Guide from Installation to Auto-Creating PRs
Complete guide to GitHub Copilot CLI: installation, MCP extensions, and Agentic Coding demo building a Windows 95 simulator with auto GitHub repo creation and PR workflow.
 Product Reviews
GitHub Copilot CLI Hands-On Review: A Terminal AI Coding Tool Put to the Test
Hands-on review of GitHub Copilot CLI public preview: installation, MCP server extensions, deep GitHub integration, and a comparison with Claude Code to help you decide if it's worth switching.
 Deep Dives
Does Claude Code Save Your Code? A Complete Privacy Policy Breakdown
Deep dive into Claude Code's privacy policy: data storage duration, model training usage, comparison with Cursor and GitHub Copilot, plus practical privacy tips for developers.
 Tutorials
Getting Started with AI Programming: A Practical Guide to Copilot Setup, Configuration, and Model Selection
A comprehensive guide covering AI programming tool selection, GitHub Copilot installation and configuration, Premium Request mechanics, AI model comparison, and extending models via Open Router.
 Tutorials
Free Claude Code: Tutorial on Using Opus Model for Free via GitHub Student Verification
Learn how to get free Claude Opus access in Claude Code via GitHub Student verification and AnyGuardianManager proxy, with full setup steps and caveats.
 Tutorials
GitHub Agent HQ: A Practical Guide to Multi-AI Agent Parallel Collaborative Development
Learn how GitHub Agent HQ orchestrates Copilot, Claude, Codex and other AI coding agents in parallel, covering Issue automation, VS Code integration, and mobile management.
 Product Reviews
Spending $300/Month on 4 AI Tools — An Honest Experience Report
In-depth review of 4 AI subscriptions totaling ~$300/month: GitHub Copilot Pro Plus, Perplexity Max, Grok, and Gemini covering coding, search, analysis, and knowledge management.