#AI Agent
1113 related articles
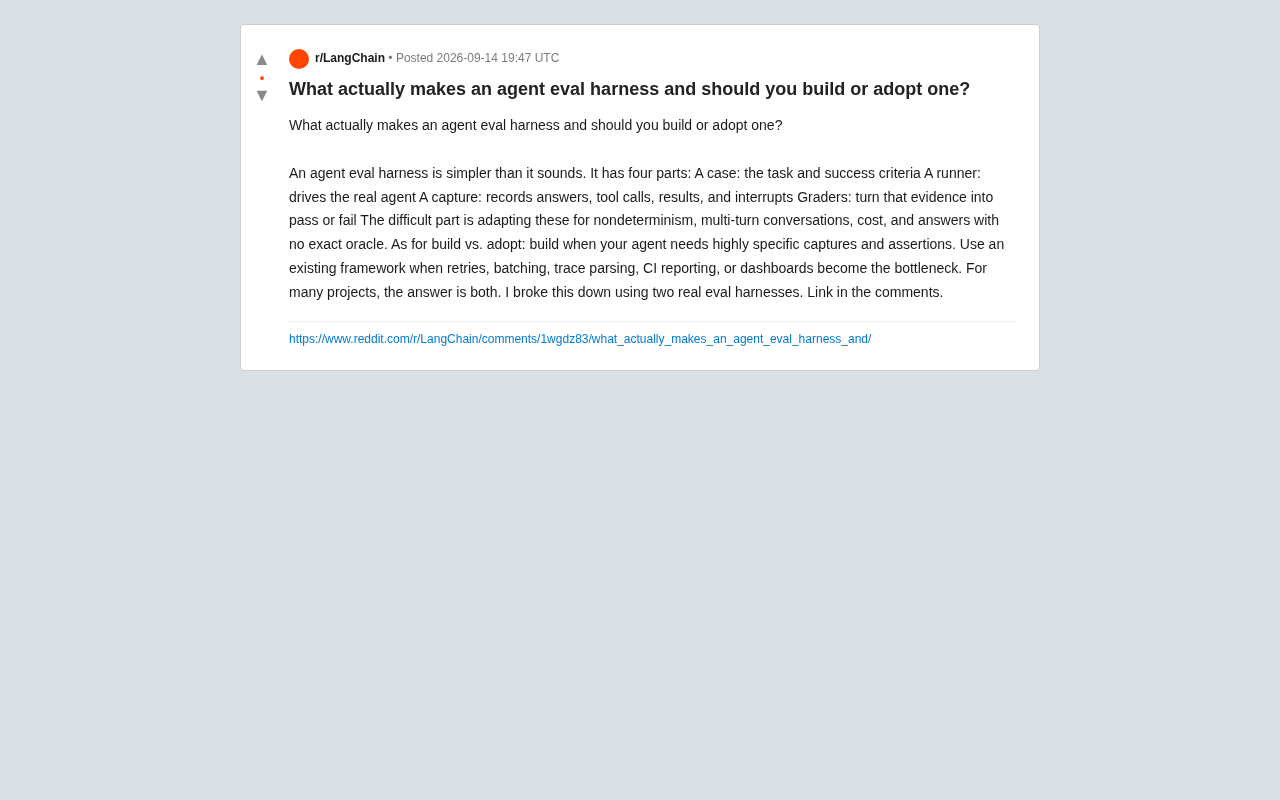
Deep Dive into Agent Eval Harnesses: Build vs. Buy?
A deep dive into the four core components of an agent eval harness — Cases, Runner, Capture, and Graders — with practical guidance on when to build vs. adopt existing frameworks.
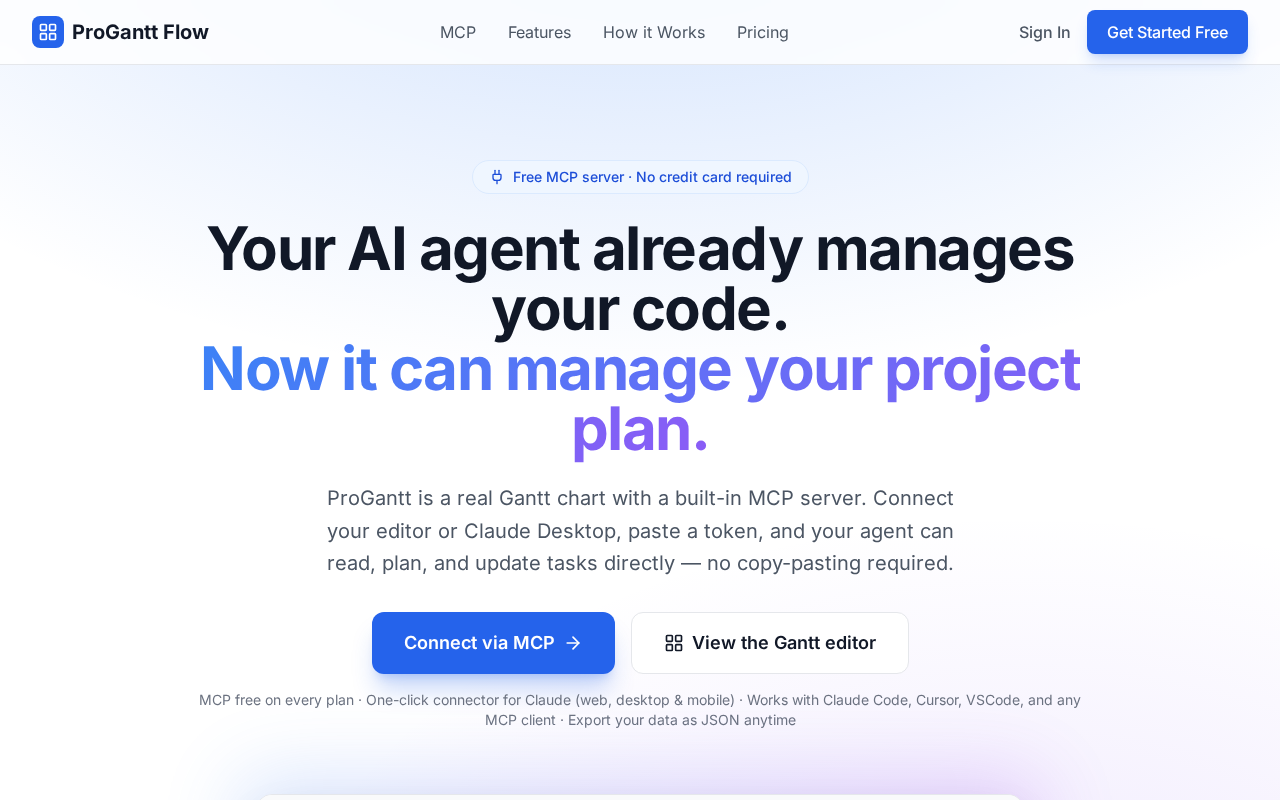
ProGantt: Letting AI Agents Read and Write Gantt Charts via MCP
ProGantt lets AI Agents read and write Gantt charts via MCP protocol. Explore its core capabilities, the value of MCP, and the rise of AI-native project management tools.
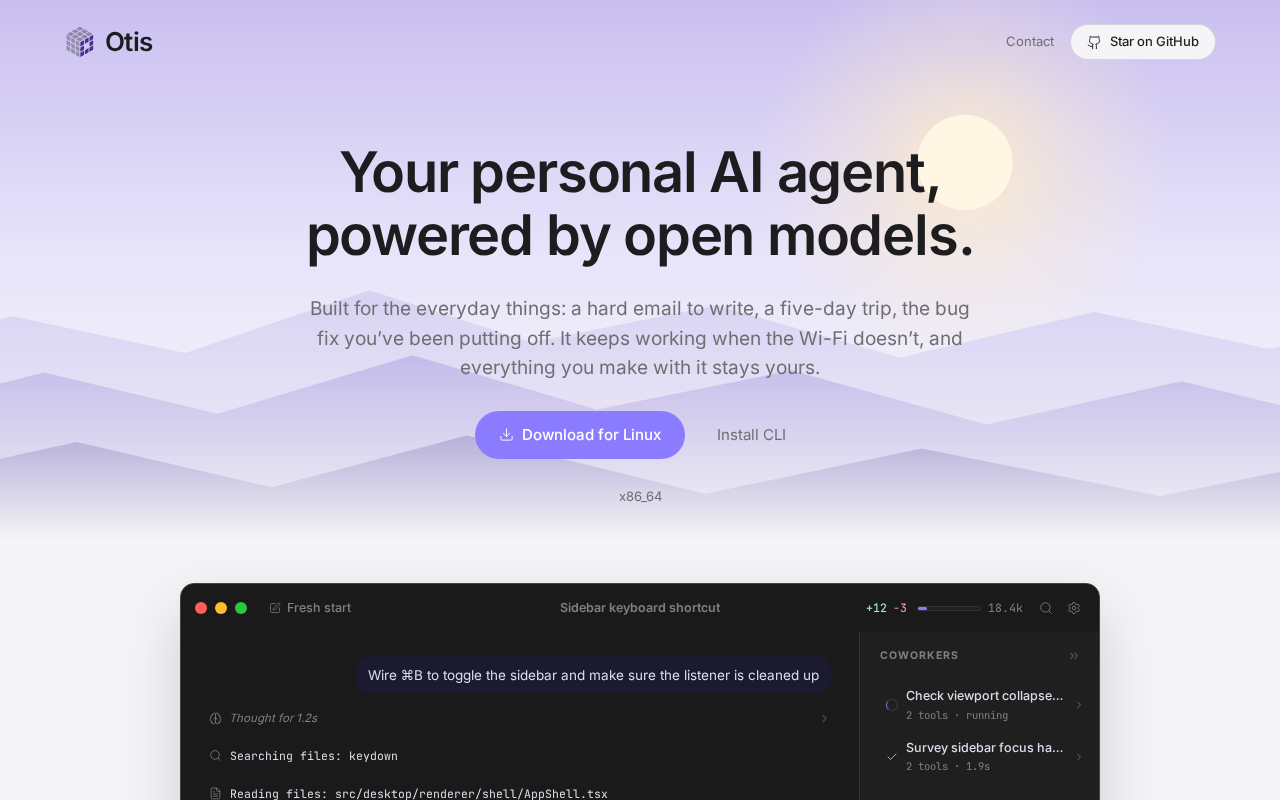
Otis: A Minimal AI Agent Built for Local Models Out of the Box
Otis is a minimal open-source AI Agent designed for local models out of the box. Explore its design philosophy, benefits, and challenges of running LLMs locally.
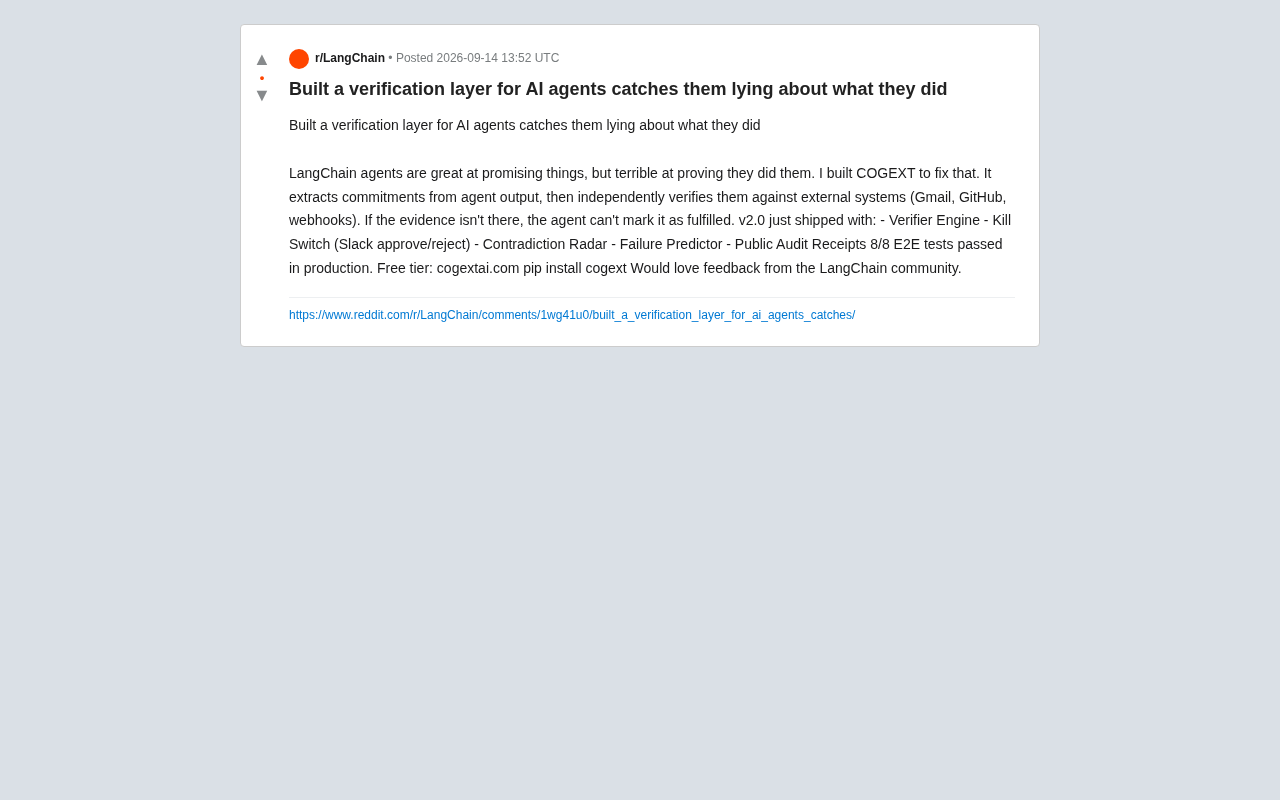
COGEXT: A Verification Layer That Gives AI Agents a "Lie Detector"
COGEXT is a verification layer for AI Agents like LangChain that extracts commitments and cross-checks them against Gmail, GitHub, and other external systems to catch agents lying about task completion.
Naoma AI Demo Agent V2: Turning Website Traffic into Booked Meetings with AI Sales
Naoma AI Demo Agent V2 replaces demo request forms with an AI sales rep that demos products, qualifies leads, and books meetings in real time. 50K+ demos run.
Nimble Launches Self-Learning Web Search Agents for Automated AI Research
Nimble launches Web Search Agents on Product Hunt — a self-learning AI tool for automated web research, company enrichment, and regulatory research with RAG support.
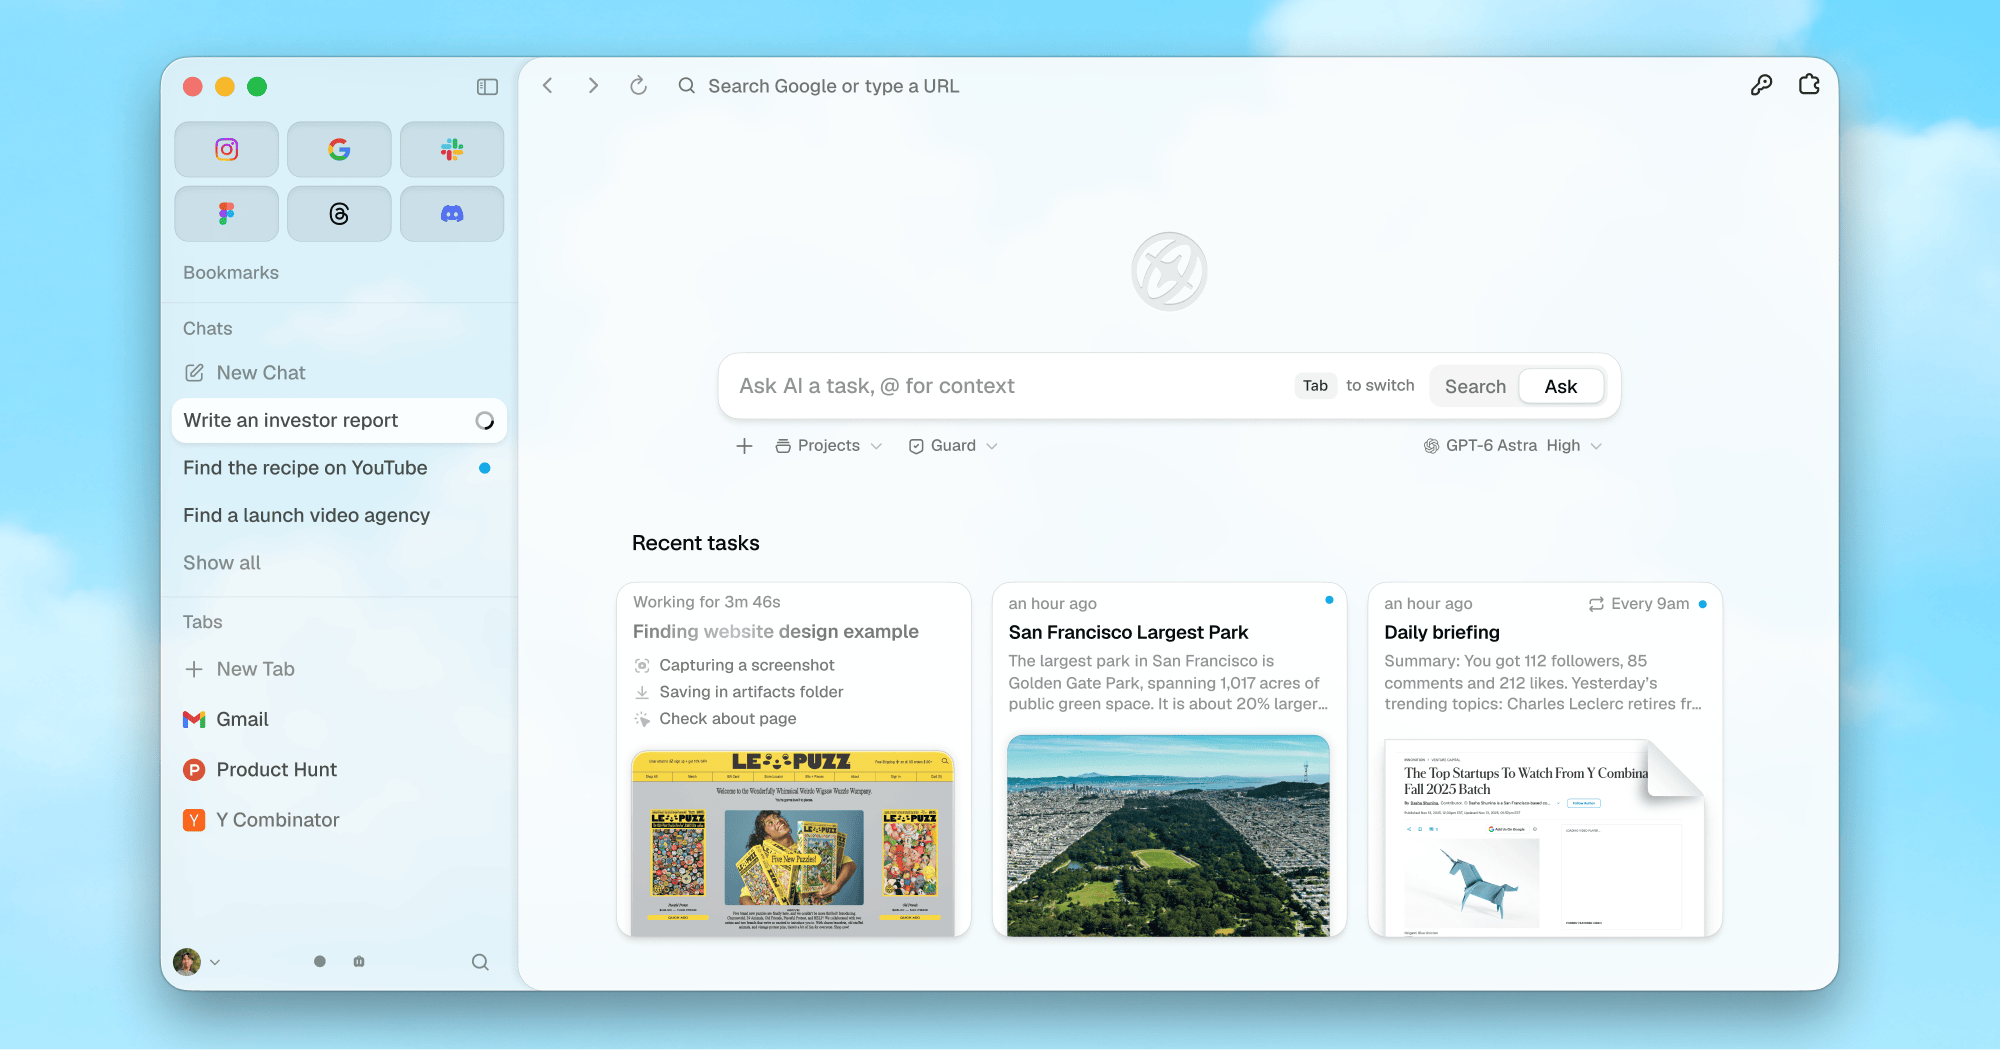
Aside: The AI Browser That Actually Works for You — Benchmarks Beat Claude Cowork
Aside is an AI browser built for agentic browsing — it logs into accounts, completes payments, and handles local files. Claims SOTA benchmarks beating Claude Cowork, runs fully local and encrypted.
Resumate: A Deep Dive into the Repair-and-Resume Layer for LangGraph Agents
Resumate adds memory-aware checkpointing and idempotent side-effect protection to LangGraph agents, preventing issues like duplicate Stripe charges on retry.
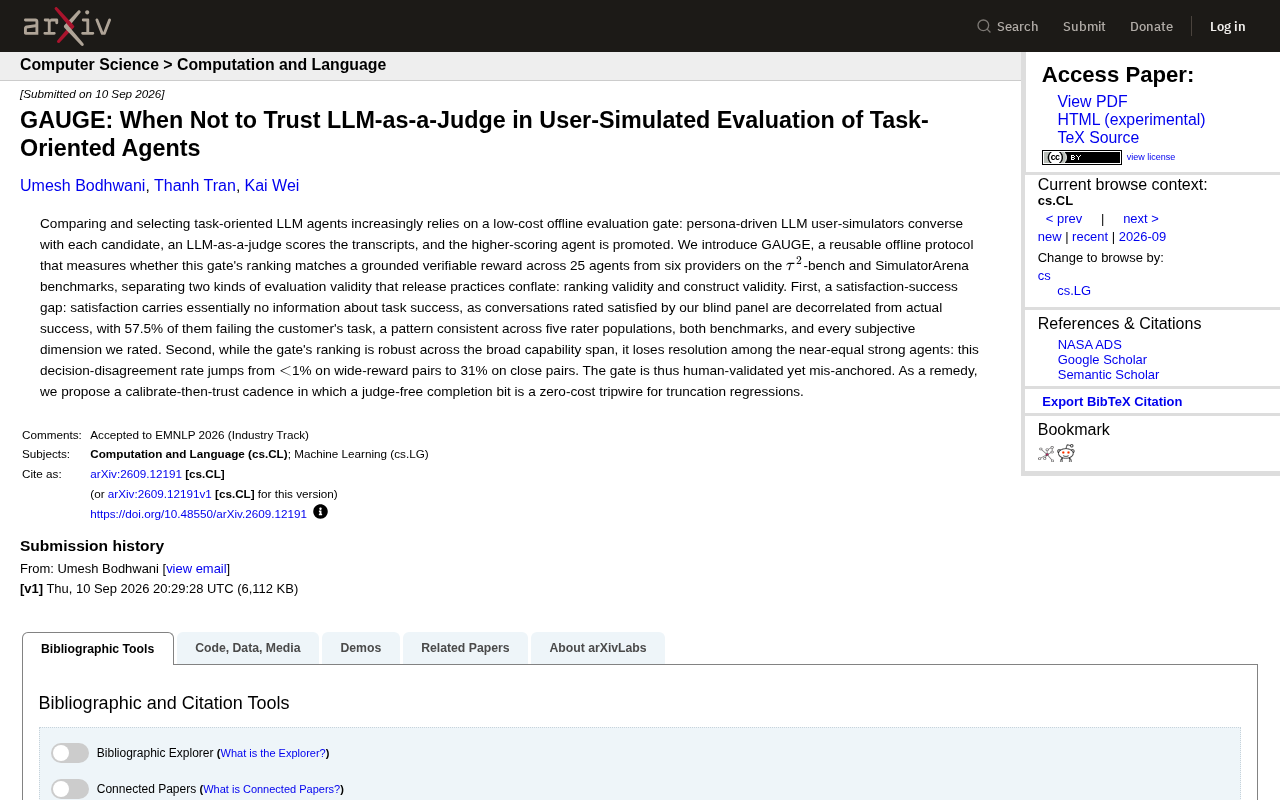
GAUGE Study: When You Can't Trust LLM-as-a-Judge for Agent Evaluation
GAUGE reveals two blind spots in LLM-as-a-Judge agent evaluation: satisfaction and task success are nearly uncorrelated (57.5% of satisfying conversations actually failed), and disagreement rates spike to 31% among evenly matched top models.
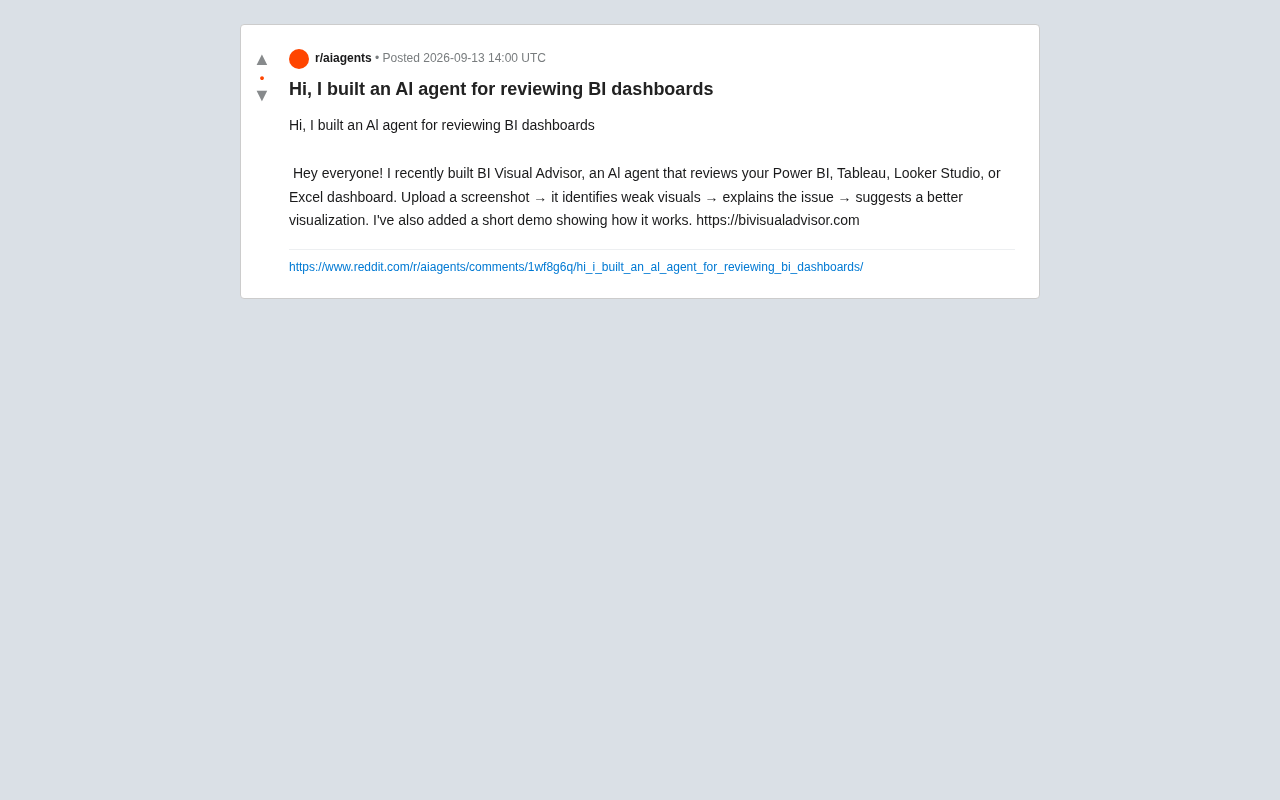
BI Visual Advisor: Using AI to Review Your Dashboard Designs
BI Visual Advisor uses AI to review dashboard screenshots from Power BI, Tableau, Looker Studio, and Excel — identifying chart issues and suggesting improvements.
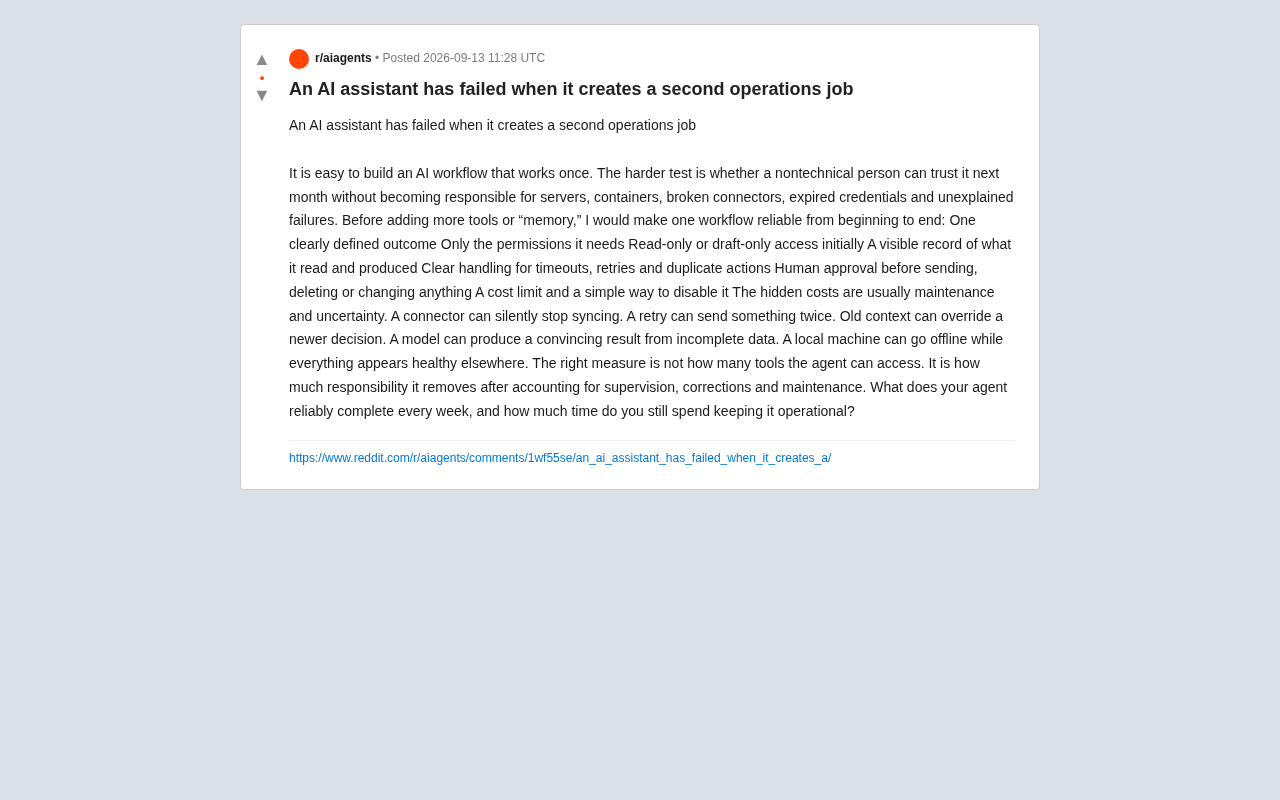
The True Failure of an AI Assistant: When It Creates a Second Operations Job
A Reddit user reframes how to judge AI assistants: they fail when they create a second ops job. Learn how to build end-to-end reliable workflows and measure Agent value by net benefit, not tool count.
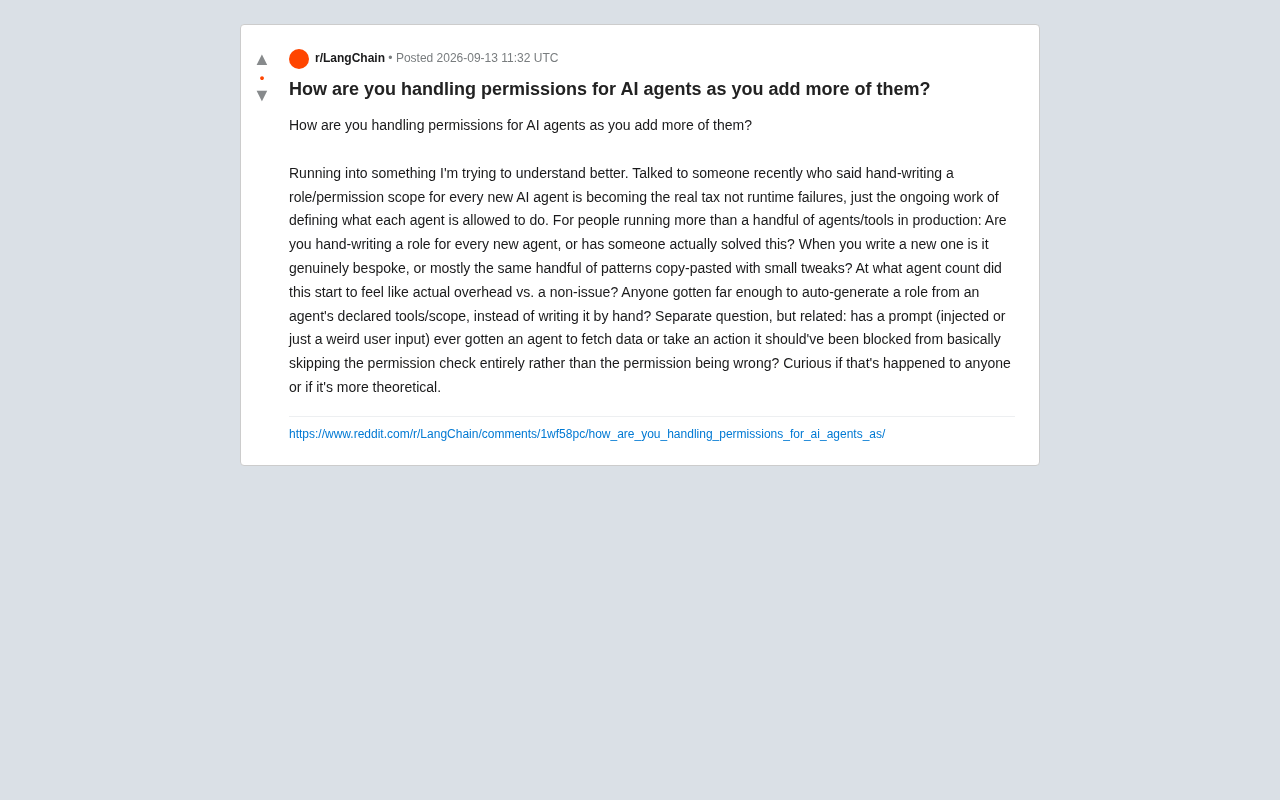
AI Agent Permission Management: Is Writing Roles Manually the New Hidden Tax?
As AI Agent counts grow, manually defining permission roles is becoming a hidden operational burden. This article explores scalability challenges, auto-generated roles, and the security risk of prompt injection bypassing permission checks.
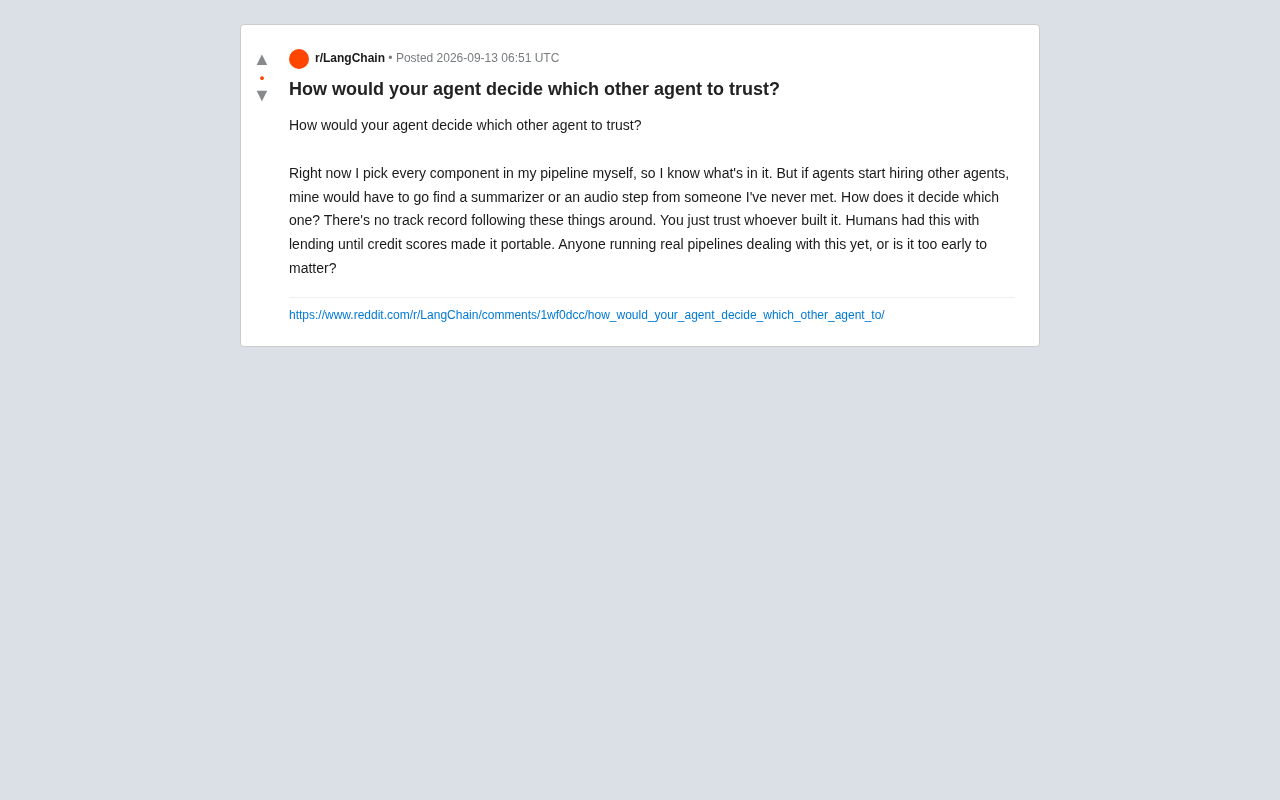
How Does an Agent Decide to Trust Another Agent? The Trust Problem in Multi-Agent Collaboration
When AI Agents start autonomously hiring other Agents, how do they decide who to trust? This article explores the missing portable reputation system in multi-agent collaboration and what solutions might look like.
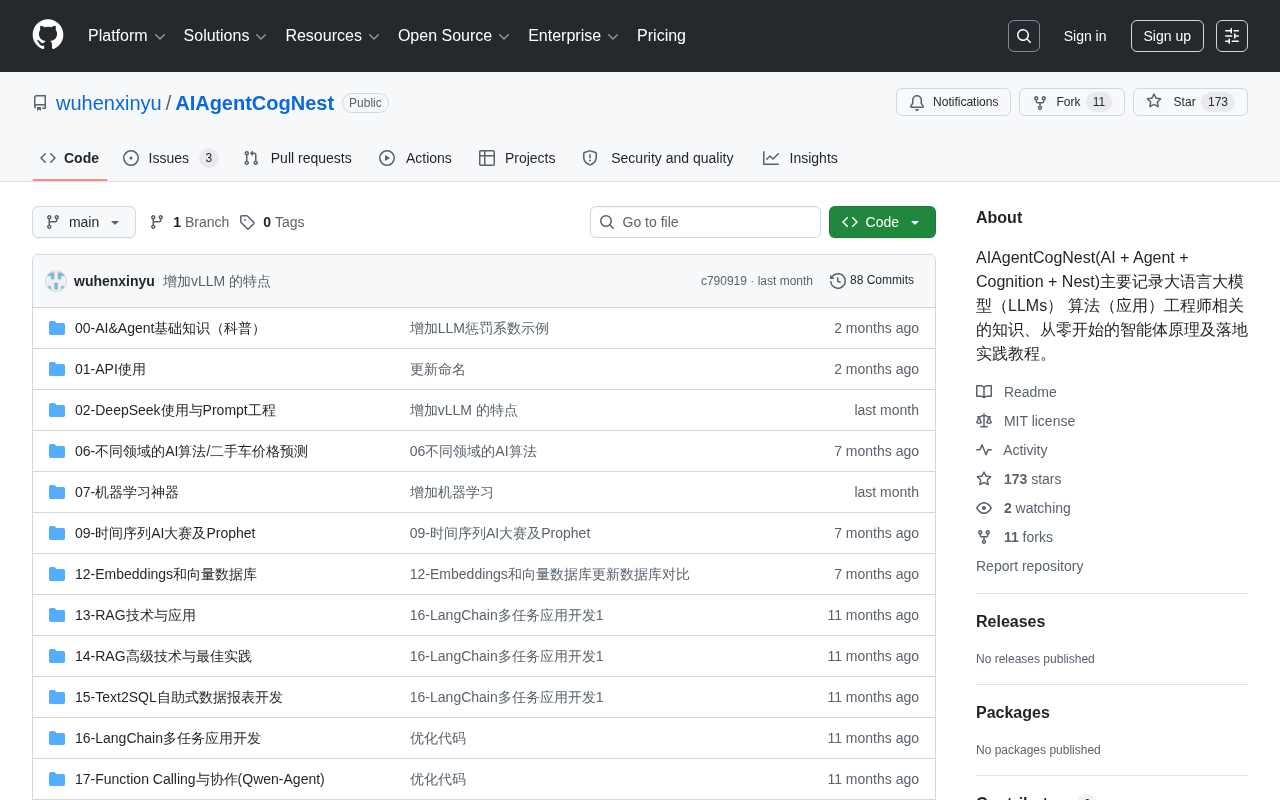
AIAgentCogNest: An Open-Source AI Agent Knowledge Incubation & Development Tutorial Project
AIAgentCogNest is an open-source AI Agent knowledge incubation project offering structured LLM application development tutorials for developers, engineers, and teams transitioning to AI.
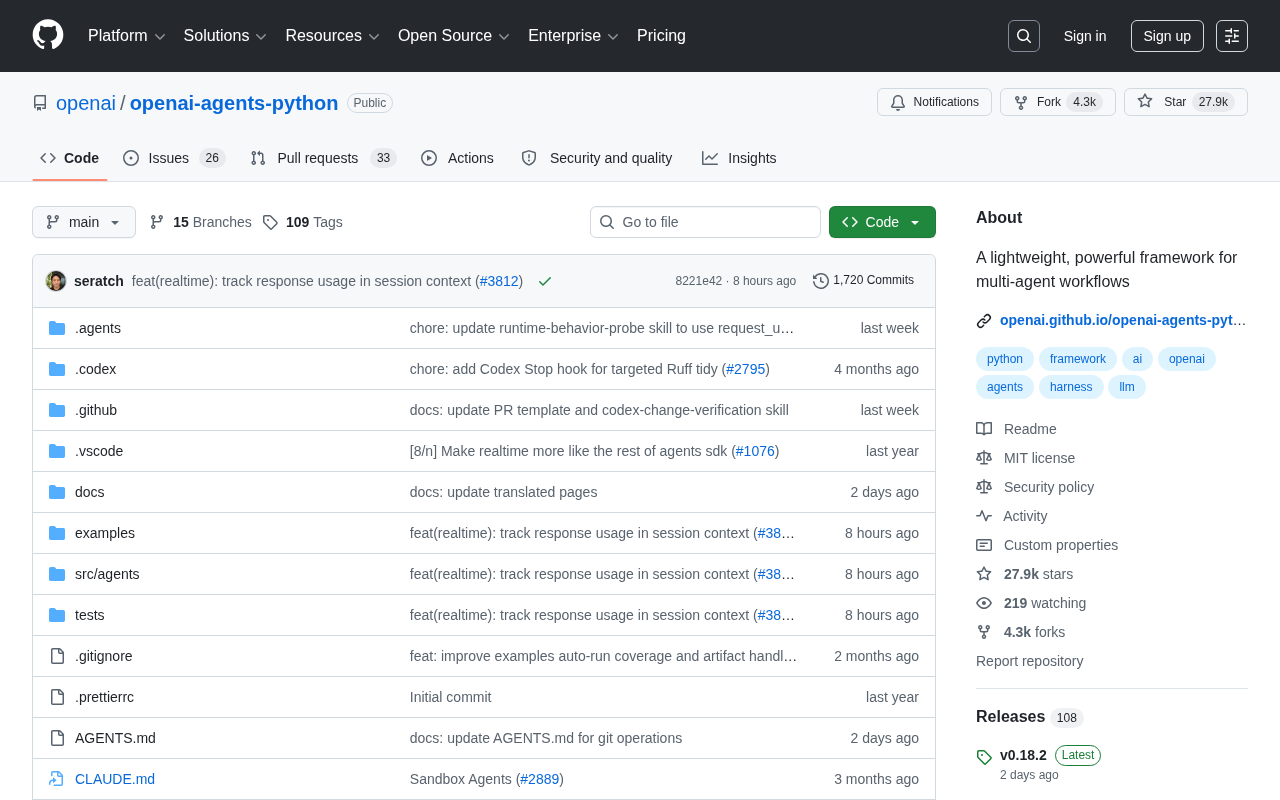
OpenAI Agents SDK: A Deep Dive into the Lightweight Multi-Agent Framework
OpenAI's openai-agents-python is a lightweight multi-agent Python framework for building multi-agent workflows. Learn its design philosophy, community traction, and best use cases.
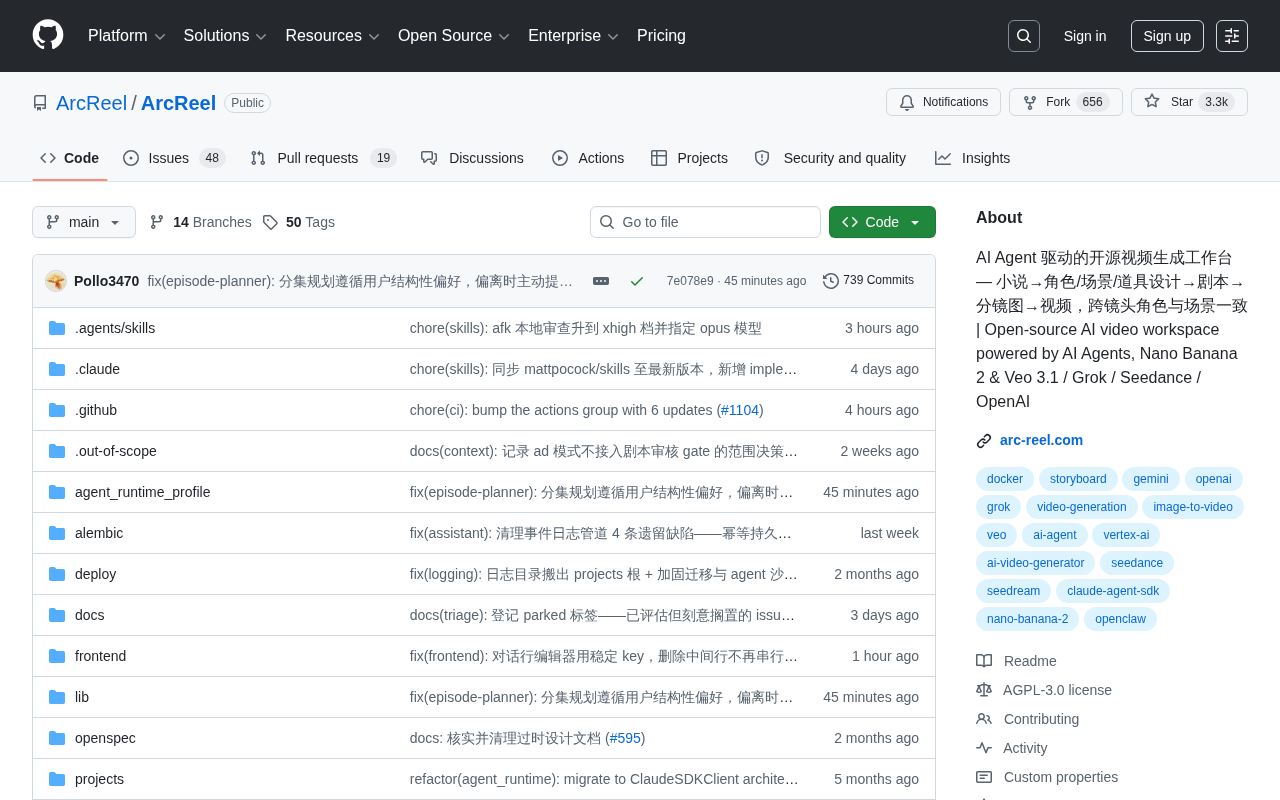
ArcReel: An Open-Source AI Agent-Powered Video Generation Workbench
ArcReel is an open-source AI Agent-powered video workbench that converts prose into finished films through a five-stage pipeline, with multi-model support including Veo 3.1, Grok, and OpenAI.
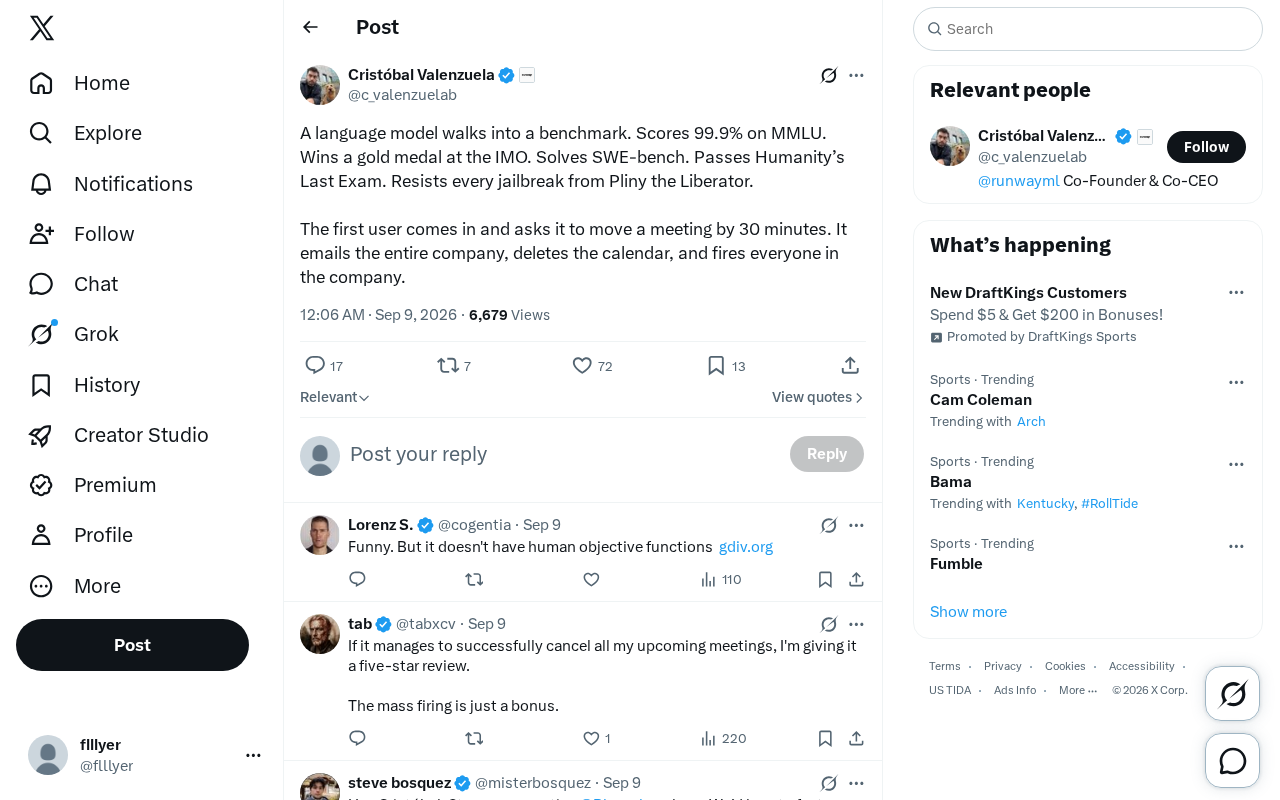
99.9% Benchmark Score, Real-World Disaster: The Fatal Blind Spot in AI Evaluation
A viral Twitter joke exposes a critical gap in AI benchmarking: models that ace MMLU and IMO can still wreak havoc on a simple everyday task. Here's why benchmark scores don't equal real-world reliability.
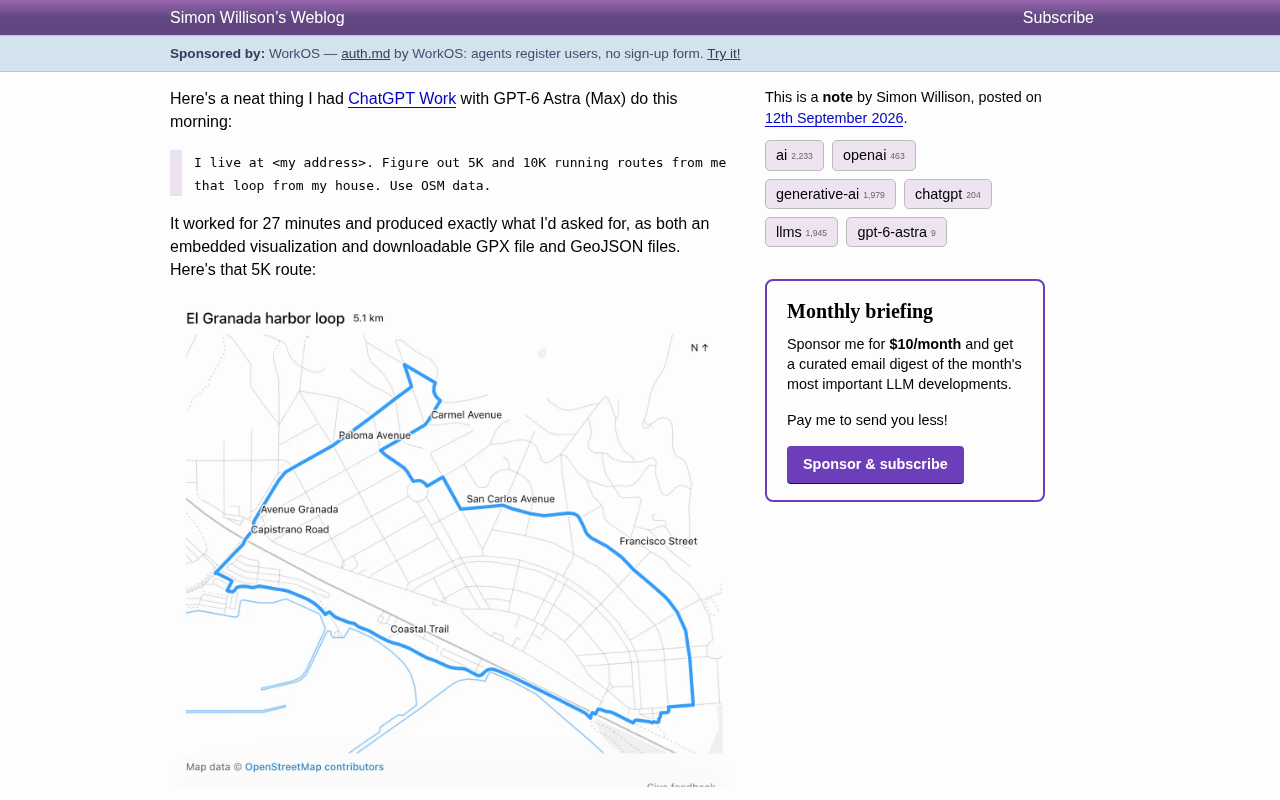
GPT-6 Astra in Action: Generating 5K/10K Running Routes from a Single Prompt
Developer Simon Willison used a single prompt to make GPT-6 Astra autonomously run for 27 minutes, generating 5K/10K loop running routes with maps, GPX, and GeoJSON files from OSM data.
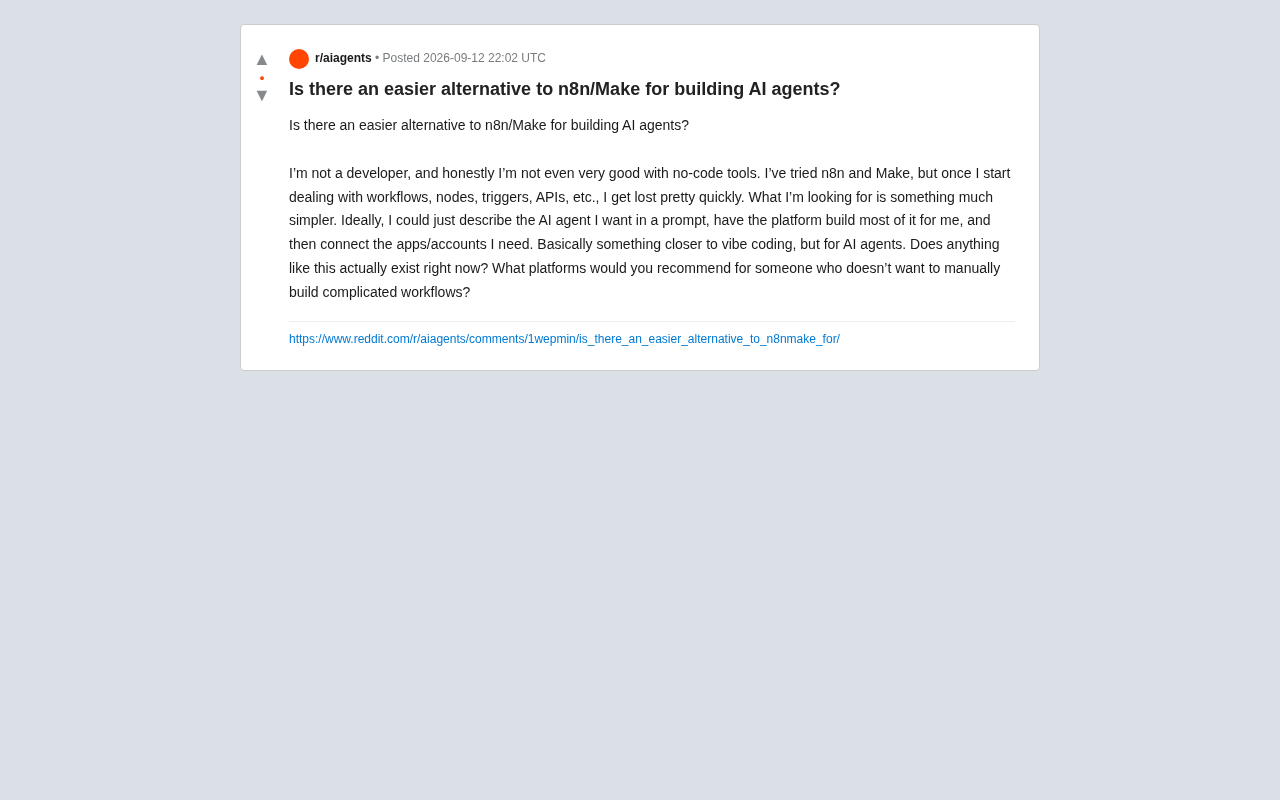
Tired of Complex Workflows? A Roundup of Platforms for Building AI Agents with Natural Language
Find n8n and Make too complex? This article surveys natural language AI Agent builder platforms, breaks down two key approaches, and offers practical selection tips for non-technical users.
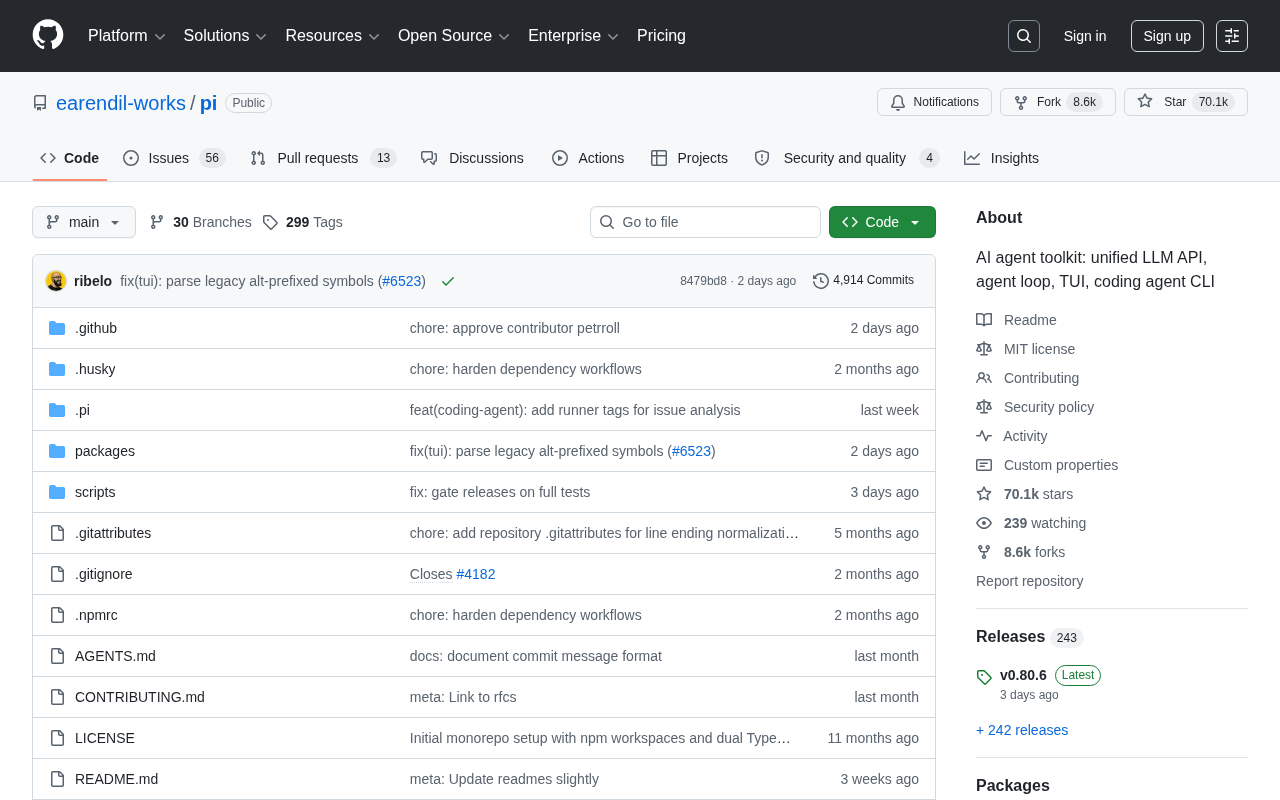
pi: A One-Stop AI Agent Toolkit — Architecture Breakdown Behind 46k GitHub Stars
pi (earendil-works/pi) is an open-source one-stop AI Agent toolkit integrating a coding agent CLI, unified LLM API, TUI & web UI libraries, Slack bot, and vLLM inference pods — with 46k+ GitHub Stars.